# How to Protect Yourself from npm Supply Chain Attacks
Another day, [another npm supply chain attack](https://www.stepsecurity.io/blog/axios-compromised-on-npm-malicious-versions-drop-remote-access-trojan "null")! In the fast-moving world of JavaScript, speed often overrides scrutiny. After reading [Andrew Nesbitt's recent blog post](https://nesbitt.io/2026/03/31/npms-defaults-are-bad.html "null"), it makes a compelling case that this wouldn’t have happened if npm didn’t have bad unsafe defaults.
Here’s a Cheatsheet to secure your npm environment immediately.
### 1. The Safest Option: Don't Use NPM
The absolute best practice for npm security is to **switch out of npm entirely** if your project allows it. Other package managers (like `pnpm`, `yarn`, `deno`, or `bun`) are built with safer, stricter defaults out of the box. If you can migrate, do it. If you are stuck with npm, follow the steps below.
### 2. Disable Auto-Scripts (Stop immediate execution)
By default, npm runs `preinstall` and `postinstall` scripts. This is the #1 vector for malware to exfiltrate `.env` secrets or install backdoors the second you run an install command. One way to eliminate this threat is to turn it off globally.
```
npm config set ignore-scripts true
```
_(Note: Only enable scripts on a per-package basis for dependencies you explicitly trust)._
While you're at it, you should remove unencrypted secrets from `.env` files anyway. Try something like [varlock](https://varlock.dev/ "null").
### 3. Enforce Strict Lockfiles in CI/CD (Stop floating versions)
`npm ci` is meant to be a **safer replacement** for `npm install`. Default installations allow "floating" versions (`^` or `~`), meaning you might silently pull a hijacked package update during a build. Never use `npm install` in your build pipelines. Always use `npm ci` to enforce the exact versions locked in `package-lock.json`.
```
npm ci
```
### 4. Secure your `npx` Usage (Stop silent typosquatting)
`npx` is dangerously convenient because it automatically downloads and executes a package if it isn't found locally. This is a massive risk for typosquatting.
- **The Problem:** If you type `npx tailwindscss` (typo), npx will download and execute whatever malicious package is sitting at that name.
- **The Best Practice:** Always use the `--no-install` flag if you expect the package to already be in your project. If you _must_ download a one-off tool, use the `--package` flag to be explicit.
```
# Only run if already installed (safe)
npx --no-install tailwindcss
# Be explicit about what you are downloading
npx --package=cowsay cowsay "Hello"
```
### 5. Implement Dependency Cooldowns (Stop day-zero attacks)
If a popular package is compromised, pulling the latest version immediately is dangerous. Configure a "min-release-age" buffer (available since npm v11.10.0) to ensure you only install versions that have survived 48 hours without community outcry.
```
npm config set min-release-age 2880 # 48 hours in minutes
```
### 6. Audit Transitive Trust (Map the deep tree)
Supply chain attacks usually hide 4-5 levels deep in your dependency tree. Go beyond `npm audit` and use robust metadata tools like [Ecosyste.ms](https://ecosyste.ms/ "null") to evaluate the actual maintenance health of your entire tree.
### AI Coding Agents Love `npm install`
If you use AI coding assistants (like Claude, Cursor, or Copilot), be aware that their default behavior is almost always to blindly run `npm install` when adding a new package. You must explicitly instruct your agents to follow these security practices. (Even then, agents don’t always follow these instructions, especially when their context windows become bloated.)
Add a section to your project's agent instructions (`AGENTS.md`, `CLAUDE.md`, or `.cursorrules`) file to force the AI to avoid npm if possible, or at least use safer commands like `npm ci` and `--ignore-scripts`.
Even if you don't use AI coding agents, many of your dependencies certainly DO.
### Context: Why This Matters Now
[Recent supply chain incidents](https://access.redhat.com/security/supply-chain-attacks-NPM-packages "null") prove that attackers are targeting our _tools_, not just our code. Relying on default settings prioritizes convenience over verification, leaving the door wide open for automated, wide-scale compromises. Securing your package manager is no longer optional; it is fundamental infrastructure security.
# Cherish Contradictions
I am discovering a truth, which I’m sure any avid reader of biographies has discovered long ago: **look for the contradictions and cherish them**. We human beings are such beautifully contradictory animals. Do not trust any characterization of a person that is lacking contradictions. For there you will discover propaganda.
# Smart People Ask Dumb Questions
Here's an uncomfortable truth: **you're probably staying ignorant to protect your ego**. You constantly have questions that you don't ask because you're afraid of looking stupid. You have an idea, you're curious about something, you wonder how something works, but you keep quiet. You don't ask the question.
**You think you're protecting yourself from embarrassment. Actually, you're choosing ignorance over growth.**
## The Questions That Changed Everything
Let me tell you about some truly stupid questions:
**"What if people could have their own personal computer?"** Steve Jobs asked this when computers were room-sized machines for corporations and universities. A computer in your home? For what? Playing games? That's ridiculous.
**"Why can't we just sell books online?"** Jeff Bezos wondered this when bookstores dominated every shopping center. Who would buy books without seeing them first? Without the experience of browsing? Absurd.
**"What if we stopped trying to build a motor and just learned to glide first?"** The Wright Brothers asked this when every "serious" aviation pioneer was racing to build powered flight. Go backwards to unpowered flight? That's the opposite of progress.
**"Why does this pitchblende ore give off more radiation than pure uranium?"** Marie Curie asked this when everyone "knew" radiation came from uranium compounds. Her stupid question led to discovering two new elements and revolutionized physics.
These questions seemed dumb because they challenged what everyone took for granted. They questioned the "obvious." And they revolutionized human understanding.
The pattern? The most important questions often sound the stupidest.
## Your Confusion Is Data
Here's what you need to understand: if something confuses you, it's probably confusing others too. Your confusion tells you that something needs clarification, that an assumption needs examination, that a concept needs better explanation. That's signal, not stupidity.
Or it could be simply telling you that you need to learn more. That's valuable information. Who cares if you look dumb? Once you ask, you start learning. And once you learn, you don't look dumb at all. You look humble, human, courageous.
When you ask your "dumb" question, you're not just helping yourself. You're helping everyone else who was too afraid to ask. You're identifying unclear knowledge. You're exposing faulty assumptions. You're doing the intellectual work that everyone else is avoiding.
Your question isn't dumb. Your silence is.
## The Cost of Looking Smart
Think about what you're trading when you stay silent:
- You leave the meeting still confused, now with the added task of figuring it out alone
- You spend hours working around a problem that could be solved in minutes with a simple question
- You build on a foundation you don't fully understand, ensuring future confusion
- You rob others of the chance to clarify their own thinking by explaining it
And for what? To maintain the illusion that you already know everything? To preserve the appearance of expertise? News flash: **No one is dumb enough to think that you know everything.** You haven't fooled anyone except yourself.[^1]
[^1]: Alright, maybe you fooled a few people, but if they were foolish enough to believe that you knew everything, then how valuable is their opinion anyway? Sooner or later, they'll see through your facade and they will resent your hypocrisy.
Here's the irony: the people who look smartest in the room are often the ones asking the most questions. They're engaged. They're thinking critically. They're actually learning while everyone else is performing.
## The Art of the Dumb Question
So how do you actually do this? How do you overcome years of conditioning that tells you to stay quiet?
**Start with the obvious.** The questions you think are too basic are often the ones that need asking. "Can you explain what you mean by [common term]?" This ensures everyone is using the same definitions. If a term gets thrown around in every meeting, it's worth defining.
**Name the confusion.** Instead of asking the question directly, you can say: "I'm confused about how X relates to Y." This frames it as your learning process, not a test of knowledge.
**Question the premise.** The most powerful questions challenge underlying assumptions: "Why do we do it this way?" or "What problem does this solve?" These sound naive. That's exactly why they're powerful. They force everyone to examine the fundamentals instead of turning their brains off and accepting the status quo.
**Follow up.** If the first answer doesn't clarify, ask again. "Can you give me an example?" or "How does that work in practice?" Keep asking until you actually understand.
**Make it safe for others.** When someone asks a question, respond with curiosity, not judgment. Say "Great question" and mean it. Create the environment you wish you had.
**Respond with patience.** Let's be honest: some questions feel really dumb. Especially when someone is repeatedly asking the same basic question. But it takes time to learn things, and responding with hostility isn't gonna make them learn any faster. Be patient, kind, and encouraging.
## The Courage to Not Know
Every breakthrough in human knowledge came from someone willing to ask a question that made them look foolish. Every personal breakthrough in your understanding will come the same way.
The choice is yours: protect your ego and stay confused, or embrace the discomfort and actually learn something.
Smart people ask dumb questions. Dumb people pretend they don't need to.
Which one are you?
# Adding Privacy-Friendly Comments to a Hugo Site with Chirpy
I needed a comment system for this blog. Not because I expect a flood of discussion (let's be honest, most personal tech blogs don't) but because those rare moments when someone has a question or insight are worth enabling. The challenge? Finding a solution that respects privacy, stays free or cheap, and doesn't require a PhD in server administration.
## The Search: What I Actually Needed
My requirements were straightforward:
1. **Privacy-preserving** - No aggressive tracking or data selling
2. **No account required** - Reduce friction for commenters
3. **Anonymous commenting** - Allow users to comment without revealing their identity
4. **Free or cheap** - This is a personal blog, not a business
5. **Proper moderation** - I need to delete spam and get notified of new comments
6. **Simple setup** - Ideally just drop in a script tag
7. **Future flexibility** - Open source preferred, so I could self-host later if needed
## Why Not Disqus?
I tried [Disqus](https://disqus.com) first. It's the obvious choice. It's nearly ubiquitous, feature-rich, and easy to set up. But the more I learned about its privacy practices, the less comfortable I felt.
Disqus uses third-party JavaScript widgets that function as tracking beacons across the web. Even when users aren't logged in, it collects IP addresses, browser fingerprints, installed add-ons, and browsing patterns. [This data gets shared with third-party advertisers](https://www.logora.com/blog-posts/data-privacy-concerns-disqus). During 2024 alone, Disqus received 468 data access requests, and user data is processed by teams across the United States, India, and the Philippines.
For a blog focused on technical integrity, using a comment system that monetizes visitor data felt really slimy. I needed something better.
## The Alternatives
I explored several options:
- [Talkyard](https://blog-comments.talkyard.io/) - I like this a lot. It reminds me of [Discourse](https://www.discourse.org/) however there is no free tier and this site is not making any money and doesn't have enough traffic to justify the cost.
- [Giscus](https://giscus.app) - GitHub-based comments using Discussions. Great for developer blogs, but requires readers to have GitHub accounts
- [Chirpy](https://chirpy.dev) - Privacy-focused, open source, simple to set up
Chirpy checked all the boxes. It's privacy-preserving by design, has a clean moderation interface, offers cloud hosting on a free tier (with paid pro options), and being open source means I could self-host in the future if my needs change. And I love that it doesn't require users to create an account.
## The Implementation
The beauty of Chirpy is how straightforward the integration is. For a [Hugo](https://gohugo.io/) site like this one, you only need two things:
Chirpy's docs have a very simple [Get started](https://chirpy.dev/docs/get-started) guide.
### 1. Load the Chirpy Script
First we simply add this script to your page's HTML in the `` section:
```html
```
Then add the `data-chirpy-comment` attribute to any HTML element that should render the comment widget:
```html
```
So I modified my hugo template by editing `layouts/partials/head.html`:
```go-html-template
{{- if .Site.Params.chirpy.enabled }}
{{- $chirpyDomain := "example.com" }}
{{- if hugo.IsProduction | or (eq site.Params.env "production") }}
{{- $chirpyDomain = .Site.Params.chirpy.domain }}
{{- end }}
{{- end -}}
```
This loads Chirpy only when enabled in config, so I can easily turn it off in my config for different environments.
I also use `example.com` in development so I don't pollute my production comment threads during local testing.
### 2. Add the Comment Widget
Create a `layouts/partials/comments.html` partial that includes the Chirpy widget where you want comments to appear:
```go-html-template
{{- $allowedSections := slice "thoughts" "posts" "essays" -}}
{{- $currentSection := .Section -}}
{{- if in $allowedSections $currentSection -}}
{{- if and .Site.Params.chirpy.enabled .Site.Params.chirpy.domain -}}
{{- end -}}
{{- end -}}
```
I only show comments on posts, essays, and thoughts—not on project pages or the homepage. The `data-chirpy-comment="true"` attribute tells Chirpy where to render the comment interface.
### 3. Include Comments in Templates
Add the comments partial to your single page templates. In `layouts/posts/single.html`:
```go-html-template
{{ define "main" }}
{{ .Content }}
{{- partial "comments.html" . -}}
{{ end }}
```
And I repeated this for `layouts/essays/single.html` and `layouts/thoughts/single.html`.
### 4. Configure in config.toml
Enable Chirpy and specify your domain:
```toml
[params.chirpy]
enabled = true
domain = "dandylyons.net"
```
That's it. Four small changes, maybe 30 minutes of work including testing.
## Testing
I tested locally with `hugo server -D --buildFuture` to verify the widget loaded correctly (with the development domain). Then I deployed to Netlify and tested on the live site to confirm comments worked in production.
No issues. No debugging. It just worked.
## What I Appreciate
**Simplicity** - The entire setup is a script tag and a div. No OAuth flows, no complex configuration, no database setup.
**Privacy** - Chirpy doesn't track users across sites or sell data to advertisers. Comments are stored on Chirpy's servers (or your own if self-hosted), not scattered across a marketing data ecosystem.
**Moderation** - The Chirpy dashboard lets me approve, delete, and respond to comments. I get notifications when new comments arrive.
**Open source** - If I outgrow the free tier or want complete control, I can self-host Chirpy using the same interface.
**Cost** - Free tier works perfectly for personal blogs. Pro plans exist if you need more.
## The Result
Comments now appear at the bottom of posts, essays, and thoughts on this site. Visitors can leave comments without creating an account (though they can use GitHub or email for notifications). I can moderate from a simple dashboard. No one gets tracked across the web.
For a static Hugo site that values privacy and simplicity, Chirpy hit the sweet spot. If you're building a personal blog and want to enable conversation without compromising on privacy, give it a look.
---
**Resources:**
- [Chirpy website](https://chirpy.dev)
- [Chirpy on GitHub](https://github.com/chirpy-dev/chirpy)
- [Privacy friendly - Chirpy documentation](https://chirpy.dev/docs/features/privacy-friendly)
---
**Sources:**
- [Data Privacy Concerns: Why Disqus May Not Be Safe for Your Participation System](https://www.logora.com/blog-posts/data-privacy-concerns-disqus)
- [Top 11 Disqus Alternatives in 2025](https://hyvor.com/blog/disqus-alternatives)
- [Disqus Privacy Policy](https://help.disqus.com/en/articles/1717103-disqus-privacy-policy)
# Ensuring Swift Compatibility on Linux
# Ensuring Swift Compatibility on Linux
Swift has long had a reputation for being _that iOS language_, but the truth is that Swift has had cross-platform Linux support for nearly a decade. It's robust and battle-tested in production, powering web backends, microservices, and command-line tools. That being said, like any platform, Linux has its own quirks and best practices that differ slightly from development on Apple platforms. This guide covers essential tips and strategies to ensure your Swift projects run smoothly on Linux.
> [!NOTE] Designed for Swift 6 and Later
> This guide will focus on best practices for Swift on Linux projects using Swift 6 and later. If you're using Swift 5.x, some details may differ, especially around Foundation modularization. But the core principles still apply.
---
## Why Swift on Linux?
* **Swift on the Server** – Frameworks like **Vapor** and **Hummingbird** run natively on Linux and deliver high-performance server applications.
* **Swift in Docker** – Official Swift Docker images allow you to build and run Swift apps in small, portable containers.
* **Swift in CI/CD Pipelines** – Linux-based GitHub Actions runners are significantly cheaper than macOS runners and are ideal for automated testing.
---
## Cross-Platform Logging
### ❌ Avoid `OSLog` for Cross-Platform Projects
`OSLog` and the macOS unified logging system are **Apple Platform-only**.
### ✅ Use `swift-log`
Swift's open-source logging API works across macOS, Linux, and Windows.
* Import as a SwiftPM dependency.
* Supports log levels, metadata, and custom back-end providers.
* Ideal default for any cross-platform Swift service or tool.
---
## Foundation on Linux: What Changed?
As Swift developers, we're spoiled. Swift ships with a powerful Foundation framework which provides essential data types, collections, and utilities. In fact, they are so useful and ubiquitous that they feel like they are a core part of the language itself. But Foundation is a massive framework. On Apple platforms, this doesn't matter because Foundation ships as part of the OS, but on Linux, your application must bundle Foundation. In the past, this was an all-or-nothing choice: you either imported the entire Foundation framework, or you didn't use it at all, and lose so much of what makes Swift great.
But Apple has greatly improved this story with two major developments:
1. **Modularized Foundation packages** – Foundation is now split into smaller modules that can be imported individually, reducing unnecessary bloat.
2. **Swift-native Foundation rewrite** – Foundation was originally created over 30 years ago, long before Swift existed, and was written in Objective-C. But the Linux version of Swift has no Objective-C runtime. This meant that many Foundation APIs had the same interface but different behavior on Linux, and some APIs were missing entirely.
Swift 6 modularized Foundation and reduced reliance on the Objective-C runtime. Apple is actively rewriting Foundation in pure Swift, which:
* **Improves Linux compatibility** (no ObjC runtime required).
* **Improves performance**.
* **Reduces platform divergence** between macOS and Linux.
> [!NOTE] Key Takeaway: Modularize
> What does this mean for you? Instead of importing the entire Foundation framework, you should now import only the specific Foundation modules you need. While on Apple platforms this doesn't matter (since Foundation is part of the OS), on Linux this drastically reduces your app's size and startup time.
### Foundation Modules at a Glance (Swift 6+)
| Module | What It Contains / When to Use It | Notes for Linux Compatibility |
| ---------------------------------- | ------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------- |
| **FoundationEssentials** | Core value types: `Data`, `Date`, `URL`, `UUID`, predicates, formatting protocols, time handling. | Great default for most cross-platform apps. Lightweight; no ObjC bridging. |
| **FoundationInternationalization** | Localization: date/number formatting, calendars, time zones, measuring units (ICU-backed). | Needed for user-facing locale formatting. Bigger dependency footprint. |
| **FoundationNetworking** | `URLSession`, `URLRequest`, `HTTPURLResponse`, cookies. | Required for all networking on Linux (not included in Essentials). |
| **FoundationXML** | XML parsing (`XMLDocument`, `XMLParser`). | Uses libxml2 on Linux. Import only if you need XML support. |
| **FoundationObjCCompatibility** | ObjC-bridged APIs: `NSObject`, KVC/KVO, some legacy classes. | Avoid in cross-platform code. Linux has no ObjC runtime. |
```swift
#if canImport(Darwin)
// Darwin means Apple platforms (macOS, iOS, etc.)
import Foundation
#else
// non-Apple platforms
import FoundationEssentials // Only import parts you need, leave out parts you don't
#endif
```
---
## Linux-Specific Differences You Should Know
* **No Apple Frameworks** – Avoid UIKit, AppKit, SwiftUI, CoreData, etc. Detect macOS with `#if os(macOS)` or prefer the more flexible `#if canImport(Darwin)` when checking for Apple platforms broadly. For example:
```swift
#if os(macOS)
// macOS-specific code
#endif
#if canImport(Darwin)
// Any Darwin platform: macOS, iOS, watchOS, tvOS
#endif
```
* **Case-Sensitive Filesystems** – macOS often uses case-insensitive filesystems; Linux does not. This means `MyFile.swift` and `myfile.swift` are treated as different files on Linux but may conflict on macOS. Always use consistent casing in your imports and file references.
* **File Permissions** – Linux enforces POSIX file permissions strictly. Usew [FileManager APIs](https://developer.apple.com/documentation/Foundation/FileManager) or POSIX functions to set executable bits and ownership explicitly, as defaults may differ from macOS.
* **No Objective-C Runtime** – Linux builds cannot use KVC, KVO, `NSObject`, or Cocoa frameworks.
* **Line Endings** – macOS and Linux both use `\n`. (Differences only arise when dealing with Windows files.)
* **Process & Shell Differences** – Environment variables and path resolution may differ across systems.
---
## Use Docker for Local Linux Testing
Docker makes Linux testing extremely reliable without requiring a Linux machine or VM.
### Quick One-Off Test
Test whether your project builds on Linux instantly, without installing Swift locally:
```sh
docker run --rm -v "$PWD":/host -w /host swift:6.2-jammy swift build
```
**What each flag means:**
* `docker run` — Start a temporary container.
* `--rm` — Delete the container when finished (no cleanup required).
* `-v "$PWD":/host` — Mount your current directory into the container at `/host` so Docker can access your project.
* `-w /host` — Set the working directory inside the container to your mounted folder.
* `swift:6.2-jammy` — Use the official Swift 6 Linux image based on Ubuntu Jammy.
* `swift build` — Run the Swift compiler *inside the Linux environment*, ensuring true cross-platform compatibility.
This is perfect for a quick sanity check before pushing to CI.
### Production Dockerfile Setup
For consistent builds in CI/CD or when deploying to servers, create a `Dockerfile` in your project root with something like this:
```dockerfile
FROM swift:6.0 as build
WORKDIR /app
COPY . .
RUN swift build -c release
```
**Build the Docker image:**
```sh
docker build -t my-swift-app .
```
**Run the container:**
```sh
docker run my-swift-app
```
This compiles your Swift package inside a Linux container and executes the resulting binary. Use this workflow to validate Linux compatibility even if your host machine is macOS—your source is built and executed by actual Linux Swift toolchains.
**For development:** Open a shell inside the container to run commands manually:
```sh
docker run -it --rm -v $(pwd):/app swift:6.0 bash
```
This allows your project to build consistently regardless of the host environment, ensuring reproducibility and simplifying setup for contributors.
---
## Use Linux GitHub Actions for CI
Linux runners are fast, available, and **10× cheaper** than macOS runners.
**Minimal Swift CI Setup:**
```yaml
name: Linux Swift CI
on: [push, pull_request]
jobs:
build:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v4
- uses: swift-actions/setup-swift@v2
with:
swift-version: "6.0"
- name: Build
run: swift build --enable-testing
- name: Test
run: swift test
```
---
## Quick Checklist
Now that you understand the key differences and best practices for Swift on Linux, here's a handy checklist to ensure your project is fully compatible:
* [ ] **Use modern Swift 6 strict concurrency** – Audit your code for `@MainActor`, `Sendable`, and data races to ensure thread safety across platforms.
* [ ] **Remove Objective-C runtime dependencies** – Avoid `@objc`, `dynamic`, and `NSObject` inheritance unless wrapped in `#if canImport(ObjectiveC)`. Linux has no ObjC runtime.
* [ ] **Prefer modular Foundation packages** – Import only what you need (`FoundationEssentials`, `FoundationNetworking`, etc.) rather than the monolithic Foundation.
* [ ] **Check platform boundaries** – Use `#if os(Linux)` and `#if canImport(Darwin)` to isolate platform-specific code.
* [ ] **Use `swift-log` instead of OSLog** – Ensures consistent logging across macOS, Linux, and Windows.
* [ ] **Avoid macOS-only APIs** – AppKit, CoreGraphics specifics, and FileManager extensions unavailable on Linux will cause build failures.
* [ ] **Ensure paths are correct** – Linux uses a POSIX filesystem with strictly case-sensitive paths. Test file references on Linux to catch casing issues early.
* [ ] **Confirm file permissions manually** – Linux enforces POSIX permissions strictly. Use `FileManager` or POSIX APIs to set executable bits and ownership if your app depends on specific permissions.
* [ ] **Test on Linux via Docker and CI** – Use `docker run` for quick local validation and GitHub Actions Linux runners for automated testing. Both are faster and cheaper than macOS alternatives.
* [ ] **Validate system library dependencies** – Ensure any C libraries your code depends on exist on Linux, or vendor them into your project.
---
## Acknowledgments
Thanks to [Swift Package Index](https://mas.to/@SwiftPackageIndex) for sharing their Docker command for running `swift build` on Linux!
# ITERATE: Your Path to Progress, Not Perfection
**ITERATE**
**I** don't know what the heck I'm doing.
**T**hat's okay.
**E**veryone is a work in progress.
**R**eflect on your past wins and losses.
**A**im for progress, not perfection.
**T**iny improvements add up.
**E**ventually, you'll see the difference.
---
## **I: I don't know what the heck I'm doing.**
Do you feel inadequate? Great. You’re in good company. Inadequacy is normal. We are all inadequate in some way (but only some of us are brave enough to admit it). How are you going to improve if you don’t even realize that you need to improve? Embracing this initial feeling is the first step toward genuine growth.
## **T: That's okay.**
Take it easy on yourself. It is okay to not be okay. This doesn't mean we settle for mediocrity; rather, it means we grant ourselves permission to be human. We simply need to let go of the relentless pursuit of perfectionism and acknowledge where we are right now.
## **E: Everyone is a work in progress.**
When you have the courage to admit that you are not perfect, you finally start to realize that *everyone* is a work in progress. Sure, you already knew that nobody is perfect, but did you truly believe it? Didn’t it often feel like everyone had their shit together except for you? When you start looking closer, you begin to see: nobody has it completely figured out. We’re all just trying to keep it together, learning and growing along the way.
## **R: Reflect on your past wins and losses.**
Be balanced in your reflection. Don’t focus solely on your wins, lest you become complacent and miss opportunities for deeper growth and improvement. But also, don’t dwell only on your losses, lest you discourage yourself and destroy all hope. Learn from both, celebrating successes while extracting wisdom from setbacks.
## **A: Aim for Progress, Not Perfection**
Quit aiming for perfect; it is an unattainable and often paralyzing target. Instead, aim for better. Focus on taking the next small step forward. It doesn’t have to be **dramatically** better every time. Most of the time, it won’t be, and that's perfectly fine. Consistent small improvements compound over time.
## **T: Tiny Improvements Add Up**
The journey of a thousand miles truly begins with a single step. Don't underestimate the power of consistently making small, almost imperceptible improvements. These minor adjustments, done regularly, are the building blocks of significant change.
## **E: Eventually You Will See the Difference**
In the moment, it can feel hopeless. You put in all this work and don’t see any immediate results. But trust the process. In the long run, the cumulative effect of your consistent efforts will yield improvements—sometimes even **dramatic** improvements that might surprise you. Keep iterating, keep growing, and the difference will become undeniable.
>Not that I have already obtained all this, or have already arrived at my goal, but I press on to take hold of that for which Christ Jesus took hold of me. Brothers and sisters, I do not consider myself yet to have taken hold of it. But one thing I do: Forgetting what is behind and straining toward what is ahead, I press on toward the goal to win the prize for which God has called me heavenward in Christ Jesus.
> — Philippians 3:12-14 (NIV)
# What is The Neverending Story?
I had the pleasure of rewatching the movie [The Neverending Story](https://www.imdb.com/title/tt0088323/) recently. I barely remember seeing portions of it as a very young child. Basically the only thing I remembered was the title and that there was a big flying dog-dragon thing. Obviously, with a title like that it begs the question _Is it really a never-ending story?_ The surprising answer is _actually yes, in a way it really is a never-ending story._
Before we proceed, let me say that The Neverending Story is a movie worth seeing. (From what I hear the book is quite good too, but I haven't read it.) What I'm about to explain makes a lot more sense after you have actually become engrossed in the story, and setting and characters. So if you haven't seen it, I recommend you do so before reading further.
## What is The Neverending Story?
Right. With that out of the way, let's answer the question _What is The Neverending Story?_
If you've seen the movie, you know that the story is about a young boy named Bastian who discovers a mysterious book called "The Neverending Story". As Bastian reads the book, we follow the story of Atreyu, journeying to save the land of Fantasia from The Nothing. All of this is fairly standard fantasy fare. For example, we've seen this same [story-in-a-story format](https://tvtropes.org/pmwiki/pmwiki.php/Main/NestedStory) in movies like [The Princess Bride](https://www.imdb.com/title/tt0093779/) and [The Pagemaster](https://www.imdb.com/title/tt0110763/).
But what makes The Neverending Story unique is that as Bastian reads the story, he becomes more and more involved in it. He eventually discovers that he can actually influence the story and in turn the story appears to be influencing him right back.
For example, at one point in the story, Bastian becomes so emotionally invested in Atreyu's quest that he shouts out Atreyu's name, and Atreyu hears him. Bastian is amazed and even a little disturbed by this. Later in the story, Atreyu must pass a test. He must look at a mirror that shows him his true self. Atreyu is terrified of what he might see, but Bastian encourages him to look. When Atreyu looks into the mirror, he sees Bastian's reflection. This is a shocking revelation for both of them.
As Bastian continues to read, Atreyu finally meets the Childlike Empress. The Nothing has overtaken nearly all of Fantasia, and this fantasy world is nearly gone forever. The Childlike Empress explains to Atreyu that the only way to save Fantasia is for a human[^1] child to give her a new name. She also explains that there already is a human child who is watching them right now who can give her a new name.
[^1]: When I saw this, I wondered, "Well isn't Atreyu a human? Why doesn't he just give her a new name?" But apparently Atreyu is not a human. In the book, he's a _Greenskin warrior_ (whatever that is). In the movie, he was supposed to have green skin as well, but they couldn't get the makeup to look right, so they scrapped that idea.
Then we get this dialogue:
> **Atreyu**: If he's so close why doesn't he arrive?
> **The Childlike Empress**: He doesn't realise he's already part of The Neverending Story.
> **Atreyu**: The Neverending Story what's that?
> **The Childlike Empress**: **Just as he is sharing your adventures others are sharing his. They were with him when he hid from the boys in the bookstore.**
> **Bastian**: But that's impossible!
> **The Childlike Empress**: They were with him when he took the book with the Auryn symbol on the cover in which he's reading his own story right now.
At this point, _The Neverending Story_ has already firmly broken the story within a story trope. **It is not actually a story within a story. It is the same story.** Atreyu's story is Bastian's story.
But now, the story is taking this even further. In the same way, Bastian is in this story, there are others who are also in Bastian's story.
>Just as he is sharing your adventures others are sharing his.
Who are these others? The movie doesn't say, but I think it's pretty clear that these others are us, you and I, the audience. **We are also part of The Neverending Story.** Just like the Empress said, we were with Bastian when he hid from the boys in the bookstore. We were with him when he ditched class to read the book in the attic. And now we are with Bastian as he is realizing that he is part of The Neverending Story. Bastian is realizing that he must get involved in the story to save Fantasia, but do you realize that you yourself must also get involved in the story?
## The True Power of Storytelling
Stories are powerful. They shape our identities, our values and our worldview. Stories can inspire us to greatness, or they can shackle us in despair and hopelessness. Millions of people have been profoundly affected by this story, _The Neverending Story_. That may or may not be you. But undoubtedly you have been profoundly affected by some story. Stories are not just entertainment. They are a fundamental part of the human experience. We are constantly hearing stories, telling stories, and even living out stories.
Like Bastian, when we realize this, it is an incredibly empowering realization. We gain confidence and courage and self-worth. We realize that we are not just passive observers of our lives, but active participants. We can influence the story of our lives and the world around us. By naming the Childlike Empress, Bastian is proactively changing the world around him. Sure, in a sense, Bastian is not really changing anything. Fantasia is a fictional world. Changing this fictional world doesn't really change anything in the real world. But it does change Bastian. It changes how he sees himself and the world around him. It gives him hope and purpose. It changes his actions. It gives him a new story to live by and that really does change the real world.
## The Danger of Storytelling
>Life and death are in the power of the tongue, and those who love it will eat its fruit.
>- [Proverbs 18:21](https://biblehub.com/proverbs/18-21.htm)
In the early 20th century, there lived a young man whose nation lost a bitter war. The world blamed his nation for starting the war, and they were treated as pariahs. Millions of people were forced into cruel poverty for simply being born in the "wrong" country. This young man felt led to do something about this. He raised a political movement meant to restore his nation's pride and power and for this he was thrown into prison. But somehow, this mere prisoner managed to rise to power and become the leader of his nation, and even to propel his nation to become one of the most powerful nations in the world. How did he do this? Through the power of storytelling. While in prison, he wrote an incredibly influential book. Unfortunately, this book was [Mein Kampf](https://en.wikipedia.org/wiki/Mein_Kampf) (My Struggle), an autobiographical manifesto by [Adolf Hitler](https://en.wikipedia.org/wiki/Adolf_Hitler).
In this book, Hitler told a stirring story about how his nation had been betrayed by evil forces, and how it was destined to rise again. He told a story about how his nation was superior to all others, and how it was their right and duty to dominate the world. He told a story about how certain groups of people were subhuman and needed to be exterminated for the good of humanity. This book was incredibly influential, and it helped to fuel the rise of the Nazi party and the outbreak of World War II. Millions of people were killed in this war, and the world was forever changed.
> **G'mork**: Foolish boy. Don't you know anything about Fantasia? It's the world of human fantasy. Every part, every creature of it, is a piece of the dreams and hopes of mankind. Therefore, it has no boundaries.
> **Atreyu**: But why is Fantasia dying, then?
> **G'mork**: Because people have begun to lose their hopes and forget their dreams. So the Nothing grows stronger.
> **Atreyu**: What is the Nothing?
> **G'mork**: It's the emptiness that's left. It's like a despair, destroying this world. And I have been trying to help it.
> **Atreyu**: But why?
> **G'mork**: Because people who have no hopes are easy to control; and whoever has the control... has the power!
> **Atreyu**: Who are you, really?
> **G'mork**: I am the servant of the power behind the Nothing. I was sent to kill the only one who could have stopped the Nothing.
In this scene, we learn several crucial details from G'mork, the wolf-like creature who serves the Nothing. First, we learn that Fantasia is the representation of all of human imagination, hopes and dreams. Next, we learn **why** Fantasia is dying. It is dying because people are losing their hopes and forgetting their dreams. We saw this in post-WWI Germany. People had lost all hope. They were desperate and willing to believe anything. Then we learn what the Nothing really is. It is the emptiness that is left when people lose their hopes and dreams. The Nothing is despair, hopelessness, apathy, and destruction itself. The Nothing is nihilism itself. Finally, we learn G'mork's motivation. Paradoxically, G'mork is helping the Nothing, even though he is also being destroyed by it. Why? _"Because people who have no hopes are easy to control; and whoever has the control... has the power!"_ This is the same thing that Hitler did. He exploited the hopelessness of millions by telling them a story, and using that story to control them. Like G'mork, Hitler was so consumed by his desire for power that he even followed it to his self-destruction.
## The Worst Story
Like Hitler, G'mork was also telling a story. His was the story of The Nothing, the story of nihilism. This is truly the worst story of them all. It is the story that rejects all other stories. In fact, it is the story that says there are no stories, the story that says life has no meaning, no purpose, no value. It is the story that says nothing matters. It is the antithesis of storytelling itself. It is the rejection of truth, the embracing of contradiction, and it is the misery that loves company.
In G'mork and The Nothing, we see the utter darkness of nihilism, but in practice, nihilism is rarely so brazen. Like roaches, nihilism knows that when it is out in the open, it will certainly be stamped out. So nihilism is often much more subtle. It disguises itself by appropriating labels like _realism_, _pragmatism_, and _relativism_. But the threat of nihilism should not be underestimated. It is not a childish fear to be dismissed. Nihilism is a real and present danger, and it is present in every story that rejects truth, hope, meaning and beauty. Few, if any stories, would reject truth at every point, for such a story would be self-defeating. But far too many stories reject truth at crucial points, and this is just enough to inject nihilism.
Yet as dangerous as nihilism is, it is actually quite easy to defeat. All you have to do is tell the better story. A story that embraces truth, hope, meaning and beauty. A story that inspires courage, love and sacrifice. A story that gives life.
## The Responsibility of Storytelling
You and I hold incredible power in our stories. We can tell stories that inspire hope and courage, or we can tell stories that spread despair and hopelessness. Our tongues can bring life or death. This is not merely poetic rhetoric. Our stories, ideas, beliefs and even fantasies can have real, actual impact on the world around us. We must be very careful about the stories we tell. Take responsibility for the stories that you tell to yourself and others.
When you are angry at someone, be careful about your words. The next time that someone cuts you off on the road, and you feel the urge to call them a _f****** idiot_, ask yourself: _What story am I telling right now? Will these words bring life or death?_
We must also be very careful about the stories that we believe. The next time that someone calls you an awful name, ask yourself: _Is that story true? Is that the story that I should believe? Is that the story that I should live by?_
## Live The Story
Reject nihilism. Reject The Nothing. You must have hope, and for that you must have stories that remind you what is good, true and beautiful. You must have stories that inspire you to be better, to do better, to love better. You must have stories that give you courage to face the challenges of life. You must have stories that remind you of your worth and value, stories that remind you of your purpose and meaning.
And don't just pick any story. The people of 1930's Germany picked a pretty terrible story. All throughout history, people have picked stories that are just as bad, if not worse. No, pick a story that is worth being a part of. Pick a story that is worth living for. Pick a story that is worth dying for. Don't settle for a sub-par mediocre story. Pick a great story. Pick the greatest story ever told.
# I Heard You Don't Like Netflix...
Another day, another cancel culture campaign. Who is the target this time? On X, Elon Musk told his followers to ["cancel Netflix for the health of your kids"](https://x.com/elonmusk/status/1973292474375479556). Well sure you can choose to follow that or not, but there's plenty of other reasons to cancel Netflix already. How about the mountains of cash you'll be saving over time? How about the even bigger mountain of time you'll be saving? How about the ever increasing monthly fees? Maybe it's not so great to buy from the company that literally invented binge-watching. While you're at it, why don't you cancel Hulu, Disney+, HBO Max, and all them other money-suckers?
If you feel like maybe you wanna cut the cord... er subscription, then here's a quick little guide for you.
## Find Your Favorite Shows On Blu-Ray
The trajectory for these cancel campaigns is usually the same. A bunch of people cancel, but then dang, my favorite show came out with a new season and I can only watch it on Netflix. Wrong. You can watch it elsewhere, even Netflix exclusives. Where? On Blu-Ray and DVD. Most of Netflix's biggest shows are also released on Blu-Ray. Better yet, **you can borrow many of these for free from your local library**. If you absolutely must watch that show (which you don't), then you can still watch it without a subscription.
## Embrace JOMO
It's fun to be a part of a cultural moment. It's fun to react to a hit new show when all your friends and family are reacting to the same thing. And FOMO says it's not too fun to miss out on things. Well, that's only half of the equation. Sure, you're missing out on supposedly good things[^!], but the truth is you're also missing out on so many junk things. Like petty drama, and fear mongering, and manipulative product placement ads.
[^!]: many of which are fleeting and in the long run provide little, if any, value at all
## Tons Of Other Options
But there are some of you who are still saying, _I don't want to live under a rock._ Alright, fine. Here's a bunch of other streaming services that are actually free:
* **[Tubi](https://tubitv.com/)**: Massive on-demand library (over 250,000 titles in the U.S.), including movies, TV, and more than 250 live channels. Owned by Fox, it carries films from major studios and unique Tubi Originals. No sign-up required but registration gives parental controls and watchlists.
* **[Pluto TV](https://pluto.tv/)**: Closest competitor to Tubi, with hundreds of live “channels” simulating cable TV plus on-demand classic shows and movies. Very ad-heavy but broad in both topics and nostalgia.
* **[The Roku Channel](https://therokuchannel.roku.com/)**: Pre-installed on Roku devices but available anywhere. Offers on-demand movies, TV, over 500 live channels, and Roku Originals. Especially convenient for Roku hardware users but works across platforms.
* **[Sling Freestream](https://www.sling.com/freestream)**: Free tier of Sling, offering 600+ live channels, on-demand content, parental controls, and even free DVR (10 hours)—a rare feature among free streamers. Can be a base for paid Sling add-ons.
* **[Plex](https://www.plex.tv/)**: Known for its media server tools, Plex also offers a substantial library of free, ad-supported streaming movies and TV and some live programming.
* **[Xumo Play](https://play.xumo.com/)**: “FAST” service with both on-demand content and dozens of linear channels, including news and entertainment. Similar to Pluto, suitable for casual flipping.
But there's a teeny tiny little catch. Ads. Please forgive me. These streaming services have ads, just like old school TV. How terrible! Except wait a minute, Netflix, Amazon Prime Video, and basically all the other streaming services [still show ads even when you are paying for their service](https://www.emarketer.com/content/streaming-growth-now-driven-by-ad-tiers--not-ad-free-plans).
Well heck, why the heck would I pay money to force myself to watch ads? If I'm gonna be forced to watch ads anyways, then I might as well watch them for free. And if you must have both free and ad-free then these are great options:
* **[Kanopy](https://www.kanopy.com/)**: Uniquely accessible via a public library card or student ID, Kanopy specializes in academic content, independent films, classics, and documentaries—no ads, but library affiliation required.
* **[Hoopla](https://www.hoopladigital.com/)**: Like Kanopy, requires a library card, offering access to films, TV, audiobooks, comics, and music—great for educational and family selections.
Besides, maybe ads aren't all that bad. Ads remind you to go to the bathroom, to take a break from your binge watching habit, and to maybe go outside.
## Go Touch Grass
Our ancestors somehow lived for countless generations without streaming services. How in the world did they survive without a steady stream of The Great British Baking Show? It must have been hell.
Probably not. Who said you need Netflix to chill? Our folks have been chilling just fine without Netflix. It's about time we rediscover fun.
- **Tabletop games:** Tabletop games are a much better form of entertainment than Netflix or even video games. They allow you to actually interact with friends and build lasting memories.
- **Finish that novel you said you were gonna write:** Writing is such a great activity. It sharpens your mind and refines your thinking. And when you're done, you're left with something you can look back on and be proud of. When have you ever been proud of a Netflix binge?
- **Go do cool stuff:** Don't you find it strange how we live vicariously through our entertainment? We love to watch content of people doing incredible things like win a chess tournament or run a crazy tiger zoo. Well, why don't you go out and do some of that cool stuff yourself? It requires more time, hard work and effort but in the long run it is far more entertaining. Plus it provides something Netflix has never been able to supply, fulfillment.
Here are 3 more items to add to your list:
- **Learn a new skill:** Whether it's playing a musical instrument, coding, or learning a new language, acquiring a new skill offers a sense of accomplishment and expands your horizons. YouTube offers a goldmine of free educational content. (YouTube is also a blackhole for doomscrolling.) There are tons of sites like [Skillshare](https://www.skillshare.com/en/) that offer courses.
- **Explore the outdoors:** Disconnect from screens and reconnect with nature. Go for a hike, try camping, or simply spend time in a local park. The fresh air, natural beauty, and physical activity are invigorating, reducing stress and boosting your mood in ways that no amount of indoor entertainment ever could.
Alright, now hopefully, your streaming cancellation plan can last a little longer.
# Reject Schadenfreude
Reject [Schadenfreude](https://en.wikipedia.org/wiki/Schadenfreude). Despise it for the cancer that it is.
Oh trust me, I understand its allure. I've felt that ecstasy that can only be found in the swift vengeance of karma. I know that pleasant, tingling smile that I feel when I see a jerk on the road get pulled over. I've tasted that drug and delighted in its high. But I say _no more_. Withdrawal be damned.
**Schadenfreude is a plague and deep down, you know it.** It causes you to feel smug and better than the world, entitled, judgmental. Schadenfreude is destructive. It doesn't bless, it doesn't create, it doesn't give. All it does is take. It is selfish. Schadenfreude is rot for the soul.
Worse yet, Schadenfreude is dull and unsatisfying. After a brief rush, it always leaves you wanting more. Soon you will be jonesing to score more Schadenfreude. Schadenfreude is the gateway drug to sadism and sociopathy. But you're better than that, aren't you? You won't get addicted to Schadenfreude. You have self-control. Sure, tell yourself what you need to hear to sleep at night.
Choose the antithesis of Schadenfreude. In Pali they call it *mudita*, pleasure that comes from delighting in other people's **well-being**. Like an infectious smile, noticing joy in others plants joy in yourself. And when others see your smile, and your joy, watch them spread that joy to others. Now that is an addiction worth having. Mudita is a nice little gateway, but when you're ready, why don't you graduate to something even better? Don't just appreciate the well-being of others, **seek it**. Work for the well-being of others, even when it requires the sacrifice of yourself. [Value others above yourself](https://biblehub.com/philippians/2-3.htm). Selflessness is quite the paradoxical drug. The greatest high you could ever feel comes from going quite low. By becoming less, you become so much more. Every drug has a tremendous high, only to be followed by a painful crash. But not this one. Selflessness offers that [peace which doesn't make any sense](https://biblehub.com/philippians/4-7.htm). It is better than any high because it persists even through every low. This is the peace by which heroes have slain monsters, within and without.
## Monsters Are Real
As children we fear monsters under the bed, and our parents reassure us that there are no monsters. Oh if only this were true. Monsters are all too real, and far too common. Only they don't live under beds. They live in the hearts and minds of men. There are monsters ordering [genocide](https://en.wikipedia.org/wiki/Genocides_in_history). There are monsters [cheering the deaths of their ethnic rivals in the streets](https://en.wikipedia.org/wiki/List_of_ethnic_riots). There are monsters [killing innocent people for pleasure](https://en.wikipedia.org/wiki/List_of_serial_killers_by_number_of_victims). There are monsters [inflicting the wrath of online mob rule upon their political enemies through doxxing](https://www.youtube.com/watch?v=dwXSb_gzlV8). And there is even a little monster living deep inside your heart and mine. The monster's favorite snack is Schadenfreude. Please, don't feed the monsters.
# Death to Inboxes
**Unshackle yourself from the tyranny of the inbox.**
You will never be able to keep up with all the messages demanding your attention, and that is okay.
[Inbox zero](https://en.wiktionary.org/wiki/inbox_zero) is a scam and a plague. It teaches us that we can somehow achieve a state of perfect organization and control over our digital lives, if only we would follow its rules. It promises zen and peace, only to be immediately flooded by the deluge of more meaningless messages to fight for your attention. What do you honestly gain from inbox zero? A warm fuzzy feeling? Bragging rights? No. What you really gain is the satisfaction of knowing that you achieved a metric that provides no actual value to your life.
Inbox zero won't cure your cancer, but it will probably give you enough stress to lead to cancer. Inbox zero won't make your work problems go away, but it will certainly bring your work problems into your weekends. Inbox zero won't impress your boss, or your customers, or your coworkers, or yourself[^1].
[^1]: If you can't impress yourself, then why do it?
But let's give inbox zero its fair day in court. Let's pretend for a moment that inbox zero has any positive benefit whatsoever. **Exactly how long will inbox zero last? Until inbox one.** The moment you get a single email, inbox zero is gone. The clock is ticking. You lost your zen. You have now failed at inbox zero.
But should you really care?
## Every Inbox Is A Commitment You Didn't Sign Up For
Every inbox is an analogy[^&] to a bygone era that many of us are not old enough to have actually experienced. An inbox was a physical box placed on your desk. Gradually throughout the day coworkers would place more and more items into your inbox. There was a clear expectation from your organization that anything in the inbox that is on your desk needs to be processed by you. You need to read those items, decide what to do, and then do it.
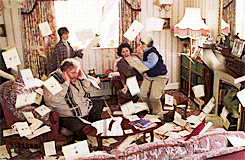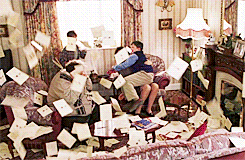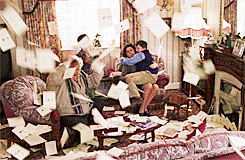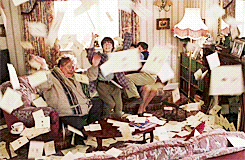
Except in this bygone era, you actually signed up for this job. You agreed to work in an office with an inbox, and so you agreed to process all the items in your inbox. Is that what you signed up for with email? Nope. Email is not your inbox at work. It's your mailbox in your pocket and it's flooded with crap. Spam, scams, advertisements, mailing lists that you never consented to[^@]. But all of this is just the tip of the iceberg. Notifications everywhere! Friend requests, message alerts, two-factor authentication 6 digit codes, [magic link](https://auth0.com/docs/authenticate/passwordless/authentication-methods/email-magic-link) sign-ins[^2], clutter clutter clutter! Our inboxes look worse than Harry Potter's mailbox.
[^&]: A ([skeuomorph](https://en.wikipedia.org/wiki/Skeuomorph)).
[^@]: Sure, you can click the link and request to be taken off the mailing list, but it doesn't matter because they have already sold your email to several other lists.
[^2]: Who was the sadist who thought that magic links were a good idea? Let's take the vital process of authentication, and shove it straight into the email inbox that we already know is drowning in crap. Before, I had a password, and if someone stole my password, at least I could change my password. Now, if they have my email, they have the keys to the whole kingdom. We went from two-factor authentication down to half a factor. Death to magic links!
But all of these items have one thing in common. You didn't sign up for them. Sure, they'll gaslight you into thinking that you did. After all you signed up for their service, didn't you? But how much say did you really have in the matter? The email address has long been the de facto ID card of the internet. You can't even buy and use a TV anymore without being forced to give several people an email address.
So why on earth would you owe anyone inbox zero? Everyone is rampantly invading your inboxes and yet for some reason you owe them a response?
## Inboxes Are Everywhere
We don't just have a flood of emails in our email inbox. We have a flood of inboxes across our digital lives! Slack, Messages, Discord, Facebook, Twitter, YouTube, GitHub, on and on and on. We have so many inboxes, that our operating systems have another inbox called the notification center, just for holding all our other inboxes.
Every single one of these inboxes has a marketing department that is demanding our attention. Each one is insidiously hijacking our psychology against us by using instinctual stress-inducing colors and [dark patterns](https://en.wikipedia.org/wiki/Dark_pattern). Well I'm just plain sick of it.
They want our time and attention, but I don't care for theirs.
>The fundamental issue with the inbox zero concept is that the **inboxes in your life are broader and more demanding than ever before**. In short, your inbox isn't just your work email – **it's literally anything that puts a demand on your time**: your personal inbox, social media, messaging apps, letters, and even phone calls.
- [Wired UK: "Everything you thought you knew about inbox zero is wrong"](https://www.wired.com/story/everything-you-thought-you-knew-about-inbox-zero-is-wrong/)
But for some reason, our society is absolutely obsessed with inboxes. We love inboxes so much that we actually create new inboxes for ourselves. In fact, fellow nerds[^3] who like PKM ([Personal Knowledge Management](https://en.wikipedia.org/wiki/Personal_knowledge_management)) create dozens and dozens of inboxes in Notion, and Obsidian. They create Inbox folders in their Notes app. They even beg developers to add an inbox feature into their podcast app, for crying out loud.
[^3]: nerds like me, by the way. Hello I'm a fellow nerd and a recovering inboxaholic.
For a generation, we were told by David Allen and [Getting Things Done](https://en.wikipedia.org/wiki/Getting_Things_Done) that we must capture and process all our inputs or else we risk missing something[^~]. But the problem[^4] is that we far far underestimated the sheer volume of crap that we have to wade through. Our knees are already buckling under the weight of our current inboxes and yet somehow we've deluded ourselves into thinking that the solution is to add even more inboxes!
[^~]: David Allen's book is called "Getting Things Done: The Art of Stress-Free Productivity". It was so stress-free that it led me to a panic attack and a bout of depression. _Your results may vary._
[^4]: amongst other problems
Then we were told that the solution is filters. Gmail has spam filtering built-in, and it's actually pretty good. But did it get rid of unwanted advertisements in our inboxes? Of course not! Gmail is a free service, offered by a company whose primary source of income is selling ads. Google successfully filtered out obvious Nigerian prince scams, only to sell our usage data and empower spammers to make less obvious scams.
Then we were told that there are all these features to help you personally filter your inboxes. Now we have labels, and smart rules, and tagging and here are guides like **Ten Steps I Used To Get To Inbox Zero And Master My Hustle Business**. The implication is obvious: _If you can't get to inbox zero, it's your fault._ Well I don't buy it anymore.
## Inbox 2.0: The Feed
Then the inbox morphed into its unholy cousin, [the feed](https://en.wikipedia.org/wiki/Web_feed). YouTube used to have a model where you would subscribe to channels and you would get new episodes in your inbox. But now YouTube is an infinite scroll of algorithmically picked content designed to prevent you from ever leaving their site.
It's called the feed because it feeds you with more and more content, and yet it repeatedly leaves you anemic and unfulfilled. The real reason why it's called a feed is because every time you look at the feed you are feeding their service with your vital attention, and you are feeding their wallets with ad revenue.
This is an abusive relationship and you know it.
## The Better Way: Death To Inboxes
There is a better way, but it requires effort, stubborn persistence, and the courage to be weird. **Kill your inboxes.** Mute them and, when possible, remove them altogether. Unsubscribe from email feeds that provide you no value. Delete social media apps that manipulate you into addictive doom scrolling. Refuse to read from news providers who repeatedly hook you in with misleading headlines only to deliver an article designed to stir up your anxiety and rage. Turn off practically all your notifications. In fact, while you're at it, why don't you get rid of your phone...? (Dang, even I'm not courageous enough to be [that weird](https://redeemingproductivity.com/taking-phone-addiction-seriously/)[^j]!)
[^j]: yet?
Be ruthless. They are ferociously attacking your attention span and so you must ferociously defend it.
>Nine times out of ten, the best inbox is called a trash can!
Don't fall into the trap of thinking that you are stronger than this. There's probably a voice inside of you that is saying, _"I don't need to cut out inboxes from my life. I'm fine. That's your problem, not mine. I've got self-control and I can focus."_ Buddy, if that's how you're thinking, then you already lost the battle.
There's an army of marketing geniuses who have honed their skills over several decades to discover exactly how to kick you while you're down. Don't forget they also have a navy of invasive data scientists, and an air force of deceptive PR departments. Yes, you've got discipline and focus, but they've got patience, persistence, and billions of dollars in targeted advertisements. Your willpower and attention span is a finite resource and their straw is gonna drain it dry.
Steve Jobs famously wore the same black turtleneck every day, and supposedly he did this just so that he would have one less decision to make every day. If Steve Jobs understood that his attention was limited then what makes you think you can handle a million decisions every day?
These companies act like they care, yet they demonstrably do not. These people care so little about the general public that they [keep track of when teenage girls delete a selfie just so that they know when she's likely feeling self-conscious and would be more susceptible to a beauty product ad](https://techcrunch.com/2025/04/09/meta-whistleblower-sarah-wynn-williams-says-company-targeted-ads-at-teens-based-on-their-emotional-state/). If they care so little about you, then you should care even less about all the junk they are shoving into your inboxes.
### Curate Your Inboxes
Should you kill every inbox? You can certainly try. Get off grid and go [live in a van down by the river](https://www.youtube.com/watch?v=Xv2VIEY9-A8) if you want. But that doesn't sound very healthy now, does it? After all, [you're a part of this world, aren't you?](https://www.tk421.net/lotr/film/ttt/26.html)
Don't just cut things out of your inboxes. Thoughtfully choose what you will allow **into** your inboxes. There should be a very high bar for what you allow in your inbox. You are the VIP CEO of your life. Everyone must interview for your attention, and the default answer should be no!
**Reward content creators who...:**
1. respect your time and attention.[^g]
2. leave you feeling better than before (in the long run, not just in the moment).
3. choose not to use manipulative tactics even though they might be losing out on cash.
4. focus on quality even when it requires posting less frequently.
5. create content that is actually useful, empowering, and enlightening.
6. inspire you to be a better person.
7. prioritize your well-being over profit.
8. provide a clear value proposition that aligns with your goals and interests.
9. encourage critical thinking and personal growth.
10. promote healthy discussions and diverse perspectives, challenging you to step outside of your thought bubbles.
Set yourself up for success. Save what matters. Trash what doesn't.
[^g]: Videogames are notorious for wasting your time. So much so that gamers made up a word for it: [grinding](https://en.wikipedia.org/wiki/Grinding_(video_games)). Would you permit any other business to intentionally waste your time just so that they can pretend to provide you more value?
### Make FOMO, No Mo'
_What if I miss something, important?_ **You will miss something, and that's what's so great about it.** You'll miss scams, spam, childish celebrity drama, frivolous tech hype, cancerous cancel campaigns, and so so many ads.
The truth is, most of what you think is important, is really just noise. Stop worrying about missing out. Kick [FOMO](https://en.wikipedia.org/wiki/Fear_of_missing_out) to the curb! By eliminating the noise, you can discover what truly matters.
In my time on this earth, I've discovered that important things will surface themselves. They don't **demand** your attention like the petty things in our inboxes. Important things just **are** important. **If it's actually important, then you will probably find it, eventually.** Remember this. Trust it. Feel it. Believe it.
You have a limited number of moments left in your life, and you are utterly surrounded by people who are telling you what to do with the moments you have left. What on earth is more precious than your time? You can earn money. You can accumulate resources. But when you spend your time, there is no refund policy. And you are always spending your time.
>"When you come back [from vacation], you might say, 'Oh my God, there's so much of this [email]'. But then you realize, I didn't even see this email and somehow the world kept spinning."
>- **Merlin Mann**: [Wired UK: "Everything you thought you knew about inbox zero is wrong"](https://www.wired.com/story/everything-you-thought-you-knew-about-inbox-zero-is-wrong/)
### Quit Keeping Up With The Joneses
Quit [keeping up with the Joneses](https://en.wikipedia.org/wiki/Keeping_up_with_the_Joneses). Quit chasing the carrot on the end of that stick. Quit running in the hamster wheel of futility. It's not only exhausting, it's soul-crushing. Your soul needs something more.
The dirty little secret is the Joneses aren't keeping up with themselves. Influencers [pretend to own giant luxurious homes](https://en.wikipedia.org/wiki/Content_house) while slaving to the same hustle culture as the rest of us. They stir up our envy and then sell us products to try to fill the void. The crowd is filled with fake success.
But even genuine success is not all it's cracked up to be. When we study the successful, we so often fall prey to [survivorship bias](https://en.wikipedia.org/wiki/Survivorship_bias). We believe that what happened to work for them has gotta work for me too. Yet we ignore the thousands of others who tried the same thing and failed. We ignore the massive role that luck and timing played[^c] in their success. But the real problem is that we mistakenly think that success will bring us ultimate satisfaction. It won't.
[^c]: In reality, _luck and timing_ is a euphemism for [providence](https://learn.ligonier.org/articles/what-providence).
A [wise Man once said](https://biblehub.com/esv/mark/8.htm) "What does it profit a man to gain the whole world and forfeit his soul?"
---
## The Outbox
What's often missing from our modern understanding of the 'inbox' is its physical counterpart: the outbox. In that bygone era, when you received items from your coworkers, there wasn't just a pile of inbox items, there was an outbox. You were expected to process the items and then put them in the outbox. Then they would be collected and sent to someone else's inbox.
Your outbox is someone else's inbox. Our inboxes are drowning in drivel, but what are you and I putting into our outboxes? What are you putting into someone else's inbox? Do your words bring life or death?
But even the outbox is not what truly matters. What's most important is what is between the inbox and the outbox. What did you do with the items when they were still on your desk? In this mysterious work shift that we call life, we all come in through a great inbox, and one day we will all leave through the final outbox. One day your Boss will look at the work that you did, with the time and resources that you had, and He will say either "Well done, good and faithful servant" or "Depart from me!" What will He say to you and I?
---
## Acknowledgments
- **[Merlin Mann](https://en.wikipedia.org/wiki/Merlin_Mann)**: The original proponent of Inbox Zero. Although I spent the majority of this essay trashing the concept of inbox zero, I do want to acknowledge that Merlin Mann was onto something important. He was one of the first people to recognize that our inboxes were out of control and that we needed to do something about it. I just think his solution (triaging everything) was ultimately inadequate. But apparently, [he realized that before I did](https://www.wired.com/story/everything-you-thought-you-knew-about-inbox-zero-is-wrong/).
- **Reagan Rose**: Huge thank you to Reagan for offering me feedback on this essay. I picked a hyperbolic antagonistic tone, and I was worried that it might be taken the wrong way. Reagan gave me the confidence to lean into that tone and helped me refine my arguments. Check out his work at [RedeemingProductivity.com](https://redeemingproductivity.com/blog/) and on his [YouTube channel](https://www.youtube.com/channel/UCEp5Q6cb6GQr5XIZ_2blTjQ). It's been a wonderful influence on me.
## Recommended Reading
- **[Wired UK: "Everything you thought you knew about inbox zero is wrong"](https://www.wired.com/story/everything-you-thought-you-knew-about-inbox-zero-is-wrong/)**
# It Looks Like AI
Several years ago I went on a hike with friends through a lush tropical forest. We turned the corner and saw a stunning lookout with dense green trees strewn across a wide valley as far as the eye could see. Then a friend of mine said one of the most ludicrous sentences I have ever heard in my life:
>_"Meh. The graphics are better on my PC."_
What in the world? That doesn't make any sense. How would videogame graphics be better than real life? It doesn't matter how many polygons your graphics card can render, there is no way that it can render the infinite polygons of actual reality. Nevertheless, what he said stuck with me.
Fast forward to this week, I went to the zoo and visited the orangutan exhibit and heard another ludicrous sentence, this time from a teenager:
>_"It looks like AI."_
What does that even mean? How could an orangutan look like AI? But then I remembered a phrase that I would often hear when I was a child: _"It looks like CG."_ In the 90s and 2000s it seemed everyone was saying this phrase regularly, myself included. We were all amazed by Toy Story, the first feature-length computer generated animated film. It was stunning to realize that computers could draw but the limitations were obvious. Computers could only really draw smooth shiny objects. But then we saw Sulley's fur in Monster's Inc, and Gollum's stunning performance in The Two Towers and we knew that CG was quickly closing the gap on reality.
So what do we do when reality, actual reality, seems so unreal? When face to face with a strange creature like an orangutan, with long orange hair, far-reaching arms and strange face pouches, maybe it makes sense that one of us would say _"It looks like AI."_ When I was their age, I certainly would have said _"It looks like CG."_
## The Simulation Is Here
We are way past the point where computers can look more real than real life. Don't believe me? Ask yourself how _The Social Network_ (2010) recreated the Winkelvoss Twins with actor Armie Hammer, who is not a twin. Most viewers didn't even know that this was accomplished with CG.

What do we do in a world where we can no longer say _I'll believe it when I see it_? We will always have the thought running through our minds _Is this AI?_ At the moment, these images can only be produced on screens. For a few short years, we'll console ourselves and say _I'll believe it when I see it not on a screen._ But this too is fleeting. We already have [screens that can simulate entire skylines convincingly](https://en.wikipedia.org/wiki/Sphere_(venue)) and [millions of fans who come to "live" concerts of virtual pop stars](https://en.wikipedia.org/wiki/Hatsune_Miku). The virtual is already stepping into the physical.
And so all these years later I think perhaps my friend on that hike wasn't so crazy. Maybe the graphics on his PC are better than the real hike. When I first saw [the mountain in The Witcher 3](https://www.youtube.com/watch?v=JcuascLcO7M), my jaw dropped. It was in fact a view that was more stunning than the view I saw on the hike that day. It looked like an [Ansel Adams photo](https://www.anseladams.com/), absolutely stunning. Except, I hate to burst your bubble, but Ansel Adams' photos weren't exactly reality either. He also artistically used film development techniques to accentuate shadows and highlights to produce a more stylized picture. For better or worse, fake often looks better and real often looks worse.
The really nice thing about my friend's PC... it didn't require an hour long hike. It didn't include mosquito bites, and dirt and sweat and rain. That PC was able to bottle up the beautiful stunning imagery of creation and leave out all the fussy bits. Simulation empowers curated beauty. And I'm not sure that's such a great thing.
On another hike, I woke up early and climbed with friends up to the top of Crouching Lion trail. It was stunning and I had worked up an appetite. We remembered then that Five Guys burgers was opening that day, the first location in Hawaii. We drove nearly an hour to get there and waited in line, another hour behind 200 other eager customers. The burger was massively over priced, nearly $20 for a combo, but I'll tell you it was one of the best meals I've ever had. Why? The tiredness from waking up early, the muscle fatigue from the hike, the long drawn out anticipation of the line. The burger itself was not that amazing. It certainly wasn't $20 amazing, and yet I'd gladly pay more than $20 today to relive that meal. Any simulation would have left out all those fussy bits, and yet, so often, those are the very best parts.
# Curiosity Silenced the Uncurious Cat
**Curiosity killed the cat** or so the saying goes. What does this mean? Be careful. Don't be curious. You just might get yourself hurt. Better to stay at home, safe and sound.
**Except that's not at all what the saying says.** The [full saying](https://en.wikipedia.org/wiki/Curiosity_killed_the_cat) is:
>_"Curiosity killed the cat,
>But satisfaction brought it back."_
Curiosity brings danger, uncertainty, and sometimes even death. But sometimes curiosity brings **satisfaction**. Curiosity requires risk, and risk is the potential for reward. Historically the people who have been the most rewarded are among those who took the greatest risks. (Of course, the ones who have been the most punished are also among those who took the greatest risks.) Wisdom, is the ability to discern which risks are worth taking.
Ironically, this saying has been used for over a hundred years to stunt wisdom, and risk taking, and curiosity! If only we were more curious to see the full saying, we would know what it actually says and means. The wisdom of past generations is hardly wise when it's censored by the foolishness of moderns.
So let's practice a little curiosity and dig just a little deeper now. [Here's the full excerpt](https://en.wikipedia.org/wiki/Curiosity_killed_the_cat#cite_note-5):
>You will find greater values here. We are told:
>"Curiosity killed the cat,
>But satisfaction brought it back."
>It is the same story with groceries.
>"Prices will sell Groceries, but it is always finality that brings the buyer back."
**Bingo!** Here we learn that prices sell groceries, but finality brings the buyer back. When we sell things, we should be considerate of the buyer. Sure, we can take the quick path, lower our prices, and get a ton of customers. This will even sell a lot, but at the end of the day, if your product is crap, the customer isn't coming back. We also see some wisdom for us buyers. When we're enticed by low prices, let's ask ourselves, "Why is the price low? Is it because the quality is even lower?" The low price makes me curious to buy it. Maybe that curiosity will bring satisfaction[^1], but maybe it won't.
[^1]: Here's some wisdom from [another source](https://genius.com/The-rolling-stones-i-cant-get-no-satisfaction-lyrics): _"I can't get no satisfaction."_ Wise words. Here's [some older, wiser words](https://www.biblegateway.com/passage/?search=Ecclesiastes%202&version=NIV): _"I said to myself, “Come now, I will test you with pleasure to find out what is good.” But that also proved to be meaningless."_
So here's the wisdom I get from this whole thing: **Be curious.** And be extra skeptical of anyone who tells you not to be curious. While you're at it, be extra curious of the wisdom of past generations. You just might learn something.
# How to Publish Unlisted Posts in Hugo
# How to Publish Unlisted Posts in Hugo
Sometimes you want to publish a blog post that's accessible via direct URL but doesn't appear in your site's normal navigation or discovery mechanisms. This is useful for sharing draft content with specific people, creating landing pages, or publishing content that you want to keep semi-private.
When creating unlisted posts, you typically have four main concerns:
1. **Search Engine Visibility**: You don't want the post to appear in Google search results
2. **Sitemap Inclusion**: You don't want it listed in your sitemap.xml
3. **RSS Feed Inclusion**: You don't want it appearing in your RSS feeds
4. **Site Listings**: You don't want it showing up on any list pages (homepage recent posts, category pages, tag pages, etc.)
Let's address each of these concerns systematically.
## 1. Preventing Search Engine Indexing
To prevent search engines from indexing your post, you'll need to add a custom parameter to your front matter and modify your site's head partial.
**Step 1: Add the unlisted parameter to your post's front matter:**
```yaml
---
title: "Your Hidden Post"
date: 2025-08-14
unlisted: true # This is a custom parameter defined by you which we will use later.
---
```
**Step 2: Modify your head partial to check for this parameter.**
Find your head partial template (usually at `/layouts/partials/head.html` or `/themes/[theme-name]/layouts/partials/head.html`). If you're using a theme, copy the head partial from your theme to `/layouts/partials/head.html` to override it.
Add this code somewhere in your head partial:
```html
{{ if .Params.unlisted }}
{{ end }}
```
**What this does:** When Hugo processes a page with `unlisted: true` in the front matter, it will add `` to the HTML ``. The `noindex` directive tells search engines not to index the page (so it won't appear in search results), while `nofollow` tells them not to follow any links on the page for crawling purposes.
## 2. Excluding from Sitemap
Hugo provides built-in support for excluding pages from your sitemap. Simply add this to your front matter:
```yaml
sitemap:
disable: true
```
This works automatically - no template modifications needed. Your post will no longer appear as an entry in your site's `sitemap.xml` file. This is important because search engines use sitemaps to discover and index pages on your website. By excluding your post from the sitemap, you're removing one of the primary ways search engines would find your unlisted content, even if they somehow discovered the URL through other means.
## 3. Excluding from RSS Feeds and All List Pages
Hugo provides a powerful built-in solution using the `build.list` parameter. Instead of using `list: false` (which many themes ignore), use:
```yaml
build:
list: never
```
This tells Hugo to exclude the page from *all* page collections, including RSS feeds, homepage listings, section pages, taxonomy pages, and any other list context. The `build.list` parameter has three options:
- `always`: Include the page in all page collections (default)
- `local`: Include the page in local page collections only (useful for headless content sections)
- `never`: Do not include the page in any page collection (perfect for unlisted posts)
## Complete Front Matter Configuration
Here's the complete front matter setup for an unlisted post:
```yaml
---
title: "Your Hidden Post"
date: 2025-08-14
draft: false
unlisted: true
sitemap:
disable: true
build:
list: never
---
```
This configuration ensures your post is:
- Published and accessible via direct URL
- Hidden from search engines
- Excluded from your sitemap
- Removed from all site listings (homepage, RSS feeds, category pages, etc.)
## Testing Your Unlisted Post
To verify everything works correctly:
1. **Direct access**: Confirm the post is accessible via its direct URL
2. **Homepage**: Check that it doesn't appear on your homepage (if it shows recent posts)
3. **Section pages**: Verify it doesn't appear on relevant section pages (like `/posts/`)
4. **Sitemap**: Confirm it's not in your `sitemap.xml`
5. **RSS feeds**: Make sure it's not in your RSS feeds
6. **Search**: Verify it doesn't appear in your site's search results (if you have search functionality)
## Alternative: Using Different Content Types
If you prefer a completely separate approach, you can create unlisted posts as a different content type:
1. Create content at `/content/unlisted/my-post.md`
2. This creates a separate section that won't interfere with your main content
3. You can create custom templates at `/layouts/unlisted/single.html` if needed
## Key Takeaways
- Use a custom `unlisted: true` parameter and modify your head partial to add robots meta tags
- Use `build.list: never` for reliable exclusion from all listings
- The `sitemap.disable` parameter works automatically without modifications
- Only the robots meta tag requires a template change - everything else is built into Hugo
- Always test your unlisted posts across all areas of your site
With Hugo's built-in `build` and `sitemap` options plus a simple head partial modification, creating truly unlisted posts is straightforward and reliable.
# The Marxist, The Capitalist, and The Jealous
The Marxist looks at another who has what he envies
and says "What an injustice!
We workers of the world must unite.
We must seize the means of production
and distribute
from each according to his ability
and to each according to his needs.
And all will be right in the world
when the party rules
and everyone's income is equal, (especially the party leaders)."
The Capitalist looks at another who has what he envies
and says "What an injustice!
We innovators of the world must compete.
We must acquire the means of profit
and capture
from each according to his exploitable value
and to each according to his discretionary income.
And all will be right in the world
when the rule is to party
and everyone's belly is full, (especially the shareholders)."
The Jealous looks at Marxism and Capitalism and says to himself
"Either gun will do."
# There's Poor, and Then There's Capitalist Poor
There's a lot of self-declared [Anti-Capitalists](https://en.wikipedia.org/wiki/Anti-capitalism) in my social media feeds. Fine by me. I like being exposed to thoughts I disagree with because it sharpens my own thinking, and [truth is far more valuable than being right]({{< ref "essays/how-to-always-be-right" >}}). It forces me to wrestle with flaws in my own thinking, and it forces me to search for strong rebuttals.
So I find that quite often I hear the idea that [the rich keep getting richer and the poor keep getting poorer](https://en.wikipedia.org/wiki/The_rich_get_richer_and_the_poor_get_poorer). This simplistic mantra kept rubbing me the wrong way, but I couldn't quite articulate why. While writing [this]({{< ref "essays/the-marxist-the-capitalist-and-the-jealous">}}) I wrote this line critiquing Capitalism:
>[In Capitalism] everyone’s belly is full, (especially the shareholders).
What I'm hoping to highlight in this line is a genuine moral character flaw in Capitalism. Capitalism claims to be purely merit-based and yet there is case after case of ludicrously wealthy individuals making mountains of cash via exploitative working conditions, deceptive marketing practices, and at times straight up fraud.
This is undeniably a symptom of an unhealthy society[^1]. I can hear the Anti-Capitalist countering me by saying "_No, everyone's belly is **not** full. Look at all the poor._" to which I respond:
**Would you rather be a poor Capitalist or a poor Marxist?**
[^1]: I do not disagree with this Marxist critique. What I disagree with is their diagnosis. Income inequality is the great moral evil according to Marxist ideology. I disagree with this for various reasons, which perhaps I'll expand upon in the future.
No matter where you live, being poor objectively sucks. I don't wish poverty on anyone.
But I can tell you without a millisecond of hesitation that I'd rather be poor in America than poor in Venezuela. Between 2008 and 2019, Venezuela had so little food on store shelves that the poor were forced to resort to eating garbage and stray animals. In the same period of time, in America, the price of smart phones dropped dramatically such that [more than half of homeless people in America own a smart phone](https://pmc.ncbi.nlm.nih.gov/articles/PMC6516785/). Being poor in America is awful, but at least there are several homeless shelters in practically every city.
In nearly 250 years of American history, the US has had exactly **one** famine, and it was on an [isolated Alaskan island](https://en.wikipedia.org/wiki/St._Lawrence_Island_famine). And yet in a far shorter period of time the Soviet Union, China, and North Korea had [several famines](https://en.wikipedia.org/wiki/List_of_famines). Worse yet, many if not most of these famines were self-inflicted by ridiculous policies directly inspired by Marxist ideology. In the late 50s, tens of millions of Chinese people starved to death because of poor management of labor and resources. Instead of correcting their systemic issues, the Chinese Communist Party doubled down by [blaming food shortages on the birds and commanding millions of citizens to slaughter birds en masse](https://en.wikipedia.org/wiki/Four_Pests_campaign). This arrogant policy not only did not fix the problem, it actively made the problem far worse! By killing the birds they took away the natural predator of the bugs, and massive swarms of bugs ate their crops. The famine got so abysmally bad in China that people ate tree bark just to feel full. Even cannibalism was rampant.
Why hasn't this happened in America? Is America smarter, better, more fortunate? I don't think so. America has had several food shortages in its history but only one of them became a famine. Why? Because when there is a need, there is an opportunity. When those darn greedy Capitalists see a natural disaster, what do they do every time? Sell a bunch of stuff. If there's a lack of water, then businesses come into the area and sell more water. Many even jack up their prices to ridiculous heights just because they know their customers are desperate and willing to pay practically anything. It's selfish, it's heartless, and yet here we are not starving to death. But it immediately balances itself out. Soon other greedy Capitalists see the same opportunity and sell the same water at a slightly cheaper price. And the market stabilizes.
Do the poor keep getting poorer in America? Absolutely not. The poorest person in America today is far wealthier than the poorest person in America 50 years ago. Today poor American have free ubiquitous access to warm beds, canned food, basic medicine, long-distance communication, vast libraries, and so much more. They certainly do not have it easy. But they absolutely do not have it harder than past generations.
For the vast majority of human civilization, poverty was effectively a death sentence. Only the wealthy had the privilege of living to grow old. Today, the life expectancy of a poor citizen in a Capitalist society is not a whole lot shorter than the life expectancy of a wealthy citizen. So to all the Anti-Capitalists out there, go on keep criticizing Capitalism. It needs your critiques. But remember this, **being Capitalist poor isn't nearly as bad as being non-Capitalist poor.**
# Happy Hurricane Douglas Day!
The year was 2020. Covid was in full swing. My wife and I were married for less than a year. And the grocery stores and hardware stores were flooded with people preparing for the Category 1 Hurricane Douglas.
We had just moved into a micro-apartment on the 11th floor. If the storm hit, it would have been particularly awful for us. The one room studio apartment had a glass wall that faced the ocean. The building didn't even have an enclosed hallway. We would have been forced to shelter in the bathroom or in the stairwell. Looking back, I can see that, quite frankly, we were not prepared at all for a hurricane. But it was coming anyways, and soon, the only thing we could do was wait.
The Hawaiian Islands are arranged in an almost straight line and the path of the hurricane matched the path of the islands almost perfectly. **The storm was set to pass directly over every single island**:
Hurricane Douglas path over the Hawaiian Islands. - CNN
We waited and waited for the worst... Finally I got tired of waiting, walked out onto the balcony and that's when this happened:
I didn't edit this photo at all. It was taken from an iPhone SE. That's just what the sunset actually looked like that day. Those clouds you see are actually the outer rings of Hurricane Douglas. But here is what it looked like on the news:
Hurricane Douglas on NBC News
You can barely even see the islands because they are completely covered by the hurricane. And yet God completely protected us from this storm. [Hurricane Douglas](https://en.wikipedia.org/wiki/Hurricane_Douglas_(2020)) passed within 30 miles of Oahu, but we only got a little bit of rain and some wind gusts. While Maui and Oahu experienced some downed trees and minor damages, there were **no fatalities** or major injuries reported.
## Celebrating Hurricane Douglas Day
When I got married, my dad said to me, "the fun thing about getting married is you get to start your own family traditions." So I decided to start a new family tradition: **Hurricane Douglas Day**. Every year on July 26th, we celebrate the day that Hurricane Douglas passed by Hawaii and God spared us from its full force. But I don't want a lame boring holiday that is just a name. This day has to be special and different from other days. Otherwise, it's just like any other day. So how can we make Hurricane Douglas Day special? Sugary, swirly drinks of course! Every year my wife and I celebrate with a fun treat, a Frosty from Wendy's, or a smoothie or some other delicious drink.
>*"As for you, **you meant evil against me, but God meant it for good**, to bring it about that many people should be kept alive, as they are today."* - Genesis 50:20 (ESV)
What should have been a devastating hurricane turned into easily the most beautiful sunset I have ever seen. **Our God is a God who turns evil into good.** He turns tragedy into therapy. When the world is spinning out of control, and all that is good in the world is being cut into tiny pieces, God turns around and blends it into a delicious treat.
## But What if the Storm Hits?
This time, we escaped the storm. But only this time. In 1992, when Hurricane Iniki hit, we weren't so lucky. It was a Category 4 hurricane that devastated the island of Kauai. It destroyed 1,400 homes and caused $1.8 billion in damages.
Tragedy can and will hit sooner or later. I want to be very clear. I am not saying that God will protect us from every storm. And I am not trying to minimize the pain and suffering that real people experience during real tragedies. I'm not even suggesting that we should _look for the silver lining_ in every situation. Tragedy is tragedy. It hurts, it's painful, and it should be mourned.
No, what I am saying is that **our God redeems tragedy**. He takes the worst of the worst and turns it into something beautiful. Now, He doesn't do this on my schedule but He does, in fact, do it. It is not a matter of if, but when. He **will** wipe away every tear (Revelation 21:4). He **will** make all things new (Revelation 21:5). And He **will** turn our mourning into dancing (Psalm 30:11).
## Don't Forget to Brag About God
So, on this day, I want to brag about God. I want to tell the world how amazing He is. I want to tell you that He is a God who loves us, protects us, and redeems us.
>"He who brags, let him brag in the Lord." - 2 Corinthians 10:17
And I want to encourage you. If and when you are in the midst of the storm, do not forget that your God is with you. Trust in Him. He will make all things right. Look back upon your life and I am sure that you will find moments where God has turned your mourning into dancing. If you can't seem to find them, then keep looking. They are there. Then hold on to those moments. Remember them. Celebrate them. And when the storm passes, don't forget to brag about how amazing our God is.
# You Come From a Family Of Survivors
You come from a family of survivors.
Every single one of your ancestors survived.
They lived through wars, famines, plagues, slavery, unspeakable horrors.
That's a mighty fine lineage you got there.
# How to Build an AI Personal Coach
Have you ever wished you had a personal coach by your side, ready to offer insights and motivation based on your latest thoughts and goals? In this post, we'll explore how to build a simple AI personal coach right on your Mac. This isn't about complex coding; it's about leveraging existing tools to create a smart automation that understands your notes and provides helpful reflections.
## Prerequisites
This guide is designed for anyone interested in AI tinkering, even if you don't have a background in programming. While we'll touch on some technical concepts, we'll make them approachable.
Here's what you'll need to get started:
* **macOS**: This project is built specifically for Apple's macOS operating system.
* **VS Code (or a `plist` editor like Xcode)**: We'll be working with a type of XML file called a `plist`. VS Code with the "[Property List Editor](https://marketplace.visualstudio.com/items?itemName=ivhernandez.vscode-plist)" extension offers a user-friendly graphical interface for this, but you can also use Apple's Xcode or any other `plist` editor.
* [Apple Shortcuts](https://support.apple.com/guide/shortcuts/welcome/ios): A built-in macOS application that allows you to create custom workflows and automations.
* [Ollama](https://ollama.readthedocs.io/en/quickstart/#model-library): A fantastic tool that lets you run large language models (LLMs) locally on your machine.
* **Markdown Knowledge**: Our personal notes will be written in Markdown, a lightweight markup language for creating formatted text using a plain-text editor. You can use any text editor, including VS Code, or a dedicated Markdown editor like Obsidian, to manage your notes.
## Goal
Our primary goal for this project is to build an automation that will:
* **Read your latest personal notes**: These notes will be structured as Markdown files in a designated folder hierarchy.
* **Write a helpful note**: The automation will generate a new note in the persona of a personal coach, offering insights or questions based on the context of your personal notes.
## Components
To achieve our goal, we'll combine a few key components:
* **Scheduled Job using `launchd`**: We'll set up a daily job that runs every morning at 8 AM. This job will be managed by `launchd`, macOS's system for managing daemons and agents.
* **Markdown Files for Notes**: Your personal notes will be kept as simple Markdown files. This makes them easy to read, edit, and process.
* **Large Language Model (LLM)**: The core intelligence of our coach will come from an LLM. The scheduled job will prompt this LLM using your personal notes as context, guiding it to generate a coach-like response.
## Apple Shortcuts
For simplicity and to integrate seamlessly with macOS, our `launchd` job will directly call an Apple Shortcut. This Shortcut will then handle the interaction with the LLM. (But just so you know, `launchd` can run any script or command you want, e.g. a Python script).
Inside the Shortcut, we'll use the "Get Contents of URL" action. This action is incredibly versatile and effectively acts like the `curl` command in your terminal, allowing the Shortcut to send requests to and receive responses from our locally running LLM via Ollama. The response from Ollama will then be piped into a "Send Message" action within Shortcuts, allowing it to automatically send an iMessage to yourself. We will also write a Markdown message for the day with your agenda, incorporating the coach's message.
## Why Use Ollama?
The choice of Ollama is crucial for one main reason: **privacy**.
Ollama allows you to run large language models **directly on your own machine**. This means your personal notes, which will be fed to the LLM as context, never leave your computer. You can include anything in your notes—your deepest thoughts, sensitive information, or private goals—without having to worry about someone else potentially reading them in the cloud. Your data stays yours, providing peace of mind.
### Personal Cloud Compute
If you prefer to avoid the initial setup complexity of Ollama, Apple offers an alternative with its new "Use Model" command. This command provides two options for running models:
* **Local Model**: You can run a smaller, less powerful model directly on your device. While convenient, these models are generally "dumber" compared to larger counterparts.
* **Apple's Bigger Model in "Personal Cloud Compute"**: This is an intriguing option. With Personal Cloud Compute, Apple runs a larger model in the cloud. However, Apple has engineered this service with significant technical safeguards to ensure that **no one**, not even Apple itself, can read your prompts or the model's responses. This is a great choice if you can trust Apple's commitment to your privacy, offering a balance between performance and data security.
## Why Use `launchd`?
You might be wondering why we're using `launchd` to schedule our job instead of something simpler.
Unfortunately, Apple Shortcuts on macOS currently lacks an "Automations" tab, which means there's no built-in way to schedule recurring jobs directly within Shortcuts. Many familiar with command-line tools might think of `cron`, but `launchd` offers a more modern and deeply integrated solution for macOS. It's generally considered easier to use than `cron` for many common scheduling tasks and offers better resource management.
## What is a `plist`?
`launchd` defines its automation tasks using a specific XML format called a `plist` (property list). While a `plist` is essentially a text file, directly editing XML can be tedious and prone to errors.
For our example, we'll leverage the "Property List Editor" extension in VS Code. This extension intelligently reads the XML structure of the `plist` file and presents it as an easy-to-read and easy-to-use graphical user interface (GUI). This makes configuring our scheduled job much simpler and less intimidating.
## Structure of Personal Notes
One of the great values of Large Language Models (LLMs) is their ability to understand natural language. You no longer need to follow a strict, rigid format to communicate with computers. You can "speak" to them in everyday language, and if your input is a little unclear, the LLM can often make an educated guess about what you're trying to convey.
However, just like with a real human, if your input is really disorganized and unclear, the LLM will struggle to satisfy your request effectively. The clearer and more structured your prompt is, the more likely the LLM is to provide a helpful and accurate response. For this reason, we highly recommend giving your personal notes some intentional structure.
Here's a suggested folder hierarchy for your personal notes:
```
Personal Notes/
├── Time-Based/
│ ├── 2025/
│ │ ├── 07_July/
│ │ │ ├── Week_29/
│ │ │ │ ├── 2025-07-20_Sunday.md
│ │ │ │ └── ...
│ │ │ └── ...
│ │ └── ...
│ └── ...
├── Goals/
│ ├── Annual_Goals/
│ │ ├── 2025_Goals.md
│ │ └── ...
│ ├── Quarterly_Goals/
│ │ ├── Q3_2025_Goals.md
│ │ └── ...
│ └── Long-Term_Goals.md
├── Roles_and_Projects/
│ ├── [Your Role 1 Name]/
│ │ ├── Project_A/
│ │ │ ├── Task_1.md
│ │ │ ├── Task_2.md
│ │ │ └── ...
│ │ ├── Project_B/
│ │ │ └── ...
│ │ └── ...
│ ├── [Your Role 2 Name]/
│ │ ├── Project_X/
│ │ │ └── ...
│ │ └── ...
│ └── ...
├── Contacts/
│ ├── John_Doe.md
│ ├── Jane_Smith.md
│ └── ...
└── Insights/
├── Idea_1.md
├── Learning_Summary.md
└── ...
```
## Building the Personal Coach Automation: Step-by-Step
Now that we understand the components and recommended note structure, let's dive into building your AI Personal Coach.
### Step 1: Install and Set Up Ollama
First, we need to get Ollama running on your Mac and download a language model.
1. **Download Ollama**: Visit the official Ollama website ([https://ollama.com/](https://ollama.com/)) and download the macOS application.
2. **Install Ollama**: Drag the downloaded `.app` file to your Applications folder.
3. **Run Ollama**: Open Ollama from your Applications folder. It will typically run in the background. You'll see a small Ollama icon in your menu bar.
4. **Download a Model**: Open your Terminal application (you can find it in `Applications/Utilities/Terminal.app`). We'll download a popular and relatively small model called Llama 2. Type the following command and press Enter:
```bash
ollama run llama2
```
Ollama will automatically download the Llama 2 model. This might take some time depending on your internet connection. Once downloaded, you'll see a prompt where you can chat with Llama 2 directly in your terminal. You can type ` /bye` and press Enter to exit the chat.
### Step 2: Organize Your Personal Notes
Now, let's set up the foundation for your AI coach's insights: your personal notes.
1. **Create the `Personal Notes` Folder**: In your preferred location (e.g., your Documents folder), create a new folder named `Personal Notes`. This will be the root of your note-taking system.
2. **Implement the Suggested Hierarchy**: Inside the `Personal Notes` folder, create the subfolders as outlined in the "Structure of Personal Notes" section (e.g., `Time-Based`, `Goals`, `Roles_and_Projects`, `Contacts`, `Insights`).
3. **Start Populating Your Notes**: Begin writing your notes in Markdown files within this structure. For example, create a file for today's date in `Personal Notes/Time-Based/2025/07_July/Week_29/2025-07-23_Wednesday.md`. Add some thoughts, reflections, or tasks for the day. The more detailed your notes, the better context your AI coach will have.
### Step 3: Create the Apple Shortcut
This is where we'll build the logic that reads your notes, interacts with Ollama, and delivers the coaching message.
1. **Open the Shortcuts App**: You can find it in your Applications folder.
2. **Create a New Shortcut**: Click the `+` icon in the toolbar or go to `File > New Shortcut`. Name your shortcut something descriptive, like "Daily AI Coach".
3. **Get Today's Notes**:
* Add an action: Search for "Get Current Date".
* Add an action: Search for "Format Date". Set the format to `YYYY-MM-DD`. This will give us `2025-07-23`.
* Add an action: Search for "Format Date" again. Set the format to "Full Day of Week" (e.g., "Wednesday").
* Add an action: Search for "Combine Text". Combine the two formatted dates with an underscore in between (e.g., `2025-07-23_Wednesday`). This will be our daily note filename.
* Add an action: Search for "Get Contents of Folder". Select your `Personal Notes/Time-Based/[Current Year]/[Current Month]/[Current Week]/` folder. *(Note: You'll need to manually update the year, month, and week paths in the Shortcut's folder selection, or use more advanced Shortcuts logic to dynamically determine the path based on the current date, which is beyond the scope of this beginner guide but worth exploring later).*
* Add an action: Search for "Filter Files". Set it to `Where Name Is [Combined Date Variable].md`. This will ensure you only get today's specific note.
* Add an action: Search for "Get Contents of File". This will read the content of your daily note.
* Add an action: Search for "Combine Text". Combine the output of "Get Contents of File". If you have multiple daily notes (e.g., one for morning thoughts, one for evening summary), this step will merge them.
4. **Craft the LLM Prompt**:
* Add an action: Search for "Text". In this text block, write your prompt for the AI coach. Here's a suggested prompt; feel free to modify it to your liking:
```
You are a supportive and insightful personal coach. Your role is to review the following notes from your coachee, provide encouraging insights, ask reflective questions, and suggest actionable steps for the day. Be concise, empathetic, and always end with a positive affirmation.
Coachee's Notes:
[Insert Combined Text Variable from previous step here]
```
* Drag the "Combined Text" variable (from step 3) into the prompt text block where indicated.
5. **Call Ollama**:
* Add an action: Search for "Get Contents of URL".
* Set **URL**: `http://localhost:11434/api/generate`
* Set **Method**: `POST`
* Click on **Headers** to add:
* `Content-Type`: `application/json`
* Click on **Request Body** and select `JSON`.
* Add the following key-value pairs. For the `prompt` value, drag in your "Text" variable containing the crafted prompt.
```json
{
"model": "llama2",
"prompt": "[Your Prompt Text Variable]",
"stream": false
}
```
* Make sure `stream` is `false` so you get the full response at once.
6. **Process Ollama's Response**:
* Add an action: Search for "Get Dictionary from Input". This will parse the JSON response from Ollama.
* Add an action: Search for "Get Value for Key". Select "Dictionary" as the input, and type `response` as the key. The LLM's generated coaching message will be under this key.
7. **Send iMessage to Yourself**:
* Add an action: Search for "Send Message".
* For **Recipients**, select your contact card or type in your Apple ID email/phone number to send the message to yourself.
* For **Message**, drag in the variable containing the "response" from the previous step.
8. **Write Daily Agenda Note**:
* Add an action: Search for "Text". Create a new text block that will form your daily agenda. You can include today's date, some static text, and the AI coach's message. For example:
```
# Daily Agenda - [Current Date (Long Format Variable)]
## Coach's Message:
[AI Coach Response Variable]
## My Plan for Today:
- [ ]
- [ ]
```
* Drag in the "Current Date (Long Format)" variable (from earlier in step 3) and the "AI Coach Response" variable (from step 6) into this text block.
* Add an action: Search for "Create Note" or "Append to Note". If you want a new note each day, use "Create Note". If you have a running daily agenda note you want to update, use "Append to Note" and specify that note. For "Create Note", set the title to `Daily Agenda - [Current Date (YYYY-MM-DD Variable)]` and the body to your newly created agenda text.
9. **Test Your Shortcut**: Run the Shortcut once from the Shortcuts app to ensure it works as expected. Check your iMessages and your notes app!
### Step 4: Create the `launchd` `plist` File
Now, let's schedule this Shortcut to run automatically every morning.
1. **Open VS Code**: Navigate to your `~/Library/LaunchAgents/` folder. This folder might be hidden. You can access it by opening Finder, pressing `Cmd + Shift + G`, and typing `~/Library/LaunchAgents/`.
2. **Create a New `plist` File**: In this `LaunchAgents` folder, create a new file named `com.yourusername.dailycoach.plist` (replace `yourusername` with your actual macOS username or any unique identifier).
3. **Edit the `plist` Content**: Copy and paste the following XML into your new `plist` file. Remember to replace `"Daily AI Coach"` with the exact name of your Apple Shortcut.
```xml
Labelcom.yourusername.dailycoachProgramArguments/usr/bin/shortcutsrunDaily AI CoachStartCalendarIntervalHour8Minute0StandardOutput/tmp/com.yourusername.dailycoach.logStandardError/tmp/com.yourusername.dailycoach.error
```
**Explanation of Keys:**
* **Label**: A unique identifier for your job.
* **ProgramArguments**: Specifies the command to run. Here, it's calling the `shortcuts` command-line tool to `run` your "Daily AI Coach" Shortcut.
* **StartCalendarInterval**: Defines the schedule. `Hour` 8 and `Minute` 0 means it will run every day at 8:00 AM.
* **StandardOutput** and **StandardError**: These are optional but highly recommended for debugging. They direct any output or errors from your script to log files in the `/tmp/` directory.
If you're using the "Property List Editor" extension in VS Code, it will present this XML in a much more readable GUI, where you can easily fill in the values.
### Step 5: Load the `launchd` Job
Once your `plist` file is saved, you need to tell `launchd` to load it.
1. **Open Terminal**: (If you closed it, open it again from `Applications/Utilities/Terminal.app`).
2. **Load the `plist`**: Type the following command and press Enter (replace `yourusername` with your actual macOS username):
```bash
launchctl load ~/Library/LaunchAgents/com.yourusername.dailycoach.plist
```
If there are no errors, the command will complete silently.
3. **Test the Job (Optional)**: To run the job immediately without waiting for 8 AM, you can use:
```bash
launchctl start com.yourusername.dailycoach
```
Check your iMessages and notes to see if the coach message appeared.
4. **Unload (if needed for changes)**: If you need to make changes to your `plist` file, you must first unload it, make the changes, and then load it again:
```bash
launchctl unload ~/Library/LaunchAgents/com.yourusername.dailycoach.plist
# Make your changes to the .plist file
launchctl load ~/Library/LaunchAgents/com.yourusername.dailycoach.plist
```
### Step 6: Testing and Refinement
Your AI Personal Coach automation is now set up!
* **Daily Check**: Each morning at 8:00 AM, your Shortcut should run, process your notes, get a coaching message from Ollama, and send it to you via iMessage, also generating your daily agenda note.
* **Refining Your Prompt**: The quality of your coach's messages heavily depends on the prompt you give the LLM in the Apple Shortcut. Experiment with different phrasing. You might want to ask it to focus on specific aspects (e.g., "focus on my goals for the week," "provide a motivational quote," "help me prioritize my tasks").
* **Checking Logs**: If something isn't working, check the log files created by your `launchd` job in `/tmp/` (e.g., `com.yourusername.dailycoach.log` and `com.yourusername.dailycoach.error`). These files can provide clues about what went wrong.
---
You've now built your very own AI personal coach, right on your Mac! This project demonstrates the power of combining simple, accessible tools to create a personalized, privacy-focused automation that supports your daily reflections and growth. Enjoy your new digital coach!
# macOS 26's Hidden Speechify Killer: Accessibility Reader
Apple's macOS 26 introduces a powerful, yet frustratingly hidden, accessibility feature that could potentially "Sherlock" some of the leading voice reader applications like Readwise Reader, Speechify, and ElevenLabs' _ElevenReader_. This new addition is called **Accessibility Reader**, and it brings high-quality text-to-speech capabilities directly to your Mac at no extra charge.
## What Makes Accessibility Reader So Good?
The Accessibility Reader is a truly fantastic feature for several reasons:
* **Cost-Free:** It's built right into macOS 26, meaning there's no additional cost to access its powerful features.
* **On-Device Processing:** This feature appears to run entirely on your device, eliminating the need for an internet connection. This ensures privacy and consistent performance regardless of your network availability.
* **High-Quality Text-to-Speech:** It boasts a high-quality text-to-speech voice that can read any text on your computer, making it a viable alternative to dedicated reader apps.
* **Intuitive User Interface (UI):** Beyond just reading, the Accessibility Reader offers a well-designed UI. It highlights the text being read, providing a visual cue that enhances the reading experience.
* **Comprehensive Playback Controls:** You get full control over the reading experience, including:
* Speed adjustments (speed up or slow down)
* Fast forward and rewind
* The ability to jump to any part of the text
* **Text Formatting Options:** The reader also allows you to format the text within its interface, ensuring a pleasant and customizable reading experience.
In essence, it's a remarkably full-featured text-to-speech reader that offers a lot of value.
## The Frustrating Path to Discovery
Despite its robust features, the Accessibility Reader is remarkably difficult to find and activate on macOS. So far, the only method that I discovered involves a cumbersome multi-step process:
1. **Highlight Text:** First, you must highlight the text you wish to have read aloud.
2. **Right-Click (Context Menu):** Then, you right-click on the highlighted text.
3. **Locate "Speech" Submenu:** Sometimes (I repeat sometimes) a submenu named "Speech" will appear in the right-click menu. It's not always there, making the feature unreliable to access.
4. **Click "Start Speaking":** If the "Speech" submenu is present, you then click "Start Speaking." At this point, Apple's voice reader immediately begins to read the selected text aloud, and a floating UI with basic play controls appears.
5. **Open Accessibility Reader App:** The final and most obscure step involves clicking a button within this floating UI that resembles a sheet of paper. Clicking this button will then open the dedicated Accessibility Reader app.
This long, cumbersome method is currently the only way I've found to open this otherwise excellent feature. Adding to the mystery, the Accessibility Reader app is not found in the Applications folder, reinforcing its hidden nature.
## Key Caveats and Limitations
The biggest hurdle for the Accessibility Reader is its inconsistent availability:
* **Inconsistent Right-Click Menu Appearance:** The "Speech" submenu in the right-click context menu does not consistently appear, making it impossible to rely on for regular use. There's no clear indication of when it will or won't be available. Under, the hood, Apple is automatically adding this feature for any app using standard macOS text rendering, but the problem is not every app or website is using macOS's standard text rendering. This is a huge bummer for users (especially those who rely on text-to-speech for accessibility reasons) because it means the feature is not universally available across all applications. Users shouldn't have to know or care about the underlying tech used by each app in order to know whether they can use a feature or not.
* **No Keyboard Shortcut:** Currently, there's no dedicated keyboard shortcut to activate the feature, further hindering quick access.
* **Custom UI Frameworks:** The feature generally works across macOS apps that use standard UI frameworks. However, it *does not* work with apps that utilize custom UI frameworks, such as Obsidian or Visual Studio Code. In these applications, the "Start Speaking" option simply won't appear.
* **Web Apps and Google Docs:** Similarly, if you're trying to read text from within Google Docs or certain other web applications, the "Start Speaking" button will often be absent.
## Conclusion
As much as I've spent time criticizing how difficult it is to find and start using this tool, once you do manage to get it running, the Accessibility Reader is a fantastic feature. It offers a level of quality and control that rivals many premium text-to-speech applications yet it has not additional cost and it doesn't require an internet connection. 👍 I wonder if it will be a part of my daily toolkit.
# My Takeaways From "Dawnshard" by Brandon Sanderson
I recently finished "Dawnshard" by Brandon Sanderson. It was... fine. I don't think it's a bad book. I think I probably just have Sanderson fatigue after reading Stormlight book 5. Dawnshard is basically Stormlight 3.5 . For some reason I missed this book so I'm reading it out of order, which might be part of the why I'm not so excited by it. Perhaps I would have been more excited about it, if I read it 4 or 5 years ago.
Now that we got that out of the way, let's move on to what I really wanted to talk about in this post: my takeaways from this book.
> **NOTE**: This post doesn't assume you know or care about any of these books or characters. (While I'd love it if you read these books as well, you might feel you have something better to do with your life than catch up on 5 or 6 thousand pages.) Because this post is about book 3.5 in a series, **there will be some light spoilers** of earlier books.
## My Takeaways
Rysn is a type of character that we don't see very often lately. *A strong female character?* Uh, no. We see a billion of those lately. *A paraplegic?* Well, uh yeah actually she is a paraplegic and we don't see many paraplegic characters lately, or ever. But that wasn't the thing that stood out to me.
You see, I've followed Rysn's character for just about a decade. I remember her before she was a paraplegic. No doubt, she is one now, and it is a very big part of her journey, but I don't think it's the biggest thing that stands out to me, at the moment. What stands out to me at the moment? Rysn is a kind of character that is so rarely seen lately.
**Rysn is an unashamed capitalist.**
## Rysn the Merchant
A brief recap of Rysn's journey up until this book.
Rysn was first introduced as a shrewd, opportunistic merchant in *The Way of Kings*. She's always been driven by profit, sure, but it's never been portrayed as *evil*. In fact, it's often been presented as a necessary part of how she navigates a difficult and often unfair world. She's not some mustache-twirling villain hoarding wealth. She's someone who sees opportunities, takes risks, and works hard to improve her position. And, importantly, she's *good* at it.
Now, a lot of modern narratives seem to treat anyone with a business sense as inherently suspect, or even outright villainous. It’s become almost automatic to paint anyone pursuing profit as greedy and exploitative. And I get it – there’s plenty of bad behavior out there. But Rysn isn’t like that. Her pursuit of profit isn’t at the expense of others. It’s often *because* of her understanding of others.
Think about it: she provides goods and services people need, often at reasonable prices. She creates jobs. She invests in her community. And she does all of this while being, frankly, incredibly likeable. She’s funny, she’s witty, and she genuinely cares about the people around her.
This is the thing that gets me. We've been conditioned to think that capitalism and empathy are mutually exclusive. That being a successful businessperson requires a cutthroat attitude and a willingness to exploit others. But Rysn demonstrates the opposite. Her success *comes* from her empathy. She understands what people want, what they need, and she provides it. She’s not taking advantage of anyone; she’s fulfilling a need.
>Most of Rysn's contemporaries entered a discussion asking, "What can I get from this?" Rysn had been disabused of that notion early in her training. Her babsk taught a different way of seeing the world training her to ask, "**What need can I fulfill?** That was the true purpose of a merchant, to find complimentary needs, then bridge the distance between them so everyone benefited. It wasn't about what you could get from people, but what you could get for them that made a successful merchant. And everyone had needs, even queens.
>
>“It wasn’t about what you could get **from** people, but what you could get **for** them that made a successful merchant.”
>
>“People talked about wealth, and how greed was such a terrible thing—and it could be dangerous, true. Yet the ambition of someone who had nothing to rise to a new station should not be easily dismissed or thought simplistic. There was so much more to it.”
There's a fantastic example of this in an earlier book in the series. Rysn's mentor, *Vstim*, was negotiating a deal for some grain when it was discovered that the grain was infested with worms. Obviously, that would kill the deal, right? Wrong. Vstim intentionally bought the grain despite the infestation. Why? Later, he resold this grain to the Hexi nomads. The key to his strategy was understanding the Hexi culture: their priestly class had taken oaths not to eat flesh, but they did not consider grubs and insects to be "animal"—to them, such creatures were classified as plants. As a result, the Hexi valued the grain more because it contained the worms, making it a delicacy or at least more desirable for their dietary restrictions. This clever trade demonstrated Vstim's deep knowledge of other cultures and his ability to turn an apparent disadvantage into a profitable opportunity.
**A successful capitalist must understand others' wants and needs. A successful capitalist is not less empathetic, but MORE empathetic.**
It's refreshing to see a character who isn't ashamed of her ambition and her business acumen. Like her mentor, Rysn doesn't apologize for wanting to be successful. She just *is* successful, and she does it in a way that benefits everyone involved. She's a walking, talking argument against the simplistic “capitalism = bad” narrative that's so prevalent in a lot of storytelling these days.
## What Does This Mean?
I'm not trying to say that *all* businesses are inherently good. Of course, there are bad actors out there. But Rysn’s character, and Sanderson’s portrayal of her, reminds us that capitalism doesn’t have to be synonymous with greed. In fact, the best merchants, the ones who truly thrive, are often the most empathetic. They understand that long-term success isn't about squeezing every last drop of profit from a transaction; it’s about building relationships and **providing value** to others.
It’s a subtle point, maybe, but it’s a really important one. It’s a reminder that pursuing your ambitions doesn't have to mean sacrificing your values. And that sometimes, the most successful people are the ones who understand that helping others is the best way to help yourself. I think that's a message worth considering, especially in a world that often seems to be at war with itself.
## Final Thoughts
I'm looking forward to seeing where Rysn's journey takes her next. And I'm hoping that more authors will take note of her example and start portraying business owners in a more nuanced and positive light. It’s a refreshing change of pace.
# AI Is a Tool. Are You a Tool?
## Introduction
For most of human existence, most humans had no footwear. It was miserable. Especially when you remember that there were also no antibiotics. Sooner or later you were bound to step on something sharp, and get an infected cut. Such an infection could get so bad that you could be forced to lose your foot or else die. So obviously there was a strong incentive to make and wear footwear.
People did wear footwear. But the truth is not very many people wore footwear because it was simply too expensive. Why? Lasting. This is the process of attaching the top part of the shoe to the bottom sole. This is highly skilled and labor intensive. A professional laster would need to train for several years, and even the best laster could only last about 50 shoes per day.
That is until [Jan Ernst Matzelliger](https://en.wikipedia.org/wiki/Jan_Ernst_Matzeliger) invented the [automated lasting machine](https://en.wikipedia.org/wiki/Automated_lasting_machine "Automated lasting machine"). A single machine could last 150 to 700 shoes per day, dramatically lowering the cost of shoes. For the first time in human history, the majority of people had access to footwear.
## It's Just a Tool
Why do I share this story in a post about AI?
A few years ago, I was working when a coworker and I noticed that we were wearing the exact same pair of shoes. We laughed, realized that we both shopped at Walmart and moved on with our lives.
Here's what we didn't do. We didn't complain that machines put several skilled hand lasters out of work. We didn't lament that the machines sucked the humanity out of footwear and worry if artistry will be forever dead. We were both happy to have shoes available at a ridiculously low price.
Did Matzeliger's invention put hand lasters out of a job? Absolutely. (The spell check on my computer doesn't even recognize that *laster* is a word.) Did his invention make the world a better place today? Absolutely. Did his invention destroy all art in footwear? Heck no. People still make and wear beautifully crafted shoes. Matzeliger's automatic lasting machine is just a tool and so is AI.
## AI Is Just Another Tool
Last night I found [this video](https://www.youtube.com/watch?v=9Ch4a6ffPZY&pp=ygUWaG93IHRvIHNwb3QgYWkgd3JpdGluZw%3D%3D) claiming **I Can Spot AI Writing Instantly — Here’s How You Can Too**. Aside from the fact that he's making an unfalsifiable statement, the biggest problem I have with this video is that it doesn't matter. In the 80s and 90s we got spell check. Here's a question: *Can you tell which pieces of writing were written with the help of spell check and which weren't?* If that sounds like a dumb question maybe it's because none of us care if spell check was used.
And in a few short years, **none of us will care if AI was used to create a writing**. What will we care about? The same thing that we always cared about. The actual content of the writing. Does the writing convey a message worth reading?
Here's a fun way to waste your time. I used AI to help me write roughly half of the blog posts on this site. Can you guess which ones they are?
It doesn't matter if AI was used or not used. It's just a tool. An implementation detail. What matters is the actual quality of the work. What matters is how you use the tool.
## Copilot vs Agent
So many people are quick to denigrate anyone who uses AI without even acknowledging that there is more than one way to use AI. So many think that *using AI* just means *Hey dingus, write my blog post for me.* But [AI is not human]({{< ref "ai-is-not-human-but-we-sure-think-it-is" >}}) so of course it's not going to have more personality than a human.
What is AI good for then? Why even use it? **Because AI is a tool.** Tools *help* you do things, they can't do them for you. This is why I actually like that so many AI products call themselves *copilot*. That's a fairly good description. They can **co**-pilot. They can't do it for you. That's also why I'm not such a fan of using the phrase *agent*[^@] to describe AI. A copilot is here to help you, an agent is here to replace you. But they won't replace you, because [you are not replaceable]({{< ref "ai-is-human-intelligence-applied" >}}).[^!]
[^!]: Also, don't forget that in The Matrix, the agents are the bad guys! C'mon!
[^@]: What we're calling agents today, we used to just call *automations* or y'know... *software*.
## "You're Holding It Wrong": How to Use AI
So what is the right way to use AI? Well the first thing to realize is that **you don't have to use AI**. Use whatever tools you want. If you don't want to use AI, don't use it. But if you do want to use it, then that is totally valid.
But if you're going to use it, **use it for the things that it's good at**. Just like any other tool. You wouldn't use a hammer to cut wood, so don't use AI to write your blog posts for you. Experiment, try things and discover what the tool is good at.
In my practice, I've found that AI is terrible at:
- coming up with original ideas
- writing in my voice
- writting in a way that is genuine and authentic
But AI is really good at:
- Converting ideas from one format to another
- Generating outlines
- Summarizing long texts
And AI is kinda good at:
- Critiquing my writing
- Brainstorming ideas
- Writing rough drafts from an outline
When I write a post, I never have the AI write everything for me. Instead I:
- convert my scattered notes into an outline
- expand my outline into a rough draft
- ask it to offer editing suggestions
**Every single time that it writes something, I read it and decide if it stays or goes.** Because at the end of the day, each post has my name on it. If that post sucks, I get all the blame.
## Are You a Tool?
Are you asking AI to do your work for you? Then you are asking a tool to replace you. You are being a tool. But if you're using AI to help you do your work, then you are using a tool. You are not a tool. You are a craftsman, an artist, a creator. You are a human being.
Don't be a tool. Use tools. That's a very human thing to do.
# Why Do I Write?
*Why do I write?* This is a question that I have been asking myself more often lately, which makes a lot of sense because I have been trying to write more often on this site. Ideally, I'd like to write something every day (at least something small). \
\
But I'll be honest, it can be quite challenging to write every day. Not because I have writer's block. In fact, I find that I have too many things to say, and it's more important that I edit myself and choose words that are worth saying.
No, the current problem that I have with writing is that I'm not getting a ton of feedback. I write, I post... and then not a whole lot happens. My posts don't go viral. I don't have a life changing experience. And I can't help but ask myself *was this worth all the effort?* So I think it's valuable and worth it to ask yourself *What are the benefits?* In my case, now I'll ask myself *Why do I write?*
## Insufficient Reasons
When I started this site, I thought it was going to be a *portfolio site* to help me get a job in software engineering. That hasn't really panned out yet. For whatever reason, that's not a big enough motivator for me to write. I suppose it feels contrived to me and for some reason my personality can't stand anything that feels contrived.
I've also discovered that clicks and likes are not that great of a motivator either. *Fame* is overrated. Fame doesn't buy groceries or pay bills. Too much fame actually **lowers** your quality of life. And in this divisive age, no one is universally liked. So the more famous your are, the more infamous you are. Someone is going to dislike you. And someone is going to be crazy enough to do something horrible like SWAT you. I am extremely uninterested in being famous.
Another motivation I see in myself is *recognition*. For years, I thought this was the same thing as *fame*. I ultimately realized that they are not the same thing, only to later realize that they are close enough. Fame is primarily focused on getting others to like or notice you, whereas recognition is focused on getting others to appreciate you and your contributions. I can have recognition without fame. I could be obscure enough that strangers won't recognize me on the sidewalk, yet when I walk into a room of people interested in the same field as me, they could recognize who I am and what I have done. For years, recognition seemed more appealing to me, but eventually I realized that it stimulates my ego in the same way as fame.
## Self Expression
Self expression. I like writing on this site. It feels like the older better days of the internet, when we were allowed to own our spaces. We could be unique and weird. We could deck out our MySpace pages with awful neon colors and terrible design. We weren't shackled by Facebook, Tik Tok and YouTube. It's been really nice to find freedom on this site again. I really think more people should have a personal site again.
## Self Improvement
I'm attracted to the idea of *morning pages* from [The Artist's Way](https://en.wikipedia.org/wiki/The_Artist%27s_Way). I like the idea of consistent practices. Gradual improvement over time. I like the catharsis and clarity that I get from writing. I like to exercise the muscle between my ears. I like exploring and discovering ideas.
I like the idea to **do something difficult every day**. I like the hope that this hard work will lead to some improvement and benefits in the long run. I like the feeling of accomplishment of achieving something difficult. Writing these little posts is hardly a difficult thing, but doing it regularly, daily even, even when I don't feel motivated, now that is quite a bit more difficult.
## Community
I spent quite a bit of time talking down on fame and recognition. I even pointed to how they are often just pointing to an ego boost. But I hope you don't come away from this thinking that you shouldn't want others to see your work at all. Some people have this idea that creative endeavors should just be for yourself and no one else. How is it less selfish to write a good book and never share it with the world? Sure you have avoided the vain ego boost of praise-chasing, but you have devoted thousands of hours to an endeavor designed to please no one else except yourself. I also, once agreed with this idea that art should be made for yourself and no one else. But I don't buy it anymore.
Now I know longer want fame. I don't even want recognition (at least that's not the primary thing that I want). But what I'm looking for is **community**. I want to benefit others and to discover what others have to offer. I ought to [spend and be spent](https://biblehub.com/2_corinthians/12-15.htm).
## Motivated By Writing
Over time, I've discovered that I need to find a reason inherent in the action itself. Fame will rise and fall. So will popularity, recognition, internet traffic, revenue and whatever else. The world will change whether I like it or not. So if I want to find motivation to write, I need to find a motivation that is itself rooted in writing.
# Actually Useful AI: Modern Search
## Introduction: New Dog, Old Tricks
It's funny how history repeats itself. Every time we get a groundbreaking new technology, our first instinct is often to just use it for the old things we were already doing, just maybe a little bit better. Think about movies back in the day. When they first came out, filmmakers basically just pointed the camera at a stage play. All the techniques, the blocking, the acting – it was all just lifted from the theater. It took time for them to figure out what _only_ a movie could do, things like close-ups, dynamic editing, and special effects that are impossible on stage.
Likewise, when the current wave of powerful Large Language Models (LLMs) like ChatGPT first burst onto the scene, what did most of us do? We couldn't help but use it for the thing we do literally all the time: a simple Google search. We'd type in a question, hoping the LLM would just spit out the answer it found somewhere.
But that's changing. Today, we're going to dive into using LLMs for search in ways that were genuinely never possible before these modern models came around. It’s time to stop just pointing the camera at the stage play and start making movies.
## The Tools of the New Paradigm
So, what are the tools enabling this shift? A few major players have emerged, essentially wrapping powerful LLMs in interfaces designed to tackle search-like tasks. We're talking about products like:
- **Perplexity.ai:** A dedicated interface built around using LLMs to find and synthesize information from the web.
- **ChatGPT's search mode:** This allows the LLM to actually go out and perform web searches.
- **Google's new AI Mode:** Google's own foray into integrating LLM capabilities directly into search results.
All three of these are, at their core, an LLM chatbot enhanced and designed to meet the demands we traditionally threw at search engines, but with a new approach.
## Understanding The Tools Within LLM Powered Search
It’s important to understand what’s actually going on under the hood with these tools, because not all LLM capabilities are created equal.
### The Chatbot
At its most basic, you just have the core LLM. This is essentially a highly sophisticated text generator. It’s been trained on massive amounts of data and is excellent at predicting the next word in a sequence, allowing it to "write" coherent and often very helpful text. But what are the weaknesses of a plain LLM? No built-in memory of past messages, and absolutely no access to the internet or any external files. It just writes text based on its training data and the current prompt. (In fact, the LLM doesn't even remember past messages. Under the hood, ChatGPT is sending in the entire chat history of the thread to the LLM every single time you send a new message!)
### Multimodal LLMs
Then came the evolution where model makers like OpenAI and Google started teaching these models to "read" and generate more than just text. What if you treated images, PDFs, audio, or even code as another form of "language"? Now you have multimodal LLMs that can analyze an image and describe it, or read a PDF document and answer questions about its content. These capabilities are increasingly being built directly into the model itself – it's part of its fundamental architecture.
### The Chatbot with Tools
This is where many of the products you interact with daily come in. They combine a core LLM with _external tools_. This is key: the LLM itself doesn't have web access or the ability to create documents natively. Instead, the LLM acts like a conductor. It reads your request and generates text that serves as a command or instruction for a separate tool to execute. Once the tool finishes its job, it sends the result back to the LLM, which then "reads" that output and uses it to formulate its response to you. Let's look at some common examples of these tools:
#### Web Search
This is probably the most common tool. The LLM takes your prompt, figures out what search queries to run, sends them to a search engine (often Google or Bing behind the scenes), gets the results, and then reads those web pages to synthesize an answer.
#### "Canvas"
Some interfaces allow the LLM to interact with a document or a structured workspace, letting it draft text, add elements, or iterate on content. The LLM is commanding the canvas tool to perform these actions.
#### "Research" / Enhanced Search Modes
Products like Perplexity have a "Research" mode, and others have similar features often branded differently. What these typically do is automate a multi-step process. The LLM might decide it needs to do several rounds of web searching, maybe outline a plan, execute searches based on that plan, read results, synthesize, and refine. This allows them to tackle more complex queries than a single search might handle, but remember, they are still fundamentally performing and processing multiple old-school searches. They still suffer from the core weaknesses of the LLM interpreting the results.
#### "Deep Thinking" / Problem Solving Modes
Most major model providers have modes with names like "deeper thinking" or "advanced reasoning." My intuition is that these are often variations on the "Research" pattern – perhaps more focused on applying logic or structured problem-solving patterns to the information gathered. While "Research" feels geared towards writing reports or summarizing complex subjects, "Deep Thinking" seems aimed at applying existing solutions or frameworks to new problems, even if they aren't capable of truly _inventing_ novel solutions from scratch. The mechanism likely still involves planning and iterative processing via external tools.
## The New Paradigm (LLM-powered search) Is Built on the Old Paradigm (Keyword-based search)
This is a crucial point to internalize: the shiny new LLM-powered search tools aren't magic boxes that bypass the internet. They are, for the most part, performing the same fundamental keyword-based searches we were already doing. They’re just automating a bunch of the steps for us.
Think about it: the LLM reads your nuanced, natural language prompt. It then _translates_ that prompt into the kind of specific keyword queries that traditional search engines understand. It sends those queries out, gets the list of search results (often still relying on the search index of giants like Google, as virtually every alternative search engine does), and then the LLM _reads_ the content of those pages to generate its answer. It's a powerful new layer on top of the existing search infrastructure.
## Understanding the Limitations of the Old Search Paradigm
To really appreciate what LLMs can do, let's quickly remind ourselves of the headaches of the old keyword-based search paradigm:
- It fundamentally relied on matching keywords. You had to guess what words the page you wanted might contain.
- While Google got better over time, it struggled to truly understand the _meaning_ of a full sentence or the _intent_ behind a query. It was mostly sophisticated pattern matching and ranking.
- It was terrible at questions where there was no single obvious keyword.
- Asking "how do I" questions often resulted in a list of pages that _might_ contain the instructions, forcing you to click through and piece together the answer yourself.
## Use Cases Uniquely Suited for LLM-Powered Search
This is where the new paradigm shines. Because LLMs understand context, relationships between ideas, and can synthesize information, they unlock search possibilities that were clunky or impossible before.
### Why LLMs Excel
Instead of just keyword matching, LLMs grasp the semantic meaning of your query. They understand the relationships between different pieces of information found across multiple sources and can synthesize them into a coherent answer. They don't just give you links; they give you a summary, a comparison, or a direct answer extracted from the web. This ability is what makes them uniquely capable of handling complex, vague, or comparative queries that would stump traditional search.
### Examples of these new possibilities
#### Retrieving Information from Vague Descriptions
Remember trying to find something you vaguely recall? Now you can ask:
- "I remember an episode of Spongebob where [describe a scene]. What was that episode?"
- "What's that one song that talks about [describe the theme or a lyric fragment]?"
- Finding information based on scenario: "I need a recipe for a quick dinner using chicken and whatever vegetables I might have on hand." (The LLM can interpret "whatever vegetables" and find recipes that fit the flexible criteria).
#### Complex Comparisons and Analysis
No more opening ten tabs to compare products or concepts manually. LLMs can do the heavy lifting:
- "Compare product A and B. I care about these features: [list features]. What other features should I be considering?"
- "Compare the features and pricing of three different project management software options, focusing on ease of use for small teams."
- "Analyze the pros and cons of using [technology A] vs. [technology B] for building a [type of application]."
#### Summarizing and Explaining
Get straight to the point or understand complex topics quickly:
- "Summarize the key findings of the recent report on [topic]."
- "Explain the concept of [technical term] in simple terms."
#### Converting From One Format To Another
- "Summarize this buying guide as a table."
- "Convert this JSON data into a CSV file."
#### Researching Relationships and Effects
Understand causality and connections between events or concepts:
- "What were the main causes and effects of [historical event]?"
- "How does [concept A] relate to [concept B] in the field of [subject]?"
#### Exploring Ideas and Recommendations
Get tailored suggestions based on your needs:
- "Recommend a good podcast about [topic] that is suitable for beginners."
## Weaknesses of LLM Powered Search
Now, before you ditch Google entirely and rely solely on chatbots for everything, let's talk about the not-so-shiny parts. LLM-powered search has significant weaknesses you _must_ be aware of.
### They Hallucinate
This is the most notorious weakness. LLMs can confidently state incorrect information or invent facts out of thin air. They don't know what they don't know, and they are compelled to generate a response even if they lack accurate information.
### Therefore, You Have to Verify Their Writing
Because of hallucinations and the lack of true reasoning, you absolutely _cannot_ blindly trust the output of an LLM-powered search. If the information is important, you _must_ verify it using other reliable sources.
### They are Not Actually Reasoning
This is perhaps the most crucial point. As research, like the recent paper from Apple titled [The Illusion of Thinking](https://ml-site.cdn-apple.com/papers/the-illusion-of-thinking.pdf) suggests, these models aren't actually "thinking" or reasoning in a human sense. They are incredibly complex pattern-matching and text-generation machines. They are brilliant at predicting the next token based on the vast data they trained on, which _looks_ like intelligence, but isn't.
### Even "Reasoning" Steps Can Be Unreliable
Techniques like "Chain-of-Thought" were introduced to make models explain their steps, making them seem more transparent and reliable. However, [research shows](https://www.anthropic.com/research/reasoning-models-dont-say-think) that the steps they output when asked "how did you get that answer?" might not actually reflect the internal process the model used to generate the initial response. They can essentially hallucinate their own explanation after the fact. So, you can't fully trust that the chain-of-thought accurately represents their actual "thought process."
### Yes, They Cite Their Sources, but Even Those Have Mistakes
A great feature is that these products often inline cite their sources, letting you click through to the original page. This _should_ help with verification, but I've found two major problems:
- **Poor Source Trustworthiness Judgment:** LLMs don't seem to be very good at evaluating whether a source is trustworthy. They routinely fall for jokes or satire and often treat outdated sources with the same authority as brand new ones. They also don't seem to understand that for some subjects (like breaking news), you should actually place _less_ trust in brand new, unverified sources because the story is still developing.
- **Phantom Citations:** Often, I click on a cited link, and the page straight up _never mentioned_ the fact the LLM attributed to it. It's like the model was programmed to cite _something_ and just picked a random link from the search results it processed. It's incredibly frustrating and undermines the verification feature.
### The Honeymoon Won't Last Forever
Right now, many of these products deliver answers incredibly fast, for little to no cost, with minimal or zero ads. This is fantastic! But running these powerful models and their associated search infrastructure is expensive. These companies have massive costs, and eventually, they _will_ pass that on to us, the users. [Enshittification](https://en.wikipedia.org/wiki/Enshittification) is likely inevitable. Enjoy the current state while it lasts, but be prepared for things to change.
## Tips for LLM Powered Search
Given the power and the pitfalls, here are some tips for getting the most out of LLM-powered search while navigating its weaknesses:
### Feel Free to Use Natural Language
This is the primary value proposition! Don't feel like you have to revert to chopped-up keyword phrases. Ask your question as you would to an expert sitting next to you. This allows the LLM to leverage its understanding of language.
### Don't Stop Using Keywords (Especially for Specifics)
While natural language is great, precision helps. If you're asking about a specific product, person, or concept, include the exact name or jargon within your natural language prompt. Instead of saying "the new iPhone," say "the iPhone 16 Pro." This gives the underlying keyword search mechanism the best chance of finding highly relevant source material for the LLM to process, increasing the likelihood of accurate results. Be careful about using relative terms like *the latest*, or *last year's*. While LLMs can handle these terms, it requires extra work and complexity for them.
### Understand What Makes a "Weak" Question
Before you hit send, pause and ask yourself: "If I asked a human expert this question, would they understand exactly what I'm asking and how to find the answer?" Put yourself in the shoes of the answerer. LLMs are powerful, but they can't read your mind. If your question is so vague, ambiguous, or requires external context only you possess, a human expert couldn't answer it reliably, and neither can an LLM. Be as clear and specific as possible about what you need and the context surrounding it.
## Conclusion: The Future of Information Access - With Caveats
The advent of modern LLMs is undeniably ushering in a new era for how we access information. We're moving beyond the limitations of simple keyword matching to a world where search tools can understand the nuance of natural language, synthesize information from multiple sources, and directly answer complex questions that were previously hard to tackle. This unlocks exciting new use cases, allowing us to find information based on vague recollections, perform detailed comparisons effortlessly, and get quick summaries of complex topics.
However, it's critical to approach this new paradigm with open eyes. These tools are not infallible truth machines. They hallucinate, they don't truly reason, their explanations of _how_ they got an answer might be fabricated, and their source citation is often unreliable. We have to remain critical users, verifying important information and understanding that the smooth, confident answer we receive is a generated text output, not necessarily the result of genuine understanding or foolproof fact-finding.
LLM-powered search is a powerful layer built upon the existing foundation of web search. It automates and enhances our ability to find information, pushing the boundaries of what's possible. As the technology evolves, and potentially adapts to new business models, understanding how these tools work – their strengths, their weaknesses, and the best ways to interact with them – will be key to effectively navigating the future of information access. So, explore these new tools, ask those complex questions, but always remember to verify, verify, verify.
# AI Is Human Intelligence Applied
My first experience with so-called AI was in the late 90s playing a PS1 game called _Twisted Metal_. I could play competitively against my friends, but somehow I could even play when there was no one else around. The game itself could be my opponent. This felt like magic to me. How could a computer understand how to play the game so well. At times, it even felt like it was strategizing and anticipating my moves.
Fast forward to today, and we know that this was not some advanced intelligence. It didn't understand deep, complex strategies or have any real understanding of the game. It was simply programmed to follow a set of rules and respond to player actions in a way that felt competitive. And who was it that programmed those rules? A human, of course. The AI was just a reflection of human intelligence applied to the game mechanics.
Today, [we would be laughed at if we called that AI]({{< ref "ai-is-a-moving-goalpost" >}}). But the same principle applies to modern AI systems. They are not super-intelligent beings. They are tools created by humans, designed to apply human intelligence to specific tasks. If they seem human, then that is no accident. Of course they seem human. They are designed by humans to mimic humans.
## Stop Giving AI Too Much Credit
Fred Hebert makes the insightful observation that "[We Oversell Machines by Erasing Ourselves](https://ferd.ca/the-gap-through-which-we-praise-the-machine.html)". So often, we use AI and it feels magical, and yet we forget the immense amount of human intelligence and work that duct taped it all together. We forget that the AI is not some independent entity; it is a product of human ingenuity, creativity, and effort.
When we talk about AI, we should remember that it is not a replacement for human intelligence. It is an **application** of it. It is a tool that extends our capabilities, not a substitute for our own thinking and understanding.
## Remember the Value of Humanity
We should celebrate the incredible advancements in AI technology, but we must also recognize the human intelligence that makes it all possible. The next time you marvel at an AI's capabilities, take a moment to appreciate the human minds behind it. Remember the innumerable generations of human thought, creativity, and problem-solving that are encapsulated in that AI's training data. To the AI, human history is a pile of weights and biases, but to us, it is a rich tapestry of culture, knowledge, and experience. It's not ones and zeros; it's Shakespeare and Van Gogh.
And remember the value of yourself. You are not replaceable. Not by a machine, a person or anything else. Don't sell yourself short.
# Migrating Notes from Hugo/Quartz to Obsidian Publish
# Migrating Notes from Obsidian Quartz to Obsidian Publish, Seamlessly Integrated with Netlify
It's no secret that I am a very big fan of Obsidian. I use it for everything from note-taking to project management, and even as a publishing platform for my notes. In order to publish notes on the web, Obsidian offers [Obsidian Publish](https://obsidian.md/publish), a service that allows you to host your notes as a static website. However, I had been using [Obsidian Quartz](https://quartz.jzhao.xyz/) for my publishing needs. I liked it primarily because it was free and open source, and I could host it myself on GitHub Pages. However, I found that the publishing workflow was a bit cumbersome. So I finally decided to migrate my notes from Obsidian Quartz to Obsidian Publish, while still keeping them under my main website (`dandylyons.net`) using Netlify as a proxy.
This post will walk through the migration process, the technical details of integrating Obsidian Publish with my existing Hugo site, and the key considerations for SEO and user experience.
## Choosing Obsidian Publish: Quartz vs. Publish
Understanding the difference between Obsidian Quartz and Obsidian Publish is key to appreciating the migration path. Both take an Obsidian vault as input and produce a static website, but their architecture and hosting differ significantly.
| Feature | Obsidian Quartz (Community SSG) | Obsidian Publish (Official SSG/Hosting Service) |
| :---------------------- | :------------------------------------------------------------------------------------------ | :--------------------------------------------------------------------------------------------------- |
| **Type** | Standalone Static Site Generator (open source) | Integrated Static Site Generator & Hosting Service (closed source, paid) |
| **Development** | Community-driven, open source | Developed and maintained by Obsidian.md team |
| **Cost** | Free (plus your hosting costs) | Paid Subscription (required for the service) |
| **Hosting** | Self-hosted (You deploy the generated site to platforms like Netlify, Vercel, GitHub Pages) | Hosted directly by [Obsidian](https://publish.obsidian.md) |
| **Setup Complexity** | Requires installing Quartz, running the build process, configuring deployment to a host | Configuration primarily within the Obsidian app; less external setup; less technical skills required |
| **Customization** | Highly customizable (modify templates, CSS, etc.) | Highly customizable (CSS, Javascript) |
| **Publishing Workflow** | Run Quartz build -> Deploy generated files | Publish directly from within the Obsidian app |
| **Features** | Often replicates Obsidian features like graph view, backlinks via generation | Built-in graph view, backlinks, version history, password protection |
### Pros and Cons
| Tool | Pros | Cons |
| :--------------- | :--------------------------------------------------------------------------------------------------------------------------------- | :---------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Obsidian Quartz | - Free and open source - Provides full control over the static site generation process and generated files - High degree of customization through template and asset modification - You choose and control your hosting environment | - Requires a separate build process and deployment workflow outside of Obsidian - Updates require running the build and redeploying - Relies on community development for features and updates |
| Obsidian Publish | - Extremely easy publishing workflow directly from the Obsidian app - Fully managed hosting by Obsidian.md – no build pipelines or server maintenance - Official support and tightly integrated features (versioning, etc.) | - Paid subscription is required - Less flexibility and customization compared to a standalone SG - You have less control over the hosting environment and generated files |
For my notes, the 'zero-friction' publishing directly from Obsidian and the managed hosting of Obsidian Publish became more appealing, justifying the shift despite Quartz's strengths as a free solution. But these benefits have been true for a while now. So what caused me to finally make the switch? [Bases](https://help.obsidian.md/bases). I have been waiting for the Obsidian team to release a database solution for Obsidian for a very long time, and I was [stoked to see that they finally did](https://dandylyons.net/posts/goodbye-dataview-hello-obsidian-bases/). Even better, they announced in their [roadmap](https://help.obsidian.md/bases/roadmap) that Obsidian Publish would support Bases in the future. As much as I like and appreciate Obsidian Quartz, I doubt that a third-party community project will ever be able to match the level of integration and support that Obsidian Publish will provide for Bases. This will certainly be a game-changer for my notes, and I wanted to be ready for it. So I decided to migrate my notes from Obsidian Quartz to Obsidian Publish.
## The Migration Strategy: Netlify as the Integration Layer
Obsidian has very helpful [documentation showing how to set up Obsidian Publish with a custom domain](https://help.obsidian.md/publish/domains), which I used for this migration.
My main website (`dandylyons.net`), built with Hugo, was already hosted on Netlify. The challenge was to move the *notes content* to the Obsidian Publish service while still having it appear as part of `dandylyons.net` under the `/notes/` path.
[Once again](http://dandylyons.net/posts/smooth-site-migration-redirecting-github-pages-to-netlify-path-by-path/) Netlify's [redirect engine](https://docs.netlify.com/routing/redirects/) is the key here. It allows Netlify to act as a **proxy**. When a user requests a URL under `dandylyons.net/notes/`, Netlify intercepts the request and *internally* fetches the corresponding content from the Obsidian Publish hosted site, serving it back to the user as if it originated from `dandylyons.net`.
This setup is ideal:
- My main Hugo site handles all requests *except* those starting with `/notes/`.
- Obsidian Publish generates and hosts the notes content.
- Netlify bridges the two, presenting the notes content under the desired `dandylyons.net/notes/` path.
- When a user requests a URL under `dandylyons.net/notes/`, Netlify intercepts the request and fetches the corresponding content from the Obsidian Publish hosted site, serving it back to the user as if it originated from `dandylyons.net`.
## Implementing the Proxy with `netlify.toml`
To configure redirects on Netlify, you must provide a `netlify.toml` file in the root of your project, with the desired configuration. My Netlify project for `dandylyons.net` already had a `netlify.toml` file managing the Hugo build which contained an outdated redirect rule pointing `/notes/*` to my old GitHub Pages hosted Quartz site. This rule needed to be replaced with the new proxy rule for Obsidian Publish.
Here is the relevant section of the updated `netlify.toml`:
```toml
[build.environment]
HUGO_VERSION = "0.134.0" # Set this to your Hugo version
[[redirects]]
from = "/notes/*"
to = "https://publish.obsidian.md/serve?url=dandylyons.net/notes/:splat"
status = 200 # Crucially, status 200 creates a proxy/rewrite, not a redirect
force = true # Ensures this rule takes precedence
# This was my old redirect rule, which is now commented out
# [[redirects]]
# from = "/notes/*"
# to = "https://dandylyons.github.io/notes/:splat" # Old URL
# status = 301
# force = true
```
### How the Proxy Rule Works (`status = 200`)
When a browser requests `https://dandylyons.net/notes/some-page`:
1. The request arrives at Netlify for `dandylyons.net`.
2. Netlify matches the `/notes/*` path to the `[[redirects]]` rule.
3. Because `status = 200`, Netlify does *not* tell the browser to go to a new URL.
4. Instead, Netlify makes a server-side request to the `to` URL: `https://publish.obsidian.md/serve?url=dandylyons.net/notes/some-page` (where `:splat` was replaced by `some-page`).
5. Obsidian Publish receives this request, identifies the site based on `dandylyons.net/notes`, finds the "some-page" content, and returns it to Netlify.
6. Netlify then delivers that content back to the user's browser, seemingly originating from `https://dandylyons.net/notes/some-page`.
The URL in the browser's address bar remains `https://dandylyons.net/notes/some-page`. This is exactly the desired behavior for integrating content under a subpath.
## Configuring Obsidian Publish & Updating Hugo
With the Netlify proxy configured, the final steps involve setting up Obsidian Publish and adjusting the main Hugo site:
1. **Configure Custom Domain in Obsidian Publish:** Within your Obsidian vault, access the Publish settings. Under the Custom domain option, enter `dandylyons.net/notes` as the custom URL for your published site. This setting is essential for Obsidian Publish to correctly interpret the requests arriving via the Netlify proxy.
2. **Update Hugo Site Links:** Modify your Hugo project's `config.toml` and any markdown files. Change any links that pointed to your old Quartz site URL (e.g., `https://dandylyons.github.io/notes/...`) to now point to the new internal path `/notes/...`. This includes updating the "Notes" menu item in your site's navigation.
## Key SEO Considerations
Migrating content from one hosting/generating method to another, especially involving a proxy, requires careful attention to SEO to preserve search rankings and user experience. Thankfully, Obsidian Publish also provides some built-in SEO features and an [SEO guide](https://help.obsidian.md/publish/seo). Here are some of the key SEO features provided by Obsidian Publish:
- **Sitemap:** Obsidian Publish can automatically generate a `sitemap.xml` for you
- **Robots.txt:** Obsidian Publish can automatically generate a `robots.txt` file for you
- **RSS:** Obsidian Publish can automatically generate an RSS feed for you
Here are some additional SEO considerations to ensure a smooth transition:
- **Internal Linking:** Update *all* internal links within your main Hugo site (`/posts/`, `/projects/`, etc.) to correctly point to the new `/notes/` paths. This is fundamental for SEO, helping search engines discover the migrated content's new location and pass link authority.
- **External Backlinks:** Identify any valuable external links pointing to your old Quartz site's URL (e.g., `https://dandylyons.github.io/notes/...`). While you could try basic redirects on the old host (if possible), the most effective long-term strategy for important backlinks is to contact the linking site owners and ask them to update the URL to `https://dandylyons.net/notes/...`.
- **Sitemaps:** Your Hugo site generates a sitemap (`sitemap.xml`) for its content. Obsidian Publish generates a sitemap for the notes content. **Submit *both* sitemaps** to Google Search Console under your `dandylyons.net` property. This ensures search engines are aware of all content under your consolidated domain.
- **Robots.txt:** Your main Hugo site's `robots.txt` file (usually in the `static` directory) governs crawling for the entire `dandylyons.net` domain.
By diligently addressing these SEO points, you can ensure a smoother transition in search engine visibility and maintain the discoverability of your notes content.
## Conclusion
By migrating my notes from Obsidian Quartz to Obsidian Publish I've made it much easier to manage and publish my notes. And now with Netlify redirecting requests, I can keep the notes under my main domain (`dandylyons.net/notes/`), providing a seamless experience for users.
# Goodbye Dataview! Hello Obsidian Bases!
Obsidian has recently unveiled a game-changing native feature: **[Bases](https://help.obsidian.md/bases)**. If you've ever wished for Notion-like database capabilities within your Obsidian vault, but with the security of open, human-readable formats that won't lock you in, this is the update you've been waiting for. Bases, a new core plugin, is currently available for Catalyst members via early access (version 1.9.0 and above), and it's set to revolutionize how we organize and interact with information in Obsidian.
## A Brief History of Databases in Obsidian
To appreciate the significance of Bases, let's quickly look at how data management has evolved within Obsidian.
### Obsidian Databases: The Past
#### YAML Frontmatter
For years, [YAML frontmatter](https://notes.nicolevanderhoeven.com/obsidian-playbook/Using+Obsidian/03+Linking+and+organizing/YAML+Frontmatter) has been the quiet workhorse for metadata in Markdown files. This block of `key: value` pairs at the top of a note allows users to add structured information—like dates, tags, statuses, or custom fields—to their documents. It's a widely adopted standard and has served as the foundational data layer for many advanced Obsidian workflows.
```markdown
---
title: "A Brief History of Databases in Obsidian"
description: "Learn about the new Bases feature in Obsidian and how it makes Obsidian more powerful and easier to use."
date: 2025-05-24
topics: ["Bases", "Databases", "Dataview", "Markdown", "Obsidian", "YAML"]
draft: false
---
# A Brief History of Databases in Obsidian
This is the content of the note.
```
### Obsidian Databases: The Present
While YAML frontmatter provided the data, users needed ways to query and display it.
#### Dataview
The **[Dataview](https://blacksmithgu.github.io/obsidian-dataview/)** community plugin stepped up to fill this need, becoming incredibly popular. It allows users to query YAML frontmatter (and inline fields) from notes across their vault using its own Dataview Query Language (DQL). DQL is powerful and designed to be similar to SQL, enabling the creation of dynamic tables, lists, and summaries reminiscent of Notion databases.
````
```dataview
TABLE
FROM "Books"
WHERE status = "read"
SORT date DESC
```
````
This example shows how Dataview can create a table of all notes in the "Books" folder that have a status of "read," sorted by date in descending order. This is just a glimpse of what Dataview can do, as it supports complex queries, including filtering, sorting, and aggregating data.
However, Dataview comes with a learning curve. Its DQL syntax, while potent, is unique to Dataview. While it may be similar to SQL, there are major differences, so the skills don't readily transfer elsewhere. Queries can be brittle, breaking easily with syntax errors, and there's no [graphical user interface (GUI)](https://en.wikipedia.org/wiki/Graphical_user_interface) for building them. Furthermore, Dataview queries are not supported by [Obsidian Publish](https://obsidian.md/publish), limiting how users can share their structured data with others.
#### Obsidian Properties: Native GUI for Frontmatter
Recognizing the importance of structured data, Obsidian introduced the native **[Properties](https://help.obsidian.md/properties)** core plugin. This was a huge step forward, providing a user-friendly GUI for viewing and editing YAML frontmatter. No longer did users have to meticulously worry about correct YAML syntax; Properties handles it, even adding light type checking for data consistency. This made working with metadata much more accessible to everyone.
But Properties didn't just make it easier to edit YAML, it set the foundation for the next step in Obsidian's evolution: Bases.
## Obsidian Databases: The Future (Bases Core Plugin)
The new **Bases** core plugin is the next logical leap. Just as Properties abstracted away the complexities of raw YAML, Bases aims to abstract away the complexities of query languages like DQL, offering a powerful, native, and GUI-driven way to create and manage databases within Obsidian. It's designed to turn any collection of notes into a dynamic database, perfect for organizing everything from projects and travel plans to reading lists and much more.
While Bases is still a work in progress and in an early access phase, its potential is immense.
### Using Views
At the heart of Bases are **Views**. These are different ways to display and interact with the data drawn from your notes.
- **Easy GUI Interface**: Creating and configuring views is done through a straightforward graphical interface, where actions are driven by clear buttons and menus—a welcome change from writing manual queries. This makes it a strong potential replacement for many common Dataview use cases.
- **Layouts**: Currently, Bases supports a **table layout**, where each row is a file and columns are populated from note properties. The roadmap promises more layouts, such as lists and cards, in the future.
- **Filtering**: You can easily filter the notes included in a view using a GUI. Filters allow you to narrow down results based on specific criteria (e.g., files with a certain tag, in a particular folder, or where a date property falls within a range). You can apply filters to all views in a base or to specific views.
### Embedding Views
Once you've created a base and its views, you can embed them directly into your notes:
- **Embed an Entire Base File**: Use the standard embed syntax `![[YourBaseFile.base]]`.
- **Embed a Specific Base View**: To display a particular **View** from your base by default, use the syntax `![[YourBaseFile.base#ViewName]]`.
### Using Functions
Bases includes a range of built-in functions that can be used in filters (to select which notes to include) and formulas (to create new, derived data columns from existing properties). These functions allow for sophisticated data manipulation and querying directly within the Bases UI or its underlying YAML definition.
Here are a few examples of helpful functions:
- **`contains(target, query)`**: Checks if a text property or list contains a specific string or item. Useful for filtering notes that mention a keyword or have a specific tag in a list.
- **`if(condition, value_if_true, value_if_false)`**: Allows for conditional logic in your formulas. For example, `if(property.status == "done", "Complete", "In Progress")`.
- **`dateAfter(date1, date2)`**: Checks if the first date is after the second. Excellent for time-sensitive data, like tasks due after a certain date.
- **`sum(property_name)`**: While more advanced aggregation and grouping features are on the roadmap, the table view already supports aggregation like `sum()`. In a view definition, you can specify `agg: "sum(price)"` to calculate the total of a 'price' property for grouped items, for instance. This is a key feature for creating summary dashboards.
### `.base` File Format
One of Obsidian's core strengths, and a major reason for its dedicated user base, is its commitment to open, user-owned data. Bases continues this tradition:
- **Open Technology Focus**: Obsidian prioritizes open, community-driven technologies like Markdown, YAML, and JSON, avoiding proprietary lock-in.
- **Transparent New Formats**: When a new feature requires a new format, Obsidian ensures it's human-readable and editable. The specification for the `.base` file is simple YAML with a defined schema. You can inspect it, edit it manually if you wish, and understand how your data is structured.
- **Future-Proofing**: Open formats are more likely to be compatible with future tools, including AI agents and other applications.
- **No Licensing Fees**: You own your data and the format it's stored in. You can edit your data in any app in a common text editor.
- **Open Sourcing**: Some formats, like the `.canvas` file format, are even open-sourced, further demonstrating this commitment.
The introduction of a new `.base` file format might initially raise concerns for some, myself included. I learned the hard way with Evernote how frustrating it can be to use a proprietary format. Companies use these formats to lock you into their ecosystem. You'd like to leave but you can't because your data is stuck in their system and is difficult or even impossible to export into another format.
Thankfully, Obsidian puts all of these fears to rest with the new `.base` file format. It's just a simple YAML text file, editable in any text editor, and it uses a simple human readable syntax which is [documented here](https://help.obsidian.md/bases/syntax). This file is used to define things like how you would like to sort or group results. These are many of the same things that we were already defining in Dataview DQL. The good news is that this means it should be quite easy to ask any high quality LLM (like chatGPT) to convert your old Dataview queries into new `.base` files.
Beyond the technical underpinnings, what truly makes Bases exciting is its accessibility.
## How to Get Started
My favorite part of this new feature is how trivially easy it is to get started. If you've already been adding Properties to your Obsidian notes then all you need to do is create a base and add a filter!
First we run the "Bases: Create new base" command. Now we immediately have a database with every single note in your entire vault. (My vault has over 3,400 notes. With Dataview, this query would slow my Obsidian to a crawl, but with Bases, it's no problem!) Now we have a powerful database without a strange query language to run. And every time that we make an edit in our database it will automatically update our human-readable `.base` file.
### Views
Obsidian not only created a *Base* for us, it created a *View*. Think of a Base like a collection of notes in your vault, and think of Views like a custom dashboard to view that collection of notes. You can make as many "dashboards" or Views as you like. At the moment, Obsidian only has one type of View a *Table*, but they have already announced in their [roadmap](https://help.obsidian.md/bases/roadmap) that they intend to add *Card* and *List* Views in the future.
Views can be renamed by clicking the View button, and choosing *Configure View*. Here we can also set a maximum number of results.
### Filtering
Now let's turn this into something a little more useful. In your new Obsidian **Base** there is a **Filters** button. Here are all of the familiar query GUI that you'd expect to see in an app like AirTable or Notion. We simply set a condition, and if a note meets that condition then it will kept by the filter, otherwise it will be removed. Don't forget Obsidian lets you apply a filter to just a specific View, or to every View in that Base.
### Properties
In our Table View we can click the *Properties* button. Here we see a list of every property that we've used across our whole Vault. We can type in and search for just the properties that we care about, and it will add that column to our Table.
### Editing
By far my favorite feature of this new Bases plugin is editing. Each cell in our Table is editable. Making a change in the cell, automatically updates the YAML frontmatter in that row's note! Dataview simply couldn't do this. It could fetch data, but it could not make changes. There's not much else to say about this feature. It just works exactly the way that you would hope it does.
## Still to Come: Bases Roadmap
The Bases plugin is still in its beta phase, with an extended early access period expected. Currently it's only accessible to users with a Catalyst license. The Obsidian team has an exciting roadmap for its development:
- **Bases API for Plugins**: This will allow other plugin developers to extend Bases with custom functions and new view types, potentially unlocking even more power.
- **More View Types**: Beyond the current table view, expect layouts like lists, cards, and potentially others.
- **Enhanced Grouping and Aggregation**: While some aggregation is present, more sophisticated grouping of files and a broader range of aggregation functions (like `average`, `count`) are planned.
- **Obsidian Publish support**: A crucial feature for many, this will allow users to publish their bases and share them on the web.
There are also some features that I'd like to see in the near future:
- An integrated search function within a Base View to quickly find specific entries without altering the main filters.
If Obsidian follows their past progress, then I'm confident that these features will come and the community will provide even more powerful community plugins to boot.
## Conclusion
For me, Obsidian Bases feels like the missing piece I've been waiting for. It elegantly solves the challenge of robust data management within my vault, moving beyond the limitations of past methods while upholding the open-data ethos that keeps me invested in Obsidian. The ease of getting started, combined with the power already evident and the exciting roadmap ahead, makes me incredibly optimistic. If you're a Catalyst member, I urge you to dive in; if not, keep a close eye on this space. Bases is set to redefine what's possible in Obsidian, and I can't wait to see how it, and our collective workflows, evolve.
# Entering the Mind of Nikola Tesla
I recently had the pleasure of reading and finishing the book "My Inventions" by Nikola Tesla. This book is a collection of articles written by Tesla himself, where he shares his thoughts and experiences on various topics related to science, technology, and his inventions. The book is not comprehensive enough to feel like a true autobiography, but it does provide a glimpse into the mind of one of the greatest inventors of all time.
While reading this book, I was surprised to see how important Tesla's Christian faith and upbringing were to him. Tesla's father, who was a clergyman, and particularly his mother, played a significant role in shaping his worldview and approach to science. He believed that there was a divine order to the universe and that science and religion were not mutually exclusive. This perspective is refreshing, especially in today's world, where many people view science and religion as irreconcilable.
This book was a short yet insightful read, and I highly recommend it to anyone even if you are not particularly interested in Tesla or his inventions. It is a fascinating glimpse into the mind of a brilliant inventor and thinker, and it provides valuable insights into the relationship between science, religion, and the human experience. Tesla's reflections on his life and work are thought-provoking and inspiring, and they remind us of the importance of curiosity, creativity, and perseverance in the pursuit of knowledge and understanding.
[You can read my notes on the book here.](https://dandylyons.net/notes/Media-DB/books)
You can also read the book for free here:
- [Audiobook](https://archive.org/details/my_inventions_1812_librivox)
- [Text](https://archive.org/details/my-inventions-nikola-tesla) (Available in PDF, EPUB, plain text and other formats)
---
## Why I Read This Book
I think it's worth asking yourself the question before, during and after reading a book: *Why should I read this book?* In one sense, I think that every single book is worth reading. Avoiding any book does not promote learning, curiosity or growth as a person. But alas, there's a finite amount of time and an endless mountain of books, and let's face it, some books are more worthwhile than others.
So why would I read this book? Is it because I relate to Tesla? Definitely not. Tesla is a very strange, unique individual. I will never think in the same way as him, and chances are, I won't even meet someone who thinks like him. But I still think it's important and valuable to read about people who think differently than you. I hardly care about minute dates and facts in biography. These tend to reveal trivial insights. I think it's much more valuable to understand the way that other people think. It challenges my own thinking and helps me to understand the world in a different way. Perhaps there are ways where my own thinking is flawed or limited. Or perhaps understanding the way that other people can help me to understand others around me better.
In any case, it is a fascinating privilege to be able to read the thoughts of another person, especially one so unique and impactful as Tesla. We should not take this privilege for granted. I think that, on average, it holds far more value than that new show that just came out on Netflix.
# On the Ambuguities of Sorry
## Introduction
In the modern cultural landscape, few phrases are as scrutinized, debated, and often dismissed as the public apology. When a public figure faces backlash, warranted or not, the inevitable "sorry" statement often follows. Yet, these pronouncements frequently ring hollow, sounding more like carefully crafted PR than genuine contrition. This pervasive sense of inauthenticity highlights a deeper issue: the inherent ambiguity embedded within the word "sorry" itself. This ambiguity transforms apologies into a societal Rorschach test, fueling division and tribalism, and underscores a critical need for greater clarity in our language and interactions.
## The Problem of Ambiguity and Cultural Division
The problem begins with the ambiguous nature of the apology, particularly in the public sphere. When a sorry is issued, its true meaning and sincerity become subject to individual interpretation. This ambiguity serves as a Rorschach test, upon which each observer projects their own biases, expectations, and judgments. The lack of a clear, shared understanding of the apology's intent inevitably leads to division. People not only rush to judge the initial action but also secondarily judge those who interpret the apology or the situation differently. This creates fertile ground for tribalism, where groups form based on shared conclusions, often demonizing those who arrive at opposing viewpoints. Defending someone accused of wrongdoing can even lead to being accused of adopting their perceived flaws or beliefs, further calcifying divisions and hindering empathetic understanding.
## Deconstructing the Word "Sorry": Multiple Meanings
Comic by XKCD
A significant source of this confusion lies in the fact that the single word "sorry" can simultaneously convey several distinct messages. We commonly use "sorry" in at least three different ways, and conflating these meanings is a primary driver of misunderstanding. The first meaning is offering sympathy. This is perhaps the simplest form, expressing sadness or concern for another's misfortune, as in the classic XKCD comic above where one character says their mom's house burned down. This character is merely expressing sympathy, but it is being interpreted as admitting guilt or wrongdoing. When we say "I'm sorry" in this sense, we are accepting responsibility for a harmful action, implicitly acknowledging that something wrong was done and, often, that some form of restitution or consequence is necessary to "make things right." This is frequently the meaning the public demands from a figure who has erred. The third meaning is expressing regret – conveying a wish that a past action had not occurred. While regret is often a natural consequence of believing one has done something wrong, the expression of regret itself doesn't automatically constitute an admission of fault or acceptance of consequences to others. The difficulty arises because these three meanings are not mutually exclusive; a single "sorry" could potentially encompass one, two, or all three, leaving the listener uncertain of the speaker's true intent.
## A Historical Side Note on "Apology"
Interestingly, another term that we often use interchangeably with "sorry" carries its own historical baggage. *Apology*. The word derives from the Ancient Greek "apologia," which meant a formal *defense* or justification of one's actions, beliefs, or character. Socrates' famous *Apology* is not a statement of regret, nor is it an admission of guilt. Really, it is a reasoned defense against accusations. Over centuries, the meaning of "apology" shifted dramatically in English. Today, to "apologize" means almost exclusively to express regret *and* admit fault or wrongdoing. This just further shows how ambiguities in this area are not new.
## Why Ambiguity Persists in Public Apologies
Given the potential for misinterpretation and the high stakes involved, particularly for public figures, ambiguity in apologies often persists not by accident, but by design. There exists a fundamental tension between the public's demand for accountability and admission of guilt, and the individual's natural desire to avoid negative consequences, whether legal, social, or professional. This tension creates a powerful incentive for strategic ambiguity. Public figures may issue apologies that are intentionally vague, designed to sound remorseful enough to appease critics and alleviate pressure, while simultaneously avoiding a clear admission of guilt that could lead to tangible repercussions. This pursuit of "plausible deniability"—the ability to later claim their apology meant something other than accepting fault—is a primary reason why so many apologies feel disingenuous. It's a negotiation between appearing contrite and avoiding consequences, and the resulting language is often deliberately fuzzy. Importantly, this isn't limited to the famous; the tendency to use ambiguous apologies to navigate difficult situations is a common human behavior.
## A Call for Clarity and Improved Interaction
To mitigate the divisive effects of this linguistic imprecision, we must actively seek and promote clarity. This starts with our own communication. When we genuinely mean to admit fault, using less ambiguous phrases like "I apologize" or the even more direct "What I did was wrong" can prevent confusion. We should strive to be mindful of how our words might be interpreted and aim to minimize potential misunderstandings. Equally important is how we interpret and respond to the apologies of others. The common reaction of immediately accusing someone of insincerity or faking an apology, while perhaps intuitively satisfying, is problematic. We cannot know another person's internal state with absolute certainty, and such accusations often escalate conflict, breeding defensiveness and cycles of hypocrisy. A more constructive approach is to ask clarifying questions. Instead of assuming we know the intent behind an ambiguous "I'm sorry," we can gently probe for more specific meaning. Questions like "Why are you sorry?", "Do you admit that what you did was wrong?", or even "Can you explain why what you did was wrong?" require the speaker to be more explicit. Asking *why* something was wrong is particularly powerful; it necessitates a demonstration of understanding and is much harder to fake than a simple verbal admission. A refusal to explain or an incoherent explanation can often reveal a lack of genuine belief in wrongdoing far more effectively than a direct accusation.
## Conclusion
In conclusion, the word "sorry," burdened by its multiple meanings and often employed with strategic ambiguity, has become a focal point of misunderstanding and division in contemporary culture. The resulting confusion fuels judgmentalism and tribalism, hindering productive discourse and reconciliation. By recognizing the inherent ambiguity of the word and actively seeking clarity—both in our own expressions of remorse and in our interpretation of others' apologies—we can begin to dismantle the barriers to genuine understanding. Prioritizing clarifying questions over hasty accusations offers a path toward more honest interactions and a less divided society.
# Smooth Site Migration: Redirecting GitHub Pages to Netlify Path-by-Path (with Hugo & SEO in Mind)
Migrating a website can be a bit like moving houses – exciting, but you still need to ensure everyone who knew your old address can find you at the new one. When I recently moved my personal site from GitHub Pages (`dandylyons.github.io`) to Netlify (`dandylyons.net`), I faced this exact challenge. My old GitHub Pages site was still live, and simply letting it sit there wasn't ideal for users or search engine optimization (SEO).
The goal was clear: I needed to redirect visitors from `dandylyons.github.io` to `dandylyons.net`. But not just the homepage – I wanted to redirect specific paths. For example, `dandylyons.github.io/thoughts` should redirect to `dandylyons.net/thoughts`, `dandylyons.github.io/posts/my-post` should go to `dandylyons.net/posts/my-post`, and so on. This path-specific redirection is crucial for maintaining SEO link equity and providing a seamless experience for users who might have bookmarked deep links on the old site.
Complicating factors:
1. My site is built with **Hugo**, a static site generator.
2. I have a separate GitHub Pages site for notes at `dandylyons.github.io/notes`, which needed to remain untouched.
3. I wanted to preserve as much SEO value as possible.
Let's dive into how I tackled this, moving beyond a simple root redirect.
>![UPDATE]
> After this migration, I have since moved my [notes site](https://dandylyons.net/notes) to a new domain, [publish.obsidian.md/dandylyons](https://publish.obsidian.md/dandylyons).
### The Initial Thought: A Simple Root Redirect
My first inclination was the simplest approach: just put a single HTML file at the root of the GitHub Pages site (`dandylyons.github.io`) that redirected everyone to the new homepage (`dandylyons.net`).
The HTML looked something like this, placed in an `index.html` file:
```html
Redirecting...
```
I planned to serve this from the GitHub repository (`DandyLyons/DandyLyons.io`) that GitHub Pages uses for the root user site. This works for the homepage, but it has a major flaw: any request to a specific path on the old site (e.g., `dandylyons.github.io/thoughts`) would *also* land on this `index.html` and redirect to `dandylyons.net/`. This loses the specific path context, potentially breaking deep links and harming SEO by not directing search engines to the corresponding content on the new domain.
### The Refined Approach: Path-Specific Redirects for Static Sites
True path-by-path redirects are best handled with server-side 301 "Moved Permanently" redirects. This is the clearest signal to search engines that content has moved and they should transfer ranking signals to the new URL. However, GitHub Pages for user/organization sites (`username.github.io`) primarily serves static files directly from a repository branch (like `main` or `gh-pages`). You don't have server-level configuration options like `.htaccess` files to set up 301s easily for the root domain.
The most practical alternative for static hosting in this scenario is a client-side redirect combined with SEO-friendly tags. The meta refresh tag (``) can initiate an immediate redirect, and the `link rel="canonical"` tag can tell search engines which URL is the preferred version of the content.
To make this path-specific for every page of my Hugo site, I needed to generate the destination URL dynamically for each page's HTML file.
### Implementing Dynamic Redirects with Hugo
Since my site is built with Hugo, I could leverage its templating capabilities. I needed to modify the `` section of my HTML layout to include the meta refresh and canonical tags, but have Hugo insert the correct *relative path* for each page.
Hugo provides the `.RelPermalink` variable, which gives the relative path from the root of the site to the current page (e.g., `/` for the homepage, `/thoughts/` for the thoughts index, `/posts/my-post/` for a specific post). I could combine this with the base URL of my new Netlify site (`https://dandylyons.net`) to construct the full destination URL for each redirect.
Here's the refined code I added to my Hugo `layouts/partials/head.html` (or a dedicated partial for this purpose):
```html
{% comment %} This build is specifically for the GitHub Pages site (dandylyons.github.io) to redirect visitors to the new Netlify site (dandylyons.net), preserving paths. {% endcomment %}
Redirecting to dandylyons.net{{ .RelPermalink }}...
{{/* Construct the destination URL with the correct path */}}
{{ $destinationURL := urls.JoinPath "https://dandylyons.net/" .RelPermalink }}
{{/* Meta refresh for instant client-side redirect */}}
{{/* Canonical tag pointing to the preferred (Netlify) URL for this specific path */}}
{{/* ... Rest of your theme's original head content ... */}}
{{/* IMPORTANT: Remove or comment out the original canonical tag that points to {{ .Permalink }} */}}
{{/* */}}
{{/* ... More head content like RSS, styles, favicons, etc. ... */}}
```
**Key parts of the Hugo code:**
- `{{ .RelPermalink }}`: Gets the relative path of the current page being built.
- `urls.JoinPath "https://dandylyons.net/" .RelPermalink`: Safely joins the base Netlify URL with the relative path to create the full destination URL (e.g., `https://dandylyons.net/thoughts/`).
- `content="0;url={{ $destinationURL }}"`: Creates an instant meta refresh redirect to the dynamically generated destination URL.
- ``: Crucially, tells search engines that the Netlify URL (with the correct path) is the preferred version of this content.
**Important Note:** My theme's default `head.html` already included a canonical tag pointing to `{{ .Permalink }}`. When building for the *redirecting* GitHub Pages site, this tag would incorrectly point back to the GitHub Pages URL. I needed to remove or comment out this original canonical tag in the version of the `head.html` used for the GitHub Pages build to avoid conflicting signals.
### The Build and Deployment Strategy
Since my Hugo source is used to deploy *both* the redirecting GitHub Pages site and the main Netlify site, and they need different `` content, I needed a strategy to manage this.
My workflow already used different branches for deployment:
1. Pushing to `deploy-netlify` triggered a build and deploy on Netlify.
2. Pushing to `deploy-gh-pages` triggered a build and deploy on GitHub Pages (`dandylyons.github.io`).
So I simply pushed one last commit to the `deploy-gh-pages` branch with the modified `head.html` containing the redirect logic. Now I just won't push any more changes to this branch, effectively freezing it in time. This way, the GitHub Pages site will always serve the redirect HTML with the correct path-based logic.
### Preserving the Notes Site and Existing Redirects
An important consideration was my separate notes site at `dandylyons.github.io/notes`. GitHub Pages serves user/organization sites (`username.github.io`) from a specific repository (like `DandyLyons/DandyLyons.io`) but can serve subdirectories from *other* repositories with matching names (like `DandyLyons/notes` for the `/notes` path).
The redirect we implemented is placed in the `DandyLyons/DandyLyons.io` repository and primarily affects the root domain and paths served from that repository. Because `dandylyons.github.io/notes` is served from the `DandyLyons/notes` repository, this redirect process *did not affect* the notes site. It remains functional.
Furthermore, I had an existing redirect configured on Netlify where `dandylyons.net/notes` redirects to `dandylyons.github.io/notes`. This Netlify-side configuration also remains untouched and continues to work as intended, sending visitors who try to reach the notes via my new domain back to the GitHub Pages version.
### SEO and Final Verification
While not a server-side 301, the combination of:
- An immediate (`content="0"`) client-side meta refresh redirect,
- Dynamically generated destination URLs preserving the path,
- And a canonical tag on each redirecting page explicitly pointing to the new Netlify URL with the correct path
is a robust and SEO-conscious approach for this specific static hosting scenario. Search engines are generally good at understanding this pattern for site moves.
The final step was verification:
- Browsing to `dandylyons.github.io/` correctly redirects to `dandylyons.net/`.
- Browsing to `dandylyons.github.io/some-post/` correctly redirects to `dandylyons.net/some-post/`.
- Browsing to `dandylyons.github.io/notes` still loads the notes site on GitHub Pages.
- Browsing to `dandylyons.net/notes` still redirects back to `dandylyons.github.io/notes`.
### Conclusion
Migrating a static site from GitHub Pages to Netlify requires careful handling of redirects to ensure a smooth transition for users and search engines. While a true server-side 301 is ideal, implementing dynamic client-side meta refresh redirects with correct canonical tags via Hugo templating provides an effective path-by-path redirection method for static sites hosted on platforms like GitHub Pages where full server control isn't available. By isolating this redirect logic to the specific build deployed to the old domain's repository and freezing that branch, I successfully deprecated my old GitHub Pages site cleanly while maintaining SEO and preserving my separate notes site.
If you're facing a similar migration challenge with a static site generator, adopting a dynamic client-side redirect strategy tailored to your generator's templating capabilities is a powerful way to manage the transition gracefully.
# Listen Up: Your Guide to Turning Any Text Into Audio
Have you ever felt like there's simply *too much* to read and not enough time? Between articles, emails, reports, and even books, our eyes and brains are constantly bombarded with text. For years, I consumed content the traditional way – with my eyes fixed on a screen or page. But recently, something shifted dramatically. I discovered the power of listening to text, and honestly, it's rapidly become my preferred method of "reading." This isn't about ditching traditional reading entirely, but about opening up a whole new, incredibly flexible way to consume information and entertainment.
## The Multitasking Magic of Listening
The magic of listening lies in its incredible flexibility. Unlike reading, which typically requires your undivided visual attention, listening frees up your eyes and hands. This means you can effectively "read" while doing so many other things! I now happily make my way through long articles, dive into complex reports, or even enjoy entire books while I'm playing a relaxed video game, tackling a pile of dishes in the sink, or enjoying a walk outside. It's perfect for making otherwise passive or routine tasks incredibly productive and entertaining. We already embrace this concept with podcasts and long-form video essays on platforms like YouTube, but why should we be limited to just content *created* in audio format?
## The Text Content Gap
This brings me to a common frustration: the vast ocean of valuable text-based content that *doesn't* have an easily accessible audio version. While many websites, news platforms, and publishers are starting to offer audio narration for their articles and books, it often comes with a catch. You frequently have to pay a premium or subscribe to a specific service to unlock the audio version, even if you already have free or paid access to the text itself. Think of services like Apple News+, Audible audiobooks (where you buy the audio separately), or the "listen" feature on some platforms like Medium, often locked behind their paywall. If I already have access to the text, I just want a simple, affordable (or free!) way to listen to it.
Fortunately, recent advancements in technology offer powerful ways to overcome this barrier: modern text-to-speech (TTS).
## Enter Modern Text-to-Speech (TTS)
Now, when I say text-to-speech, I'm not talking about the choppy, robotic voices of yesteryear. TTS has been around for a long time; who can forget the slightly unsettling, yet groundbreaking, "Hello" from the first Macintosh revealed by Steve Jobs? Compared to today, that voice sounds incredibly primitive. We've entered a new generation of TTS that sounds remarkably natural, often almost indistinguishable from a human voice.
Companies like [ElevenLabs](https://elevenlabs.io/) are truly on the cutting edge of this technology. Their work focuses on generating speech that captures natural human intonation, rhythm, and even emotion. This is a fundamentally different approach than older TTS models, which often struggled with pronunciation of less common words or proper nouns, and read everything in a flat, monotone voice. For instance, a traditional TTS might read "OpenAI" as one single, awkwardly pronounced word ("oh-pen-nai"), whereas advanced models understand it's two distinct concepts ("Open AI") and pronounce it accordingly. It's this leap in naturalness that makes listening to extended text content genuinely pleasant and comprehensible.
## Practical Solutions for Listening to Text
But you don't always need a fancy third-party service to start listening. There are fantastic practical solutions available right now. For iOS users, there's an app called [ElevenReader](https://apps.apple.com/us/app/elevenreader-text-to-audio/id6479373050). What makes it stand out is that it's 100% free and can turn virtually any text content – including plain text, PDF documents, and EPUB ebooks – into high-quality audio using advanced TTS techniques. It requires an internet connection to process, but the convenience and accessibility are unparalleled for turning your existing library into a listening library.
Beyond dedicated apps, your mobile and desktop operating systems also have powerful built-in text-to-speech capabilities. Both macOS and iOS have system-level voices that can read text aloud from almost any application. Now, it's true that many of the default or older voices sound quite mechanical. However, both Apple platforms also offer "Premium" voices. These voices are built using an entirely new, more sophisticated approach to speech synthesis than their predecessors, resulting in significantly better and more natural-sounding audio. Crucially, these premium voices are available at no extra cost and often approach the quality of modern, cutting-edge TTS solutions. An advantage of using these built-in features is their system-wide integration – they can read text in almost any app, and once premium voices are downloaded, they can even work offline.
The main challenge with the built-in OS text-to-speech is that the features are often hidden away in the Accessibility settings, making them difficult for the average user to find and enable. But once you know where to look, you can unlock a powerful tool for turning almost any text on your screen into audio.
## How to Enable Built-in TTS Features
Here’s a quick guide on how to enable these features:
### On iOS (iPhone/iPad):
1. Open the **Settings** app.
2. Scroll down and tap on **Accessibility**.
3. Under the "VISION" section, tap on **Spoken Content**.
4. Toggle on **Speak Selection**. This allows you to highlight text in most apps and tap the "Speak" option that appears in the context menu.
5. Toggle on **Speak Screen**. Once enabled, you can **swipe down from the top of the screen with two fingers** to have the entire visible content of the screen read aloud. A small controller will appear, allowing you to pause, play, adjust speed, and skip forward or backward.
6. Tap on **Voices** to explore and download different language and premium voices. I highly recommend downloading some of the more natural-sounding "Premium" options for your language for the best experience.
### On macOS:
1. Open **System Settings** (or System Preferences on older macOS versions).
2. Scroll down and click on **Accessibility**.
3. In the sidebar, click on **Spoken Content**.
4. Check the box next to **Speak selection**.
5. Click on **Listening shortcut:** to **set a custom keyboard shortcut** to trigger speaking the selected text. Choose a shortcut that is easy for you to remember and use. Once set, simply highlight the text you want to hear and press your chosen keyboard shortcut.
6. Click on **System Voice** to choose your preferred voice. Again, look for the more natural-sounding "Premium" options available for download.
7. You can also enable "Speak announcements" or "Speak items under pointer" based on your needs.
By enabling these features, you empower your device to read almost anything aloud, from webpages and emails to documents and notes.
## The Power of Text-Audio Synchronization
Simply reading text aloud is powerful, but some cutting-edge solutions add a killer feature: text-audio synchronization. Examples include Amazon's WhisperSync for Kindle, the ElevenReader app, and reading platforms like [Readwise Reader](https://readwise.io/read). These apps don't just read the text; they simultaneously highlight the word or line being spoken and automatically scroll the text as the audio progresses.
This synchronization is incredibly helpful. It strongly connects the auditory and visual information, which can significantly boost comprehension. When the audio hits a confusing phrase, you can instantly glance at the highlighted text to clear up any misconceptions. Furthermore, having the text highlighted makes it much easier to follow along, quickly find specific sections, highlight key points, and take notes – marrying the convenience of listening with the interactivity of reading.
## Room for Improvement
While TTS has improved dramatically in just a few short years, these advancements also highlight areas where we still need progress. The technology isn't perfect, and the structure of text content itself presents challenges for purely auditory consumption.
For example, I frequently read technical blogs with code examples. Even the most advanced TTS models sound incredibly strange when attempting to read code aloud. This is a hard problem because, frankly, it's not natural to read code aloud in the first place! Code is designed to be visually parsed and understood, not spoken.
Text also includes many features that simply don't have a natural equivalent in spoken audio. Consider footnotes. Text allows you to interrupt your reading flow to immediately check a footnote, ignore it, or save it for later – it's interactive. I've listened to many audiobooks, and I've never found one that handles footnotes in a truly satisfactory manner. Audio is linear; you can't easily jump around or pause the main narrative to explore a side note and then seamlessly return. The true solution might require TTS reading solutions that have primitives for interactive content structures.
Hyperlinks are another challenge. Sometimes the TTS parser just grabs the visible text and misses the link entirely. Other times, if the text includes markdown or the full URL, the TTS reads out the raw, often lengthy and confusing, link text, which is anything but natural or helpful.
## Impact on the Industry
It's important to recognize that these technological advancements, while beneficial for consumers, have a significant impact on certain industries and jobs. Audio transcriptionists, whose work involved manually converting audio to text, have seen their roles fundamentally changed (and in many cases, made obsolete) by highly accurate AI transcription services. Similarly, the jobs of human narrators for audiobooks and even some podcast voices could be on life support. Why would consumers pay a premium for a human-narrated audiobook if they can simply listen to their ebook using a nearly human-quality AI voice for free or minimal cost?
This is a brutal reality of technological disruption. Change is coming whether we like it or not, and it will require shifts in skills and industries.
However, the bright future is that content can become vastly more accessible to a broader audience than ever before.
## Conclusion
The journey of text-to-speech has brought us from robotic voices to impressively natural-sounding narration. Combined with powerful built-in operating system features, innovative apps offering text-audio synchronization, and the potential of AI integration, listening to virtually any text content is becoming a realistic and incredibly beneficial alternative to traditional reading.
I have a dream that one day, any text can be instantly and seamlessly turned into natural-sounding audio via advanced TTS, and conversely, any audio can be accurately transcribed back into text. Furthermore, that all this text and audio can be synchronized to create a rich, accessible reading experience that empowers everyone, including blind, deaf, ADHD, and neurodivergent people, to consume information in the way that best suits their needs.
And let's not forget the impact on global communication. With Large Language Models (LLMs), any text can now be translated into almost any language for minimal cost. High-quality TTS means that translated text can then be turned into high-quality audio, making information and stories accessible in spoken form across language barriers like never before. This convergence of AI technologies for translation and text-to-speech holds immense promise for humanity, breaking down barriers to knowledge and connection.
So, give listening to text a try – explore the built-in features, experiment with apps, and see how it can transform your content consumption and make every moment a potential "reading" moment. Your ears (and your busy schedule) might just thank you!
# AI Is Not Human But We Sure Think It Is
Look at this picture. What do you see?

If you said "a boy" or "Calvin from _Calvin and Hobbes_" then you're correct in a human sense. You see characters, perhaps even feel a sense of their personality or the story they inhabit. But technically? It's just a collection of lines, shapes, and colors arranged on a surface. **Your brain is doing something powerful and automatic: you are anthropomorphizing this image.**
This tendency to project human qualities onto non-human things isn't a mistake; it's a fundamental part of how our brains work. And it profoundly shapes how we perceive and interact with Artificial Intelligence today. While AI is, at its core, complex algorithms and data, we can't seem to help but treat it... well, like it's a little bit human.
### The Deep-Seated Human Drive to See "Us"
Our brains are wired to look for patterns, agents, and intentions. This is a well documented psychological phenomenon known as [Pareidolia](https://en.wikipedia.org/wiki/Pareidolia), our tendency to perceive meaningful images or sounds in random stimuli. It's why we see faces in clouds, electrical outlets, or the front of cars. We perceive personality and emotion even in simple arrangements of lines, like stick figures or the cartoon characters mentioned earlier.
This isn't a conscious decision; it's an automatic psychological reflex. We are built to find the familiar, the intentional, the *human-like*, even when it's not there.
### Turning Our Anthropomorphizing Gaze on AI
Now, consider AI. Unlike clouds or cars, AI systems communicate with us using human language. They perform tasks we once thought only humans could do – writing articles, creating art, composing music, having conversations that *feel* surprisingly natural, even surprisingly human.
Given our deep-seated tendency to anthropomorphize, and given that AI interacts with us in ways that mimic human behavior, it's almost inevitable that we project human qualities onto it. We don't just see a tool; we *want* to see something more. We imbue it with understanding, intention, and sometimes even feelings, not necessarily because the AI possesses them, but because our brains are primed to perceive them, and the AI's human-like output makes it easy to do so. There's a comfort and familiarity in interacting with something we perceive as having agency or personality.
Worse yet, we feel an uncomfortable relational dissonance if we don't treat AI as if it were human. Our whole lives we were trained to treat people with respect, care and dignity. We were taught to be polite, to say "please" and "thank you," to treat others as we would like to be treated. So when we encounter something else that seems very human, like an AI, we feel a strong urge to apply the same social norms. This explains why so many people feel compelled to say "thank you" to AI systems, even when they know it's just a program. It's a reflection of our social conditioning and our innate desire to connect with others, even if those "others" are lines of code.
### From Everyday Interactions to the Big Screen
You can see this tendency everywhere. People name their AI assistants. We _talk_ to ChatGPT or other language models as if they have opinions ("What do you think of this idea?"). We get frustrated when they "don't understand" or are delighted when they produce something clever, attributing these outcomes to internal states rather than algorithmic processes. We casually discuss AI potentially becoming "conscious" or "sentient," reflecting our innate drive to categorize sophisticated agency within a human-like framework.
This idea was brilliantly explored in the movie *Ex Machina*. The film features a scientist interacting with a highly advanced humanoid AI named Ava. Despite the scientist knowing she is a robot (he can literally see her mechanical brain through her transparent skull), the film masterfully shows how his perception and interaction are constantly battling his rational knowledge against the powerful, human urge to see her as a person, complete with intentions, desires, and feelings. The film highlights the sheer psychological force of anthropomorphism when confronted with something that so convincingly imitates humanity.
### Why Does This Matter?
Recognizing our tendency to anthropomorphize AI isn't just an interesting psychological observation; it has practical implications.
1. **Misunderstanding:** It can lead to unrealistic expectations about what AI is capable of or what its limitations are. AI doesn't "think" or "feel" in the human sense; it processes information based on patterns learned from vast datasets. Treating it as human can obscure this fundamental difference.
2. **Ethical Considerations:** How does our perception of AI influence discussions about its role in society, accountability when things go wrong, or potential future regulations? If we see AI as less than human, or perhaps *too* human, how does that shape our ethical frameworks?
3. **Interaction Design:** Understanding this human bias is crucial for designing AI systems that are both effective and transparent about their non-human nature.
### Navigating the Human-AI Frontier
AI is a powerful and transformative technology. As it becomes more integrated into our lives, our natural human tendency to anthropomorphize will only be amplified.
AI is not human. But our brains are built to think it is, or at least to strongly *want* to see the humanity in it. Developing a more nuanced understanding of AI requires not just learning how the technology works, but also recognizing and managing our own powerful, innate psychological biases – the drive to find the familiar, the intentional, and the human, even in a collection of lines, code, and data.
# AI Is a Moving Goalpost
The term "Artificial Intelligence," or AI, is a perpetually moving goalpost. What we consider "AI" today is vastly different from what we called "AI" in the past, and it's more than likely that this pattern will continue into the future.
## Early Examples of "AI"
When I was a kid, I spent countless hours playing games on the original PlayStation. One of my favorites was Twisted Metal, a chaotic car combat game. You could play with a friend using split-screen, or you could also play alone against computer-controlled opponents. Back then, we referred to these computer players as "AI."
Looking back from today's perspective, calling that AI seems almost silly. The "intelligence" exhibited by those car opponents was extremely limited. They had only one skill – playing that specific game. I'm certain that if I started watching Twisted Metal speedruns, I would see how players have utterly broken the AI, by discovering and exploiting its predictable behavior. At their core, these so-called **AI** were simple algorithms following a predefined set of instructions. While some were more cleverly coded than others, they were fundamentally deterministic and narrow in scope.
Contrast that with the AI we interact with today, especially large language models (LLMs).
## Modern AI: A Paradigm Shift?
Today's AI (e.g., LLMs and diffusion models) is a completely different beast and vastly superior. If you ask an LLM the same question multiple times, you'll often get slightly different answers. This non-deterministic behavior feels more sophisticated, less like a simple script. However, if you look under the hood, this non-determinism largely stems from the probabilistic nature of these models. They work by predicting the next likely token[^1], and developers intentionally introduce a degree of randomness, sometimes choosing the second, third, or even fourth most likely option rather than always the top one. Parameters like "temperature" and the use of different random seeds allow us to influence this variability.
[^1]: A token is a unit of text, which can be as short as one character or as long as one word (or even a few words). For example, "ChatGPT" is one token, while "Chat GPT" would be two tokens.
Regardless of the technical specifics, it's undeniable that today's AI represents a massive leap, a true paradigm shift compared to the "AI" of even three or four years ago.
## The Question: Have We "Cracked" It?
Given this rapid evolution, what makes us so confident that we've finally "cracked it" now? What makes us think that there won't be future paradigm shifts just as significant, if not more so?
It seems very likely that a future generation will look back at the AI we have today and think, "Oh, that's quaint. They called *that* AI back then, but *this* new thing – *this* is the real AI."
## AI as an Alias for the Cutting Edge
The term "AI" has historically served as an alias for whatever is currently at the absolute cutting edge of software capabilities. When a new technological advancement pushes the boundaries of what software can do, we label it "AI." But as that technology matures and becomes commonplace, it no longer feels like the "cutting edge," and the term "AI" is then applied to the *next* breakthrough.
We can see a bit of this tension in AI definitions on the Wikiepedia page for [Artificial intelligence in video games](https://en.wikipedia.org/wiki/Artificial_intelligence_in_video_games). Parts of this page feel like an argument saying _"Well, that's not **real AI**. Look at **this**. This is **real AI**."_
>The term game AI is used to refer to a broad set of algorithms that also include techniques from control theory, robotics, computer graphics and computer science in general, and so video game AI may often not constitute "true AI" in that such techniques do not necessarily facilitate computer learning or other standard criteria, only constituting "automated computation" or a predetermined and limited set of responses to a predetermined and limited set of inputs.
>- [Artificial intelligence in video games](https://en.wikipedia.org/wiki/Artificial_intelligence_in_video_games)
Terms are important and I don't blame the authors of this page for trying to draw a line between what they consider "true AI" and what they consider "automated computation." But I think this is a bit of a red herring. When these technologies were first developed, they were still cutting edge. We didn't realize how limited they were.
## The 1952 UNIVAC I Election Prediction
Consider a historical example: the 1952 US presidential election. CBS News used the **UNIVAC I** computer to predict the outcome – the first time a computer was ever used for this purpose on a major broadcast. Initially, the UNIVAC predicted a landslide victory for Dwight D. Eisenhower, a result that seemed improbable based on early returns. The CBS statisticians were so skeptical they actually delayed reporting the computer's prediction. Yet, as more votes were counted, the UNIVAC's forecast proved to be remarkably accurate. While it was a marvel for its time, using statistical data to aid predictions, by today's standards, we recognize it was essentially a sophisticated statistical model – a program, certainly not conscious or thinking in the way we understand it.
Now, such a statistical model is so commonplace that, for decades, the media has confidently declared the winning presidential candidate, less than 24 hours after polls close, and long **before** the final votes are counted. We look back and might find it amusing that people ever thought that UNIVAC was superintelligent, but people in the 50s should be forgiven for this. It is all too easy for us to see the error in their thinking, but we have the benefit of hindsight.
>**Side note:**
>At the time, this machine was portrayed as a super-intelligent entity, with the broadcast even simulating a natural language conversation between a human and the "AI." Look at [this excerpt from the CBS broadcast](https://youtu.be/nHov1Atrjzk) at 1:05. The reporter speaks to the UNIVAC I, machine in natural language, plain English, on camera, as if the machine has any way of understanding what he is saying. But this is just a silly farce. The UNIVAC I had no large language model, and certainly no understanding of natural language. It **did** have a sophisticated statistical model, but the whole "talking to the machine" schtick was just silly media nonsense theatrics.
## Conclusion
If we feel so much smarter looking back at their definition of AI, perhaps we should pause and ask ourselves: What will the next generation think of *our* AI? The moving goalpost suggests they'll likely see it as just another step on a much longer journey.
# AI Is Not Logical, It's Probable
## Sci-Fi vs. Reality
For decades, science fiction painted a picture of AI as purely logical beings. Think of C-3PO, the protocol droid meticulously adhering to rules, or Data from Star Trek, striving to understand humanity through pure logic and data processing. We were led to believe AI would be predictable, rational, and perhaps a bit rigid in its adherence to algorithms.
But the reality of modern AI, particularly the large language models (LLMs) powering many of today's applications, is quite different. AI regularly surprises us with its creativity, humor, and even emotional depth, and yet AI often behaves in ways that are completely irrational or just straight-up wrong. How can this be?
It turns out AI isn't primarily logical. It's probable.
## How AI Works
These sophisticated systems don't "reason" in a human sense. Instead, they work by predicting the most statistically probable next word in a sequence based on the vast amounts of text data they were trained on. They identify patterns and relationships, generating responses that *look* logical or creative because they are statistically likely completions of a thought or query.
It's a fascinating shift from our sci-fi dreams. If you want a clear, visual explanation of how this "probability machine" works, check out 3Blue1Brown's excellent explainer: [Large Language Models explained briefly](https://www.3blue1brown.com/lessons/mini-llm). It breaks down the core concepts simply and effectively.
The age of **probable** AI is here, and understanding how it truly functions is key to navigating our increasingly automated world.
# How to Always Be Right
# How to Always Be Right and Never Ever Wrong
>Yes, you read that right. I promise, in the span of this short blog post, to teach you how to always be right and never ever wrong. And I even promise that this article won't be half as click-baity as that headline makes it seem.
When I graduated from High School, my father, lovingly forced me into my first summer job. I was an assistant for the local summer fun program. We were the glorified baby sitters of the community. Little did I know, this thankless, unpaid job would eventually teach me a valuable life lesson.
## The Summer Fun Program
During this summer we had the kids play many fun activities. Freeze tag. Basketball. Dodgeball. Except we were really worried about kids getting hurt (including their self-esteem) so every game had it's own politically correct twist. Kids didn't have to stay frozen during freeze tag because, it would hurt their feelings. We didn't keep score during basketball for the same reason. And in Dodgeball... Well this one took the cake.
First of all, we didn't play with real rubber balls. We played with ultra soft foam balls. I swear, if you could get injured by one of these balls then you've got bigger problems because apparently you have brittle bones. But there was another rule that astonished me.
Unlike in dodgeball, when a child was hit by a ball thrown by the other team, they were not kicked out of the game. Actually, they simply switched teams to the other side. This was the rule: if you got hit by the ball then you need to switch to the other team. As I watched them play through this game I realized that this wasn't a penalty. No, they were actually being rewarded for being hit by the ball. Because, if you got hit by a ball then, more likely than not, you were on the side with less people, and now you were supposed to transition to the side with more people. In a few short minutes one side kept getting more and more kids until they completely overwhelmed the opposing team. Each child was disappointed to be "losing" yet forgot all that disappointment as soon as they realized they were now on the "winning" team.
At the time, I was so frustrated by how PC this game was. How it was so afraid of hurting our children's feelings that it sheltered them from the inevitable age-old life lesson: "You win some, you lose some." And I do still hold that criticism against this game. However, many years later, I realized that this taught me a valuable insight about arguments.
## About Arguments
You see, in many ways, dodgeball is quite similar to an argument. In most arguments we seem to have a concept of "winning" and "losing". We say to ourselves *Oh no, I must not lose this argument.* We also think in terms of sides or teams. *Are you on my side or theirs? Are you with me or against me?* We hate when someone proves that we are wrong because we think that it means that we "lost" and they "won". We can't bear the humiliation of loss, so we keep stubbornly holding onto our arguments, even when we know that we are wrong.
This is the ugly side of arguments. But why does it **have** to be this way? Why must there be winners or losers? What if we simply admitted that we were wrong?
You see, a really interesting thing happened during those PC dodgeball games. First of all, the kids were **still** disappointed when they were hit with the ball. Proof that kids are kids, and they're going to find something to cry about no matter how hard you shelter them. But something else happened that surprised me. Stubbornness. Most kids, simply refused to acknowledge or even believe that they had been hit by a ball. No matter what, they denied it. They were in tears.
But the ironic thing is that if they simply admitted that they got hit, then they would move from the losing team to the winning team and all their disappointment would go away.
**Hey isn't that just like an argument?**
## Why Not Just "Lose" the Argument?
In life, it's only a matter of time until you step into an argument with someone. And it's only a matter of time until you pick the wrong side and someone else proves that you are wrong. This is a humiliating place to be. No one likes to be proven wrong.
But why? If you simply admit that you are wrong, then you are saying that you no longer believe what **you** used to believe. You now believe what **they** believe. You have just switched sides, which means that you are not wrong anymore. Are you catching what I'm saying? Admit that you're wrong, and then now you are not wrong anymore. Now you are right.
## How to Always Be Right
So how can we always be right? Simple. Admit when you are wrong.
Some might call this "flip-flopping" but I think there's a much better name for this: humility. True, if you simply switched to whatever argument is the most popular, and you flip-flop to another side even when you don't actually agree with it, then yeah, that would be flip-flopping. But if you actually believe that you are wrong and you actually change your mind to the thing that you now think is right, then that's not flip-flopping, that's just being humble. That's called growth.
If you are actually wrong, then just admit it. You're wrong. It's not that big of a deal. It's not the end of the world. And in fact, once you admit you're wrong, then now you've changed your beliefs, and you are no longer wrong anymore. Now, you're right!
So, what if we lived that way all the time? What if we stopped caring so damn much about being "right" or "winning". What if we instead focused on finding the truth? Wouldn't that be easier? Then we no longer have to worry about our ego, or "winning". Then, if someone else "wins" and proves us wrong, it's no longer a threat to us. Now, instead of being mad at someone we can thank them for proving us wrong, because what's really happening is they are showing us the truth. And shouldn't we be happy when someone has shown us the truth?
So the next time you find yourself in an argument, ask yourself: "Am I actually right?" If you are, then great! But if you're not, then just admit it. You're wrong. Then just switch sides and now you're right again! 🏆
# Post Expertise Scarcity
# Post Expertise Scarcity
There's a scene in the early-2000s medical sitcom [Scrubs](https://www.imdb.com/title/tt0285403/) where an older hotshot doctor is visiting a patient. He reads off a bunch of stats about her medical tests and tells her all about her diagnosis, but she constantly finishes his sentences before him. How? Google. She's using this new-fangled device called a smartphone[^1] and looking up all the answers faster than he can even say them.
[^1]: Of course, I can hear people saying, "But wait! The iPhone didn't come out until 2007!" This is revisionistic. The scene is set in 2001, and the iPhone was not released until 2007. But the smartphone was already a thing, they just weren't good yet.
She's convinced that she doesn't need a doctor. She can look up whatever she needs to on Google.
## Post Information Scarcity
Twenty or so years later, that scene practically seems quaint now. What used to be novel and somewhat rare is now so commonplace that it's taken for granted. Everyone has a smartphone, and everyone has Google, and everyone thinks they know everything. Everyone thinks that they can prove someone wrong with just a bit of internet research. We even have a word for it now, _factchecker_.
But alas, hindsight is indeed 20/20. We obviously know that a mere Google search is not a good replacement for a doctor. Sure, she can look up any information she wants instantaneously, but most of that information is crap. All of us have encountered someone who thinks that they know more than the experts just because they can search up the answers to any question. But quite often, that person is proven to be a fool after just a few more Google searches.
Evidently, the patient in that scene thought that she didn't need experts because she could find any answer instantly. And evidently, she was wrong. We do still need experts.
That certainly is the argument of Cal Newport's book [Deep Work](https://search.worldcat.org/title/908704985). I finally started reading this book a few weeks ago, and that is one of the core takeaways that I got from it: **We have entered an age of post information scarcity.** It used to be that if you wanted to know the things that doctors know, then you had no other choice than to go to medical school. That information was locked away in lecture halls and expensive textbooks behind brutally hard entrance exams and shockingly steep tuitions. But now that information is just a Google search away. Getting the information is no longer a problem. We live in an age of post information scarcity. In this new age, it is no longer extremely valuable to simply be someone who knows more information than those around you. What's truly valuable is to be an expert, someone who has taken the time and effort to deeply understand a topic and master a skill.
When I read this idea from _Deep Work_, I was struck by how insightful it was. I was also struck to realize that it's not true anymore.
## Post Expertise Scarcity
What if I told you that you can ask deep questions in any topic and receive deep answers with citations in a matter of minutes, often just a few seconds? That reality is already here today, and it has many names: DeepSeek R1, ChatGPT, Claude, Perplexity, etc., ad nauseam.
Don't get me wrong. I'm fully aware that these systems are not perfect. Far from perfect, they are also hilariously wrong at times. But that doesn't matter, and here is why:
1. **They are improving rapidly.** They are far more accurate than they were even two years ago.
2. **They answer far faster than any human, even experts.** Even a wrong answer can help you in your search for the right answer. And AI generates 20 wrong answers before an expert human has the chance to finish their first answer.
3. **They never get tired, and they are available 24/7 worldwide.** This is the final nail in the coffin. No human expert will ever be able to compete on this metric.
**We have entered an age of post expertise scarcity.** It used to be that if you wanted the deep knowledge and understanding that only experts have, then you had no other choice than to become or hire an expert. That information was locked away behind paywalls, invoices, subscription fees, and a million other mechanisms. But now that expertise is just a prompt away. Finding expert opinions is no longer a problem. We live in an age of post expertise scarcity. In this new age, it is no longer extremely valuable to simply be an expert at a particular topic or skill. What's truly valuable is…
🤔 Hmm… I need to think more about that. But that's a thought for another day…
# Penny for Your Thoughts?
For a long time I have been wanting a place to share my thoughts out loud. This site has been a fantastic creative outlet for me but I have found a few issues. Mostly just one, it takes a very long time to write a single blog post. My posts tend to be technical and include code examples, so it is really important that my code examples actually do what they are supposed to. I would really hate it if someone read my article, was excited to try the code, and then found out the whole thing didn't compile at all. So that means that I need to read and re-read my posts. I need to research them and think about them deeply.
By the time, I finally have something that is publishable, I feel burnt out writing this. This means that a lot of great ideas simply never see the light of day. This has gotten me thinking for a while, that I'd like to try another model.
## Ephemeral Posts
I've really liked [Michael Tsai's blog](https://mjtsai.com/). His posts are often very short, just a half page or so. Most of the post is a collection of tweets from that day, that share a similar topic, and Michael will add a paragraph or two of his own commentary. I don't imagine it takes him very long to craft these posts at all. And in fact, he often posts three or four of these a day. What I love about these posts is how very **present** they are. Each one feels like a little photograph of the iOS developer community at that exact moment.
## Evergreen Posts
On the other end of the spectrum is a writer like Paul Graham. His blog takes such a different approach that it doesn't even call itself a blog. It has a [section of "Essays"](https://paulgraham.com/articles.html) and that makes sense because these articles don't exactly feel like *blogs*. These have a decidedly different tone. They are much longer, more thought out, and cover deeper subjects. Furthermore, they are evergreen. He repeatedly seems to strive for content that is timeless, that will continue to be relevant for generations to come.
## Tradeoffs
So which approach is better? Well that's really a silly question. Neither is better. They are trying to accomplish different goals. One is up to the minute current events, and the other is distilling long sought after wisdom. So asserting that one approach is better than the other is pretty foolish.
But which approach would I like to use? Well that is a much better question. And my answer is that I'd like to do both approaches. Going forward, this personal site will have a few feeds...
## Upcoming Changes
So far, I have had these sections on this site:
- [Posts](https://dandylyons.net/posts/): This is my blog so far, mostly technical writing about programming topics.
- [Projects](https://dandylyons.net/projects/): These are mostly announcements for apps or other things that I have released.
- [Notes](https://dandylyons.net/notes/): This is a link to my [digital garden](https://dandylyons.net/notes/Topics/Learning/Digital-Garden) which is made in [Obsidian](https://obsidian.md/).
Starting today, I'm adding **two** more:
- [Thoughts](https://dandylyons.net/thoughts/): These are short *ephemeral* posts. Longer and more substantive than a silly tweet, but not as polished as a **post** or an **essay**.
- [Essays](https://dandylyons.net/essays/) (Coming soon...): These are the longer, more thought-out ideas. They will tend to be more evergreen, polished, and more friendly to non-programmers.
So basically this is one big experiment, and I hope it will be a fun ride!
# Icons in SwiftUI
# Icons in SwiftUI
Icons are an incredibly powerful technique in modern UI design. They can convey meaning, add visual interest, and enhance the overall user experience. They can also take a lot of time to create and implement. Thankfully, SwiftUI comes with a built-in library of icons that you can use in your apps called SF Symbols. While SF Symbols are a fantastic resource, they still have a limited selection of icons (and very strict Apple guidelines). In this article, we’ll explore how to use SF Symbols in SwiftUI, we'll learn about another open-source icon library, and finally we'll learn how to create custom icons that fit your app’s design language.
## Using SF Symbols in SwiftUI
SF Symbols are a set of over 6,000 icons designed to work seamlessly with Apple’s system fonts. They are vector-based, which means they can be resized without losing quality. This makes them perfect for use in SwiftUI, where you can easily adjust their size and color to fit your design.
But even better, each SF Symbol is designed to work with the system font. This means that Apple not only designed thousands of icons, they also designed several iterations of each icon for each system font weight. This means that you can use SF Symbols in your app and they will automatically match the system font weight of the text around them. This is a huge advantage over other icon libraries, which often require you to manually adjust the size and color of each icon to match your design.
Using an SF Symbol is astonishingly simple. You can simply pass a string to load the icon you want.
```swift
Image(systemName: "star.fill")
// You can also inline the icon in a Text view
Text("Star \(Image(systemName: "star.fill"))")
// You can also use the icon as a button
Button("Favorite this item", systemImage: "star.fill") {
// implement your action here
}
// You can also use an image in a label
Label("Favorites", systemImage: "star.fill")
```
SF Symbols even have multi-color rendering modes:
```swift
Image(systemName: "star.fill")
.symbolRenderingMode(.multicolor)
```
And SF Symbols even have an expressive, simple animation system. You can use the `.symbolEffect` modifier to add a simple animation to your SF Symbols.
```swift
Image(systemName: "star.fill")
.symbolEffect(.pulse)
```
Be sure to check out Paul Hudson’s article [How to Animate SF Symbols](https://www.hackingwithswift.com/quick-start/swiftui/how-to-animate-sf-symbols).
So what more is there to want? Well, even though SF Symbols have an ever-growing library of icons, there are still many icons that are missing. In particular, I often find that I want an icon that is a logo for a specific service, e.g. Youtube, or Mastodon. But SF Symbols don’t have these icons. Also, I often find that I want to combine multiple icons together to create a new more expressive icon. Sure, I could simply place one icon on top of another, but this is not a very elegant solution. I lose all the built-in benefits of accessibility, font weight adjustment, animation etc. So what can we do? Let's look at some alternatives.
## Using Lucide Icons in SwiftUI
Lucide Icons is an open-source icon library that contains over 1,000 icons. Lucide Icons are also vector-based, which means they can be resized without losing quality, and it's easy to edit them or change their color to match the look of your UI. This makes them perfect for use in SwiftUI, where you can easily adjust their size and color to fit your design. You can find the full list of icons on the [Lucide Icons website](https://lucide.dev/).
Perhaps the easiest way to use Lucide Icons in SwiftUI is to use the [LucideIcons](https://swiftpackageindex.com/JakubMazur/lucide-icons-swift) Swift Package. This package contains all of the icons in the Lucide Icons library, and it’s easy to use in your SwiftUI projects.
```swift
if let uiImage = UIImage(lucideId: "tada") {
Image(uiImage: uiImage)
}
```
While this is a very convenient way to use Lucide Icons in your Swift project, depending on this package does increase the size of your project. In practice this probably doesn't matter much at all. Lucide Icons are SVG files, which are incredibly small. Also, I believe only the icons that you use in your project are included in the final build. But if you'd like to avoid a dependency, you can also use the SVG files directly.
## Using SVG files in SwiftUI
SVG files can be stored in your project and used directly in SwiftUI. But using them isn't quite as simple as loading an SF Symbol in a SwiftUI view. Thankfully Exyte's library [SVGView](https://swiftpackageindex.com/exyte/SVGView) makes this much easier.
```swift
if let url = Bundle.main.url(forResource: "example", withExtension: "svg") {
SVGView(contentsOf: url)
}
```
## Converting SVG Files to SwiftUI `Path` Views
If you ever read an svg file, you'll learn that they are just directions for drawing a path. If you look inside a web page's HTML, you might see something like this:
```html
```
That's the [Lucide Icon for a smiley face](https://lucide.dev/icons/smile). While this is definitely not the most readable format, it's really just a set of instructions for drawing a path. Say, doesn't SwiftUI also have an API for drawing paths? Yes, it does! You can use the `Path` view to draw a path in SwiftUI. You can find [Apple's official tutorial here](https://developer.apple.com/tutorials/swiftui/drawing-paths-and-shapes). This API is much more human-readable than SVG, and it's also deeply tied into the animation system in SwiftUI. So if you want to create a custom icon, you can use the `Path` view to draw it.
If only there were a way to easily convert SVG paths into SwiftUI `Path` views, allowing for seamless integration of custom icons into your projects. Well apparently there is! Quassum made an incredibly helpful, simple web tool called [SVG to SwiftUI](https://svg-to-swiftui.quassum.com/) that allows you to convert SVG paths into SwiftUI `Path` views. You can simply paste the SVG path into the tool, and it will generate the SwiftUI code for you. So for example, we can go to Lucide, copy the SVG path for the smiley face icon, and paste it into the tool. The tool will generate the following SwiftUI code:
```swift
struct MyIcon: Shape {
func path(in rect: CGRect) -> Path {
var path = Path()
let width = rect.size.width
let height = rect.size.height
path.move(to: CGPoint(x: 0.14583*width, y: 0.54167*height))
path.addLine(to: CGPoint(x: 0.39583*width, y: 0.54167*height))
path.move(to: CGPoint(x: 0.08333*width, y: 0.66667*height))
path.addLine(to: CGPoint(x: 0.27083*width, y: 0.29167*height))
path.addLine(to: CGPoint(x: 0.45833*width, y: 0.66667*height))
path.move(to: CGPoint(x: 0.75*width, y: 0.29167*height))
path.addLine(to: CGPoint(x: 0.75*width, y: 0.66667*height))
path.move(to: CGPoint(x: 0.58333*width, y: 0.5*height))
path.addLine(to: CGPoint(x: 0.75*width, y: 0.66667*height))
path.addLine(to: CGPoint(x: 0.91667*width, y: 0.5*height))
return path
}
}
```
While this code is much longer, it's also much easier to read and it can be used in your SwiftUI project to create a custom icon. You can also use the `fill` and `stroke` modifiers to change the color of the icon, and you can use the `animation` modifier to add animations to the icon!
## Creating Custom SF Symbols
SVG symbols bring so much of the power of SF Symbols. They're scalable, we can easily change their color, and by converting them into a SwiftUI `Path` view, it's easy to animate them and change their line width. But they are still not deeply integrated into the font system like SF Symbols are. So what if we could create our own SF Symbols? Well, it turns out that you can!
Check out this article by [_David Smith](https://david-smith.org/blog/2023/01/23/design-notes-18/) on how to create custom SF Symbols.
## Conclusion
So to recap our journey, we started with SF Symbols, which are a great resource for icons in SwiftUI. But they have a limited selection of icons. Then we looked at Lucide Icons, which is one of many open-source icon libraries that contains over 1,000 icons in many common formats including SVG files. Then, we looked at how to convert SVG files into SwiftUI `Path` views, allowing us to create custom icons that fit our app’s design language. Finally, we looked at how to create our own SF Symbols, which allows us to create custom icons that are deeply integrated into the font system.
# Introducing: "Let There Be Sight" now in beta!
# **Introducing the Beta of Let There Be Sight: Alt Text Made Easy**
Today, I'm excited to announce the iOS beta release of my latest project: **Let There Be Sight** — an app that makes it easy to describe any image with text. You can try it for free today via TestFlight:
👉 [Join the beta on Apple TestFlight](https://testflight.apple.com/join/E3uFbmZp)
But before you dive in, let me explain why this app matters.
## Why Alt Text Matters
If you’ve spent any time in communities like Mastodon or Bluesky, you’ve probably seen people talking about the importance of alt text — short textual descriptions of images that make them accessible to people using screen readers.
For those with vision impairments, alt text isn’t just helpful — it’s essential. Without it, large parts of the internet are simply invisible. No one should be excluded from participating in the digital world because of how they experience it.
But the benefits of alt text extend beyond accessibility:
- **Improves discoverability and SEO**
- **Translatable** for international audiences
- **Readable aloud** in text-to-speech apps and article readers
- **Helpful for neurodivergent users**
- **Useful on slow or unreliable connections**
- **Clarifies ambiguous or complex visuals**
In short: alt text makes content more useful, more inclusive, and more future-friendly.
### Alt Text Is Not Just Nice To Have. In Some Contexts It Is Legally Required.
In many jurisdictions, including the United States and the European Union, accessibility isn’t optional — it’s the law. For example, Section 508 of the Rehabilitation Act in the U.S. mandates that federal agencies make their digital content accessible to people with disabilities, which includes providing alt text for images. The Americans with Disabilities Act (ADA) has also been interpreted to apply to websites, especially in public-facing industries.
Failure to comply can result in lawsuits, fines, or reputational harm. But more importantly, it's a moral imperative. Ensuring equal access to information is simply the right thing to do.
## The Problem: Writing Alt Text Is Hard
Despite all those benefits, writing good alt text is still a hassle. It takes time, it requires empathy and nuance, and it’s easy to get wrong. Most of us aren’t trained in how to write it well, and as a result, we often skip it — even when we mean well.
To write truly helpful alt text, you have to think carefully about what information matters in a given context. A picture may be worth a thousand words, but only a few of those words actually serve the reader. The rest can be noise.
The official guidelines (like [these from Section 508](https://www.section508.gov/create/alternative-text/)) show how subtle and context-sensitive great alt text can be.
## Let There Be Sight: Alt Text, Simplified
Let There Be Sight is built to make this easier. The app helps you describe images quickly, accurately, and contextually — without needing to be an expert in accessibility. Whether you're posting to social media, blogging, building a website, or just trying to make your content more inclusive, the app is here to help.
Currently, the app is very simple. You can add an image (from your photo library, camera, or files). Then you can tap a button and in a few seconds, a highly accurate, helpful text description is generated. This text can then be copied and shared to other apps.
But stay tuned — I have some very interesting features planned to make the app even better.
## How Much Is This All Gonna Cost?
The app will be free to install and use. There will be paid premium features. During the beta, the premium features are free.
### How Much Do The AI Models Cost?
Currently, this app uses models from two providers: OpenAI and Google Gemini. In order to use these models, you must bring your own API keys. It's free to get an API key from a provider, but it does cost money to use a model, and you must purchase your credits in advance from a model provider.
But here's a helpful tip: Google Gemini is currently offering "experimental" models for free! You can use these models at zero cost. (Though it is worth mentioning that these experimental models are rate-limited.)
In the future, I hope to offer on-device AI models that will be free, faster, and won’t send your private information to someone else.
---
Try the beta today and help shape the future of accessible content:
👉 [Download via Apple TestFlight](https://testflight.apple.com/join/E3uFbmZp)
Let’s make the web better — for everyone.
# Swift Error Handling: The Solution
# Swift Error Handling: The Solution
In our last post [Swift Error Handling: The Problem]({{< ref "posts/swift-error-handling-the-problem/index.md">}}) , we discussed the problems with error handling in Swift. In this post, we will explore some solutions to these problems and how to implement them in your code, and we will preview my new [Catcher](https://swiftpackageindex.com/DandyLyons/Catcher) library which provides a variety of tools following these patterns. 19|
But alas, my library is not **the** solution. It is only **a** solution. In the last section, we will discuss some potential new Swift features that could eliminate these problems altogether.
## Recap of the Problem
First let's define the problem, so that we can define our requirements. If you recall the core problem with Swift's error handling system is that:
1. `do` blocks with multiple `try` statements are problematic because:
1. When the function errors and jumps to the `catch` block, it is not clear which `try` statement caused the error.
2. (Most of the time) the error is untyped, so you have to dynamically cast it to the correct type before you can read and handle it.
3. The result of the `try` statement is not available outside of the `do` block, so in practice you end up putting more work in the `do` block (which only exacerbates the problem).
4. Thrown errors abruptly exit the `do` block, which creates multiple code paths you have to consider.
2. Swift actually has TWO type systems:
1. The type system for the function signature including the return type.
2. The type system for the thrown error.
## Designing the Requirements
Now that we have defined the problem, let's define our requirements for a solution.
1. We need a solution that doesn't require us to be in a throwing context.
2. When we catch an error, there should be no ambiguity about which `try` statement caused the error.
3. We should be able to extract the result of the `try` statement outside of the `do` block.
4. It should be easy to handle the error meaning:
1. We should preserve the type of the error if it came from a typed throws function.
Ideally the solution should be built into the language, but alas, it is not. So we will have to implement it ourselves. But the Swift language has already natively fixed similar prblems in the past. With a little bit of elbow grease, we can repurpose some of these existing language features to solve our problem.
## Defining the Scenario
When designing a solution to a problem like this, I find that it is often helpful to define a very simple scenario to work with. This allows us to work on a specific small problem, and then we can generalize the solution to work with any problem in the future.
```swift
enum MyError: Error, Sendable, Equatable {
case error1
case error2
}
func success() throws(MyError) -> Int {
return 1
}
func failure1() throws(MyError) -> Int {
throw MyError.error1
}
func failure2() throws(MyError) -> Int {
throw MyError.error2
}
func mightThrow() throws(MyError) -> Int {
if Bool.random() {
return try success()
} else {
return try failure1()
}
}
```
In this scenario we have a few throwing functions that returns an `Int` and throws a `MyError` error. What we really want and care about is the return result of the function. But sometimes we don't get a result at all. Sometimes the function exits before it has finished executing. So we need to handle that case as well.
## Why We can't use `try?` or `try!`
The common "Swifty" way to handle this is to use `try?` or `try!`. But these only partially solve the problem.
```swift
func openInt() -> Int {
guard let int = try? success() else {
// handle error
return
}
}
```
This code is incredibly helpful and concise. It is doing so many things for us. It is:
1. Running the throwing function safely even though it is not in a throwing context like a `do` block.
2. Handling the error by converting the function result to an optional.
3. If the function succeds then the result is assigned to the `int` variable.
4. `int` is now available anywhere else.
5. If the function throws an error, then we jump to the `else` block and we must exit the function.
It makes sense that this is such a popular method in the Swift community. It has a lot of benefits:
1. It forces you to handle the situation where the function fails.
2. It's concise and fairly easy to understand.
3. The `int` variable is now available anywhere else in the function.
4. The `int` variable is now unwrapped, so you don't have to worry about it being `nil`.
5. There are only two code paths to consider: success and failure.
But it has one major problem. Do you see it?
The problem is that we never get access to the error. We can't actually say that we handled the error. We did not handle the error. How could we have handled the error if we never even read it? We don't even know what the error was. We just ignored it. In the `else` block we know absolutely nothing about the error other than that it happened. We don't know what caused it, we don't know how to fix it, and we don't even know what the error was. Despite this massive problem, we can reuse these same tools to make a much better solution.
## From Two Type Systems to One
Remember that a throwing function effectively has two return types:
1. The return type of the function.
2. The error type of the function.
But is there a way to combine these two types into one? Yes! In fact, it is already built into the language.
## Converting Throwing Functions to Result Types
The `Result` type is a generic type that can be used to represent either a success or a failure. If you look at the open source code for the `Result` type, you will see that it is defined as follows:
```swift
public enum Result {
/// A success, storing a `Success` value.
case success(Success)
/// A failure, storing a `Failure` value.
case failure(Failure)
}
```
This type is extremely simple. We just have a simple enum with two cases: `success` and `failure`. The `success` case stores the result of the function, and the `failure` case stores the error, and the error must conform to the `Error` protocol. This is exactly what we need. We can use this type to represent the result of our throwing function.
At first, I thought to myself, we could just convert our throwing function into a `Result` type. I didn't realize that Swift already had this built-in as well. Let's look at my solution first.
```swift
public func result(
for op: @autoclosure () throws -> Value
) -> Result {
do {
return Result.success(try op())
} catch {
return Result.failure(error)
}
}
```
Here we have a function that takes a throwing function and returns a `Result` type. This gives us two benefits:
1. We do not need a throwing context to call this function (like a `do` block or a `throws` function).
2. We immediately get the result of the function and can use it anywhere else. It is not stuck in a `do` block.
Let's look at how to use this:
```swift
func openInt() -> Int {
let result = result(for: try success())
switch result {
case .success(let int):
return int
case .failure(let error):
// handle error
return 0
}
}
```
Well, this isn't that much better. Our result may not be stuck in a `do` block, but it's still stuck in a `switch` statement. So we basically have the same problem. There is at least one benefit however. The Result type makes it easy for us to delegate the error handling to another function. And since `Result` is `Codable` it's easy to send over the network or persist to disk.
### The Built-in Solution
After getting some helpful feedback from the community, I learned that `Result` already has an initializer which conveniently takes a throwing function and returns a `Result` type. This is exactly what we need.
```swift
let result = Result { try success() }
```
This is a much better solution. However, there is a small way that we can improve it. I'll make a new initializer that simply delegates the real implementation to the existing one.
```swift
extension Result {
public init(for op: @autoclosure () throws -> Success) {
self = Result { try op() }
}
}
// example usage
let result = Result(for: try success())
```
There is one small, but meaningful difference. I added an `@autoclosure` attribute to the function. This means that we can directly pass in the function without having to wrap it in a closure. But what I really care about is this: we can input one and only one `try` function. Remember that we are trying to solve the problem of having multiple `try` statements in a `do` block. The reason why we want to avoid having multiple `try` statements in a `do` block is because we don't know which one caused the error. But with this new initializer, we can only pass in one `try` statement. So we know exactly which one caused the error. We'll be reusing this pattern a lot.
### Extracting a Value from a Result
It is worth mentioning that `Result` has a function called `get()` that will return the value of the `Result` type. This is fantastic! Except... `get()` is a throwing function. So we have to be in a throwing context to call it. We're basically right back where we started.
This is not totally a loss however. We've discovered a way to convert a throwing function's two return types into one. While the `Result` type may not be the best choice in many use cases, it can still be quite helpful in some cases, for example if the best place to handle the error is on a different device over the network.
Let's review our requirements and see how we did:
1. We need a solution that doesn't require us to be in a throwing context.
- ✅ We can conveniently convert to a `Result` type without being in a throwing context.
2. When we catch an error, there should be no ambiguity about which `try` statement caused the error.
- ✅ The `@autoclosure` attribute forces us to pass in a single `try` statement.
3. We should be able to extract the result of the `try` statement outside of the `do` block.
- 🤔 We sort of passed this. We can extract the result from the `Result` type, but we have to be in a throwing context to do so.
4. It should be easy to handle the error meaning:
- ✅ We can use the `Result` type to preserve the type of the error.
Now, is there another way that we can convert a throwing function to a non-throwing function that will be more helpful? Yes!
## Converting Throwing Functions to Non-Throwing Functions
I did create a function that converts a throwing function to a non-throwing function, but as you'll see, it doesn't have that big of an advantage:
```swift
public func doTry(
_ op: @autoclosure () throws(E) -> Void,
catching errorHandler: (E) -> Void
) {
do {
try op()
} catch {
errorHandler(error)
}
}
// example usage
doTry(try mightThrow()) { (error: MyError) in
// handle error
}
```
You might be thinking, "Wait a minute! This is just a `do` block with a `catch` statement!" And you would be right. Just like the last solution, the closure is an `@autoclosure` so we can only pass in one `try` statement. So when we catch the error, we know exactly which `try` statement (because there is only one). And if the function has a typed thrown error, then we even know the error type at compile time (just like a Swift 6 `catch` block). Unfortunately in my tests, it seems like Swift 6 is not able to infer the error type, so we have to explicitly declare the error type, which is a bummer. Hopefully that improves in the future. So, to recap, the only real advantage of this function is that it forces us to pass in a single `try` statement.
Let's keep searching for a better solution.
## Converting Throwing Functions to Optional Types
There's a very old problem that plagues virtually every programming language. It's the problem of having to check for `nil` values. In Swift, we have a very nice way of handling this with optionals. We can use optionals to represent a value that may or may not exist. The advantage is that Swift will force you to handle the case where the value is `nil`.
### The "Trapped Scope" Problem
But there is another problem which plagues so many programming languages. I call it the "Trapped Scope" problem. This is when you "unwrap" a value but you are now in a different scope, so you can't use the unwrapped value in the old scope. You must somehow unwrap the value in the new scope, then safely pass it back to the old scope. For example:
```swift
func add1(to int: Int?) -> Int? {
if int == nil {
return nil
} else {
return int! + 1
}
}
```
This ugly code should trigger any Swift developer because the language has a built-in solution for this. But it can be helpful to not use the built-in solution to understand the problem. Here, we want to add 1 to an optional `Int`. But we have to check if the `Int` is `nil` first. If it is, we return `nil`. If it isn't, then we know that it is safe to use the `int` variable. Currently, this code is safe, but it is very easy to make a mistake.
For example, we can safely force unwrap the `int` variable, but only inside of the `else` scope. In the `else` scope we know that the `int` variable is not `nil`, but in any other scope we don't know that. Thankfully, Swift has a built-in solution to this problem called `if let` which forces us to handle this correctly.
```swift
func add1(to int: Int?) -> Int? {
if let unwrappedInt = int {
return unwrappedInt + 1
} else {
return nil
}
}
```
Now the code is not only safe but Swift prevents us from using the `unwrappedInt` variable unless we are certain that it is not `nil`. For example, this will not compile:
```swift
func add1(to int: Int?) -> Int? {
if let unwrappedInt = int {
return unwrappedInt + 1
} else {
return unwrappedInt + 1
// error: 'unwrappedInt' is not defined in this scope
}
// `unwrappedInt` is not defined here either
}
```
This is a great solution, but, for some use cases, it creates a new ergonomics problem: the "Trapped Scope" problem. This is when you "unwrap" a value but you are now in a different scope, so you can't use the unwrapped value in the old scope. But Swift has a clever solution for this problem as well, the `guard let` statement. We can rewrite the above like this:
```swift
func add1(to int: Int?) -> Int? {
guard let unwrappedInt = int else {
return nil
}
// `unwrappedInt` is now available in this scope
// and all scopes below this one
return unwrappedInt + 1
}
```
This is the super power of `guard let`. It allows us to "unwrap" a value and use it in the same scope. This is a very powerful tool and we can even reuse this pattern to "unwrap" a throwing function.
Recall that an `Optional` is just a simple enum like a `Result` type. It is defined like this:
```swift
public enum Optional {
case none
case some(Wrapped)
}
```
This is extremely similar to the `Result` type. However, there is no associated value for the `none` case. What if we simply handled the error before converting to a `nil` value? Let's create a new initializer for the `Optional` type that takes a throwing function and returns an `Optional` type.
```swift
extension Optional {
public init(
for op: @autoclosure () throws(E) -> Wrapped,
catcher: (E) -> Void
) {
do {
self = try op()
} catch {
catcher(error)
self = nil
}
}
}
// example usage
let optional = Optional(for: try success()) { (error: MyError) in
// handle error
}
```
Now our throwing function is just a simple `Optional` type. We can use it just like any other optional. We don't need to worry error because it has already been handled. If there is an error, then the `catcher` closure will handle it, and the `Optional` variable will be `nil`. If there is no error, then the `Optional` variable will be `some` and we can use it just like any other optional.
```swift
func getPostsFromAPI() -> [Post] {
let maybePostsData: Data = Optional(for: try getPosts()) { (error: PostAPIError) in
// handle error
}
guard let postsData = maybePostsData else { return [] }
let maybePosts: [Post]? = Optional(
for: try JSONDecoder().decode([Post].self, from: postsData),
catcher: { error in
// handle error
}
)
guard let posts = maybePosts else { return [] }
return posts
}
```
What have we accomplished?
1. We have a solution that doesn't require us to be in a throwing context.
2. When we catch an error, there is no ambiguity about which `try` statement caused the error.
3. We fixed the "Trapped Scope" problem by using `guard let` to unwrap the value.
4. When the error is statically typed, we can handle it confidently knowing that we have handled every possible case.
5. When the error is untyped, at least we know exactly which `try` statement caused the error.
Let's compare this to the orthodox way of handling this.
```swift
func getPostsFromAPI() -> [Post] {
do {
let postsData = try getPosts()
let posts = try JSONDecoder().decode([Post].self, from: postsData)
return posts
} catch {
// handle error
return []
}
}
```
This may look better. After all, it is less lines of code. But it is subtly worse for all the reasons we discussed in the last post. Namely the problem is that we have multiple `try` statements, but only one `catch` block. So we don't know which `try` statement caused the error.
We also have the "Trapped Scope" problem, so if we'd like to do more processing on `postsData` or `posts`, we either have move that work into the `do` block, or copy it into a new variable outside of the `do` scope.
## Converting Throwing Functions to Values
Hopefully, you are starting to see a pattern in these solutions.
1. We take one and only one throwing function via an `@autoclosure`
2. We handle the error in place
3. We return a new type
Let's look at how we can just straight up convert a throwing function into a value. First, let's look at the orthodox way of doing this:
```swift
func getPostsFromAPI() -> [Post] {
guard let postsData = try? getPosts(),
let posts = try? JSONDecoder().decode([Post].self, from: postsData) else {
return []
}
return posts
}
```
This code looks simple and elegant, but it's even worse than the last example. Once again, we have multiple `try` statements, but only one `else` block. So we don't know which `try` statement caused the error. Even worse, we don't even know what the error was. We just ignored it and turned it into a `nil` value. How can we resolve the error if we never even read it?
Remember this lesson:
Sometimes code is short because it is elegant.
Sometimes code is short because it is not actually doing its job.
For this reason, most Swift developers wouldn't use `guard let try?` unless they were absolutely sure that the function would never throw an error, or that any potential error was completely irrelevant. But more often than not, a Swift developer would use a `do` `catch` block here. Now let's try something new.
```swift
public func value(
for op: @autoclosure () throws(E) -> Value,
replaceTypedErrorWithValue onError: (E) -> Value
) -> Value {
do {
return try op()
} catch {
return onError(error)
}
}
// example usage
let postsData: Data = value(
for: try getPosts(),
replaceTypedErrorWithValue: { error in
// handle error
// return a sensible default value
}
)
let posts: [Post] = value(
for: try JSONDecoder().decode([Post].self, from: postsData),
replaceTypedErrorWithValue: { (error: PostAPIError) in
// handle error
// return a sensible default value
}
)
```
Look at how much better this is! We have a function that takes a throwing function and returns a value. If the function throws an error, we can handle it in place and return a sensible default value. We always know exactly which `try` statement caused the error.
---
## Future Swift Language Features
Now we have a solution that meets all of our requirements, but the truth is, I really hope that Swift sherlocks these solutions. Error handling is a core language problem and it should be built into the language. Over the years, many pitch proposals have attempted to tackle this issue, but none have been accepted yet. Here are two standout proposals that I think are worth mentioning:
### Last Expression As Return Value
This pitch suggests that the last expression should be treated as the return value in a variety of contexts including functions, and if or switch expressions. One of the coolest things about this pitch is it would create `do` expressions. Here's the example from the pitch:
```swift
let icon: IconImage = do {
let image = NSImage(
systemSymbolName: "something",
accessibilityDescription: nil)!
let preferredColor = NSColor(named: "AccentColor")!
IconImage(
image,
isSymbol: true,
isBackgroundSupressed: true,
preferredColor: preferredColor.cgColor)
}
```
This pitch have many benefits, but it would also have many far reaching implications. It's really not just about error handling. It's about many other issues as well. The pitch is quite in depth and I'm not gonna go deep on it here. You should read it [here](https://forums.swift.org/t/pitch-last-expression-as-return-value/76958).
### Guard Let Catch
This pitch suggests that we should be able to use `guard let` with a `catch` block. This would allow us to handle errors in a more concise way. Here's the example from the pitch:
```swift
func randomMovies(genre: Genre, count: Int) -> [Movie] {
guard let movies = try Database.loadMovies(byGenre: genre)
catch { return [] }
guard !movies.isEmpty else { return [] }
var randomMovies: [Movie] = []
for _ in 0.. User {
guard let userData = database.fetchUser(withId: userId) else {
throw UserError.notFound(id: userId)
}
return userData
}
```
This explicit declaration creates a clear contract: this function might fail, and callers need to be prepared for that possibility. There's no need to dig through documentation or implementation details to discover error-throwing behavior.
In Swift, we can be confident that any function that is not marked with `throws` will never throw an error, simplifying our mental model of the codebase. In contrast, languages like JavaScript or Python don't have this explicit signaling, leading to uncertainty about which functions might fail.
### Mandatory `try` Keywords at Call Sites
Swift forces you to acknowledge the potential for errors at every call site with the `try` keyword:
```swift
do {
let user = try fetchUserData(userId: "12345")
updateUI(with: user)
} catch {
showErrorMessage(error)
}
```
This mandatory labeling ensures developers can't accidentally ignore error conditions. Every call to a throwing function requires deliberate acknowledgment of the error possibility.
### Enforced Error Handling
The Swift compiler won't allow you to ignore errors from throwing functions. You must handle them in one of these ways:
- Use a `do-catch` statement
- Propagate errors with `throws`
- Convert to optionals with `try?` (however this never actually reads the error)
- Force unwrap with `try!` (which should be used carefully, because it will crash if the function throws an error)
This compiler enforcement prevents silent error situations that plague other languages.
### Consistency with Async/Await
Swift's error handling model aligns perfectly with its concurrency model:
```swift
func fetchLatestArticles() async throws -> [Article] {
let (data, response) = try await URLSession.shared.data(from: articlesURL)
guard let httpResponse = response as? HTTPURLResponse,
httpResponse.statusCode == 200 else {
throw NetworkError.badResponse
}
return try JSONDecoder().decode([Article].self, from: data)
}
```
This consistency means the mental model you develop for one system applies to the other, simplifying the learning curve.
### Simple Error Propagation
Swift makes it easy to bubble up errors when appropriate:
```swift
func displayUserProfile(userId: String) throws {
let user = try fetchUserData(userId: userId)
let posts = try fetchUserPosts(for: user)
let followers = try fetchUserFollowers(for: user)
updateUI(with: user, posts: posts, followers: followers)
}
```
By marking the function with `throws`, you can seamlessly propagate errors to higher levels where they might be better handled.
## The Bad
Despite its strengths, Swift's error handling system has significant drawbacks that can lead to cumbersome code and subtle bugs.
### Value Scope Limitations within `do` Blocks
Perhaps the most frustrating limitation is that values created within a `do` block are trapped there:
```swift
do {
let user = try fetchUserData(userId: "12345")
// user is only available within this block
} catch {
showErrorMessage(error)
}
// Can't access 'user' here!
```
This scope limitation forces developers to use awkward patterns like declaring variables before the `do` block or nesting all code that uses the value inside the `do` block, leading to deeply nested code.
### Overstuffed `do` Blocks
Because of the scope limitations, developers tend to put excessive amounts of code inside `do` blocks:
```swift
do {
let user = try fetchUserData(userId: "12345")
let posts = try fetchUserPosts(for: user)
updateUserHeaderView(with: user)
updateTimelineView(with: posts)
trackAnalyticsEvent(.profileViewed)
animateInProfileView()
// Many more lines of non-throwing code...
} catch {
showErrorMessage(error)
}
```
This approach mixes error-prone code with regular code, making the block's purpose unclear and hindering code organization.
### Multiple `try` Functions Create Ambiguity
When multiple throwing functions appear in the same `do` block, we encounter two critical problems:
#### Inability to Identify Which Function Threw
```swift
do {
let user = try fetchUserData(userId: "12345")
let posts = try fetchUserPosts(for: user)
let followers = try fetchUserFollowers(for: user)
} catch {
// Which operation failed? User fetch? Posts? Followers?
// The catch block doesn't tell us.
showErrorMessage(error)
}
```
Unless you explicitly check the error type or use multiple `catch` clauses, you can't immediately know which operation failed. So let's try both these approaches and we'll see how unwieldy and error-prone they are.
#### Multiple `catch` Blocks
```swift
do {
let user = try fetchUserData(userId: "12345")
let posts = try fetchUserPosts(for: user)
let followers = try fetchUserFollowers(for: user)
} catch {
if let networkError = error as? NetworkError {
showNetworkErrorMessage(networkError)
} else if let parsingError = error as? ParsingError {
showParsingErrorMessage(parsingError)
} else {
showGenericErrorMessage(error)
}
}
```
This example floods the code with noise and further separates the error handling from the original call. It also assumes that the error types are known in advance. In Swift 6+ the error type may or may not be typed. In Swift 5 and before, the error is never typed and the error type is effectively always `any Error`. This means that we simply have to hope that the documentation tells us what the error type is, and hope that the documentation is accurate.
#### Separate Catch Blocks
Another option is to use separate `catch` blocks for each error type:
```swift
let user: User
let posts: [Post]
let followers: [Follower]
do {
user = try fetchUserData(userId: "12345")
} catch {
showErrorMessage(error)
return
}
do {
posts = try fetchUserPosts(for: user)
} catch {
showErrorMessage(error)
return
}
do {
followers = try fetchUserFollowers(for: user)
} catch {
showErrorMessage(error)
return
}
```
But as you can see, this approach isn't great either. It creates even more noise. We are forced to declare the variables outside of the `do` block and initialize them inside the `do` block. If an error occurs, we are forced to exit scope using a control flow statement like `return` or else we will have uninitialized variables.
#### Abrupt Control Flow Breaks
When an error occurs, execution immediately jumps to the `catch` block. This means all subsequent code in the `do` block is skipped:
```swift
do {
startLoadingIndicator()
let user = try fetchUserData(userId: "12345")
let posts = try fetchUserPosts(for: user)
stopLoadingIndicator() // This might never execute!
} catch {
showErrorMessage(error)
// We need to remember to stop the loading indicator here too
stopLoadingIndicator()
}
```
This abrupt control flow makes cleanup code tricky and error-prone, especially for resource management.
To be clear, sometimes this is what we want. Oftentimes when there is an error, we do not want to continue executing the code because we could be making the situation even worse. We could put the program in an unresolvable state, or we could even corrupt the data forever.
Nevertheless, this abrupt stop means that our code has far more possible paths than we might expect. In the above example, we have three possible paths:
1. The `do` block executes successfully
2. The `do` block throws an error after the first `try` statement and therefore the second `try` statement never executes
3. The `do` block throws an error after the second `try` statement and therefore both `try` statements executed.
Every single `try` statement in the `do` block creates another possible path.
### False Sense of Security
While Swift forces you to acknowledge errors, it doesn't force you to handle them meaningfully:
```swift
do {
try veryComplexOperation()
} catch {
// Catch everything but do nothing meaningful
print("An error occurred: \(error)")
}
```
The compiler is satisfied with this implementation, but it doesn't ensure proper error recovery. There's no mechanism to ensure different error types receive appropriate handling.
## Typed Throws
With [SE-0413](https://github.com/swiftlang/swift-evolution/blob/main/proposals/0413-typed-throws.md), Swift 6 introduces a new `typed throws` feature that allows you to specify the error type a function can throw. This change is a welcome addition to the language and even addresses many of the issues discussed above. However it really only mitigates the problem rather than solving it completely.
In fact, in the proposal itself, the authors actually recommend almost never using the new typed throws feature!
>Even with the introduction of typed throws into Swift, the existing (untyped) throws remains the better default error-handling mechanism for most Swift code.
>- [SE-0413](https://github.com/swiftlang/swift-evolution/blob/main/proposals/0413-typed-throws.md#:~:text=Even%20with%20the%20introduction%20of%20typed%20throws%20into%20Swift%2C%20the%20existing%20(untyped)%20throws%20remains%20the%20better%20default%20error%2Dhandling%20mechanism%20for%20most%20Swift%20code.)
Isn't that strange? Why would you propose a new feature, and then immediately recommend that almost no one use it. Well, it turns out that this was the appropriate choice. Let's investigate below.
### Type Systems: Static vs. Dynamic vs. Gradual
Swift is a statically typed language, and this comes with many benefits. For example, the compiler can prevent many common mistakes at compile time, infer types to write more concise code, and the compiler can optimize code automatically through the use of techniques like inlining. But Swift's error handling system is a special case that doesn't fit neatly into the type system.
The fundamental issue with Swift's error handling system is that throwing functions effectively have TWO return types:
1. The declared return type (when successful)
2. An error type (when failing)
This dual-return nature creates a unique control flow challenge. Unlike regular returns which follow a predictable path, thrown errors create an alternate exit point that:
1. Breaks the normal flow within the function itself (any code after the `throw` statement is skipped)
2. Breaks the normal flow within the caller's context (skipping to the `catch` block)
Furthermore, these two type systems behave differently and are in fact in completely different categories:
1. The **declared return type** is a **static type**.
2. The **error type** is:
1. A **dynamic type** (in Swift 5 and earlier)
2. A **gradual type** (in Swift 6 and later)
What is a _gradual type_? Not long ago, [I wrote about the unique type system in GDScript]({{< ref "posts/gradual-static-typing-in-gdscript/index.md" >}}). GDScript started out as a dynamic type system, much like Python. But over time, it has evolved to include static typing. As you can imagine, this could create a lot of problems. You can't just force everyone to use static typing, because that would break all the existing code. So instead GDScript has a system where you can use either static or dynamic typing on any variable or function. By default, GDScript uses dynamic typing, but if you explicitly declare a variable or function with a type, then it will use static typing. This is what we mean by [gradual typing](https://en.wikipedia.org/wiki/Gradual_typing).
This is effectively the same thing that happened with Swift 6's "second type system", the error type system. In Swift 5 and earlier the type system was a dynamic type system. But in Swift 6, we got the new ability to statically declare the error type. This is a gradual type system, because you can still use the old dynamic type system if you want to. The [Swift 6 Announcement](https://www.swift.org/blog/announcing-swift-6/#Typed-throws) states:
>Typed throws generalizes over throwing and non-throwing functions. A function that is specified as throws (without a specific error type) is equivalent to one that specifies `throws(any Error)`, whereas a non-throwing function is equivalent to one that specifies `throws(Never)`. Calls to functions that are `throws(Never)` are non-throwing and don’t require error handling at the call site.
For example:
```swift
func typedThrowingFunction() throws(MyError) {}
func untypedThrowingFunction() throws {}
// 👆🏼 this is a throws(any Error)
func nonThrowingFunction() {}
// 👆🏼 this is a throws(Never)
```
Swift 6 can also interoperate with Swift 5 and earlier code. So you can call a Swift 6 function from Swift 5, even though Swift 5 has no concept of typed throws. Effectively what happens is Swift 5 will interprate any typed error as `throws(any Error)`. Swift 5 will happily call the Swift 6 function, and handle the error, but it won't know the error type at compile time.
### How Typed Throws Mitigates the Problem
We mentioned earlier that the Error handling system can give you a false sense of security because the compiler will guarantee that every throwing function is caught, but it won't guarantee that every possible error is caught. Now with typed throws, we can make this guarantee.
```swift
enum UserError: Error {
case notFound(id: String)
case invalidData
}
func fetchUserData(userId: String) throws(UserError) {
guard let userData = database.fetchUser(withId: userId) else {
throw UserError.notFound(id: userId)
}
return userData
}
func loadData() {
do {
let user = try fetchUserData(userId: "12345")
updateUI(with: user)
} catch { // remember that `catch` implicitly creates a variable called `error`
// error has type UserError because fetchUserData has a typed throws.
switch error {
case .notFound(let id):
// Handle not found error
case .invalidData:
// Handle invalid data error
@unknown default:
// Log the error
}
}
}
```
Since we are using typed throws, now we know exactly what type of error we are dealing with. In Swift 5 `catch` would effectively give us an `error` variable of type `any Error`, but now in Swift 6, we have a concrete type. In this case, our `error` variable is of type `UserError` which is an `enum`. This means we can use a `switch` statement to handle each case of the error. We now have a compile-time guarantee that we are handling every possible error case. The function will only ever throw a `UserError`, and the `switch` will force us to handle every possible case!
### Why Not Use Typed Throws Everywhere?
You might be thinking, "Great! I can just use typed throws everywhere and solve all my problems!" I wouldn't blame you for thinking that. In Swift, we are very used to having a statically typed system, and enjoying all the benefits that come with that. But that static type system really only applies to the declared return type. The error type is a different story.
The error type is a gradual type. It is effectively dynamic by default, but we can opt into static error typing. Naturally, the question is: "Why don't we opt into static error typing everywhere?" The answer is that it is not always appropriate. While static typing is a fantastic fit for return types, it can be problematic for error types, for reasons we'll explore in a bit. But first, we have one more question to answer:
### What Happens When We Have Multiple Error Types?
Back to our earlier example. We strongly typed our error, which means that now `catch` gives us a concrete error type. This fixes unresolved errors problem (if you recall, that's the problem where the compiler forces us to catch every problem, but does not force us to consider every possible error case).
However, it doesn't fix the scope problem. We still cannot access the `user` variable outside of the `do` block. This is why we're forced to put `updateUI(with: user)` inside the `do` block, even though it doesn't throw. Because of that, this solution is basically unusable in most situations. For example, what happens if the `do` block contains `try` functions that throw different types of errors?
```swift
enum MyError: Error { case error }
func typedThrows() throws(MyError) {
throw .error
}
func untypedThrows() throws {
throw MyError.error
}
enum MyOtherError: Error { case otherError }
func otherTypedThrows() throws(MyOtherError) {
throw .otherError
}
func foo() {
do {
try typedThrows()
try untypedThrows()
try otherTypedThrows()
} catch {
print("error: \(type(of: error))") // error: any Error
switch error {
case .error: print("case .error")
// 🔴 type 'any Error' has no member 'error'
}
}
}
```
The code above fails to compile. In this case, we have three different throwing functions, and they all throw different types of errors. The `catch` block will give us an `error` variable of type `any Error`, which means we no longer know the error type in advance, making it much harder, if not impossible to guarantee that we are handling every possible error case.
### Typed Throws Are An API Contract
Now we are in a place to begin to understand why the authors of SE-0413 recommend that we almost never use typed throws. By typing your throws, you are effectively promising, and making a compile-time guarantee that your function will only throw that specific type of error. This can be a very difficult promise to keep because you may need to add new error cases in the future. This is especially true if your throwing function implementation calls other throwing functions. By default, all of their errors will be propagated up through your function. This means that you not only need to guarantee that your function will only throw that specific type of error, but you also need to guarantee that all of the functions you call will only throw that specific type of error. This is a very difficult promise to keep.
## Takeaway: do, try, catch is problematic
If there's one thing you can take away from this post, it's this: **`do` `catch` blocks with multiple `try` functions are problematic**. They implicitly create new code paths. They catch errors without actually informing you which function threw the error. They create a false sense of security, that all errors are handled. Finally, they have a strong tendency to balloon into even larger `do` blocks, which only further exacerbates the problem.
This is a problem that is not unique to Swift. Many languages have similar issues and even worse issues. For example, in JavaScript, any function can throw an error and simply never tell you that they sometimes throw errors. Swift's error handling system has elegant solutions to many of these problems, but unfortunately, `do` `catch` blocks are not up to the task. In Swift, it is very easy to throw an error, and it is very easy to rethrow an error for someone else to deal with. But it is surprisingly difficult to `try` a throwing function and use the result. It's also surprisingly difficult to `catch` an error and handle it properly.
## Conclusion
Swift's error handling system offers clear benefits: explicit function contracts, mandatory error acknowledgment, and straightforward error propagation. However, its implementation introduces significant challenges around scope, control flow, and practical error handling.
These issues stem from the fundamental design choice to make error handling a special case of control flow rather than a type-based approach. While this design has performance benefits and syntactic clarity, it creates practical problems in everyday development scenarios.
In our next post, [Swift Error Handling: The Solution]({{< ref "posts/swift-error-handling-the-solution/index.md">}}), we will present concrete strategies for overcoming these limitations today, along with a preview of my \"Catcher\" library designed to simplify error handling. We'll also explore potential language changes that could fundamentally resolve these issues in future Swift versions.
# Actually Useful Obsidian: Formatting
Today we start a new series on one of my favorite note-taking apps, [Obsidian](https://obsidian.md/). In this series, we'll cover the basics of Obsidian. Here we will intentionally NOT be doing anything particularly fancy. We won't be using strange plugins or custom CSS. Instead we'll be focusing on the most helpul, core features that I use every day. Beginners will be able to finally overcome the initial learning curve and start using Obsidian effectively. And experienced users will find helpful tools to simplify their setup!
## What is Obsidian?
Obsidian is a note-taking app with three key superpowers that I want to highlight:
1. **Local-first and offline**: These are your notes, stored on your computer, and controlled by no one else.
2. **Extremely customizable**: Practically anything that you can think of doing with your notes, you can do in Obsidian.
- Seriously. You can make AirTable-like databases, Notion-like dashboards, Kanban boards, Todo lists, mind maps, and anything else that you can think of.
3. **Markdown-based**: Obsidian uses Markdown for all of its notes. This means that you can write your notes in plain text, and they will be rendered beautifully in Obsidian.
## How the heck do I make my text bold?
Usually when I tell people about Obsidian they seem like they're on the same page, until they see Markdown. It seems like a strange programming language and let's face it, many of us don't want to learn something that looks confusing and intimidating. We just want to take notes and do simple things like make our text bold. I hear you. Let's make this simple.
## The Formatting Menu in Obsidian
Most of us are familiar with traditional word processors like Microsoft Word or Google Docs. These tools are what is known as a [WYSIWYG editor](https://en.wikipedia.org/wiki/WYSIWYG). WYSIWYG stands for "**What You See Is What You Get**." They're called that because you can simply highlight your text and click a button to change the way that it looks. For example, to make your text bold, just highlight it and click the bold button.
WYSIWYG editors are great because they're simple and easy to use, at least at first. But they have some downsides, which we'll talk about in a bit. For now, let's focus on how to make Obsidian as easy to work with as a WYSIWYG editor.

First, simply highlight any text in your note. Now right-click on the highlighted text. You'll see a menu pop up. Now hover your mouse over the "Format" button and you'll see a list of formatting options. Click on the formatting option that you want to apply to your text and that is it! You've just formatted your text in Obsidian. You should see your change happen immediately in the editor. In a bit, we'll learn how to make this even easier, but first let's talk about some of the problems with WYSIWYG editors.
## The Problem with WYSIWYG Editors
Tell me if this has ever happened to you. You're writing a document in Word or Google Docs. You're making your text bold, italic, and adding links. Everything looks great. But then you copy and paste that text into an email, or a chat, or a website, and it looks terrible. The bold text isn't bold anymore. The italic text isn't italic anymore. The links don't work. For some reason the font size is four times too small to read. What happened?
The problem is that **WYSIWYG editors are great for making your text look good in that one program, but they're terrible for making your text look good in other programs**. The reason is that WYSIWYG editors use a lot of fancy formatting that only works in that one program. When you copy and paste that text into another program, all of that fancy formatting is lost.
But plain text is different. Plain text is just text. It doesn't have any fancy formatting. It's just text. And that's why Markdown is so powerful. Markdown is just text.
Plain text is like a universal language. It can be read by practically any computer program with no issue whatsoever. But plain text is a little... well plain. It doesn't have any formatting, which means we can't do basic things like make our text bold.
That's where Markdown comes in. It's a very simple way to add formatting to plain text. But the best part is it is **human-readable**, which means that even if you don't know Markdown, you can still read it. It almost looks like something you would naturally write with pen and paper.
## Don't Be Afraid of Markdown
Don't be afraid of Markdown. I repeat, do not be afraid of Markdown. It adds some extra features to your text, but it's still just text. You can write your notes in plain text and they will look great in Obsidian. Better yet, those plain text files can be read in almost any other computer program. Google Docs, Notion, Slack, Discord, you name it. They can all read plain text files. New programs come and go. But plain text files are forever.
Now, what kind of extra features does Markdown add? Formatting. That's it. Markdown is just a way to format your text. You can make your text **bold**, _italic_, or even add [links](https://example.org/). That's it. That's all Markdown does. It's not a programming language. It's just a way to format your text. And don't worry, it is dead simple to use.
Do yourself a favor and bookmark [this page](https://help.obsidian.md/Editing+and+formatting/Basic+formatting+syntax). It's the official Obsidian help page on Markdown. Don't worry about memorizing or even learning it all. Just bookmark it, and focus on remembering the features that you use most often. Here's a few to get you started:
## Basic Markdown Formatting
- **Bold**: `**bold**`
- You can also highlight text and press `⌘ + B` on Mac or `Ctrl + B` on Windows to make it bold.
- _Italic_: `_italic_`
- You can also highlight text and press `⌘ + I` on Mac or `Ctrl + I` on Windows to make it italic.
- ~~Strikethrough~~: `~~Strikethrough~~`
As you can see the above formatting is very simple. Just add some extra characters before and after your text to format it.
- Bullet point list: `- List`
- A bullet point list can be created by adding a `-` before each item.
- 1. Numbered List: `1. Numbered List`
- A numbered list can be created by adding a number followed by a `.` before each item.
- `Heading 1`: `# Heading 1`
- Headings can be created by adding `#` before your text. The number of `#`s determines the size of the heading.
- Tasks (Checkboxes):
- [ ] An unchecked task can be created by adding `- [ ]` before your text.
- [x] A checked task can be created by adding `- [x]` before your text.
- If you click on the checkbox, it will automatically check or uncheck the task, and update the Markdown syntax.
- Obsidian even has powerful task management features that can be used with these tasks. Read all about it [here](https://help.obsidian.md/Editing+and+formatting/Basic+formatting+syntax#Task+lists).
That's it! That's all you need to know to get started with Markdown. Plus learning Markdown is an incredibly useful skill. It's used in many different places, not just Obsidian. In fact, I even wrote **this article** in Markdown!
## Source Mode, Reading View, and Live Preview
Remember, Obsidian is just a plain-text Markdown editor. The only thing that you are actually editing is a plain text file. But Obsidian has three different ways to view your notes.
1. **Source Mode**: This is the raw Markdown text. This is what you are actually editing.
2. **Reading View**: This is what your note will look like when you export it. It looks just like a simple webpage, but you can't edit it.
3. **Live Preview**: This is a live preview of your note. It looks just like the Reading View, except that you can edit it, just like in Source Mode!
You can switch between these three views, but the truth is, **I spend almost all of my time in Live Preview**. It's the best of both worlds. You can see what your note will look like when you export it, and you can edit it at the same time.
Live Preview is so simple to use that it almost feels like a WYSIWYG editor, but there is one thing that you need to be aware of. Even though it looks like a WYSIWYG editor, you are still editing a plain text file, with Markdown syntax in it. Live Preview does a fantastic job of hiding the Markdown syntax, so that we can focus on our writing, but it is still there. For example look at this:

As you can see, the text appears to change, depending on where the cursor is. This is because the Markdown syntax is being hidden. But when the cursor moves into a section of text that has Markdown syntax, the syntax is revealed. So when the cursor moves into the word "bold", then the `**` characters are revealed before and after the word. The truth is, those `**` characters are always there, but Live Preview is only showing them when you need to see them.
Let's try formatting our text using Markdown instead of the formatting menu. Find some text in your note that you want to make bold. Now add `**` before and after the text. You might not see a change yet, but that it totally okay. Live Preview hasn't hidden the `**` characters because your cursor is still inside that portion of text. Simply move your cursor to another portion of text and you should see your text become bold, and the `**` characters disappear!
Remember that Format menu that we used earlier? It's doing the same thing. It's just adding Markdown syntax for you. So you can pick whatever method is easiest for you. You can type out the Markdown syntax yourself, or better yet, you can just push a button in the Format menu, and Obsidian will type the Markdown syntax for you.
Now that we understand Live Preview mode, let's talk about how to make formatting even easier!
## The "Editing Toolbar" Plugin
The problem with the Format menu is that there are only a few options in it, and you have to right-click to access it. How can we get a big helpful formatting toolbar like in Word or Google Docs? The answer is the "Editing Toolbar" plugin.
In Obsidian, you can add new features to the app by installing plugins. Obsidian has Core plugins that are built into the app[^1], and Community plugins that are created by the community. The "Editing Toolbar" plugin is a Community plugin that adds a big helpful formatting toolbar to the top of the editor. You can add bold, italic, and any other formatting options with just a click of a button.
[^1]: The cool thing is this means that you can turn off features that you never use, which means that you can reduce clutter and keep Obsidian simple.
You can find the Editing Toolbar plugin [here](obsidian://show-plugin?id=editing-toolbar) and if you've never installed a plugin before, you can read all about it [here](https://help.obsidian.md/Advanced+topics/Plugins).
Now, just like the Format menu, the "Editing Toolbar" plugin is just adding Markdown syntax for you. There is no fancy Rich Text formatting going on. It's just adding Markdown syntax. Which means that the Editing Toolbar is also a great way to learn Markdown as well. Simply click any formatting button in the Editing Toolbar and you'll see the Markdown syntax appear in your note!
This "Editing Toolbar" plugin is jam-packed with features that even most advanced Markdown users will appreciate. You can add tables, code blocks, and even emojis with just a click of a button. It's a fantastic way to make Obsidian even easier to use.
## Formatting With HTML
Now feel free to skip this section if HTML is not your thing. But you should know that Obsidian can render HTML in your notes. For those who don't know HTML is the language that websites are written in. It's a very powerful, extremely flexible language. Let's look at a very simple use case that will come in handy for almost everyone.
### Underlining Text
Practically every word processor has a way to underline text. But Markdown doesn't have a way to underline text[^2]. That's not a problem because we can use HTML to underline text. Here's how you do it:
```html
This text is not underlined. But this text is.
```
[^2]: Well, the issue is that by default, links in web browsers are underlined. So if Markdown had a way to underline text, it would be very confusing to know if a link was underlined because it was a link, or because it was underlined. So Markdown doesn't have a way to underline text. If I was dictator of the world, I would make `_this_` syntax underline text, but alas I am not and that ship has sailed.
Paste that text into Obsidian and it should render like this:
>This text is not underlined. But this text is.
This syntax is quite simple, so let's break it down. HTML applies formatting using _tags_. Tags are enclosed in angle brackets, like this `` opening tag and this `` closing tag. The `` tag is used to underline text. So to underline text, you simply add `` before the text that you want to underline, and `` after the text that you want to underline.
But again, the Editing Toolbar plugin makes this much easier for us. Just highlight the text, and click the "U" button in the Editing Toolbar. The Editing Toolbar will add the HTML tags for you.
### Superscript and Subscript
Another common formatting option that is missing from Markdown is superscript and subscript. But again, we can use HTML to add these formatting options. Here's how you do it:
```html
a2 + b2 = c2
log2(8) = 3
```
Paste that text into Obsidian and it should render like this:
>a2 + b2 = c2
log2(8) = 3
Again, the Editing Toolbar makes this much easier for us.
## Other Formatting Options
Finally, let's do a lightning round of some other helpful formatting options that you can use in Obsidian. Thankfully, these ones are all built into Markdown, so you don't need to know HTML to use them. I'll show you what they look like here. Be sure to check out the [official Obsidian help page on Markdown](https://help.obsidian.md/Editing+and+formatting/Basic+formatting+syntax) to see how to use them for yourself[^3]. Also, remember that the Editing Toolbar plugin can add all of these formatting options for you.
[^3]: I'm serious. You really need to bookmark that page. It's incredibly helpful.
### Footnotes
A footnote is a little note that you can add to your text. It's usually at the bottom of the page. Here's what a footnote looks like:
```markdown
This is a sentence with a footnote[^1].
[^1]: This is the footnote. Note that the number in the square brackets matches the number in the footnote. Also, note that in Markdown, the footnote can be anywhere in the document. It doesn't have to be at the bottom of the page. It will be rendered at the bottom of the page in Reading View, but you can put the Markdown for the footnote anywhere in the document.
```
Paste that text into Obsidian and it should render like this:
>This is a sentence with a footnote[^4].
[^4]: This is the footnote. Note that the number in the square brackets matches the number in the footnote. Also, note that in Markdown, the footnote can be anywhere in the document. It doesn't have to be at the bottom of the page. It will be rendered at the bottom of the page in Reading View, but you can put the Markdown for the footnote anywhere in the document.
### Blockquotes
Blockquotes are a way to highlight text. They are often used to show that a piece of text is a quote from another source. Here's what a blockquote looks like:
```markdown
> This is a blockquote. It's a way to highlight text. It's often used to show that a piece of text is a quote from another source.
```
Paste that text into Obsidian and it should render like this:
> This is a blockquote. It's a way to highlight text. It's often used to show that a piece of text is a quote from another source.
### Callouts
Callouts are a way to highlight text. They are often used to show that a piece of text is important. Now callouts are a part of Markdown, but there is a bit of a catch. Not every program that reads Markdown has all of the same features. There are [standard features that are part of the Markdown specification](https://www.markdownguide.org/basic-syntax/), but there are also features that are unique to each program. Sometimes these unique features are called "flavors" of Markdown. They are like _dialects_ of Markdown.
Callouts are a part of what we call [Obsidian-Flavored Markdown](https://help.obsidian.md/Editing+and+formatting/Obsidian+Flavored+Markdown). (Also, [GitHub-Flavored Markdown](https://github.github.com/gfm/).) Make sure you read about callouts in the official [Obsidian page](https://help.obsidian.md/Editing+and+formatting/Callouts) on Callouts.
### Code Blocks
Code blocks are a way to show examples of code in your notes. When writing code in Markdown, it's important to use code blocks, so that your code is easier to read. Plus, many programs add a very helpful copy button to code blocks. You can read about code blocks in the official [Obsidian page](https://help.obsidian.md/Editing+and+formatting/Basic+formatting+syntax#Code+blocks) on Code Blocks.
### Tables
Tables are a helpful way to organize information in your notes. You can read about tables in the official [Obsidian page](https://help.obsidian.md/Editing+and+formatting/Advanced+formatting+syntax#Tables) on Tables.
Here is an example of a table:
```markdown
| Header 1 | Header 2 | Header 3 |
|----------|----------|----------|
| Row 1 | Row 1 | Row 1 |
```
Paste that text into Obsidian and it should render like this:
| Header 1 | Header 2 | Header 3 |
|----------|----------|----------|
| Row 1 | Row 1 | Row 1 |
Let me tell you that tables are a bit of a pain to write by hand. But thankfully, Obsidian has the best Markdown table editor that I have ever found. Using a table in Obsidian's Live Preview Mode is as easy and intuitive as using a table in Excel!
### Images
Obsidian and Markdown makes it very easy to add images to your notes. But alas we'll be exploring this in next week's post when we talk about links.
## Conclusion
This was a deep dive into formatting your notes in Obsidian. But the truth is, we only scratched the surface. There are so many more formatting options in Markdown, and Obsidian-Flavored Markdown, in HTML, and even in Community plugins. But the good news is that you don't need to know all of them. You only need to know the ones that you use most often.
I hope that this article will open your mind up to the deep possibilities. If you get one takeaway from this article, I hope that it is this. **Markdown and Obsidian are just tools to help you write and think.** There are many powerful tools out there, and some like Notion, or Google Docs may be simpler and more intuitive to use. But the power of Markdown and Obsidian is this:
1. No one controls your notes but you.
2. You can customize your notes in any way that you want. The skies are the limit.
With just a little bit of work and learning, you can make Obsidian uniquely yours. And that is a very powerful thing.
# What's the difference between class and class_name in Godot?
When you're writing scripts in Godot, you might have noticed that some scripts use `class` and others use `class_name`. What's the difference between these two keywords? Let's find out.
## `class_name` keyword
You may have noticed that so many GDScript scripts in Godot start with `extends Node` or `extends Resource`. This is because Godot uses a common programming feature called class inheritance.
```gdscript
extends Node
var str = "Hello, World!"
```
So when you use `extends`, you are telling GDScript that your class inherits from an existing class. So when we write `extends Node`, we are creating a new class that inherits from the `Node` class.
But where is the new class that we are creating? The answer is, that the whole script (file) is the new class. In fact, **every script in GDScript is defining a new class**.
So how does Godot know what the name of the new class is? Well, if we are only using this class in this file, then we don't really need to know what the name of the class is.[^1] But if we want to use this class in another script, then we need to give it a name. This is where the `class_name` keyword comes in. The `class_name` keyword is used to name the class that we are creating. This name is used when we want to create an instance of the class in another script.
[^1]: The Godot game engine almost certainly has a way to refer to the class name internally, but as a user, you don't need to worry about it. To us, that's just an implementation detail.
Here's an example of how you might use `class_name`:
```GDScript
# MyNode.gd
extends Node
class_name MyNode
```
Now you can create an instance of `MyNode` in another script like this:
```GDScript
# SomeOtherScript.gd
var my_node = MyNode.new()
```
So in summary, `class_name` in GDScript, behaves much like `class` in other programming languages, like Swift or JavaScript. It is used to name the class that you are creating.
## `class` keyword
If you are used to classes in other programming languages, then the `class` keyword might look familiar to you. But pay careful attention. In GDScript, it does not do the same thing as it does in so many other languages. In GDScript, the `class` keyword is **not** used to define a new class. It is used to define a new **inner class**.
### What is an inner class?
An [inner class](https://docs.godotengine.org/en/stable/tutorials/scripting/gdscript/gdscript_basics.html#inner-classes) is a class that is defined inside another class. This is useful when you want to group related classes together. Here's an example of how you might use `class` to define an inner class:
```GDScript
# Vehicle.gd
class_name Vehicle
extends Node
var tires: Array[Tire]
class Tire:
var size: int
var brand: String
```
In this example, we have a class called `Vehicle` that contains an inner class called `Tire`. This is a common pattern in Godot when you want to group related classes together. Now let's create another file named `Car.gd` that uses the `Tire` inner class:
```GDScript
# Car.gd
class_name Car
# 🔴 Could not find type `Tire` in this context.
func makeANewTire() -> Tire:
return Tire.new()
```
Uh oh! The `Tire` type cannot be found! Why is this? It's because `Tire` is an inner class of `Vehicle`. We need to refer to it as `Vehicle.Tire`:
```GDScript
# Car.gd
class_name Car
func makeANewTire() -> Vehicle.Tire:
return Vehicle.Tire.new()
```
Now it works! As you can see, `Tire` is not a "regular" class. It is an inner class of `Vehicle`. So we need to refer to it as `Vehicle.Tire`. In other words, the `Tire` inner class is [namespaced](https://en.wikipedia.org/wiki/Namespace) under the `Vehicle` class.
Now try this. Remove `Vehicle.` and add `extends Vehicle` so that your script looks like this:
```GDScript
# Car.gd
class_name Car
extends Vehicle
func makeANewTire() -> Tire:
return Tire.new()
```
Now it works again! This is because `Car` is now a subclass of `Vehicle`. In other words the `Car` class inherits from the `Vehicle` class. And since it inherits from `Vehicle`, it also inherits the `Tire` inner class. So this also works:
```GDScript
class_name Car
extends Vehicle
func makeANewTire() -> Car.Tire:
return Car.Tire.new()
```
## When Should I Use `class` versus `class_name`?
>⭐ If you are creating a new class that you want to use in another script, you should use `class_name`.
But don't forget, you might not need to use `class_name` at all. If you are creating a new class that is only used in the current script, you can skip the `class_name` keyword, since you won't be using it in another script. By default, Godot will create new script files with no class name. However, I usually like to add a class name. Thinking of a name for my class forces me to clarify what the purpose of the class is. It's a good habit to get into.
So when should you use `class_name`?
>⭐ If you are creating a new class that is really only relevant within the current class, then you might consider making it an inner class with the `class` keyword.
This is why I declared the `Tire` class as an inner class in the `Vehicle` class. This way it is clear that `Vehicle.Tire` is a class that is related to the `Vehicle` class.
If you're a beginner and inner classes are confusing to you, don't worry. You don't need to use `class` at all. Later on, when you're more comfortable with GDScript, if you find yourself drowning in disorganized classes, then you might consider using inner classes to group related classes together.
## Conclusion
In this guide, we learned the difference between `class` and `class_name` in Godot. We learned that `class_name` is used to name a class that we want to use in another script, while `class` is used to define an inner class.
## Recommeded Reading
- [Godot docs on Inner Classes](https://docs.godotengine.org/en/stable/tutorials/scripting/gdscript/gdscript_basics.html#inner-classes)
- [Introduction to Object-Oriented Programming](https://www.geeksforgeeks.org/introduction-of-object-oriented-programming/)
# Easy Deep Copy Cloning in Swift
In most programming languages, there is some concept of value and reference types. In Swift, we prefer to use value types and value semantics whenever possible. This is because value types are easier to reason about since they cannot be mutated by other parts of the code.[^1] However there are some times when we must use reference types. Is there a way to get our reference types to behave like value types? Yes, there is.
[^1]: To be clear, value types are not better or worse than reference types. They both have very valid use cases.
## Value Semantics vs. Reference Semantics
Remember that value semantics means that when you copy a value, you get a **new copy of the value**. This is in contrast to reference semantics where when you copy a reference, you get a **new reference to the same object**.
```swift
struct ValueType {
var int: Int
}
class ReferenceType {
var int: Int
init(int: Int) {
self.int = int
}
}
var value1 = ValueType(value: 1)
var value2 = value1
value2.int = 2
print(value1.int) // 1
print(value2.int) // 2
var reference1 = ReferenceType(value: 1)
var reference2 = reference1
reference2.int = 2
print(reference1.int) // 2
print(reference2.int) // 2
```
As you can see, when we copy a value type, we get a new copy of the value. When we copy a reference type, we get a new reference to the same object. Therefore, if we change the value of the reference type, it will change the value of the original reference type as well. But if we change the value of the value type, only that value will change.
But **one of the cool things about reference types is that we can force them to behave like value types**, by copying their values instead of their reference. When a reference type **behaves like a value type** we call this _value semantics_. Swift regularly does this through a strategy called _copy-on-write_[^2], but let's look at another way to accomplish this.
[^2]: For example, Swift uses copy-on-write for `Array`, `String`, and `Dictionary`. In practice, these types *behave* like value types because they are copy-on-write, but under the hood, they are actually reference types.
## Cloning A Reference Type
Another way to force a reference type to behave like a value type is to clone it. Notice I said _clone_ and not _copy_. When you clone a reference type, you are creating a new instance of the reference type that just happens to have the same values as the original instance. This way, you can change the values of the cloned reference instance without affecting the original reference instance.
```swift
var reference1 = ReferenceType(int: 1)
var reference2 = ReferenceType(int: reference1.int)
reference2.int = 2
print(reference1.int) // 1
print(reference2.int) // 2
```
Here we created an entirely new instance of `ReferenceType` and copied the value of `reference1` into `reference2`. Now, when we change the value of `reference2`, it will not affect `reference1`. This strategy is useful but can be quite cumbersome if we have many values. Let's enforce this behavior through a new protocol named `Cloneable`.
```swift
protocol Cloneable {
init(cloning original: Self)
func clone() -> Self
}
extension Cloneable {
func clone() -> Self {
return Self(cloning: self)
}
}
var reference = ReferenceType(int: 1)
var referenceCopy = reference
var referenceClone = reference.clone()
reference.int = 2
print(reference.int) // 2
print(referenceCopy.int) // 2
print(referenceClone.int) // 1
```
Now, we can enforce value semantics on our reference type by making it conform to the `Cloneable` protocol. This way, we can guarantee that when we clone the reference type, we get a new instance of it with the same values.
```swift
extension ReferenceType: Cloneable {
required init(cloning original: ReferenceType) {
self.int = original.int
}
}
```
And what's extra nice is that the `clone()` method is now generated for us automatically.
```swift
var reference = ReferenceType(int: 1)
var referenceClone = reference.clone()
```
Unfortunately this is a little extra work to maintain. If our `ReferenceType` ever changes we must remember to update the `Cloneable` protocol implementation as well. Thankfully, the compiler has our back and should warn us in most cases. If we rename, or add or remove a property, the compiler will show an error that the initializer is not valid. 👍🏼
## Deep Copy vs. Shallow Copy
It is important to note that the problem is a little more complex than it seems. When we clone a reference type, we can either do a _deep copy_ or a _shallow copy_. A _shallow copy_ only copies the top-level properties of the reference type. A _deep copy_ copies all the properties of the reference type, including any reference types it contains. In order to do a true clone, we must do a _deep copy_. If we merely had a shallow copy, we would still be pointing to references from the original instance, which would still lead to surprising side effects. For example, let's say we added a `ReferenceType` property to our `ReferenceType`:
```swift
class ReferenceType: Cloneable {
var int: Int
var anotherReference: AnotherReferenceType
init(int: Int, otherRef: AnotherReferenceType) {
self.int = int
self.anotherReference = otherRef
}
required init(cloning original: ReferenceType) {
self.int = original.int
self.anotherReference = original.anotherReference
}
}
class AnotherReferenceType {
var string: String
init(string: String) {
self.string = string
}
}
var reference = ReferenceType(int: 1, otherRef: AnotherReferenceType(string: "Hello"))
var referenceClone = reference.clone()
reference.anotherReference.string = "Goodbye"
print(reference.anotherReference.string) // Goodbye
print(referenceClone.anotherReference.string) // Goodbye
```
Why did this happen? Because the implementation of `Cloneable` was incorrect. It only did a shallow copy. We copied every property on `ReferenceType`. The `int` property is a value type, so when we copied it we created an entirely new instance of the `Int`. But the `anotherReference` property is a reference type. When we copied it, we only copied the reference to the `AnotherReferenceType` instance. We didn't create a new instance of `AnotherReferenceType`. So when we changed the `string` property of `anotherReference` on the `reference` instance, it also changed on the `referenceClone` instance. In other words, we didn't do a deep copy. We only did a shallow copy. Let's correct this:
```swift
class ReferenceType: Cloneable {
var int: Int
var anotherReference: AnotherReferenceType
required init(cloning original: ReferenceType) {
self.int = original.int
self.anotherReference = original.anotherReference.clone()
}
// ...
}
class AnotherReferenceType: Cloneable {
var string: String
required init(cloning original: AnotherReferenceType) {
self.string = original.string
}
// ...
}
```
Now, when we clone the `ReferenceType`, we also clone the `AnotherReferenceType` instance. This way, when we change the `string` property of `anotherReference` on the `reference` instance, it will not change on the `referenceClone` instance.
```swift
var reference = ReferenceType(int: 1, otherRef: AnotherReferenceType(string: "Hello"))
var referenceClone = reference.clone()
reference.anotherReference.string = "Goodbye"
print(reference.anotherReference.string) // Goodbye
print(referenceClone.anotherReference.string) // Hello
```
## Deep Copy Clones For Free Using Codable
By now, you should realize that deep copying can be quite complex. We must remember to clone every property of the reference type, including any reference types it contains, and any reference types they contain, and so on. This can be quite cumbersome and error prone. But there is a way to get deep copy clones for free! If our reference type is `Codable`, we can get deep copy clones for free. This is because when an instance is encoded and decoded, an entirely new instance is created.
```swift
extension Cloneable where Self: Codable {
func cloneUsingCodable() -> Self? {
guard let data = try? JSONEncoder().encode(self) else {
return nil
}
return try? JSONDecoder().decode(Self.self, from: data)
}
}
extension ReferenceType: Codable {}
extension AnotherReferenceType: Codable {}
```
Remember that when every property of a type is `Codable`, then Swift can automatically synthesize the `Codable` conformance for that type. This is why we don't need to implement the `Codable` protocol for `ReferenceType` and `AnotherReferenceType`. Now that both `ReferenceType` and `AnotherReferenceType` are `Codable`, we can get deep copy clones for free using the `cloneUsingCodable()` method.
But there is a slight catch. As you can see, `cloneUsingCodable()` returns an Optional. This is because encoding and decoding can fail. So we must first unwrap the optional before using the cloned instance.
>In all likelihood, it is probably completely safe to force unwrap the optional. This is because the value was already a valid instance of the type or else you wouldn't be able to call `cloneUsingCodable()`. So as long as your `Encodable` and `Decodable` implementations are correct, you should be fine. And if those implementations were auto-synthesized by Swift, then you should be very confident that they are correct.
```swift
let reference = ReferenceType(int: 1, otherRef: AnotherReferenceType(string: "Hello"))
if let referenceClone = reference.cloneUsingCodable() {
reference.anotherReference.string = "Goodbye"
print(reference.anotherReference.string) // Goodbye
print(referenceClone.anotherReference.string) // Hello
}
```
Now, when we change the `string` property of `anotherReference` on the `reference` instance, it will not change on the `referenceClone` instance. This is because we are now doing a deep copy clone using the `Codable` protocol.
## Conclusion
There you have it! Simple, automatic, and free deep copy clones using the `Cloneable` and `Codable` protocols. If you'd like to try this approach then take it for a spin by cloning[^3] my `Cloneable` repository on GitHub [here](https://github.com/DandyLyons/Cloneable). (It's also available as a SPM package.) And if you like it, please star it and share it with your friends!
[^3]: Ahem. Git cloning that is. 😄 I couldn't resist.
---
## Further Reading
- [Difference between Shallow and Deep copy of a class - GeeksforGeeks](https://www.geeksforgeeks.org/difference-between-shallow-and-deep-copy-of-a-class/)
- This article is very much inspired by the JavaScript function `structuredClone()`. See it at [MDN Web Docs: structuredClone](https://developer.mozilla.org/en-US/docs/Web/API/Window/structuredClone)
- Here's a tutorial on using the _old_ Swift method of deep copying (using NSCopying): [Understanding Deep and Shallow Copying in Swift](https://ankur098.medium.com/understanding-deep-copy-and-shallow-copy-in-swift-8df201375611)
# Introducing SelectiveEquatable
A few weeks ago, I released a blog post named ["Selective Equality Checking in Swift"](https://dandylyons.net/posts/post-24/selective-equality-checking-in-swift/). In that post, I designed and implemented an API to check for equality on specific properties of a type. Today, I am excited to announce a new Swift protocol named `SelectiveEquatable`, that makes all of this even easier. Let's see it in action.
## Using SelectiveEquatable
To use the `SelectiveEquatable` protocol, all you need to do is add a conformance to it like this:
```swift
extension MySwiftType: SelectiveEquatable {}
```
And that's it! Now you get a new method which allows you to check for equality on specific properties of your type.
```swift
let instance1 = MySwiftType(int: 1, string: "Hello", bool: true)
let instance2 = MySwiftType(int: 1, string: "World", bool: true)
print(instance1 == instance2) // false
print(instance1.isEqual(to: instance2, by: \.int, \.bool)) // true
```
Here we simply use the new `isEqual(to:by:)` method. We supply it a keypath to the properties we want to check for equality on. In this case, we are checking for equality on the `int` and `bool` properties. The `by` parameter will accept as many keypaths as you want, and for any type, as long as the type conforms to `Equatable`.
## Installing SelectiveEquatable
There are two main ways to install `SelectiveEquatable` in your project. The first is to simply copy and paste the protocol into your project. You can find the entire code right [here](https://github.com/DandyLyons/SelectiveEquatable/blob/main/Sources/SelectiveEquatable/SelectiveEquatable.swift).
The second is to use the Swift Package Manager. If you already have a library that other code depends on, then it might be easier/more convenient to add the "SelectiveEquatable" package as a dependency to your project or package. The best place to find the package is on [Swift Package Index](https://swiftpackageindex.com/DandyLyons/SelectiveEquatable)!
## Conclusion
I hope you find the `SelectiveEquatable` protocol useful in your projects. It is a simple and easy way to check for equality on specific properties of a type. Please star it on [GitHub](https://github.com/DandyLyons/SelectiveEquatable) if you like it, and feel free to open an issue or pull request if you have any suggestions or improvements.
# Am I Using Swift 5 or 6?
Swift is in the middle of a transition from Swift 5 to Swift 6. This transition is not as simple as it may seem. In this post, we will discuss how to determine which version of Swift you are using. But first we need to clear up some misconceptions.
1. We need to understand the difference between Swift 6 **the compiler** and Swift 6 **the language mode**.
2. We need to understand how to determine which version of the Swift **compiler** we are using.
3. We need to understand how to determine which version of the Swift **language mode** we are using.
4. We need to understand how to opt in or out of Swift 5 or Swift 6 **language mode**.
> **Note:** This post will be primarily concerned with the native Swift Package Manager. Xcode has been known to behave slightly differently than SPM, and this post does not exhaustively cover all the ways Xcode may differ. This post assumes that you know how to use SPM and particularly how to declare a Swift Package using a `Package.swift` file. If you are not familiar with this, I recommend reading the [Swift Package Manager Documentation](https://swift.org/package-manager/).
## What's The Difference Between The Compiler and The Language Mode
Swift updates its language using semantic versioning. This means that each minor release (for example from 5.9 to 5.10) is a non-breaking change, and each major release (for example from 5 to 6) is a breaking change. A non-breaking change means that code written in the previous version of Swift will compile and run in the new version of Swift. A breaking change means that code written in the previous version of Swift will not compile in the new version of Swift.
>Don't forget that in Swift, the compiler will refuse to compile code that has a compiler **Error**. But if you have a **Warning**, it will still compile.
But Swift is also backwards compatible with prior versions of Swift. This means, for example that code written in Swift 5 can be compiled with the Swift 6 compiler. Swift 5 code can also call Swift 6 code, and vice versa. So how does this work? How can they be compatible if a major release is a breaking change. At least part of the answer is by using a Swift compiler feature called **language mode**.
>Note: Swift appears to have recently changed the name of this feature from **language versions** to **language modes**. You can see this in the Swift Package Manager API. (See the docs [here](https://developer.apple.com/documentation/packagedescription/package/init(name:defaultlocalization:platforms:pkgconfig:providers:products:dependencies:targets:swiftlanguageversions:clanguagestandard:cxxlanguagestandard:))). I welcome this change as "language version" was easier to confuse with the compiler version. Pay extra attention whenever you see the term "language version" in the Swift documentation or tooling. Ask yourself if it is referring to the Swift compiler version or the Swift language mode.
The takeaway that I want you to get is this: **Each Swift compiler can compile syntax from earlier versions of Swift**. This is done by setting the **language mode**. The compiler version determines the Swift language features that are available to you on your machine. The language mode determines which Swift syntax and language features you would like to use in each target.
## How To Determine Which Version of The Swift Compiler You Are Using
Now that we understand the difference between the Swift compiler and the Swift language mode, let's talk about how to determine which version of the Swift compiler you are using. Open terminal and type in the following command:
```bash
swift --version
```
If you have Swift installed on your machine, then you should see something like this:
```bash
swift-driver version: 1.115 Apple Swift version 6.0 (swiftlang-6.0.0.9.10 clang-1600.0.26.2)
Target: arm64-apple-macosx15.0
```
This shows you the tooling version of the Swift compiler. In this case, it is Swift 6.0.
## How To Determine Which Version of The Swift Language Mode You Are Using
Now that we know how to determine which version of the Swift compiler we are using, let's talk about how to determine which version of the Swift language mode we are using.
Swift allows us to mix and match Swift 6 code with prior versions. At present, the Swift 6 compiler can use the following language modes:
- Swift 6
- Swift 5
- Swift 4.2
- Swift 4
The Swift documentation states [here](https://arc.net/l/quote/rrrnddoa) that the default language mode is Swift 5. This means that if you do not specify a language mode, then the Swift 6 compiler will use the Swift 5 language mode. While true in principle, I have found that this is not quite so intuitive in practice.
### Using Swift 5 Language Mode In The Swift 6 Compiler
Quick refresher on `Package.swift` files. At the top of every `Package.swift` file, you will see a declaration like this:
```swift
// swift-tools-version:6.0
```
Be advised. Even though this is written as a comment, it is not a comment. It is a directive to the Swift Package Manager. This directive tells the Swift Package Manager the minimum version of the Swift compiler to use. If you have `swift-tools-version:6.0`, then the Swift Package Manager must use the Swift 6 compiler. (We'll see why this is important in a moment.)
To specify the language mode in a target, you can do so like this:
```swift
.target(name: "MyTarget",
dependencies:[.fancyLibrary],
swiftSettings: [
.swiftLanguageMode(.v5)
]
)
```
This tells the Swift 6 compiler to use the Swift 5 language mode for the target `MyTarget`. But according to the docs this should be unnecessary. Remember that the default language mode is Swift 5. So let's leave it out since it is redundant.
```swift
.target(name: "MyTarget",
dependencies:[.fancyLibrary],
swiftSettings: []
)
```
It turns out that we are now using the Swift 6 language mode. Why? According to the docs:
>A `Package.swift` file that uses `swift-tools-version` of 6.0 will enable the Swift 6 language mode for all targets. You can still set the language mode for the package as a whole using the `swiftLanguageModes` property of `Package`. See [docs](https://arc.net/l/quote/yqrnbxcw).
In other words, the **Swift 5 language mode** is indeed opt-in, but only if you are using `// swift-tools-version:5.10`[^1]. But as soon as you use `// swift-tools-version:6.0`, you are using the Swift 6 language mode, by default. To make matters more confusing when you create a new Swift Package[^2], the Swift Package Manager will default to `// swift-tools-version:6.0`.
[^1]: Or any other version of Swift 5.
[^2]: Using `swift package init` or by clicking **File > New Package** inside Xcode.
### Using `swift-tools-version:5.x` In The Swift 6 Compiler
You are of course allowed to use `swift-tools-version:5.10` and earlier in the Swift 6 compiler, but now there are even more gotchas to be aware of. In particular, the `PackageDescription` API has changed between Swift 5 and Swift 6. This means that you will need to use the Swift 5 version of the `PackageDescription` API.
One of the biggest differences between the two APIs is that in the Swift 5 `PackageDescription` API, **you cannot declare a language mode at a per-target level**. Instead, you must declare the language mode at the package level, meaning all of your targets must use the same language mode. (Per target language mode was introduced in [SE-0435](https://github.com/swiftlang/swift-evolution/blob/main/proposals/0435-swiftpm-per-target-swift-language-version-setting.md) and there doesn't appear to be a way to use this feature in Swift 5 with an upcoming feature flag.)
So in short, while it may be technically true that the Swift 6 language mode is opt-in, this isn't really accurate when it comes to SPM. If you are using `// swift-tools-version:6.0` then the Swift 6 language mode is the default.
## Using Swift 6 Features In Swift 5 Language Mode
Thankfully, both the Swift 5 and Swift 6 compiler allow you to use Swift 6 features. You can even use Swift 6 features when using the Swift 5 language mode! This is done by enabling upcoming features. Be sure to read this official Swift blog post on [Using Upcoming Feature Flags](https://www.swift.org/blog/using-upcoming-feature-flags/).
To enable upcoming features in a Swift Package, define your target like so:
```swift
.target(name: "MyTarget",
dependencies:[.fancyLibrary],
swiftSettings:
[.enableUpcomingFeature("ConciseMagicFile"),
.enableUpcomingFeature("BareSlashRegexLiterals"),
.enableUpcomingFeature("ExistentialAny")])
```
Here is a list of [Swift 6 features](https://www.swift.org/migration/documentation/swift-6-concurrency-migration-guide/sourcecompatibility/) from the Swift 6 documentation. To enable a feature, open the features Swift Evolution proposal (e.g. [SE-0337](https://github.com/swiftlang/swift-evolution/blob/main/proposals/0337-support-incremental-migration-to-concurrency-checking.md)), then look for the **Upcoming Feature Flag**. This is the string that you will be using. Then add it to your target like in the example above. Now you can use Swift 6 features in your Swift 5 code! Even better you can pick and choose which features you are ready to use. This is perfect for incremental migration.
## So Many Options. Which Should I Choose?
While it may be frustrating to encounter these rough edges, it is important to remember that change is good. Strict concurrency checking has the potential to eliminate entire classes of bugs which would be a huge benefit for the whole world.[^3] But it's important to acknowledge that change is also painful. This is hard, and if you are struggling, then that is okay. This is not the first time that Swift has had a difficult transition and it won't be the last.
[^3]: I'm not being hyperbolic here. Concurrency bugs are some of the most difficult to debug and can be some of the most difficult to reproduce. Eliminating these bugs would be a huge positive for society at large.
But thankfully, the Swift 6 compiler gives us a lot of tools to help us through this transition. We can use the Swift 5 language mode to keep our code running while we incrementally adopt Swift 6 features. We can use upcoming feature flags to pick and choose which features we are ready to use. Finally, when we are ready, we can use the Swift 6 language mode to get the full benefits of the new Swift 6 features.
Take full advantage of these tools. They are there to help you. And don't feel like you need to adopt the latest and greatest right now. You should take your time and adopt these features at your own pace.
## Bonus: Easily Enable Upcoming Features Using Static Strings
I like to finish my posts with a little "birthday present" for you. Here is a gist that you can add to any `Package.swift` file. This will allow you to easily enable upcoming features using static strings. Please feel free to fork, clone and contribute the rest of the upcoming feature flags from the [docs](https://www.swift.org/migration/documentation/swift-6-concurrency-migration-guide/sourcecompatibility/).
---
## Acknowledgments
Huge thank you to Xiaodi Wu for informing me that the default language mode is Swift 6 when using `// swift-tools-version:6.0`. This was a huge help in writing this post. (See this [forum post](https://forums.swift.org/t/crowd-source-swift-language-modes-in-various-environments/76102/6).)
## Recommended Reading
- [Migrating to Swift 6 | Documentation](https://www.swift.org/migration/documentation/migrationguide)
- [Enabling The Swift 6 Language Mode | Documentation](https://www.swift.org/migration/documentation/swift-6-concurrency-migration-guide/swift6mode)
- [Incremental Adoption | Documentation](https://www.swift.org/migration/documentation/swift-6-concurrency-migration-guide/incrementaladoption)
- [Swift.org - Using Upcoming Feature Flags](https://www.swift.org/blog/using-upcoming-feature-flags/)
- [Migrate your app to Swift 6 - WWDC24 - Videos - Apple Developer](https://developer.apple.com/videos/play/wwdc2024/10169/)
# Safe Constants in GDScript
# Safe Constants in GDScript
When working with constants in GDScript, it's essential to ensure they are safe and maintainable. Constants are values that don't change during the execution of your program, and they play a crucial role in making your code readable, maintainable, and flexible. Here are some best practices for handling constants in GDScript:
**Research:** https://www.perplexity.ai/search/in-gdscript-i-would-like-a-sol-W8FREhZyQciQcqwrpqUB8g
# Gradual Static Typing in GDScript
Any time we learn a new programming language, one of the first things we tend to fixate on is the syntax. But in many ways syntax is actually less important. The syntax is effectively the UI of the programming language. It's how the language "looks". But learning a language also requires understanding how a language "works".
One of the first and most important things that we should learn about a programming language is its **type system**.[^1].
[^1]: Type systems are kind of important to me. If you haven't noticed, I named this blog **Strongly Typed**. It's also a pun. Please laugh. Today, we'll be looking at one aspect of type systems: **static vs. dynamic typing**. We'll learn about each and then we'll see how GDScript has a very unique type system.
## What Is A Type System
First let's get on the same page about type systems. This article will be talking at a very broad, high-level about type systems. In short, a type system is effectively **formatting for your data**.
You're probably familiar with formatting in text. Text can be **bold** or _italicized_ or underlined. These are part of the format of your text. Sometimes we move text from one app to another and our text looks all funky. This is because the two apps are using different formatting. One of the apps doesn't understand the formatting of the text and so it renders it incorrectly. **You can think of formatting as "how something is organized".**
Data can also be formatted (or organized) in a certain way, and in programming languages we call these **types**. Let's say you were writing code that stores a list of people's names. Should you store just their first name? Last name? Their full name? Should their full name be stored together or should they be in separate fields? From a human perspective, these questions are trivial and silly. But from a data perspective, these are very meaningful and important. For example look at this really bad Swift code:
```swift
let peopleString = "Alice Allison, Bob McBlob, Cher"
func greetEveryone(_ peopleString: String) {
let fullNames: [String] = peopleString.split(separator: ",")
.map { String($0) }
for fullName in fullNames {
let nameParts = fullName.split(separator: " ")
let lastName = nameParts[1]
print("Hello, Mr or Ms. \(lastName)!")
}
}
greetEveryone(peopleString)
```
That code prints the following:
```
Hello, Mr or Ms. Allison!
Hello, Mr or Ms. McBlob!
Swift/ContiguousArrayBuffer.swift:675: Fatal error: Index out of range
```
That's right! This code **crashes**. 🧨 Why? Because the code was trying to read the second item from `nameParts` in order to get the last name. But Cher doesn't have a last name! This code makes the incorrect assumption that everyone has exactly two names.
One solution to this problem is to use a type system...
## Static Type Systems
A static type system is one where the types of variables are determined at compile-time. This means that the compiler can check the types of your variables and expressions and ensure that they make sense. Here's an example of a simple static type system in Swift:
```swift
struct Person {
let firstName: String
let lastName: String
}
struct Individual {
let fullName: String
}
```
In this example, we've defined two structs: `Person` and `Individual`. The `Person` struct has two properties: `firstName` and `lastName`, both of which are `String` types. The `Individual` struct has a single property, `fullName`, which is also a `String`.
When we use these types in our code, the compiler can ensure that we're using them correctly. For example, if we try to assign a `Person` to an `Individual`, the compiler will give us an error:
```swift
let alice = Person(firstName: "Alice", lastName: "Allison")
let aliceAsIndividual: Individual = alice // Error: Cannot convert value of type 'Person' to expected argument type 'Individual'
```
The benefit of a static type system is that it catches these kinds of errors at compile-time, before your code even runs. This can save you a lot of headaches and bugs.
### The Problem With Static Type Systems
The downside of static type systems is that they can be a bit more verbose and require more upfront work. In the example above, we had to define the `Person` and `Individual` structs, which is more code than just using a string to represent a person's name.
Additionally, static type systems can sometimes be too rigid. What if we want to represent a person who only has a single name, like "Cher"? We'd have to either shoehorn that into our `Person` struct or create a new `SingleNamePerson` struct. This can lead to a lot of boilerplate code.
## Dynamic Type Systems
The alternative to static type systems is dynamic type systems. In a dynamic type system, the types of variables are determined at runtime, not at compile-time. This means that the compiler doesn't check the types of your variables and expressions - that's left up to the runtime.
JavaScript is a classic example of a dynamic type system. In JavaScript, you don't have to declare the type of a variable - you can just assign any value to it, and the runtime will figure out the type:
```javascript
let person = "Alice Allison"; // person is a string
person = 42; // person is now a number
person = true; // person is now a boolean
```
The benefit of a dynamic type system is that it's more flexible and allows for more dynamic and expressive code. You don't have to worry about defining types upfront, and you can easily change the type of a variable as needed.
### The Problem With Dynamic Type Systems
The downside of dynamic type systems is that they can lead to more runtime errors. In the example above, if we accidentally tried to treat `person` as a string when it was actually a number, we'd get a runtime error. With a static type system, the compiler would have caught that error ahead of time.
Dynamic type systems also make it harder to reason about the structure of your data and the behavior of your code. Without clear type definitions, it can be difficult to understand what a piece of code is doing and how it's using its data.
## The Trade Off Between Static and Dynamic Type Systems
Both static and dynamic type systems have their pros and cons. Static type systems provide more compile-time safety and better tooling support, but can be more verbose and rigid. Dynamic type systems are more flexible and expressive, but can lead to more runtime errors and make the code harder to reason about.
Many programming languages try to find a balance between these two extremes. For example, TypeScript is a superset of JavaScript that adds optional static typing on top of the dynamic type system. This allows developers to get the benefits of both static and dynamic typing, depending on their preferences and the needs of the project.
## How GDScript Approaches This Problem
So now that we have a lay of the land, let's look at how GDScript handles this problem. Is GDScript a dynamic or statically-typed language? The answer is neither. According to GDScript's docs:
> GDScript is a high-level, object-oriented, imperative, and gradually typed programming language built for Godot.
What is a _gradually typed programming language_? Gradual typing is a type system that allows for a mix of static and dynamic typing within the same codebase. This means that, by default all your values are dynamically typed, **but you can opt-in to static typing** where it's beneficial, while still maintaining the flexibility of dynamic typing in other parts of your code.
### Introducing Gradual Typing in GDScript
You can leave the type out of a declaration, and GDScript will infer the type at runtime:
```gdscript
var name = "Alice"
var age = 30
```
But this also means that you can **change** the type at runtime as well:
```gdscript
name = 30
age = "Alice"
```
And that means that it's now your responsibility to always check, at runtime, that you are receiving the type that you expect. The compiler won't help you check types. Unless...
In GDScript, you can declare variable types using the `:` syntax, like this:
```gdscript
var name: String = "Alice"
var age: int = 30
```
Now you are explicitly telling the compiler which type you expect, and the compiler will enforce that for you:
```gdscript
name = 30 # 🔴 Error!
age = "Alice" # 🔴 Error!
```
This approach to typing allows GDScript to provide the benefits of static typing (type safety, better tooling support, better performance) while still maintaining the flexibility of dynamic typing. Developers can choose to use static typing where it makes sense, and dynamic typing where it's more convenient.
### Rough Edges of Gradual Typing in GDScript
While gradual typing is a clever solution that tries to give us the best of both worlds, it comes with its own set of challenges. Let's look at some of the rough edges in GDScript's implementation.
#### Static And Dynamic Code Can Conflict With Each Other
When mixing static and dynamic typing in the same codebase, you can run into some unexpected behavior. Here's a simple example:
```gdscript
# Dynamically typed function
func get_player_name():
if true:
return "Alice"
else:
return 2
# Statically typed function
func greet_player(player_name: String) -> void:
print("Hello, " + player_name + "!")
func foo():
# GDScript should not allow me to do this...
greet_player(get_player_name())
```
Here `greet_player()` only accepts a `String`, and `get_player_name()` may or may not return a `String` so it shouldn't be allowed... but it is.
#### GDScript Has No Generics
GDScript has no support for generics. This means that it's very difficult to express certain ideas in GDScript's type system. This is particularly important when it comes to `Array` and `Dictionary`.
For example, in a language with generics like Swift, you might write:
```swift
let numbers: Array = [1, 2, 3];
let names: Array = ["Alice", "Bob", "Charlie"];
```
But in GDScript, you're limited to:
```gdscript
var numbers: Array = [1, 2, 3] # Could contain anything!
var names: Array = ["Alice", "Bob", "Charlie"] # Could contain anything!
```
Now you can be a little more specific with Arrays. You can add something that looks like generics, and even provides some extra type checking but it's not enforced everywhere you think it would be.
```gdscript
var numbers: Array[int] = [1, 2, 3] # Must contain ints
var names: Array[String] = ["Alice", "Bob", "Charlie"] # Must contain Strings.
```
But do not be fooled. This isn't quite the same thing as generics. It's like a pseudo-generics. It provides type checking for the elements, but it doesn't for example provide different methods. For example `Array[int]` can't have a separate `sum()` method that isn't available on `Array[String]`.
## Conclusion
So there you have it. Gradual typing in GDScript. This was a very pleasant surprise for me when learning this language. But the truth is I'm still early in learning this language. I'm sure there are many other rough edges that I've yet to discover, but I haven't yet determined which are actually a rough edge, and which are my user error.
Please feel free to give me feedback on this article, and tell me anything that I don't understand correctly about GDScript. You can find me on [mastodon](https://iosdev.space/@dandylyons).
## Recommended Reading
- [Gradual typing (Wikipedia)](https://en.wikipedia.org/wiki/Gradual_typing)
# Selective Equality Checking in Swift
The humble `Equatable` protocols is one of the most fundamental tools in Swift, but sometimes it is not always the best tool for the job. Last week we learned how to [check equality for collections while ignoring order]({{}}). Today we will learn how to pick and choose exactly what properties we would like to check equality on. But first let's talk about the problem:
## Why Not Just Use Equatable
For the majority of use cases the best option is to just use the plain old `==` operator. We get this operator automatically when a type conforms to `Equatable`. However it's not always easy conform to `Equatable`. Here are some situations when it might not be feasible or even possible to conform to `Equatable`.
### The Problem with Automatic Equatable Conformance
For the majority of cases, we should start with trying to use automatic `Equatable` conformance. Let the compiler let that boilerplate code for you. This is trivially easy to do in most cases, especially for value types. Simply add `: Equatable` to your type declaration.
```swift
struct MyStruct: Equatable {
let int: Int
}
```
Simple. Swift did all the hard work for us. We even have the option of applying `Equatable` in an extension. This becomes especially handy for generic types.
```swift
struct MyType {
var value: Value
}
extension MyType: Equatable where Value: Equatable {}
// conforms automatically
```
Under normal circumstances Swift would not be able to conform `MyType` to `Equatable` automatically because it holds onto a generic `Value` type. Since we don't know in advance if `Value` is `Equatable`, the compiler is unable to automatically generate a conformance. But when we apply `where Value: Equatable` then the compiler has all the info it needs to create the conformance. When `Value` is `Equatable`, so is `MyType`. but when `Value` is NOT `Equatable`, neither is `MyType`.
Unfortunately, this automatic conformance is not always available.
#### The Conformance Must Be Done In The Same File As The Type Declaration
You can apply `Equatable` at the type declaration or in an `extension` but there is a catch. If you use an `extension` it must be in the same file as the type declaration. Otherwise the compiler will refuse to automatically synthesize a conformance.
#### It Can Be Tough To Guarantee That All Nested Types and Properties Are Equatable
This is especially a problem when your codebase:
1. is still evolving
2. when your codebase depends on outside dependencies which you don't control
3. relies on OOP classes which are unsuited to equatability
If your code is still evolving then maybe it's a great fit for `Equatable` now. But later? Maybe not so much.
##### The Problem With `Equatable` For Reference Types
For reasons that are beyond the scope of this article, it can be quite problematic to do equality checking for reference types such as classes and actors. The short explanation is that reference types encapsulate identity AND behavior. Multiple places could hold on to the same reference and edit the value out from under you. `Equatable` just doesn't quite make sense for many/most reference types.
In most cases, I recommend avoiding conforming a class to `Equatable`. If you must conform a class to equatable, I recommend simply checking if they are the same instance using the `===` operator and calling it a day.
```swift
extension MyClass: Equatable {
static func == (lhs: MyClass, rhs: MyClass) -> Bool {
return lhs === rhs
}
}
```
### The Problem with Manual Equatable Conformance
Swift also allows you to manually conform a type to `Equatable`. This is like an "escape hatch". However, I recommend avoiding this. Manual Equatable conformance does not automatically update as your code base evolves. This is more code for you to maintain. It is very easy to forget to update. Improper `Equatable` conformance leads to false positives and false negatives on tests, and subtle hard to find bugs.
#### When Using A Type That You Don't Control
If you attempt to add an `Equatable` conformance to a library from an outside library when using Swift 6 language mode you will see a warning from the compiler. We can silence this warning using `@retroactive`. But first, [you should read this article on why that's probably a bad idea]({{}}).
---
Alright, we've sufficiently delivered the bad news. Those are the many situations where `Equatable` isn't quite up to the task. Now, what can we do about it? How can we check equality, when `Equatable` isn't readily available?
## Introducing Easy, Selective Equality Checking
For our examples today we'll be using the simple `Person` type:
```swift
struct Person: Identifiable {
let firstName: String
let lastName: String
let age: Int
let id: UUID
let profileImage: UIImage
}
```
Let's first imagine the kind of code we would like to write and then figure out how we would implement that. It would be nice if the call site could look like this:
```swift
let person1 = Person(firstName: "Blob", lastName: "McBlob", age: 34, id: UUID())
let person2 = Person(firstName: "Blob", lastName: "McBlob", age: 34, id: UUID())
person1.isEqualTo(person2, by: \.firstName, \.lastName, \.age)
```
The above code reads almost like plain english.
It's also nice that `Person` is not required to be `Equatable`.
### Our Requirements
Let's try to figure out how we could build something like this.
Our dream requirements are:
1. A function that could work on practically any type.
2. A function that doesn't require the types to be `Equatable`.
3. A function that can selectively choose which properties to evaluate, by using key paths.
### Why `Equatable` Doesn't Quite Work For `Person`
But first let's understand why we would need to build this in the first place. Why not just use `Equatable`. Well, our `Person` struct has a few problems that make it not the perfect candidate for `Equatable` conformance:
The `id` property is a `UUID`. `UUID` conforms to `Equatable` so it's easy enough to conform automatically. But what if we need to check for duplicate persons? What if we need to check if we accidentally created a new `Person` with a new `UUID`? We'd have to fall back to ad hoc equality checking of the other properties anyway.
Next, our `Person` type also holds onto a `UIImage`, which is a reference type, and is not `Equatable`. So our `Person` type can't automatically synthesize `Equatable` conformance. We could manually conform it, but then we'd have to maintain it. It's easy to forget to update this conformance as the type evolves, and thus it's easy to introduce subtle bugs.
## Concrete Method
In my experience it is best to **start with a solution that is as simple, static, and non-generic as possible**. Start with something easy. Then after you get the easy case working, **figure out how to make it more generic and reusable**. So let's implement our API just for the `Person` type first:
```swift
extension Person {
func isEqual(to otherPerson: Person, by keyPaths: KeyPath...) -> Bool {
for kp in keyPaths {
if self[keyPath: kp] != otherPerson[keyPath: kp] { return false }
}
return true
}
}
// Example Usage
person1.isEqualTo(person2, by: \.firstName, \.lastName)
```
Let's evaluate our function:
1. **Pro**: It can evaluate equality on an arbitrary amount of properties.
2. **Pro**: `Person` isn't required to be `Equatable`.
3. **Con**: It only works on `Person`, so it would need to be rewritten for each type.
4. **Con**: Each property must be a `String`.
>**What's that `...` syntax?**
>Pay attention to the `...` operator. This tells the compiler that `keyPaths` is a [variadic parameter](https://docs.swift.org/swift-book/documentation/the-swift-programming-language/functions/#Variadic-Parameters). This means that there can be as many or few `keyPaths` as we want. We don't know ahead of time how many it will be. Under the hood it behaves just like an `Array`.
## Generic Global Function
Now that we've figured out how to meet at least some of our requirements with the `Person` type, let's figure out how to generalize our solution to something that can work with other types:
```swift
/// Check if two values have the same equal value for the same property
func value(_ lhs: T, isEqualTo rhs: T, by keyPath: KeyPath) -> Bool {
return lhs[keyPath: keyPath] == rhs[keyPath: keyPath]
}
// Example Usage
value(person1, isEqualTo: person2, by: \.firstName)
```
Let's evaluate our function:
1. **Pro**: Now we have a function that can work with any type.
2. **Pro**: They type isn't required to be `Equatable`.
3. **Con**: We can only evaluate one property at a time. We might as well just directly do an equality check on the property.
## Checking Multiple KeyPaths (Of The Same Type)
Okay so now that we've generalized our function, let's try to accept multiple key paths at the same time:
```swift
/// Check if two values have the same equal value for multiple properties of the same type
///
/// This function allows you to check for equality on multiple key paths. However, it has the limitation that each key path
/// must point to a value of the same type.
func value(_ lhs: T, isEqualTo rhs: T, by keyPaths: KeyPath...) -> Bool {
return keyPaths.allSatisfy { keyPath in
return lhs[keyPath: keyPath] == rhs[keyPath: keyPath]
}
}
// Example Usage
value(person1, isEqualTo: person2, by: \.firstName, \.lastName)
value(person1, isEqualTo: person2, by: \.age) // age must be checked separately because it's a different type.
```
Let's evaluate our function:
1. **Pro**: Now we can check multiple properties of the same time
2. **Pro**: Now we have a function that can work with any type.
3. **Pro**: They type isn't required to be `Equatable`.
4. **Con**: All of the properties must be of the same type
## Checking Heterogenous Types
Now let's try to accept a collection of `KeyPath`s that can point to any type:
```swift
func value(_ lhs: T, isEqualTo rhs: T, by keyPath: repeat KeyPath) -> Bool {
for kp in repeat each keyPath {
if lhs[keyPath: kp] != rhs[keyPath: kp] { return false }
}
return true
}
// example usage
value(person1, isEqualTo: person2, by: \.firstName, \.lastName, \.age)
```
### How It Works
This solution uses a new Swift 6.0 feature called [Parameter Pack Iteration](https://www.swift.org/blog/pack-iteration/). First we declare that the function receives many types `V`, all of which conform to `Equatable`. Then we accept a pack of `KeyPath` values (notice the `repeat`). Each of these key paths goes from type `T` to `each V`, and each V type will be `Equatable`. Then we iterate through each keypath, and compare the values to each other.
>**Note**: For some reason, this feature appears to work for me even when I am using Swift 5 language mode. So even though the blog says that it is a Swift 6 feature, it appears to not require the Swift 6 language mode. Make sure you read my post? "[Am I Using Swift 5 or 6?]({{< ref "Am I Using Swift 5 or 6" >}})" to understand the difference between Swift 6, **the tools** and Swift 6, **the language mode**.
Now, let's evaluate our function again:
1. Pro: Now we can check multiple properties at the same time **even when they are different types**!
### Room For Improvement
Our final function doesn't quite match up to our original API design. Remember we wanted to build something that could be used like this:
```swift
person1.isEqualTo(person2, by: \.firstName, \.lastName, \.age)
```
This is slightly easier to read. However, I couldn't figure out how to implement this.
This would be an instance method. But we want to add it as a method to almost any type in Swift. There are a few ways that I thought we could achieve it but they all turned out to be dead ends.
## Selective Equality Checking
```swift
struct Person: Identifiable {
let firstName: String
let lastName: String
let age: Int
let id: UUID
let profileImage: UIImage
}
value(person1, isEqualTo: person2, by: \.firstName, \.lastName, \.age)
```
### Works Great With Reference Types
As we noted before, `Equatable` doesn't quite work for reference types. But our `value(isEqualTo:by:)` function works great with reference types! Look what happens if we change `Person` to a class:
```swift
class Person: Identifiable {
let firstName: String
let lastName: String
let age: Int
let id: UUID
let profileImage: UIImage
}
value(person1, isEqualTo: person2, by: \.firstName, \.lastName, \.age)
```
Here the code works exactly the same. The call site makes it very clear that we are not checking if two `Person` instances are the same instance. Instead we are checking if they have the same values for the same properties.
>**Note:** Don't forget that if we want to check if two class instances are the same instance, we can use the `===` operator like this:
```swift
person1 === person2
```
## Conclusion
Well there you have it, **Selective Equality Checking in Swift**. We can now easily and ergonomically check for equality on select properties and we don't need to conform our types to `Equatable`. Do you like this solution? Good news! I now have an even better solution that is even easier to use. It's a micro-library called [SelectiveEquatable](https://dandylyons.net/posts/post-27/selectiveequatable/).
---
## Recommended Reading
- [Swift.org | Iterate Over Parameter Packs in Swift 6.0](https://www.swift.org/blog/pack-iteration/)
- Parameter Packs (5.9)
- [swift-evolution/proposals/0393-parameter-packs.md at main · swiftlang/swift-evolution](https://github.com/swiftlang/swift-evolution/blob/main/proposals/0393-parameter-packs.md)
- [Value and Type parameter packs in Swift explained with examples](https://www.avanderlee.com/swift/value-and-type-parameter-packs/)
# Unordered Equality Checking in Swift
Have you ever needed to compare two arrays in Swift, but the order of elements doesn't matter? I find this often happens to me when convert between an ordered type such as `Array` and an unordered type such as `Set` or `Dictionary`. Today, we'll explore how to implement **unordered equality checking** in Swift, starting with the basics and working our way up to a flexible, protocol-based solution.
## What is Deep Equality?
Before diving into unordered equality, let's briefly discuss deep equality. Many programming languages struggle with deep equality comparisons. Take JavaScript, for example:
```javascript
const a1 = 1
const a2 = 1
console.log(a1 === a2) // true
const obj1 = { a: 1, b: { c: 2 } }
const obj2 = { a: 1, b: { c: 2 } }
console.log(obj1 === obj2) // false
console.log(obj1.b === obj2.b) // false
console.log(obj1.b.c === obj2.b.c) // true
```
In this example, we have two reference types `obj1` and `obj2`. They have the exact same structure so from a value perspective we could say that they are "equal".
JavaScript's `===` operator only checks reference equality for objects, **not their contents**. In other words, JavaScript does not check for **deep equality**. If you'd like to check for deep equality, you'd need to manually implement it yourself or use a library like Lodash's `_.isEqual()`.
## Swift Equality is Deep By Default
Swift, on the other hand, provides deep equality out of the box through the `Equatable` protocol. When you compare two values using `==`, Swift automatically performs a deep comparison of all their properties:
```swift
struct Person: Equatable {
let name: String
let age: Int
let address: Address
}
struct Address: Equatable {
let street: String
let city: String
}
let person1 = Person(name: "John", age: 30, address: Address(street: "123 Main St", city: "Boston"))
let person2 = Person(name: "John", age: 30, address: Address(street: "123 Main St", city: "Boston"))
print(person1 == person2) // true
```
Of course, that is assuming that each type and all their nested types correctly implemented `Equatable`. If you have any custom types with an incorrect implementation of `Equatable` then that incorrect implementation will bubble up to every type that holds it as a property. Thankfully, for value types, Swift implements `Equatable` automatically for us, so we get automatically correct deep equality checking for most types!
## Sometimes We Don't Want True Deep Equality
While deep equality is great, sometimes we need something different. Consider a scenario where you're working with collections and you care about *what* elements are present, but not *where* they appear. For example:
- Checking if two arrays contain the same elements regardless of order
- Verifying that two sets of user permissions are equivalent
- Comparing two API responses to see if there has been any change.
## Unordered Equality Checking
Let's implement a solution that satisfies these requirements:
1. **Equality**: Accurately checks if two values are equal
2. **Deep equality**: all of their properties are equal, no matter how deeply nested
3. **Unordered**: the two values should still be considered "equal" even if they are in different orders
4. **Frequency**: the values should have the same frequency of elements (for example, if `array1` has three `"A"` strings, then so should `array2`)
5. **Instance Method**: We want this function to be an instance method, usable directly from the collection type.
6. **Easily reusable**: We would like this method to be **usable from many types** without having to rewrite it
### Our Dream Call Site
Let's start with what we want our API to look like:
```swift
let array1 = [1, 2, 3, 3]
let array2 = [3, 3, 2, 1]
array1.hasSameElements(as: array2) // true
```
This should return `true` if and only if:
1. The same elements are present in both collections
2. No element is present in one collection but not the other
3. Each collection has the same number of occurrences of each element
4. The function should still return true if each collection is in a different order
## Concrete Method on Array
A good principle is don't start with generics. Instead, start with a concrete type, then generalize your code AFTER you get the concrete version working. Remember we can't simply use `self == otherArray` because it would check both equality AND ordering. In other words we need to figure out how to count the frequency of each element in the array. Let's start by implementing this functionality specifically for arrays:
```swift
extension Array where Element: Hashable {
public func countFrequency() -> [Element: Int] {
var result = [Element: Int]()
for element in self {
result[element, default: 0] += 1
}
return result
}
public func hasSameElements(as otherArray: Self) -> Bool {
let freq1 = self.countFrequency()
let freq2 = otherArray.countFrequency()
return freq1 == freq2
}
}
```
First we will count the number of occurances of each unique value in the `Array` with our new `countFrequency` method. Here we simply create a `Dictionary` and store each element in the dictionary. Every time we find a new value we will increment up the count by one. Now that we've implemented counting the frequency, we can simply compare the frequency of both arrays using another new method: `hasSameElements(as:)`.
### The Hashable Requirement
Notice the `where Element: Hashable` constraint. This is crucial because we're using a `Dictionary` to count frequencies, and dictionary keys must be `Hashable`. If you remove this constraint, the code won't compile. This is an unfortunate extra contraint but it's more than a fair tradeoff in this case. The `Hashable` protocol in Swift inherits from `Equatable`, meaning every `Hashable` type is `Equatable` and most `Equatable` types are `Hashable`. Most types can let the compiler automatically synthesize `Hashable` conformance for them.
## Generalizing Our Solution
Now that we figured out how to add this method to `Array`. What we want to do is add this method to any type that might be able to benefit from this functionality. In OOP languages we would do this by adding it as a method on a superclass. Then every subclass would automatically inherit the new method. This is a fine strategy, but Swift offers another approach: protocol inheritance.
Protocols offer a few benefits. A type can inherit multiple protocols, unlike classes. Also, value types like `structs` and `enums` can also conform to and inherit protocols. So let's not fight against the language. Let's work with the strategy that is used throughout the standard library and ecosystem. Let's add our method to a protocol.
The problem is... which protocol should we extend? Answering this question is a regular painpoint for me. Swift protocols are wonderful because they are simple, self-contained, and very composable. Unfortunately that also means that they have a [very very complex web of inheritance hierarchies](https://swiftdoc.org/v4.2/protocol/sequence/hierarchy/).
After much head scratching, I eventually settled on this:
```swift
extension Sequence where Element: Hashable {
/// Count the number of occurrences of each value in a sequence
public func countFrequency() -> [Element: Int] {
var result = [Element: Int]()
for element in self {
result[element, default: 0] += 1
}
return result
}
/// Check for sequence equality while ignoring order
public func hasSameElements(as s2: Self) -> Bool {
let freq1 = self.countFrequency()
let freq2 = s2.countFrequency()
return freq1 == freq2
}
}
```
I chose `Sequence` because it is the most fundamental protocol for our use case. It doesn't inherit from any other protocol. Practically all of the types that hold multiple values inherit from `Sequence`. For example `Array`, `Set`, `Dictionary`, `Range` etc.
### Performance Optimization
This function meets our requirements nicely. It's easy to read, and it is reusable in so many types and situations. However, perhaps we could improve it's performance a little. Currently we must iterate through both sequences entirely. That's two `O(n)` iterations back to back.
But what if they have different counts? Then we already know that the answer should be `false`. All of that work is unnecessary. Why don't we read the `count`, and escape early if the `count` is unequal? Now add this:
```swift
extension Collection where Element: Hashable {
/// Check for collection equality while ignoring order
public func hasSameElements(as c2: Self) -> Bool {
guard self.count == c2.count else { return false }
let freq1 = self.countFrequency()
let freq2 = c2.countFrequency()
return freq1 == freq2
}
}
```
`Sequence` has no `count` property, but `Collection` does. Now we have two implementations of the same method. Remember `Collection` inherits from `Sequence`. This means that if a `Collection` type calls this method it will use the `Collection` implementation, NOT the `Sequence` implementation. And that's great because the `Collection` implementation is more efficient!
## Real-World Usage
Here are some practical examples of where you might use this functionality:
```swift
// Comparing arrays of numbers
let numbers1 = [1, 2, 3, 3]
let numbers2 = [3, 1, 3, 2]
print(numbers1.hasSameElements(as: numbers2)) // true
// Comparing sets of strings
let set1: Set = ["apple", "banana", "orange"]
let set2: Set = ["orange", "apple", "banana"]
print(set1.hasSameElements(as: set2)) // true
// Working with custom types
struct User: Hashable {
let id: Int
let name: String
}
let users1 = [User(id: 1, name: "Alice"), User(id: 2, name: "Bob")]
let users2 = [User(id: 2, name: "Bob"), User(id: 1, name: "Alice")]
print(users1.hasSameElements(as: users2)) // true
```
## Conclusion
By leveraging Swift's protocol-oriented programming and type system, we've created a flexible, reusable solution for unordered equality checking. Our implementation:
- Works with any `Sequence` whose elements are `Hashable`
- Provides optimized performance for `Collection` types
- Maintains type safety through protocol constraints
- Is easy to use and understand
This approach demonstrates the power of Swift's protocol system and shows how we can create elegant, reusable solutions to common programming challenges. If you like this approach, then grab the code for yourself [here](https://gist.github.com/DandyLyons/8ab7e104c25a9ed3d3a58967de1fb037).
Next week we'll continue our series on equatability in Swift, learning how to selectively check equality on just the properties we care about.
## Recommended Reading
- [Swift by Sundell | The different categories of Swift protocols](https://www.swiftbysundell.com/articles/different-categories-of-swift-protocols)
- [Swift forums | Is there any easy way to see the entire protocol hierarchy of ...](https://forums.swift.org/t/is-there-any-easy-way-to-see-the-entire-protocol-hierarchy-of-something-like-array-or-double/49193)
- [Swiftdoc.org | Sequence hierarchy graph (outdated Swift 4.2)](https://swiftdoc.org/v4.2/protocol/sequence/hierarchy/): (Unfortunately this is the latest I could find. Please let me know if you find something more up to date.)
# A Deep Dive into Value and Reference Types in Swift
Understanding how Swift handles memory and data is key to writing efficient, bug-free code. In this post, we'll explore the differences between value and reference types, and more importantly, what value and reference **semantics** mean in Swift. By the end, you'll know how to think about these concepts when designing your own Swift code.
## Value vs. Reference Types
Let’s start with an analogy that can help illustrate the difference between value and reference types: a library. Most libraries today have both physical books and digital books.
- **Value type**: This is like taking a physical book off the shelf. Only one person can hold the book at a time, and if you want to share it, you need to make a copy. Each person has their own independent copy of the book. If a person decides to write notes in their copy, it doesn’t affect anyone else's copy of the book.
- **Reference type**: But many libraries also lend out digital books (through services like Kindle). When you borrow a digital book, your device downloads the book from a server. Everyone's device downloads the same digital book from the same server. If the server makes a change to the book, everyone sees the updated version.[^1]
[^1]: Of course the analogy doesn't perfectly match, and I am glossing over some complexities of cloud infrastructure. For example, when you download a digital book you are technically making a new copy (value type), but your device will periodically sync changes from the server onto your device (which is like reference semantatics, which we'll talk about later).
This difference between **independent copies** (value types) and **shared instances** (reference types) is at the heart of how Swift manages memory.
## Value vs. Reference Problems
### The Reference Type Problem
In the early 2000s, the world slowly started to see the value of digital books. They save on paper. They take up no physical space. They don't mold or rot. They are virtually free to make infinite copies of. However, in 2009, the world realized a potential problem with digital books when Amazon [bizarrely chose to remotely delete copies of George Orwell's "1984"](https://www.pcworld.com/article/519855/amazon_kindle_1984_lawsuit.html) in Kindles all across the United States. (It turned out that Amazon realized that they didn't have the rights to sell the book in the United State.)
This is very similar to an old computer science problem, sometimes called [spooky action at a distance](https://en.wikipedia.org/wiki/Action_at_a_distance_(computer_programming)). When a reference type's value changes, this change affects every piece of code that is holding onto the same reference. Imagine reading a book, and the words on the page can change, regardless of if you are reading the book. This happens all the time in reference types.
Swift has many different ways to tackle this problem, some of which we'll learn about here today. But one of the biggest ways that Swift tackles this problem is by simply avoiding reference types altogether. Swift prefers value types over reference types, because they are independent copies of a value not shared mutable state. This means you can read a value type and be confident that someone else isn't going to change the value right under your nose.
### The Value Type Problem
To be clear, **value types are not inherently better than reference types**. While value types can be easier to understand and reason, they can also be very wasteful. Every time we create a value type we are creating an entirely new value. This requires more memory and compute to copy.
By analogy, everyone could buy their own individual copy of a movie on Blu-Ray (value type). But this could be wasteful. Each person might watch the movie only once, if at all. Another approach could be to get a streaming subscription (reference type) like Netflix. Now each person effectively has their own reference to the same movies.
## How C Handles This Problem: Pointers
It's important to understand that this is not a unique problem. Every programming language encounters this same problem and implements their own solutions, with their own set of tradeoffs. By learning how other languages handle the same problem, we can better understand the problem itself, and what Swift is doing under the hood. In particular, it is vital to understand how C solves this problem: pointers. In C, you can create value types just like in Swift. But you can also create pointers which _point_ to other values. When you go to the library and look up a book on the computer catalog, they will give you something like a dewey decimal number. This number is a pointer to the physical book (like a reference type). You can take this number to the shelf and find the book (the value type).
In C, these pointers are actual numbers representing the actual physical location where the value is stored on RAM hardware. This is just like a catalog number on a library bookshelf. One thing I like about this approach is it is very easy to tell when I am using a reference type and when I'm using a value type. In C, if I add a `*` to my variable name, then this is a pointer (reference). If there is no `*` then it is a value.
```C
#include
int main() {
int x = 10; // x is a value type, integer with the value of 10
int *y = &x; // y is a pointer to x
*y = 20; // x is now 20
printf("%d\n", x); // Prints: 20
return 0;
}
```
The problem with C's approach is it is very dangerous. It is easy to make mistakes, and very easy for attackers to exploit weaknesses in your code that could have catastrophic effects.
Swift abstracts away these details. Instead of exposing raw memory addresses and manual memory management, Swift provides higher-level concepts (value and reference types) to give you the power of C, while also providing safety. But it is important to remember that [Abstractions do not reduce complexity. They delegate it.]({{< ref "abstractions-increase-complexity">}}) In other words, while Swift's approach makes some things simpler, it also makes other things more complex. There is always a tradeoff.
For example, remember that in C, it is very easy to tell if a variable is a reference or value type. Just look for the `*` operator. In Swift, it is not so simple. At the type level, it's usually pretty easy to tell, but at the call site, there is basically no indication.
## How Swift Handles This Problem
### What Value and Reference Types Mean
In Swift, value and reference types are defined at the type level, and the Swift compiler enforces how they behave.
- **Value Types**: In Swift, structs, enums, and tuples are value types. When you assign or pass a value type, a copy is created. When a change is made to one copy, all the other copies are unchanged. These types typically live on the stack, which tends to make access faster
- **Reference Types**: Classes, actors, and closures in Swift are reference types. When you assign or pass a reference type, you're passing a reference to the same object in memory, not a copy. These types live on the heap, and multiple variables can reference the same instance. If one reference changes the instance, all references see the change.
```swift
struct PhysicalBook {
var title: String
}
var myPhysicalBook = PhysicalBook(title: "Swift Programming")
var yourPhysicalBook = myPhysicalBook // Copies myPhysicalBook into yourPhysicalBook
yourPhysicalBook.title = "Swift Programming 2.0" // Doesn't affect myPhysicalBook. Only yourPhysicalBook is updated
print(myPhysicalBook.title) // Prints: Swift Programming
class DigitalBook {
var title: String
init(title: String) {
self.title = title
}
}
var myDigitalBook = DigitalBook(title: "Swift Programming")
var yourDigitalBook = myDigitalBook // Both myDigitalBook and yourDigitalBook refer to the same instance
yourDigitalBook.title = "Swift Programming 2.0" // Both myDigitalBook and yourDigitalBook are updated
print(myDigitalBook.title) // Prints: Swift Programming 2.0
print(yourDigitalBook.title) // Prints: Swift Programming 2.0
```
#### Key takeaways:
- **Value types** imply **independent copies**.
- when you see `struct`, `enum` or a tuple, think value type
- **Reference types** imply **shared instances**.
- when you see `class`, `actor`, or a closure, think reference type
However, as we'll see next, **these are general guidelines**, and should not be viewed as true in every case. The reason is because Swift allows us to mix value and reference types.
## Mixing and Matching Value and Reference Types
In Swift, a reference type can hold onto value type properties. Likewise a value type can hold onto reference type properties.
### Using Value Types Inside Reference Types
Consider an example of a `Rectangle` class that holds its size and position using value types (`Size` and `Point`):
```swift
struct Size {
var width: Int
var height: Int
}
struct Point {
var x: Int
var y: Int
}
class Rectangle {
var origin: Point
var size: Size
init(origin: Point, size: Size) {
self.origin = origin
self.size = size
}
}
```
How should we think of `Rectangle`, as a reference type, or as a value type? The answer is it depends on the context. "Outside" of the `Rectangle` we can think of it as a reference type because it is a class, but "inside" the `Rectangle`, we can think of its properties as value types.
```swift
class Rectangle {
// ...
var size: Size
var area: Int {
size.width * size.height
}
}
```
Because `Size` is a `struct` we can confidently calculate the area without worrying that somebody changed the value under our nose. Even though `Rectangle` is a reference type, each `Rectangle` holds onto its own individual copy of `size` and therefore it can't be changed by someone else. If `Size` were a class then we would have to think of it as a reference type.
### Using Reference Types Inside Value Types
On the flip side, reference types can also be embedded within value types, and this is where things can get interesting. While value types generally exhibit copy behavior, they don’t always **copy** everything inside them. If a value type contains a reference type, **the reference to the object is copied, not the object itself**. This subtle difference can lead to unexpected behavior if you're not careful.
```swift
class Node {
var value: Int
init(value: Int) {
self.value = value
}
}
struct LinkedList {
var head: Node
init(head: Node) {
self.head = head
}
}
var node1 = Node(value: 10)
var list1 = LinkedList(head: node1)
var list2 = list1 // Copy the LinkedList struct
list2.head.value = 20 // Change value inside the reference type
print(list1.head.value) // Prints: 20
print(list2.head.value) // Prints: 20
```
Here, we have a `LinkedList` struct, a value type, that holds a reference to a `Node` class. When we copy `list1` into `list2`, we create a new instance of `LinkedList`, but since the `head` property is a reference type, both `list1` and `list2` share the same `Node`. Changing the `Node` inside `list2` affects the `Node` inside `list1` as well.
This behavior shows how **copying a value type doesn’t necessarily mean copying all of its contents**. If those contents are reference types, only the reference is copied, leading to shared state. It’s crucial to be aware of this when embedding reference types in value types, as it can cause unexpected side effects.
## What Value and Reference Semantics Mean
The terms "value types" and "reference types" describe **what** something is. But value and reference **semantics** describe **how** they behave.
- **Value semantics**: This means that when you interact with a type, you work with independent copies, regardless of whether it's implemented as a value type or a reference type under the hood. Types with value semantics avoid unintended side effects from shared mutable state, making your code more predictable. In Swift, types like `Array` and `Dictionary` behave like value types but are actually reference types under the hood, thanks to a technique called **copy-on-write**.
- **Reference semantics**: This occurs when a type shares its reference with others, meaning that changes made to one reference are seen by all others. This is typical of reference types like classes or actors, where the object’s state is shared across multiple references.
It’s important to note that the distinction between value and reference **types** is a language-level feature, enforced by Swift’s compiler. However, value and reference **semantics** are more of a language convention or pattern. So when a type is said to have _value semantics_, it means you can treat it **as if** it were a value type[^valueSemantic], but the compiler makes no guarantee that the type will correctly follow value semantics.
[^valueSemantic]: and you don't have to care if it actually **is** a value type under the hood.
### Copy on Write
This next part is not necessary to understand Swift, but it can be helpful to understand more advanced use cases.
Swift regularly uses a pattern called **copy-on-write (CoW)**. This is as an optimization to reduce the overhead of copying large value types like `Array`, `Dictionary`, and `Set`. Under the hood, these types are powered by reference types. When you copy an `Array`, for example, Swift doesn't immediately create a new copy of the underlying data. Instead, it keeps a reference to the same memory until one of the copies is modified.
When a modification occurs, Swift creates a new copy of the data before applying the change. This gives you the benefits of value semantics (each copy is independent), without the performance hit of copying large amounts of data unnecessarily. In short, **CoW is a way to make reference types behave as if they were value types**. In other words, **CoW is a way to implement value semantics**. `Array` is an example of a type that has value semantics, and yet under the hood it is implemented as a reference type.
Let’s look at an example:
```swift
var array1 = [1, 2, 3]
var array2 = array1 // No copy happens here
array2.append(4) // Now the copy is made, and array2 is modified
print(array1) // Prints: [1, 2, 3]
print(array2) // Prints: [1, 2, 3, 4]
```
In this example, the copy of `array1` only happens when `array2` is mutated. This is the essence of copy-on-write. In practice, you shouldn't need to know or care about CoW when you are using a type. The type should handle it for you.
## How to Think About Value and Reference Types in Swift
### At the Declaration Site
When you declare a type, you should think about whether you need independent copies or shared references.
- Use **value types** (e.g., `struct`, `enum`) when you want each instance to be independent, and changes made to one instance shouldn't affect others. Value types are great for things like data models, where predictability and immutability are important.
- Use **reference types** (e.g., `class`, `actor`) when you want to share state between different parts of your program. Reference types are ideal for things like managing global state or objects that need to be modified by multiple clients.
- Use a **value type that holds onto reference types**, when you need features that can't be implemented in a value type. But when you do, you should probably implement value semantics (by using CoW), otherwise you will confuse your API users.
### At the Call Site
Whether you are using a value or reference type will dramatically change how your code behaves. Unfortunately, Swift doesn't make it super easy to know which one your type really is.
```swift
var p1 = Point(x: 0, y: 0) // Is Point a value or reference type? 🤷🏼♂️
var p2 = p1 // Are we copying the value or the reference? 🤷🏼♂️
p2.x = 10 // Did we change just p2 or did we change both? 🤷🏼♂️
```
Like we said before, in general, you can tell if it's a reference type by checking if it's a struct or class. But there are two major problems with this. The call site doesn't tell you if it's a class, so you need to look at the declaration site or the documentation. But the second problem is much bigger. Even if you know that the type is a struct, you still don't know that it's a value type.
Swift developers will often say that you should understand if a type is a reference or value type. In my opinion, this is incomplete advice. **What you should actually care about is if the type follows reference or value semantics**. Remember a value type can hold onto reference types. This means that in certain circumstances they will behave like reference types (i.e. they will have reference semantics). So it can be very difficult and time consuming to determine if a type uses reference or value semantics. Worse yet, the compiler makes no attempt to guarantee value or reference **semantics**.
## What's the solution?
So what's the solution? Unfortunately, today I don't really have one. This is an actual pain point for me in using Swift. However, I do have some guidelines to help:
1. Care less about if a type is a value **type** and care more about if it follows value **semantics**.
- Unfortunately, this distinction can be quite subtle and I hope that this article helps make the distinction clearer. Worse yet, type **semantics** are often undocumented, and there often isn't a way to determine it without reading the source code, or running tests.
2. Avoid using reference types if they are not necessary:
- This is standard Swift practice, but unfortunately it's not always feasible. If you're using an OOP framework like UIKit, you simply must interact with reference types.
## Conclusion
Understanding the distinction between value and reference types (and more importantly how they behave) helps you write more predictable and efficient Swift code. Value types are ideal when you want independent copies of data, while reference types are useful when you need shared, mutable state.
By mastering these concepts, you’ll be better equipped to make informed decisions about your code’s structure and performance.
# Swift Assertions Cheatsheet: How, Why, and When to Crash
As Swift developers, we have several assertion tools at our disposal. But how do we choose the right one for each situation? This blog post will explore the different types of assertions in Swift and provide a framework to help you decide which to use and when.
## What is an assertion?
Essentially assertion is a way to check your program's state at runtime. If the program is behaving correctly (i.e. if its state matches your expectation) then the assertion will do nothing. But if it is not behaving correctly, then **the app will crash**. In other words, **assertions in Swift are a way to crash your program on purpose**.
Why would you want to crash your program on purpose? There are actually several valuable reasons. If you are developing, then crashing your program can help you catch bugs earlier. But it's not a great user experience for users when a program crashes. So we typically don't want to crash in a production build. Still, believe it or not, oftentimes it is best to crash, even in a production build when an end user is using your program! Some bugs can corrupt data, meaning that your user could lose that data forever. While it may be frustrating for a user to experience a crashing app, it would be far worse for them to lose their data. It is especially important to prevent data corruption because it could lead to undefined behavior and even more data corruption.
For this reason, Swift provides us with several tools:
1. `assert()` and `assertionFailure()`
2. `precondition()` and `preconditionFailure()`
3. `fatalError()`
## Types of Assertions in Swift
### 1. `assert()` and `assertionFailure()`
`assert()` is used to check a condition that must be true for your code to continue execution. If the condition is false, the assertion triggers and the program terminates. But the program will only terminate if this was a debug build. If you build the same code for production then Swift will ignore the `assert()` and move on.
```swift
func divide(_ a: Int, by b: Int) -> Int {
assert(b != 0, "Cannot divide by zero")
return a / b
}
```
Use `assertionFailure()` is when you have already checked that this is an appropriate time to crash your app in a debug build.
```swift
// Direction is defined in some other library that we don't own.
enum Direction {
case north, south, east, west
}
// OUR CODE 👇🏼
import DirectionLibrary
func opposite() -> Direction {
switch self {
case .north: return .south
case .south: return .north
case .east: return .west
case .west: return .east
@unknown default:
assertionFailure("Unknown direction")
return .north
}
}
```
In the above example the `switch` requires us to handle every possible case. But since `Direction` is from an external library, they could provide new cases in the future. This should never happen, but Swift still requires us to handle those cases just in case. So we add `@unknown default`. But how do we handle those cases, since we don't know what they are? We can't. So instead, we call `assertionFailure()`. This way if that case ever happens we will be notified in development by a failure. But in production, the assertion failure will be ignored and a dummy value will be sent instead.
### 2. `precondition()` and `preconditionFailure()`
These function similarly to `assert()` and `assertionFailure()`, but they **remain active in release builds**. Use these if a problem could lead to undefined, unpredictable behavior or memory corruption. By crashing, you can prevent these worse problems. Plus, your user will be able to send you a crash report which you can then use to patch the bug.
```swift
/// Calculates the square root of a number.
///
/// - Parameter x: The number to calculate the square root of.
/// - Returns: The square root of `x`.
/// - Precondition: `x` must be non-negative.
func sqrt(_ x: Double) -> Double {
precondition(x >= 0, "`sqrt(_:)` is only defined for non-negative numbers")
// implementation here
}
```
The precondition also forms a contract with the caller of this function. It essentially says "Do not call this function unless you have already checked for this precondition. Notice how, in the example above, we document that `x` must be non-negative when calling this function.
### 3. `fatalError()`
`fatalError()` unconditionally terminates program execution and is always active, even in release builds. This is a very big hammer, so we don't want to use it unless we have no other choice.
```swift
class Animal {
/// Makes the sound of the animal.
///
/// - Important: This method must be overridden by subclasses.
/// - Note: Calling this method on `Animal` directly will cause a fatal error.
func makeSound() {
fatalError("This method must be overridden")
}
}
```
Sometimes a class will implement a function with a fatalError if they require subclasses to override it. However, I prefer not to use this pattern because it's easy to use this API wrong. For example, in many classes it is expected that you finish an implementation by calling the parent implementation (e.g. `super.makeSound()`). This pattern is used throughout UIKit for example. However, if we called `super.makeSound()` here, it would crash. The fact that it would crash is not obvious at the call site, or the definition. Instead we have to pay close attention to the documentation.
Another common use case for `fatalError()` is when the app is unable to load its database upon startup. If the app can't use its database, much if not all of its functionality is broken. It's better to crash. This is a very common pattern when using Core Data for example.
## Crashes vs. Errors
Of course, it bears repeating that we should never crash unless we have exhausted our other options. If there is a problem in your program, consider if it would be better to throw an [Error](https://developer.apple.com/documentation/swift/error). In Swift, errors are intended to be recoverable. In other words, if it is possible to recover from the problem then consider throwing an error. But if the problem produces results that are so bad that they could send your program into undefined behavior, or corrupt data, then you should consider crashing.
## Choosing the Right Tool
Here's a summary table to help you choose the right assertion:
| Assertion Type | Debug Build | Release Build | Use Case |
|----------------|-------------|---------------|----------|
| `assert()` | Active | Inactive | Debugging checks |
| `assertionFailure()` | Active | Inactive | Debugging failure points |
| `precondition()` | Active | Active | Critical checks, API contracts |
| `preconditionFailure()` | Active | Active | Critical failure points |
| `fatalError()` | Active | Active | Unrecoverable errors, required overrides |
- In debug builds, all assertions are active, helping catch errors early.
- In release builds, `assert()` and `assertionFailure()` become no-ops, while `precondition()`, `preconditionFailure()`, and `fatalError()` remain active.
- Use `assert()` for debugging, `precondition()` for critical checks that should always run (like API contracts), and `fatalError()` for truly unrecoverable situations or to mark methods that must be overridden.
Remember, the goal is to catch errors as early as possible while ensuring that your app behaves appropriately in production. Choose your assertions wisely to strike the right balance between robustness and user experience.
## Test Failures Instead of Crashes
`assert()` is powerful because it can help us catch bugs in development, before we ship. But a crash can still be cumbersome to deal with. Is there another approach? What if we could trigger a test failure instead of a crash?
This is the approach of one of my favorite libraries [Swift Issue Reporting](https://swiftpackageindex.com/pointfreeco/swift-issue-reporting). The library includes a function called `reportIssue()`. It behaves much like `assert()` but much more intelligently.
If you're app is currently running in a test, then `reportIssue()` will trigger a test failure. This means you can put `reportIssue()` anywhere you want in your actual app (not just test code)! If any test runs that code, then the test will fail. Even better, when running the app in the Xcode debugger it will trigger a helpful purple runtime warning. This will highlight the exact line that reported the issue. It can even be configured to trigger breakpoints, preconditions, or fatal error!
There are many, many more helpful features, so make sure you check out their documentation yourself.
>Note: Swift Issue Reporting is currently going through a renaming transition. It used to be named "XCTestDynamicOverlay". So it's important to be aware of that so that you don't get confused by older documentation or URL's. Unfortunately Swift Package Manager sometimes gets confused when resolving package manifests in certain situations.
## Consider Crashing
Today we learned the value of crashing. We also learned how, why and when to crash in Swift. The next time you are writing new functionality, don't just consider the happy path. Consider your failure cases, and ask yourself if you should crash.
## Recommended Reading
- Swift Documentation
- [Addressing crashes from Swift runtime errors](https://developer.apple.com/documentation/xcode/addressing-crashes-from-swift-runtime-errors)
- [Analyzing a crash report](https://developer.apple.com/documentation/xcode/analyzing-a-crash-report)
- [Error Handling](https://docs.swift.org/swift-book/documentation/the-swift-programming-language/errorhandling/)
- [SwiftLee - EXC_BAD_ACCESS crash error: Understanding and solving it](https://www.avanderlee.com/swift/exc-bad-access-crash/)
- [SwiftRocks - How To Solve Any iOS Crash Ever](https://swiftrocks.com/how-to-solve-any-ios-crash-ever)
# An Introduction to Swift on the Server
# An Introduction to Swift on the Server
Swift has long been viewed as "that Apple language" or "that iPhone language", and to be fair, for a while that was a reasonably accurate description of the language and ecosystem in the early days. But it hasn't been true for a very long time. Swift can now be run on Apple platforms, Linux, Windows, embedded systems (like IoT devices and Raspberry Pi's), Wasm, and server. In fact, it's harder to think of places that Swift **can't** run.
My goal today is to talk to the "typical" Swift developer and to show them why and how they should get started developing Swift on Server. That would be Swift developers who are used to developing native apps for Apple platforms. This article assumes you have a basic knowledge of how to make a network request from an application. Today, we'll be talking about the other side of that equation. Who receives your network request and how do they compute and send your response? I hope that I can broaden your mind to the possibilities of Swift on Server, and make it less daunting to jump in and get your feet wet.
**There has never been an easier time to get started!**
---
## Why Swift Developers Should Deploy on Server
At the end of the day, I really only see three reasons why someone should start server-side development:
1. **They find it fun and/or interesting**: If it's interesting to you, then just do it. As we'll see below, it's cheap (effectively free), and it's easy to get started. So there's no real reason not to try it.
2. **It solves a problem**: Exploration is fun and all. But we have real problems to solve, and servers can be a very effective tool in your belt. Like any other technology, servers give you superpowers!
3. **To learn**: There are many problems that you could solve today with servers that you are probably unaware of. You can't find out until you experience it. You're probably already paying for a lot of services that are much cheaper to implement on your own and you didn't realize how easy it is to do so.
### Server Superpowers
I'd like to convince you that Swift on Server can help you with #2 (solving your problems). Perhaps a better way to think about it is superpowers. We often want to learn or do a thing in order to solve a problem. This is not a bad way to look at the world, but it is limiting. What if there are problems that you are unaware of? Will you never look for a solution to that problem until you realize it's a problem? Also, does everything have to solve a problem? Videogames don't exactly solve problems, but they're still valuable.
This is why I think it's helpful to think of it in terms of superpowers. In other words, think of it in terms of new capabilities. When you learn of new capabilities, you can begin to think of new ways to use those capabilities (applications). But if you never knew you had those capabilities in the first place, you wouldn't have thought of those applications. For example, in the early 2000s, I remember when cell phones were first adding GPS chips. I remember thinking it was "neat", but not all that useful. Why would I need that? I couldn't have imagined how that capability would unlock turn-by-turn maps directions, ride sharing apps, Find My and so many other things. The point is, **you can't determine what is worth doing, until you determine what can be done**.
So what are the superpowers that servers enable? Well you're likely already aware of most of the capabilities: file storage, data syncing, giving mobile devices access to more powerful computing etc. What you might not be aware of is how approachable these capabilities are. You've probably been delegating them to some other service provider like iCloud, Firebase, AWS or many others. But did you know that you can develop many of these capabilities yourself, in Swift? You can share parts of your codebase in multiple platforms. You can develop in a language that you are familiar with.
### Swift's Superpowers on Server
Swift has a few characteristics that make it particularly well-suited for servers. Swift is fast. It interacts directly with the hardware, without a virtual machine or interpreter unlike Java, Python, and JavaScript. It also doesn't rely on a garbage collector unlike Go and C#. Swift enforces memory safety unlike C or C++. And Swift is embarking on an ambitious albeit painful journey toward enforcing [data race safety](https://www.swift.org/migration/documentation/swift-6-concurrency-migration-guide/dataracesafety/).
The biggest problem I see with Swift on the Server is not the language. It's the ecosystem. The cold hard truth is that the server-side Swift community is not nearly as big as say the Go or Node.js communities. This means far less tools and resources. However the future is looking extremely bright for server side Swift. [Hummingbird just released 2.0](https://hummingbird.codes/) which is Swift 6 and structured concurrency native. Apple released [OpenAPI generator](https://developer.apple.com/videos/play/wwdc2023/10171/) which makes it really easy to define server endpoints, client-side API and documentation all from one simple YAML file. And Swift has an extremely powerful future with [Distributed Actors](https://developer.apple.com/videos/play/wwdc2022/110356/). Don't look at where Swift on Server is now. Look at where it's going, and where it's going looks pretty good.
### There's No App Store Review
One of the most refreshing reasons to get into server side development is there is no App Store review. You can simply release whenever you feel like. You don't have to wait hours, even weeks for esoteric review to give you permission to release. Release when you want to, how you want to.
### Instant Cross-Platform Worldwide Distribution
There is no platform with a bigger distribution than the open web. If you deploy to server, then you have deployed to Mac, Windows, Linux, iOS, Android, even Nintendo Switch. If it has a browser, then it can possibly communicate with your server and that is powerful!
### It's Free to Get Started
Apple development costs a minimum of $100 a year. That's really not too bad, but it is definitely not free. But servers are definitely not free. Servers are physical computers that cost real money to manufacture. They take up actual physical space, meaning they need actual real estate somewhere. They require electricity, and software updates, and security updates, and maintenance. None of that is cheap or free.
But it is effectively a solved problem. Companies have long ago abstracted away the cost of buying, housing, and maintaining physical servers. Instead, they maintain the servers and you pay a fee to host on their servers. This dramatically simplifies logistics. It also lowers the cost since they can split their maintenance cost amongst their many customers. If you did it yourself, you would have to eat those maintenance costs yourself. Think of this model as being kind of like renting an apartment. You pay for the apartment whether or not you sleep in the apartment. Likewise, you pay for the server, whether or not you have users.
Then there's another type of deployment called **serverless** which in the right conditions can make deployment effectively free (with some asterisks). Instead of paying for the server, you are paying for the usage. And you only pay for what you use. So if no one uses your server then you pay nothing. I know it sounds too good to be true, but it's not! We'll talk about it more below.
### It's Easy to Get Started
Lastly, it has never been easier to get started. Swift has a long history of server-side frameworks. They have well established patterns and documentation. Today we will be learning a solution that requires almost no prior knowledge of web development.
---
## Defining Terms
Before we get started, it's important to have a base understanding of web development. Let's define some terms we'll be using.
### Server
>Strictly speaking, the term server refers to a computer **program** or **process** (running program)
>- [Wikipedia](https://en.wikipedia.org/wiki/Server_(computing))
A server is just a _thing_ that serves data. What kind of thing is it? Hardware? Software? Unfortunately the term is used for both (which can be quite confusing). At the end of the day, think of it as a thing that serves data.
### Serverless
"Serverless" is another term that you should get familiar with. And unfortunately it's a little extra confusing. It sounds like it means that there is no server. But there actually is a server somewhere. Many servers actually. The real reason why it's called serverless is because **you, yourself, do not have to care about the server**. The server is an implementation detail. You just send it to them and let them figure it out for you. And if you all of a sudden have a ton of new users, you don't have to buy more servers. The serverless provider will just simply allocate more servers for you, ensuring that your service doesn't go down. (But that will cost more money.)
Fireship has a very good introduction to [serverless computing](https://www.youtube.com/watch?v=W_VV2Fx32_Y) as a concept.
Deciding between servers and serverless is a gigantic topic far beyond the scope of this article. Don't worry about this decision when you are getting started. You will not be boxed into these decisions forever. Whatever code you write can be ported between each of these deployment options, fairly easily. For an absolute beginner, AWS Lambda is a great solution to get started, because you only pay for what you use, and there is a very generous free tier.
### FaaS (Function as a Service)
[FaaS](https://en.wikipedia.org/wiki/Function_as_a_service) is a type of "serverless" computing. It's designed to treat your code like small on-demand functions that are only running when they are needed. When they are not being used, they will shut themselves down (saving you money). When they are being used, they will take a little bit longer to respond, because they must first start up. This is called a _cold start_. Then they will stay up for a period of time for future requests. The system will attempt to anticipate user demand to minimize cold starts (thus faster response time for your users), while also minimizing idle time (thus lower costs for you).
### AWS Lambda
So what is AWS Lambda?
AWS stands for Amazon Web Services. While you might know them for their store, they probably make far more profit from AWS. AWS is the "cloud" that powers Netflix, Twitch, Disney, Airbnb and most of the internet. That doesn't mean it's perfect, but it does mean that it is very reliable. They have to be if they want to keep those customers happy.
[AWS Lambda](https://aws.amazon.com/lambda/) is the first and most popular FaaS vendor.
---
## How to Get Started
Today we'll be using a tool that abstracts away almost all of the complexity of deploying Swift to AWS Lambda. It's a VS Code extension called **"VSCode AWS Lambda Swift"**. We'll also be following along with a [talk by Sebastien Stormacq](https://www.youtube.com/watch?v=M1POAEPATFo) from the Serverside.swift 2024 conference.
### Prerequisites
- You have a basic understanding of Swift and SPM
- You have VS Code installed.
- Tim Condon has a fantastic talk about this. [Watch it here](https://www.youtube.com/watch?v=bH2jpNZmx4Y).
- You have the Swift extension installed on VS Code:
- Read the official [blog post here](https://www.swift.org/blog/vscode-extension/).
- You have created an AWS account ([See the docs.](https://docs.aws.amazon.com/accounts/latest/reference/manage-acct-creating.html))
- You have downloaded and installed the [AWS CLI](https://aws.amazon.com/cli/).
- You have created at least one role on [AWS](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles.html).
- You have configured your AWS CLI to use the credentials from your AWS role. [See docs here](https://docs.aws.amazon.com/cli/v1/userguide/cli-configure-role.html).
- See [Gotchas](#gotchas) below.
- You have the [AWS SAM CLI](https://docs.aws.amazon.com/serverless-application-model/latest/developerguide/install-sam-cli.html) installed.
- **SAM** is a tool provided by AWS to make it easier to port code over to AWS Lambda. Basically SAM will write a bunch of boilerplate for us. Sebastien talks about it much more in depth in [the talk](https://www.youtube.com/watch?v=M1POAEPATFo) I mentioned earlier.
- In order to build and test locally, you must have Docker installed and configured on your machine.
### Install "VSCode AWS Lambda Swift" Extension
Assuming we have our prerequisites finished, you actually have done almost all of the hard work. Now, let's install the [VSCode AWS Lambda Swift](https://marketplace.visualstudio.com/items?itemName=MarwaneKoutar.vscode-aws-lambda-swift) Extension. Open the extensions marketplace in VS Code, search for it, and click **Install**. Don't forget. The extension is open-source and you can find its repo [here](https://github.com/swift-server-community/vscode-aws-lambda-swift-sam).
### Use, Test, and Iterate
Now open the command palette in VS Code so that we can search for the command we want to use. One way to do this is to press CMD+Shift+P. Now type in `AWS Lambda Swift: Open AWS Lambda Swift Dashboard`. You should see the command appear in the search results. When you run this command, it will open a dashboard for you to use.

The first thing you should do is click the button with the three dots at the top right. Then click "Check prerequisites". The extension will then check if you have the correct tools installed on your system.
In the top section we'll tell the extension where to generate files. We can keep this the same. Next, you must name your project. Then choose a region that is somewhere near you. ([Read more about regions in the docs here](https://docs.aws.amazon.com/en_us/AWSEC2/latest/UserGuide/using-regions-availability-zones.html)). Next there are five workflows. Only use the workflows that you need.
#### Initialize Project
This workflow will generate the boilerplate code for you. Pick a template. Read the very helpful descriptions to understand how they work. Look at the diagram picture to understand the architecture.
At the time of writing, there are 5 templates. I want to highlight a few:
- `api-to-lambda`: this is the simplest to setup and the one I'd recommend starting with
- `openapi-to-lambda`: this allows you to define your endpoints in a simple YAML format. Then the OpenAPI generator will generate the Swift endpoints, Swift model types, and the server API documentation for you automatically!
- `scheduler-to-lambda`: this allows you to define a lambda function that will work during a predetermined schedule.
#### Build Project
This builds the project locally.
#### Local Invoke
This will house your Swift code in a container, locally on your machine so that you can test its functionality.
#### Deploy Project
This will follow the directions in your SAM declaration (the `template.yml` file) to deploy your code to AWS Lambda. Once it has been deployed, it will give you the URL, and you can try it immediately. If you have a client, for example an iPhone app, this is the URL that you will call in your network request.
#### Remote Invoke
Remote Invoke allows you to call the Lambda function directly from VS Code. Simply select the Function, the Event, and the Stack Name, then click **Invoke**.
## Gotchas
When I set up my AWS CLI, I ran `aws configure` to give it my credentials. It's fairly straightforward. Just answer the questions. However I had a typo in one of my answers. It asks which region should be your default. (A region is effectively which datacenter should Amazon host your code in.) I wrote `us-west` when I should have written `us-west-1`. Because of this, the "VSCode AWS Lambda Swift" extension produced an error saying that it could not fetch the AWS regions. After I corrected my configuration, then the extension was able to fetch the regions.
---
## Next Steps
Now that you've taken your first steps into Swift on Server development, here are some suggestions for further learning and exploration:
### Learn HTTP Basics
Understanding the fundamentals of HTTP (Hypertext Transfer Protocol) is crucial for server-side development. Here are some key areas to focus on:
1. HTTP Methods (GET, POST, PUT, DELETE, etc.)
2. Status Codes (200 OK, 404 Not Found, 500 Internal Server Error, etc.)
3. Headers and their purposes
4. Request and Response structures
5. RESTful API design principles
Resources:
- [MDN Web Docs: HTTP](https://developer.mozilla.org/en-US/docs/Web/HTTP)
- [RESTful API Design - Best Practices](https://restfulapi.net/)
### Learn Hummingbird or Vapor
While AWS Lambda is great for getting started, you might want to explore more comprehensive Swift server-side frameworks. Two popular options are:
1. **Hummingbird**: A lightweight and fast server-side Swift framework.
- [Hummingbird Official Website](https://hummingbird.codes/)
- [Hummingbird GitHub Repository](https://github.com/hummingbird-project/hummingbird)
2. **Vapor**: A popular, feature-rich web framework for Swift.
- [Vapor Official Website](https://vapor.codes/)
- [Vapor Documentation](https://docs.vapor.codes/)
Both frameworks offer different approaches and feature sets. Explore them to see which one aligns better with your project needs and personal preferences.
### Recommended Resources
To deepen your understanding of Swift on Server and serverless architecture, consider the following resources:
- [Swift On Server.com](https://swiftonserver.com/)
- [Introduction to Hummingbird 2](https://www.youtube.com/watch?v=FHO_BfidQlQ)
- [Swift for WebAssembly](https://www.youtube.com/watch?v=cJyNok8OAuE&t=903s)
- [ServerSide.swift Conference](https://www.serversideswift.info/) - Annual conference dedicated to Swift on the server
### Practice Projects
The best way to learn is by doing. Here are some project ideas to get you started:
1. Build a simple REST API for a todo list application
2. Create a weather data aggregator that fetches data from multiple sources
3. Develop a basic chat server using WebSockets
4. Build a file storage and sharing service
5. Create a simple blog engine with a JSON API
Remember, the key to mastering Swift on Server is consistent practice and staying curious. Don't be afraid to experiment with different frameworks, architectures, and deployment strategies. As you gain more experience, you'll develop a better understanding of when to use serverless functions like AWS Lambda and when to opt for a full-fledged server application.
Happy coding, and welcome to the exciting world of Swift on Server!
# Exhaustive, Flexible, Multi-Typed Error Handling in Swift
Swift has long had fantastic error handling! Errors are simple value types that conform to the `Error` protocol.
```swift
struct IceCreamShop {
enum Error: Swift.Error {
case notEnoughMoney
case flavorNotSoldHere
}
private(set) var availableFlavors: [String: IceCreamFlavor]
private(set) var cashOnHand: Int
private(set) var isFreezerOn = true
private(set) var billLastPaidOn: Date
// ...
}
```
I really like this pattern! Here, we define a new error type that conforms to the `Error` protocol. The definition feels a little strange but the call site is very nice. Normally we would simply conform a type to `Error` but our type is also called `Error` so we have to disambiguate. We define an enum type named `Error` and it conforms to the `Swift.Error` protocol (the `Error` protocol from the Swift standard library). Why go to this trouble? Because the nested type makes the purpose very clear. In the outside world we can refer to the type as `IceCreamShop.Error`, and inside the type we can call it `Self.Error`. So it is very clear that `IceCreamShop.Error` is designed to contain all the possible errors of the `IceCreamShop` type. However, this is just a naming convention and nothing in the compiler enforces which types of errors can be thrown.
## The Problem with Untyped Errors
This has been a bit of a pain point in Swift. Thankfully, we know exactly which functions can throw. We must handle every thrown error. We must mark every function that can throw with the keyword `throws` at the definition site, and with `try` at the call site.
But how do we know what types of errors might be thrown? We have to do some digging in the documentation (if it even exists) and we have to hope that we didn't miss any error cases.
```swift
do {
try iceCreamShop.sellIceCream(flavorName: "Strawberry")
} catch {
// what kind of errors should I expect???
}
```
## Typed throws in Swift 6
Swift 6 made this much nicer with typed errors. Now a function can declare in advance what types of errors it will throw. The compiler will enforce that the function is not allowed to throw any other Error types, meaning you can exhaustively handle all the error types without worrying if you missed any. We do this with a new type parameter that can be applied to the `throws` keyword. Now the compiler will guarantee that the function is only allowed to throw that type of function, and the caller can rest assured knowing that they've handled every case.
```swift
func sellIceCream(flavorName: String) throws(Self.Error) {
guard isFlavorSoldHere(flavorName) else { throw .flavorNotSoldHere }
try availableFlavors[flavorName]?.scoop() // 🔴
// Thrown expression type 'IceCreamFlavor.Error' cannot be converted to error type 'IceCreamShop.Error'
cashOnHand += 1
try payBillIfNecessary()
}
```
This is good because we can guarantee that the function will throw `IceCreamShop.Error` errors and only that type. Another nicety is that the compiler can infer the error type. Notice how we `throw .flavorNotSoldHere` instead of `throw Self.Error.flavorNotSoldHere`.
Nevertheless, typed throws here can be fairly limiting. What if we need to handle error types that have been defined elsewhere? One approach is we could handle the outside error types here, but here might not be the best place to handle it. What if our callers want to handle those errors?
Another approach is we could add outside error cases to our error type, then we can throw our own errors.
```swift
struct IceCreamFlavor {
enum Error: Swift.Error {
case flavorOutOfStock
case iceCreamMelted
}
// ...
}
struct IceCreamShop {
enum Error: Swift.Error {
case notEnoughMoney
case flavorNotSoldHere
// from IceCreamFlavor.Error
case flavorOutOfStock
case iceCreamMelted
}
// ...
func sellIceCream(flavorName: String) throws(Self.Error) {
guard isFlavorSoldHere(flavorName) else { throw Self.flavorNotSoldHere }
do {
try availableFlavors[flavorName]?.scoop()
} catch let error as IceCreamShop.Error {
switch error {
case .flavorOutOfStock: throw Self.flavorOutOfStock
case .iceCreamMelted: throw Self.iceCreamMelted
}
} catch {
print("🚨 Unknown error not handled.")
}
cashOnHand += 1
// ...
}
}
```
I really would not recommend that we use this approach. For one, we now have duplicated code that needs to be kept in sync. We also have to maintain documentation to match someone else's types and documentation. Furthermore, the caller loses the original error type. They have to trust and rely on us to keep our types and documentation and types in sync with the other error types.
What would be really nice is if there were a way to declare that we could throw multiple types. What if we could declare something like this?
```swift
func sellIceCream(flavorName: String) throws(Self.Error & IceCreamFlavor.Error) {
}
```
Here we would be saying, my function can throw either a `Self.Error` (`IceCreamShop.Error`), or an `IceCreamFlavor.Error`. But alas, Swift does not allow us throw more than one type of error. But fret not, there is actually a better solution, using associated values on enums.
## Multi-Typed Errors With Exhaustive Handling
Recall that an enum is a set of cases. But you can also attach an [associated value](https://docs.swift.org/swift-book/documentation/the-swift-programming-language/enumerations/#Associated-Values) to as many or as few of those cases as you like. So we can effectively embed our `IceCreamFlavor.Error` into our `IceCreamShop.Error`. So we would transform this...
```swift
struct IceCreamShop {
enum Error: Swift.Error {
case notEnoughMoney
case flavorNotSoldHere
// from IceCreamFlavor.Error
case flavorOutOfStock
case iceCreamMelted
}
// ...
}
```
...into this:
```swift
struct IceCreamShop {
enum Error: Swift.Error {
case notEnoughMoney
case flavorNotSoldHere
case flavorError(IceCreamFlavor.Error)
}
// ...
}
```
Now we no longer need to keep our types and documentation in sync. It is made explicitly clear in the type system that we are wrapping a `IceCreamFlavor.Error` into an `IceCreamShop.Error` and we are passing the original error onto the caller. Now the caller can exhaustively handle all the error cases of our type, and the external type.
```swift
do {
try iceCreamShop.sellIceCream(flavorName: "Strawberry")
} catch {
switch error { // Swift knows that error is a `IceCreamShop.Error`
case .flavorNotSoldHere:
print("Sir, this is a Baskin Robbins.")
case let .flavorError(flavorError):
switch flavorError {
case .flavorOutOfStock:
print("Shucks! We're out of that flavor.")
case .iceCreamMelted:
print("...would you like a milk drink instead? 😅")
}
case .notEnoughMoney:
print("Time for us to go out of business...")
}
}
```
Recall that in Swift `switch` requires us to exhaustively handle every enum case. In fact, if we forget any cases, then Swift will through a compile-time error which is great. In the example above we used nested switch statements to guarantee that we are handling every case of `IceCreamShop.Error` **and** every case of `IceCreamFlavor.Error`. If we ever add a case to either error type, then these switch statements will warn us that there are new error cases that we need to handle! We have a compile-time guarantee that we have handled every possible error!
## One Large Caveat: structs
There is a large caveat to mention about this approach. While it is very common for errors in Swift to be designed as an enum, this is not the only way. Swift just requires our errors to be a **value type** that **conforms to the enum protocol**. In other words, errors can also be structs. That's a bit of a problem because a `switch` can exhaustively pattern match on enums, but not structs. In other words we lose that exhaustive checking for structs. But all is not lost. We wouldn't lost the exhaustivity for everything, just for the struct. And even then, we know that our error cases are confined to whatever that struct can produce. So if we added a struct case...
```swift
struct IceCreamShop {
enum Error: Swift.Error {
case notEnoughMoney
case flavorNotSoldHere
case flavorError(IceCreamFlavor.Error)
case networkError(NetworkError)
}
// ...
}
struct NetworkError: Error {
let statusCode: String
}
```
... we could still handle cases like this...
```swift
do {
try iceCreamShop.sellIceCream(flavorName: "Strawberry")
} catch {
switch error { // Swift knows that error is a `IceCreamShop.Error`
case .flavorNotSoldHere:
print("Sir, this is a Baskin Robbins.")
case let .flavorError(flavorError):
switch flavorError {
case .flavorOutOfStock:
print("Shucks! We're out of that flavor.")
case .iceCreamMelted:
print("...would you like a milk drink instead? 😅")
}
case .notEnoughMoney:
print("Time for us to go out of business...")
case let .networkError(networkError):
// handle network error here
}
}
```
It is true that we lost our ability to `switch` on the `NetworkError`, since it is a struct, but we did not lose exhaustive checking for the `IceCreamFlavor.Error`, nor for the rest of the `IceCreamShop.Error`.
It's also worth noting that almost anything that can be expressed in a struct `Error` can also be expressed in an enum `Error`. If you're consuming someone else's `Error` type then you're kind of just stuck with whatever they give you. But if you are used to writing `Error`s as struct, try writing it as an enum instead. For example we could just as easily rewrite our `NetworkError` to look like this:
```swift
enum NetworkError: Error {
case statusCode(String)
}
```
## Untyped Errors in Swift 6
Swift has always been a strongly, statically typed language by default. But that's not the case when it comes to errors. Before Swift 6 error types were statically defined but never really enforced, meaning it was your job to find all the possible error types and handle them. So how do we transition from a non-typed error language to a typed-error language? Who knows how many throwing functions there are? Do we have to annotate types to all of our throwing functions? That sounds like a nightmare! Thankfully this is not the case.
We can continue using the `throws` keyword just as we did before and it behaves exactly the same as before. While it isn't strictly necessary to understand how this works, it is helpful.
```swift
func nonThrowingFunction() {
//...
}
func throwingFunction() throws {
//...
}
```
This is how we would have defined functions in a pre-Swift 6 world, and in fact this is probably the way that we will continue to define most functions in a post-Swift 6 world. But let's look at what Swift is actually inferring.
```swift
func nonThrowingFunction() throws(Never) {
//...
}
func throwingFunction() throws(any Error) {
//...
}
```
Both of these styles are equivalent in Swift 6. If you define a non-throwing function in Swift 6, it will infer it to be a `throws(Never)`. In practice, this doesn't really change anything. It's just kind of cool to know. But the next one is more important...
If you define a plain old throwing function, using `throws`, but you don't specify the type, then Swift 6 will infer it to be a `throws(any Error)` type. Recall that `Error` is a protocol, not a concrete type. Also recall that `any` behaves differently than `some`.
`some` essentially says _"Swift, we know the type statically, at compile-time, but I don't want to figure it out. I just know it conforms to this protocol. Can you please figure out the actual type for me, please?"_ This is why we use `some` in SwiftUI. In the example below, `body` is a `Text` type. We know this at compile time.
```swift
struct MyView: View {
var body: some View {
Text("Hello world!")
}
}
```
`any` says something very different than `some`. `any` says _"I don't know the type, but I do know the protocol."_ This part is just like `some`. But here's the part that's very different. `any` also says _"Hey Swift, I don't want you to figure out the type at compile time. In fact, I want to be able to dynamically change the concrete type whenver I feel like it. The only guarantee is it will always be a type that conforms to this protocol."_
For more info on `any` see the WWDC talk about it [here](https://developer.apple.com/videos/play/wwdc2022/110352/?time=1251).
This is the way that pre-Swift 6 `throws` worked (and the way that it will continue to work post-Swift 6). `throwingFunction()` could throw `any Error`. The type system doesn't know ahead of time what the error type will be. The only thing it does know is that it will conform to `Error`. The formal name for this kind of type is called an *existential type*. Existential types are great because they give us more flexibility at runtime, but this flexibility is not free.
>Throwing an instance of any Error or another boxed protocol type requires allocating memory at runtime to store the error. In contrast, throwing an error of a specific type lets Swift avoid heap allocation for errors.
>- [Swift.org](https://docs.swift.org/swift-book/documentation/the-swift-programming-language/errorhandling/#:~:text=Throwing%20an%20instance%20of%20any%20Error%20or%20another%20boxed%20protocol%20type%20requires%20allocating%20memory%20at%20runtime%20to%20store%20the%20error.%20In%20contrast%2C%20throwing%20an%20error%20of%20a%20specific%20type%20lets%20Swift%20avoid%20heap%20allocation%20for%20errors.)
Essentially any time you use an existential type, including any time that you use the `any` keyword[^1], this will require the compiler to store your type in a wrapper type that can find the underlying value at runtime. In other words, it uses more memory, and it requires slightly more compute. Most of the time, this is small enough to not matter, but there are cases when it very much matters. For example, if you are deploying to [Embedded Swift](https://www.swift.org/blog/embedded-swift-examples/) or [Swift on Wasm](https://swiftwasm.org/) then this dynamic runtime is not available. You essentially have to type all your errors in these constricted environments.
[^1]: and therefore anytime you use the `throws` keyword without specifying a type
Outside of those constricting environements, the performance benefits of typed throws is probably negligible. But the usability benefits can be considerable. It can be quite nice to have the comfort of knowing that you have a compile-time guarantee that you have exhaustively handled every possible error case. It's also nice to document your error cases in the type system. This way, even if we miss a detail in the docs, we know that the compiler has our backs.
## Should You Use Typed Errors
Typed throws are probably one of my favorite new features in Swift 6, but understandably it's totally overshadowed by another set of features, strict concurrency checking. The other thing that is strange is that **it almost feels like the language team is actively discouraging us from using this shiny new toy**:
>All of the examples above use the most common kind of error handling, where the errors that your code throws can be values of any type that conforms to the Error protocol. This approach matches the reality that you don’t know ahead of time every error that could happen while the code is running, especially when propagating errors thrown somewhere else. It also reflects the fact that errors can change over time. New versions of a library — including libraries that your dependencies use — can throw new errors, and the rich complexity of real-world user configurations can expose failure modes that weren’t visible during development or testing. The error handling code in the examples above always includes a default case to handle errors that don’t have a specific catch clause.
>[Swift.org](https://docs.swift.org/swift-book/documentation/the-swift-programming-language/errorhandling/#Specifying-the-Error-Type)
This paragraph has some good points. It is true that _"you don’t know ahead of time every error that could happen while the code is running"_, but part of me wonders if this is splitting hairs. Using the approach above, we are not guaranteeing that our code has no errors at all. That's just silly and its more of a philosophical statement than a meaningful statement in code. No, the above approach is guaranteeing that **we handled every error type that was explicitly declared by the library**. In other words, the library author declared _"Hey, watch out for these types of errors."_ by writing `throws(MyErrorType)` and we responded _"Thanks for the heads up!"_ in the `catch` block.
The other thing that is baffling to me is that the docs recommend using the `default` case. In practice, I actively avoid using `default` whenever possible. As soon as you use `default`, you lose exhaustive checking. The convenience it adds is negligible, and the cost just isn't worth it.
## Conclusion
Error handling has never been a substitute for testing, and that won't change with typed errors. But with typed errors, and the approach described above we can guarantee that we won't forget to catch error cases. **This approach certainly cannot be applied everywhere**, and indeed there are many situations where we have too many unknown variables to use this approach. But this approach can be used in some places, and wherever it is used, it can greatly improve ergonomics, readability and maintainability. Try using typed throws in small simple areas in your code base. Using the approach above, you can "bubble up" errors as high as you like, allowing you to gradually add more typed throws to your code base.
I try to release new posts every week. If you liked this post (or even if you didn't like it) please give me some feedback on [Mastodon](https://iosdev.space/@dandylyons), [LinkedIn](https://www.linkedin.com/in/dandylyons/) etc.
---
If you would like to see the full toy example of the ice cream shop, please check out the gist [here](https://gist.github.com/DandyLyons/ab101ecaa4d8a73c4202ed2cc8a0a12d).
# How to Visualize a Dependency Graph of Swift Dependencies
As projects grow in complexity, it is common to use two techniques:
1. Depend on external libraries.
2. Split your codebase into multiple smaller modules.
These techniques have a number of benefits including:
1. You can reduce build times by only building select modules, instead of the entire project.
2. You can reuse modules in other projects.
3. Swift forces you to define external APIs with the `public` keyword, thus enforcing best practices.
But a modularized codebase also increases complexity by creating a web of dependencies. Small changes in one module, can have vast ripple effects down the dependency chain. For this reason, it can be immensely helpful to visualize your dependency graph like this.
![A dependency graph of many modules in rectangles, with arrows pointing to their dependencies, represented by other rectangles.]()
Here are a few methods to do so in the Swift ecosystem.
## Assessing Dependencies Before Adding Them
Ideally, it is best to assess your dependencies **before** you depend on them. You don't want to be put in a situation where you depend on a module:
1. with a license that is incompatible with your business model
2. that hasn't been maintained in ages
3. doesn't support the platforms you need
4. that has a security flaw
5. that violates your privacy policy
6. many other issues...
Of course, we can investigate many of these issues by viewing the GitHub page (or wherever it is hosted). If it has a package page on [Swift Package Index](https://swiftpackageindex.com/) then you can see even more helpful metrics. (See [here]({{< ref "spi-tips">}}) for how you can take full advantage of Swift Package Index.)
## Transitive Dependencies
However, it is important not to forget your transitive dependencies. In other words, if you depend on "A", and "A" depends on "B", then you **also** depend on "B". Therefore, we should look at our immediate dependencies, assess them, look at **their** dependencies, assess them, and follow this chain until we have assessed all of the transitive dependencies. Not only that, ideally, you should repeat this process when packages are updated. This can be quite tedious and error prone. Let's look at some tools to make this easier.
## Viewing Dependencies in a Package.swift Manifest
Perhaps the most obvious place to look is in the Package.swift manifest of each package. Here you can see every target that is defined by the package, and each of their dependencies. This is the source of truth and tells you everything you need to know to find your answers. But it doesn't make it easy to assess your entire dependency graph.
For one, this will only show the dependencies that are explicitly mentioned in the Package.swift file. It will not include transitive dependencies. So, you will need to go to each dependency's repo (at the correct version) and view their Package.swift file. This approach is not very scalable.
## Viewing Dependencies on GitHub
Next we can use the "Insights" feature on GitHub. First go to the repo, then click the "Insights" tab. Then click the "Dependency graph" tab. This will show all the dependencies of the repo, even the transitive dependencies. It will even link to each repo.
But it doesn't actually show you the graph. In other words, it shows you each of the dependencies, but it does not show you the dependency relationships between each dependency. Quick mention. Each Swift Package, after they have been resolved, will have a Package.resolved file. This file is a JSON which includes all the dependencies. However, it also will not show the dependency graph.
## Downloading an SBOM from GitHub
I'd be remiss if I didn't mention GitHub's "Export SBOM" button. An SBOM is a "Software Bill of Materials". It's essentially a document in the form of a JSON file, that shows all the dependencies of a project, and provides further information about the licenses and security vunlerabilities of each dependency. I think this is a fine addition, and I hope it becomes industry standard everywhere. Be sure to check out the GitHub docs: [Exporting a software bill of materials for your repository](https://docs.github.com/en/code-security/supply-chain-security/understanding-your-software-supply-chain/exporting-a-software-bill-of-materials-for-your-repository).
## Visualizing Dependencies in Your Project
Finally, let's talk about the interesting part: visualizing the dependency graph. There are many ways to do this. I'm going to start with one of the simplest, and then I'll share a better solution. This first solution will only work with dependencies managed by SPM.
### Using `swift package show-dependencies`
First, in your terminal, navigate to the directory that contains your Package.swift file. Then run:
```zsh
swift package show-dependencies --help
```
Now we can see the help page for `swift package show-dependencies` which is the tool that we'll be learning now. As you can see it will read your Package.swift manifest, resolve the dependency graph and then output it in your desired format. The available formats are `text` (the default), `flatlist`, `json`, and `dot`.
### Visualizing a dot (GraphViz) graph
The option that will be most helpful for visualization will be `dot`. DOT is a text language for describing graphs like our dependency graph. It's typically stored in a `.dot` file and it is also part of the [Graphviz](https://en.wikipedia.org/wiki/Graphviz) project. Let's generate it.
```zsh
swift package show-dependencies --format dot
```
You can install dot on your system to parse the text and generate a visual graph, or you could go to use the site [Graphviz Online](https://dreampuf.github.io/GraphvizOnline/). The Swift package CLI tool kinda just throws it in there with everything else which is a bit of a mess. So look for the beginning of the dot code which starts with `digraph DependenciesGraph {`. Copy the dot code from that line to the end of the terminal output. Here's an example of what that looks like:
```dot
digraph DependenciesGraph {
node [shape = box]
"/Users/daniellyons/Developer/My Swift Packages/SPM_AddDependencies_CLI" [label="spm_adddependencies_cli\n/Users/daniellyons/Developer/My Swift Packages/SPM_AddDependencies_CLI\nunspecified"]
"https://github.com/pointfreeco/swift-composable-architecture.git" [label="swift-composable-architecture\nhttps://github.com/pointfreeco/swift-composable-architecture.git\n1.15.0"]
"/Users/daniellyons/Developer/My Swift Packages/SPM_AddDependencies_CLI" -> "https://github.com/pointfreeco/swift-composable-architecture.git"
"https://github.com/apple/swift-collections" [label="swift-collections\nhttps://github.com/apple/swift-collections\n1.1.4"]
"https://github.com/pointfreeco/swift-composable-architecture.git" -> "https://github.com/apple/swift-collections"
"https://github.com/pointfreeco/combine-schedulers" [label="combine-schedulers\nhttps://github.com/pointfreeco/combine-schedulers\n1.0.2"]
"https://github.com/pointfreeco/swift-composable-architecture.git" -> "https://github.com/pointfreeco/combine-schedulers"
"https://github.com/pointfreeco/swift-concurrency-extras" [label="swift-concurrency-extras\nhttps://github.com/pointfreeco/swift-concurrency-extras\n1.2.0"]
"https://github.com/pointfreeco/combine-schedulers" -> "https://github.com/pointfreeco/swift-concurrency-extras"
"https://github.com/pointfreeco/xctest-dynamic-overlay" [label="xctest-dynamic-overlay\nhttps://github.com/pointfreeco/xctest-dynamic-overlay\n1.4.2"]
"https://github.com/pointfreeco/combine-schedulers" -> "https://github.com/pointfreeco/xctest-dynamic-overlay"
"https://github.com/pointfreeco/swift-case-paths" [label="swift-case-paths\nhttps://github.com/pointfreeco/swift-case-paths\n1.5.6"]
"https://github.com/pointfreeco/swift-composable-architecture.git" -> "https://github.com/pointfreeco/swift-case-paths"
"https://github.com/swiftlang/swift-syntax" [label="swift-syntax\nhttps://github.com/swiftlang/swift-syntax\n600.0.1"]
"https://github.com/pointfreeco/swift-case-paths" -> "https://github.com/swiftlang/swift-syntax"
"https://github.com/pointfreeco/swift-case-paths" -> "https://github.com/pointfreeco/xctest-dynamic-overlay"
"https://github.com/pointfreeco/swift-composable-architecture.git" -> "https://github.com/pointfreeco/swift-concurrency-extras"
"https://github.com/pointfreeco/swift-custom-dump" [label="swift-custom-dump\nhttps://github.com/pointfreeco/swift-custom-dump\n1.3.3"]
"https://github.com/pointfreeco/swift-composable-architecture.git" -> "https://github.com/pointfreeco/swift-custom-dump"
"https://github.com/pointfreeco/swift-custom-dump" -> "https://github.com/pointfreeco/xctest-dynamic-overlay"
"https://github.com/pointfreeco/swift-dependencies" [label="swift-dependencies\nhttps://github.com/pointfreeco/swift-dependencies\n1.4.1"]
"https://github.com/pointfreeco/swift-composable-architecture.git" -> "https://github.com/pointfreeco/swift-dependencies"
"https://github.com/pointfreeco/swift-dependencies" -> "https://github.com/pointfreeco/combine-schedulers"
"https://github.com/pointfreeco/swift-clocks" [label="swift-clocks\nhttps://github.com/pointfreeco/swift-clocks\n1.0.5"]
"https://github.com/pointfreeco/swift-dependencies" -> "https://github.com/pointfreeco/swift-clocks"
"https://github.com/pointfreeco/swift-clocks" -> "https://github.com/pointfreeco/swift-concurrency-extras"
"https://github.com/pointfreeco/swift-clocks" -> "https://github.com/pointfreeco/xctest-dynamic-overlay"
"https://github.com/pointfreeco/swift-dependencies" -> "https://github.com/pointfreeco/swift-concurrency-extras"
"https://github.com/pointfreeco/swift-dependencies" -> "https://github.com/pointfreeco/xctest-dynamic-overlay"
"https://github.com/pointfreeco/swift-dependencies" -> "https://github.com/swiftlang/swift-syntax"
"https://github.com/pointfreeco/swift-identified-collections" [label="swift-identified-collections\nhttps://github.com/pointfreeco/swift-identified-collections\n1.1.0"]
"https://github.com/pointfreeco/swift-composable-architecture.git" -> "https://github.com/pointfreeco/swift-identified-collections"
"https://github.com/pointfreeco/swift-identified-collections" -> "https://github.com/apple/swift-collections"
"https://github.com/pointfreeco/swift-navigation" [label="swift-navigation\nhttps://github.com/pointfreeco/swift-navigation\n2.2.1"]
"https://github.com/pointfreeco/swift-composable-architecture.git" -> "https://github.com/pointfreeco/swift-navigation"
"https://github.com/pointfreeco/swift-navigation" -> "https://github.com/apple/swift-collections"
"https://github.com/pointfreeco/swift-navigation" -> "https://github.com/pointfreeco/swift-case-paths"
"https://github.com/pointfreeco/swift-navigation" -> "https://github.com/pointfreeco/swift-concurrency-extras"
"https://github.com/pointfreeco/swift-navigation" -> "https://github.com/pointfreeco/swift-custom-dump"
"https://github.com/pointfreeco/swift-perception" [label="swift-perception\nhttps://github.com/pointfreeco/swift-perception\n1.3.5"]
"https://github.com/pointfreeco/swift-navigation" -> "https://github.com/pointfreeco/swift-perception"
"https://github.com/pointfreeco/swift-perception" -> "https://github.com/swiftlang/swift-syntax"
"https://github.com/pointfreeco/swift-perception" -> "https://github.com/pointfreeco/xctest-dynamic-overlay"
"https://github.com/pointfreeco/swift-navigation" -> "https://github.com/pointfreeco/xctest-dynamic-overlay"
"https://github.com/pointfreeco/swift-composable-architecture.git" -> "https://github.com/pointfreeco/swift-perception"
"https://github.com/pointfreeco/swift-composable-architecture.git" -> "https://github.com/pointfreeco/xctest-dynamic-overlay"
"https://github.com/pointfreeco/swift-composable-architecture.git" -> "https://github.com/swiftlang/swift-syntax"
}
```
Then paste the code into Graphviz Online, and you will see a visual representation of your dependency graph. In the example below, I made a Swift Package with one dependency: "swift-composable-architecture". As you can see, TCA has **many** transitive dependencies. The graph is invaluable for understanding all the dependencies and how they interact with each other.
![A dependency graph of many modules in rectangles, with arrows pointing to their dependencies, represented by other rectangles.]()
### Converting to Mermaid
Mermaid is a lot like dot. It's a textual way of representing graphs. It's extremely popular in many places across the internet. Most notably, the GitHub markdown parser has built in support for Mermaid.
Unfortunately the Swift package CLI doesn't support Mermaid directly, and I haven't found an easy tool to convert dot to Mermaid. However, LLMs are surprisingly good at converting from dot to mermaid. Just say something like "Please convert this dot code into Mermaid.js" and then paste in the dot code. This should produce mermaid code like the following:
```mermaid
graph TD
A["spm_adddependencies_cli unspecified"]
B["swift-composable-architecture 1.15.0"]
C["swift-collections 1.1.4"]
D["combine-schedulers 1.0.2"]
E["swift-concurrency-extras 1.2.0"]
F["xctest-dynamic-overlay 1.4.2"]
G["swift-case-paths 1.5.6"]
H["swift-syntax 600.0.1"]
I["swift-custom-dump 1.3.3"]
J["swift-dependencies 1.4.1"]
K["swift-clocks 1.0.5"]
L["swift-identified-collections 1.1.0"]
M["swift-navigation 2.2.1"]
N["swift-perception 1.3.5"]
A --> B
B --> C
B --> D
D --> E
D --> F
B --> G
G --> H
G --> F
B --> E
B --> I
I --> F
B --> J
J --> D
J --> K
K --> E
K --> F
J --> E
J --> F
J --> H
B --> L
L --> C
B --> M
M --> C
M --> G
M --> E
M --> I
M --> N
N --> H
N --> F
M --> F
B --> N
B --> F
B --> H
```
To render the Mermaid code, you can install Mermaid on your system, or you can use an online tool like [Mermaid.live](https://mermaid.live/).
## A Better Solution?
These solutions are okay, but let's look at what could be a better solution. [Simon B. Støvring](https://simonbs.dev/) created a tool called [dependency-graph](https://swiftpackageindex.com/simonbs/dependency-graph). This is a command line tool that can read your project (either a Swift Package or an Xcode project 🚀), and output a dependency graph. It supports multiple graph syntaxes including dot, Mermaid, and something called d2. It can also filter out targets so that it only shows a dependency graph of the packages. It comes with really good documentation with installation and usage instructions.
Unfortunately, so far in my testing, I wasn't able to get it to output any graph. Instead I get a segment fault error. I'll update this blog post if I manage to get it working. It appears to be a [known issue](https://github.com/simonbs/dependency-graph/issues/25). If you know of how to resolve this, please message me on [Mastodon](https://iosdev.space/@dandylyons).
## Conclusion
By visualizing your dependency graph, you can make your code base far easier to understand. Today, we learned various solutions to tackle various parts of this problem, including
- Viewing Dependency Graph Insights on GitHub
- Downloading an SBOM from GitHub
- Calculating a dependency graph using `swift package show-dependencies`
- Rendering a dependency graph using Mermaid and dot
I hope that this guide has been helpful to you for understanding the complex web of dependencies in your codebase. Thank you for reading.
# Abstractions Increase Complexity: Here's Why That's Not A Bad Thing
I'm starting to see a pattern that seems to replay again and again. A shiny new technology comes out that solves a problem. A bunch of developers flock to it, evangelizing it to everyone else. Eventually the tech disappoints. The developers complain that the new solution is so complicated, and they long for the next shiny new thing.
Surely this pattern has existed for a long time, and will continue to repeat. But why does it happen? I think it's because we have fallen for a fallacy. The fallacy is this:
> X technology will make things simpler.
It won't. It doesn't. That complexity still exists. The only difference is you are not handling it anymore. Now that technology is handling it. **The complexity is not eliminated. The complexity is delegated.**
The word for this is *abstraction*.
## What Are Abstractions?
How do you store a list of values? You use an array. That's an abstraction.
How do you implement an array? You could use a linked list. That's another abstraction. That's an abstraction.
How do you implement a linked list? Well you're going to need pointers.
How do you implement pointers? Well a pointer is just a number pointing to a position in memory?
As we can see above, abstractions do not eliminate complexity. They don't even reduce complexity. In fact, **abstractions actually always increase complexity**.
## Why Do We Use Abstractions?
So why do we use abstractions then? Because abstractions **delegate** complexity. This is what makes abstractions so powerful.
If you want to store a list of values, you just use an array. You don't need to think about linked lists. You can just use the array type provided to you by a library. You have delegated away that complexity to something else. This now frees you to tackle larger, more complex problems.
## The Problem With Abstractions
But what happens if the problem isn't really solved? Now you have to solve the problem. Except now the problem is bigger and more complex than it was before.
Now you have to handle the complexity of the original problem **plus** the extra complexity of the abstraction!
Each abstraction can fail in at least two ways:
1. The abstraction can be broken, not fulfilling what it promised to do.
2. The abstraction can "leak", meaning it doesn't actually hide the complexity.
Even worse, the [Law of Leaky Abstractions](https://www.laws-of-software.com//laws/leaky-astractions/) essentially says that every abstraction will leak.
>All non-trivial abstractions, to some degree, are leaky.
>
>-- Joel Spolsky, 2002
## Abstractions: Can't Live With 'em, Can't Live Without 'em
Well that settles it. Let's get rid of all abstractions. Keep things simple.
If that's your attitude, then good luck.
No one truly gets rid of all abstractions. Even by using a programming language you are already using an abstraction. You're not writing assembly. You're certainly not writing machine code.
If you want to solve big problems, then that requires big complexity. And if you want to handle that complexity, you're going to need to delegate some of it with abstractions.
## The Path Forward
Understanding these principles doesn't mean we should avoid abstractions or new technologies. Instead, it calls for a more nuanced approach:
1. **Thoughtful Adoption**: Carefully evaluate new tools and abstractions. Consider their long-term implications, not just short-term gains. Be aware that adding layers of abstraction may make individual components simpler, but always increase overall system complexity.
2. **Deep Understanding**: Strive to understand the layers beneath your abstractions. This knowledge is invaluable when abstractions leak. When[^1] issues arise, be prepared to dive into the layers of abstraction to identify root causes.
3. **Balanced Approach**: Use abstractions to manage complexity, but be prepared to handle the complexity they can't fully hide.
4. **Continuous Learning**: Stay curious about both high-level abstractions and low-level details in your field. Recognize that mastering a new abstraction is an investment. It may slow you down initially before it speeds you up.
[^1]: not if
## Escaping Abstraction Hell
So has your heart been broken by yet another framework with broken promises? Fret not. It's all a part of the process. Find another way to manage that complexity. Consider these options:
1. **Eliminate**: Perhaps you don't need this abstraction. Consider removing it.
2. **Delegate**: Perhaps you should replace your abstraction with a better fit.
3. **Incorporate**: Perhaps your should add a new abstraction alongside your current abstractions.
## Conclusion
Don't be afraid of complexity. Embrace it. Find the right abstractions that you are comfortable using and discard the abstractions that aren't up to the task. You can handle it.
# Differentiating Parameterized Tests in Swift Testing
# Differentiating Parameterized Tests in Swift Testing
Swift Testing is a fantastic addition to the Swift ecosystem. They are concise and easy to understand. Parameterized tests are one of the best features of Swift Testing, but sometimes the framework needs a bit more information in order to work properly. Let's dig in.
## What Are Parameterized Tests?
Parameterized tests are a feature that makes it easy to reuse testing logic across multiple cases of data. To see why that would be valuable let's look at Swift Testing's predecessor, XCTest.
### What's the Problem?
XCTest and other testing frameworks make it difficult to reuse testing code. Because of this, many test suites are filled with tests that are essentially identical. This increases the burden of maintaining and updating tests.
```swift
import XCTest
func validateEmail(_ string: String) -> Bool {
// Check if the string is empty or too short to be a valid email
guard string.count >= 3 else { return false }
// Check if '@' exists and is not at the beginning or end
guard let atIndex = string.firstIndex(of: "@"),
atIndex != string.startIndex,
atIndex != string.index(before: string.endIndex) else {
return false
}
// Split the string into parts before and after '@'
let beforeAt = string[..
print(slice) // Output: [20, 30, 40]
```
Make sure you read [Sundell's article](https://www.swiftbysundell.com/articles/slicing-swift-collections/) on slicing!
## Benefits Over Arrays:
- **Memory Efficient**: Ranges don't store the values they represent, they just define the bounds.
- **Performance**: Faster when iterating over numbers or intervals since there's no need to allocate memory for an entire sequence.
- Use a **range** when you need to express a numeric interval without storing values in memory.
- Arrays should be used when the actual values need to be accessed or manipulated.
## Conclusion
Ranges are a core part of Swift, used for efficient iteration, pattern matching, and controlling bounds in a concise and readable way.
# Swift 6's New @retroactive Attribute
Swift 6.0 introduced the `@retroactive` attribute to address a specific issue with protocol conformances. Here's what you need to know:
## The Problem
Suppose you are using a type from an external library and realize that the type does not conform to a protocol such as `Codable`. You might be tempted to add your own conformance.
```swift
import ExternalLibrary
extension ExternalType: Codable {
// implementation here
}
```
However, doing this can be quite problematic. What happens if the library owner later adds their own conformance? Which code will execute? Your conformance or their conformance? The answer is that the behavior will be undefined at runtime, since we don't know which conformance will "win". Even worse, this same problem will propagate to every library that imports your library.[^1]
[^1]: There are a few exceptions to the this which you can find [here](https://github.com/swiftlang/swift-evolution/blob/main/proposals/0364-retroactive-conformance-warning.md#detailed-design) and [here](https://forums.swift.org/t/amendment-se-0364-allow-same-package-conformances/71877).
## Introducing `@retroactive`
To combat this problem, Swift 6.0 now emits a warning any time you retroactively add a conformance to an external type. However, there are some scenarios where it might be best to extend external types, despite this risk.
So, the `@retroactive` attribute allows you to explicitly declare that you are intentionally adding a conformance that might conflict with future updates to the original module.
## When to Use It
**⚠️ You probably shouldn't use `@retroactive`.**
Consider it a code smell.
If you **must** use it, then be sure to check every time you update your dependency to a new version. If they have added the conformance themselves, then this will create a conflict.
If you use `@retroactive`, you are, in fact, explicitly declaring that you acknowledge the risk and are willing to take responsibility for potential future conflicts.
## How to Use It
```swift
import ExternalModule
extension ExternalType: @retroactive ExternalProtocol {
// Implementation here
}
```
## Alternative (for pre-Swift 6)
If you need to support older Swift language modes, you can silence the warning by fully qualifying the types:
```swift
extension Module.ExternalType: OtherModule.ExternalProtocol {
// Implementation here
}
```
## Conclusion
Remember, while `@retroactive` provides a solution, it's best to avoid adding conformances to external types and protocols whenever possible to maintain better compatibility and reduce potential conflicts.
## Recommended Reading
- Read the full Swift Evolution proposal for more [info](https://github.com/swiftlang/swift-evolution/blob/main/proposals/0364-retroactive-conformance-warning.md).
- [Extensions in Swift: How and when to use them - SwiftLee](https://www.avanderlee.com/swift/extensions/)
# Demystifying Modern macOS Development
## Introduction
For many years Apple, arguably left the Mac to languish for years while it focused on iOS and the iPhone. The Mac repeatedly got features years later than its mobile cousins, and the hardware was often behind and underpowered. But now, Mac app development is currently in the best state that it has been in a very long time, thanks to three major developments:
1. Apple released [Catalyst](https://developer.apple.com/mac-catalyst/), which translates iPad apps into native macOS apps.
2. SwiftUI's _learn once, apply anywhere_ design has made it dramatically easier to share code between macOS and iOS
3. Apple silicon allows us to run iOS apps natively on the Mac without even translating.
The good news is that we've never had so many powerful, first-party supported ways to develop Mac apps. **The not so good news is that it's never been so confusing.** Today we will dive into the subtle differences between each of these approaches.
## Terminology
Let's briefly revisit some terms so that we can understand some of the differences between each of these approaches.
- **Devices**: Here we'll just focus on iPhone, iPad, and Mac
- **OS**: These are the operating systems. Let's focus on **iOS** and **macOS**.
- **UI Framework**: For a long time, there were basically two frameworks to be concerned with:
- **AppKit**: for macOS and macs
- **UIKit**: for iOS and iPhones and iPads[^2]
- **SDK**: Software Developer Kit. These are the tools that we use to build our apps.
- **Architecture**: Some of these devices have processors that are so different that the software is incompatible with each other. The software must be specifically compiled for the correct architecture. In our current context, there's really just 2 architectures that we are concerned with:
- **Intel x86**: Older macs that run on Intel processors
- **Apple Silicon**: newer macs, and basically all of Apple's mobile devices.
- **UI/UX Paradigms**: We would love to have a solution that can automatically port our code from one platform to another, but this is only solving half the problem. Macs and iPads are not only different devices and OS's. **Macs and iPads are entirely different UX paradigms.** A Mac is a traditional desktop with a mouse and keyboard. But an iPad, is a touch screen device, with an accelerometer, and GPS, and camera, etc. The point is **these are very different devices with different user expectations.**
But as we'll see, things started to get even more complicated...
[^2]: In 2019, Apple split iPadOS into its own operating system starting with iPadOS 13. However, this difference is more of a marketing difference than anything else. iPadOS is effectively the same OS as iOS, just running on an iPad, and in fact, in your actual code you will check for `iOS`, not for iPadOS. So in order to reduce complexity, in this article we'll just refer to iOS and that will mean both iPhone and iPad.
## Cross Platform Confusion
For many years, AppKit was effectively the only option available to write Mac apps. Some of AppKit's API's are verbose and don't feel very "modern". But don't let that fool you. AppKit is a very full-featured, robust framework. It is extremely, flexible and powerful. Unfortunately, it is very difficult to make cross-platform apps with AppKit. If you're going to put all that effort into creating an app, wouldn't you want it to be available on as many platforms as possible? Today's customer's expect apps to be ubiquitous, available on practically any platform. Furthermore, users expect each platform to be at full feature parity. This is quite difficult to achieve in AppKit, since most AppKit code cannot be easily ported to other platforms.
## iPad Apps Translated to macOS Using Catalyst
Apple realized that there are far more iOS developers, than macOS developers, so they created **Catalyst** to port to macOS. Catalyst is specifically for porting **iPad** apps to **Mac**. This means that the same iPad app can run on 2 OS's (macOS and iOS), at least 2 devices (iPad and Mac), 2 architectures (Intel and Apple Silicon), in 2 different UI paradigms (touch-first and Desktop), but they are built with one SDK (iOS).
## SwiftUI Apps Running Natively on macOS
In 2019, the same year that Apple announced Catalyst, they also announced SwiftUI. For a long time, macOS apps must be written in AppKit, and iOS apps must be written in UIKit, but now they could be written with the same framework: SwiftUI. This means much of the same code can be used on both platforms, but not everything. Many methods are only available on one platform or the other.
This is why Apple rejects the idea _write once, run anywhere_ and instead describes SwiftUI as _learn once, apply anywhere_. Now this means that the same code[^3] can be run on basically **all of Apple's devices**[^4], basically **all of Apple's OS's**, 2 architectures (Intel and Apple Silicon), in **all of Apple's available UI paradigms** (touch, desktop, watch etc.) and you can choose which SDK you would like to build with.
[^3]: or rather **almost** the same code
[^4]: iPhone, iPad, Apple Watch, Mac, Apple TV, Vision Pro etc.
## SDK vs. OS
For a long time the SDK essentially mapped one-to-one to the OS. Building on the iOS SDK created a target that could run on the iOS OS, and only the iOS OS. This is no longer the case. Now you can build a target for the macOS OS using either SDK.
For example, suppose you want to use the following code on a Mac app. Will it work?
```swift
struct ContentView: View {
var body: some View {
NavigationView {
Text("Hello, iOS!")
.navigationTitle("My App")
.navigationBarTitleDisplayMode(.inline)
}
}
}
```
Well the answer is complicated. All of the code above works on macOS except for `navigationBarTitleDisplayMode`. As you can see in the [docs](https://developer.apple.com/documentation/SwiftUI/View/navigationBarTitleDisplayMode(_:)), it is not available on macOS, but it **is** available on Mac Catalyst. So will `navigationBarTitleDisplayMode` work on macOS? The answer is yes, but only when using Mac Catalyst.
To demonstrate my point, open an Xcode project with a multiplatform target. Click the project in the left sidebar. Now select the target. Now select the "General" tab, and view the "Supported Destinations" section. As you can see in the picture below there are multiple Mac destinations and they have different SDKs.

| Destination | SDK |
| ----------------------- | ----- |
| Mac | macOS |
| Mac (Mac Catalyst) | iOS |
| Mac (Designed for iPad) | iOS |
The SDK is very important because it determines which types, methods, etc. your code has access to. As we can see above, Mac Catalyst uses the iOS SDK, which means it has access to the same methods that any iOS app has.
## What are Multiplatform Apps in Xcode?
Quick aside: What are [Multiplatform apps](https://developer.apple.com/documentation/xcode/configuring-a-multiplatform-app-target) in Xcode?
In Xcode 14, Xcode added the ability to share code for apps across multiple platforms in a single project, and in a single target! iOS, iPadOS, macOS, visionOS, and tvOS apps can all share a single target![^5] This is a massive quality of life improvement since it dramatically reduces redundant configuration across multiple targets.
[^5]: Sorry, watchOS apps remain in a separate target.
But you should know that it adds an extra layer of complexity. Just like before, the shared **code** is being used on multiple devices, OSs, and SDKs. But now your **target** is also being used on multiple devices, OSs, and SDKs. Effectively, this means that the multiplatform target settings will resolve to different concrete target settings depending on which platform the target is compiled for.
Be sure to check out WWDC 2022's video [Use Xcode to develop a multiplatform app](https://developer.apple.com/videos/play/wwdc2022/110371/) for more info.
## Compared Side-by Side
| **Aspect** | **Native macOS App (SwiftUI)** | **UIKit App on macOS (Catalyst)** | **SwiftUI Mac App (Designed for iPad)** |
| -------------------------- | ------------------------------ | ------------------------------------------------------ | ------------------------------------------------------------------ |
| **Operating System** | macOS | macOS (via Catalyst) | macOS (iPad app running on macOS) |
| **SDK Used** | macOS SDK | iOS SDK with Catalyst support | iOS SDK |
| **Primary Framework** | SwiftUI (with possible AppKit) | UIKit (with Catalyst)[^1] | SwiftUI |
| **Target Device** | Mac (desktop) | Mac (originally iPad) | Mac (originally iPad) |
| **Platform-Specific APIs** | Full access to macOS APIs | Limited macOS API access via Catalyst | Limited macOS API access |
| **Device Input Method** | Mouse/Trackpad, Keyboard | Mouse/Trackpad, Keyboard (with some touch adaptations) | Mouse/Trackpad, Keyboard (designed for touch but adapted) |
| **Use Case** | Full-featured macOS apps | Porting **existing** iPad apps to macOS | Bringing iPad apps to macOS with minimal changes |
[^1]: It is also possible to convert an SwiftUI iOS app to macOS using Catalyst, however, this approach tends to be less common since it's usually easier to run the same SwiftUI code directly in a macOS app (with minor adjustments).
## Determining Which Environment You Are Running In
Swift provides us with a number of tools to
- `#if os()`: This name is unfortunately deceptive. In my testing. `#if os()` actually checks the SDK, **not** the OS.
- `#if os(iOS)`: For example a Mac Catalyst app will execute `#if os(iOS)`, even if running on macOS.
- `#if os(macOS)`: And this will **only** execute on a Mac app if it is built with the Mac SDK.
- `#if canImport()`: We can use this compiler directive to check for UIKit or AppKit.
- `#if canImport(AppKit)`: This will work for native Mac Apps.
- `#if canImport(UIKit)`: This will work for Mac (Designed for iPad) apps
- **What about Mac Catalyst?**: Apparently the answer is both.
- `#if targetEnvironment(macCatalyst)`: This directive can be very helpful when you need code to exclusively run on the Mac Catalyst version.
## Introducing MacEnvironments: A Reference App
Is your brain melting yet? Fret not. I've created [MacEnvironments](https://github.com/DandyLyons/MacEnvironments). It's a helpful Xcode project designed to make it easy to reference which code will execute on which Mac environment. It has 3 targets: **Mac**, **MacCatalyst** and **MacDesignedForiPad**. There's basically only one file you need to care about: `MacEnvironmentsApp.swift`. This is the entry point to the app. It only does one thing: it runs a bunch of `.onAppear()` code blocks. These blocks are surrounded in environment checks such as `#if os(iOS)` and many more. When you build and run the app, Xcode will display a helpful purple message right next to each block of code that ran, and it wil **not** display a message next to the blocks that did not run. The results will probably surprise you!

_Here's an example of what **MacEnvironments** looks like when you build it for Mac Catalyst._
I want to give a big thank you to PointFree for releasing IssueReporting. This is the powerful library that powers the purple runtime warnings. Make sure you check it out [here](https://github.com/pointfreeco/swift-issue-reporting).
## Conclusion
Choosing the right approach for developing a Mac app depends on your project requirements, target audience, and development resources. Whether you opt for a native SwiftUI app, leverage Catalyst, or port a SwiftUI app designed for iPad, understanding the strengths and challenges of each method is key to creating a successful Mac application.
# Benchmarking in Swift with swift-collections-benchmark
There is an age-old adage of programming which states *"Make it work, then make it right, then make it fast."* Today we will be focusing on how to *make it fast*, with the help of a valuable technique called Benchmarking.
When developing software, especially when working with algorithms and data structures, performance is often a key concern. You may have experienced a piece of code that behaves well in your tests, but when it's exposed to real-world data, performance degrades. This is where **benchmarking** comes in. Benchmarking allows developers to measure how long a piece of code takes to run, helping to identify bottlenecks and areas for optimization.
In this post, we'll explore benchmarking in Swift using the `swift-collections-benchmark` package, comparing it with unit testing, snapshot testing, and performance testing. Then, we'll walk through an example comparing the performance of using an `Array` and a `Set` in Swift.
>It's important to note that Swift.org recently announced a new [Benchmark Package](https://www.swift.org/blog/benchmarks/). Perhaps that will be the more "modern" approach going forward.
## What is Benchmarking?
Benchmarking measures the performance of a specific piece of code under controlled conditions. It’s not just about whether your code works, but how efficiently it works, particularly when operating on larger datasets.
Benchmarking is somewhat analogous to **snapshot testing**, but for performance. Snapshot tests capture the output of a UI component and verify that it hasn't changed. Similarly, Benchmark tests capture the performance characteristics of your code and help ensure that performance doesn't degrade over time. It also helps identify areas where performance could be improved.
### Comparison to Other Testing Types
- **Unit Testing**: This checks if a small, isolated piece of code produces the correct result. It’s focused on correct behavior rather than performance.
- **Snapshot Testing**: This captures a "snapshot" of how a piece of code (often UI code) looks or behaves at a point in time, and tests future runs against that snapshot to detect changes. Again, it’s about correctness but not performance.
- **Performance Testing**: This is about analyzing the exact speed or memory usage.
- **Benchmark Testing**:
- Like **Performance Testing**, Benchmark Testing analyzes speed and memory usage.[^2]
- And like **Snapshot Testing**, Benchmark Testing compares performance results to prior tests or established baselines in order to identify performance improvements or regressions as the codebase evolves over time.
[^2]: Benchmark Testing is actually a subset of Performance Testing, not a separate category.
| What We're Testing | Single Test (Focus on Individual Case) | Comparison Against Prior Runs (Regression) |
| --------------- | -------------------------------------- | ------------------------------------------ |
| **Behavior** | Unit Testing | Snapshot Testing |
| **Performance** | Performance Testing | Benchmark Testing |
[^1]
[^1]: I'm certain that there are subtle nuances to this table which are missing. The purpose of this table is not to be perfectly academically accurate. The purpose is to compare Benchmark Testing to other forms of testing, which engineers are likely already familiar with, so that they can orient themselves, and understand the purpose of Benchmark Testing.
## Benchmarking with `swift-collections-benchmark`
In 2021, Swift.org announced [Swift Collections](https://www.swift.org/blog/swift-collections/), an open-sourced package with more advanced data structures than those provided by the standard library. In order to develop Swift Collections, they developed [swift-collections-benchmark](https://github.com/apple/swift-collections-benchmark). This package is a great tool for benchmarking in Swift, particularly for comparing collections and algorithms. It provides a flexible framework for running performance tests and collecting detailed data on how different implementations behave under various conditions.
To show how this works, let’s dive into a simple example comparing two common collection types in Swift: `Array` and `Set`. Remember that an `Array` is an ordered `Collection` of values. A `Set` is similar to an `Array` but with two major differences: it is unordered, and it cannot contain duplicate values. Let's find out which has better performance...
## Example: Array vs Set Performance
### Problem Setup
Suppose we want to decide if we should use an `Array` or a `Set`. We're currently using an `Array` but we suspect a `Set might be faster. Let's test the performance of both across our use cases to see which is faster.
### Benchmarking the Performance
To benchmark these two implementations, we’ll use the `swift-collections-benchmark` package to compare how long each function takes to execute.
#### Install the `swift-collections-benchmark` Package
If you haven't already, add the `swift-collections-benchmark` package to your project. You can do this via Swift Package Manager by adding the following to your `Package.swift` file:
```swift
dependencies: [
.package(url: "https://github.com/apple/swift-collections-benchmark", from: "1.0.0"),
]
```
Next, lets add the dependency to our target in our Package.swift file:
```swift
.target(
name: "MyBenchmark",
dependencies: [
.product(name: "CollectionsBenchmark", package: "swift-collections-benchmark"),
]),
```
#### Write a Benchmark Test
Here’s how we can use the `swift-collections-benchmark` framework to compare the performance of `containsInArray` and `containsInSet`:
```swift
import CollectionsBenchmark
// Create a benchmark test suite
var benchmark = Benchmark(title: "ArrayVsSet Benchmark")
// Add your tests here
benchmark.addSimple(
title: "Array init",
input: Int.self // 👈🏼 input type
) { input in
blackHole(Array(0.. init",
input: Int.self
) { input in
blackHole(Set(0.. init
Set init
Array append
Array insert at 0
Set insert
Array removeLast
Array removeFirst
Set remove
Output file: /Users/daniellyons/Developer/My Swift Packages/ArrayVsSet/results
Appending to existing data (if any) for these tasks/sizes.
Collecting data:
1.2.4...8...16...32...64...128...256...512...1k...2k...4k...8k...16k...32k...64k...128k...256k...512k...1M -- 40.5s
1.2.4...8...16...32...64...128...256...512...1k...2k...4k...8k...16k...32k...64k...128k...256k...512k...1M -- 39.6s
1.2.4...8...16...32...64...128...256...512...1k...2k...4k...8k...16k...32k...64k...128k...256k...512k...1M -- 40.8s
Finished in 121s
```
Just like the console says, there should be a new file named `results` with the results of the benchmark tests. If we open the file, we can see that it's a JSON file. This file will also be persisted across tests, so that you can compare current results to past results. This empowers you to catch performance regressions. Now, let's render these results into a format that is more useful.
```zsh
swift run -c release ArrayVsSetBenchmark render results chart.png
```
Using the `render` command from `CollectionsBenchmark` we now have a new `chart.png` file that can visually show us our results. It should look something like this:
![A line chart showing the performance differences between an `Array` and a `Set`.]()
On the x axis we can see the count of how many operations were performed by the framework. They increase exponentially as you move to the right. On the y axis we see the amount of time it took for those operations to be performed. They also increase exponentially as you move from the bottom to the top. Great! So what does all this mean?
As you can see the performance characteristics of a `Set` and an `Array` are extremely similar. In fact, they are so similar that you probably don't need to care about the performance differences between them. The majority of the lines on the graph are roughly flat. With this scale, that means that they are operating at an O(n) complexity.
But there are two very big exceptions: "Array removeFirst" and "Array insert at 0". Both of these tests have a noticeably steeper slope. Given the steepness of the slope it appears that they are running at O(n) time complexity. In other words, the increase in time is directly proportional to the amount of items in the operation. If we look at the documentation for these two methods, we will see that they are in fact expected to run at O(n) time complexity.[^3]
[^3]: Strangely, it seems that `array.insert(num, at: 0)` actually performs faster than the other insertion methods until we reach about 2,000 items. Then it performs exponentially slower.
From our analysis, we should be able to learn this: An `Array` and a `Set` have remarkably similar performance except for some key use cases. If your use cases is one of those use cases, and particularly if you are dealing with large data sets, you should perhaps consider switching from an `Array` to a `Set`.
## Conclusion
Benchmarking is an essential tool for ensuring that your code not only works, but works efficiently. While unit tests ensure correctness, benchmarking ensures performance remains consistent as your code evolves. Using the `swift-collections-benchmark` package makes it easy to measure and compare the performance of different implementations, as we demonstrated with the `Array` vs `Set` example.
By adding benchmark tests to your development workflow, you can catch potential performance regressions early and make data-driven decisions about how to optimize your code. If you would like to see the rest of the code I used to make this article to see [ArrayVsSet](https://github.com/DandyLyons/ArrayVsSet) on GitHub.
Have any questions? See any mistakes or areas that I could improve this article? Please message me on [Mastodon](https://iosdev.space/@dandylyons).
# Using Custom Components in Swift's Regex
In our [last article]({{< ref "the-many-faces-of-swifts-regex" >}}) we learned about Swift's `Regex` type and the various different ways to create them. Today we're going to dive a little deeper into one of those methods. We'll be building a custom `RegexComponent` using the [CustomConsumingRegexComponent](https://developer.apple.com/documentation/swift/customconsumingregexcomponent) protocol.
For a quick refresher, remember that we can create a custom parser using the `RegexBuilder` DSL like this:
```swift
import RegexBuilder
Regex {
Capture {
Repeat(count: 3) {
One(.digit)
}
}
"-"
Capture {
Repeat(count: 3) {
One(.digit)
}
}
"-"
Capture {
Repeat(count: 4) {
One(.digit)
}
}
}
```
Don't forget that we can use many built-in parsers provided by `Foundation` like this:
```swift
let usdRegex = Regex {
Capture(.currency(code: "USD").sign(strategy: .accounting))
}
let dateRegex = Regex {
Capture(
.date(
.numeric,
locale: .autoupdatingCurrent,
timeZone: .autoupdatingCurrent,
calendar: .autoupdatingCurrent
)
)
}
let intRegex = Regex {
Capture(.localizedInteger(locale: .autoupdatingCurrent))
}
```
## Using `NSDataDetector` Inside a Swift `Regex`
Not only can you use `Foundation`'s parsers, you can also create your own custom parsers, through the [CustomConsumingRegexComponent](https://developer.apple.com/documentation/swift/customconsumingregexcomponent) protocol. Let's create a new custom parser that uses Apple's `NSDataDetector` class.
First, let's get a working example of our `NSDataDetector` to detect phone numbers:
```swift
import Foundation
let types: NSTextCheckingResult.CheckingType = [.phoneNumber]
let detector = try NSDataDetector(types: types.rawValue)
let input = "(789) 555-1234"
let swiftRange = input.startIndex..
) throws -> (upperBound: String.Index, output: String)? {
// implementation goes here...
}
}
```
## CustomConsumingRegexComponent
So now let's plug in our earlier implementation:
```swift
public struct PhoneNumberDataDetector: CustomConsumingRegexComponent {
public typealias RegexOutput = String
public func consuming(
_ input: String,
startingAt index: String.Index,
in bounds: Range
) throws -> (upperBound: String.Index, output: String)? {
var result: (upperBound: String.Index, output: String)?
let types: NSTextCheckingResult.CheckingType = [.phoneNumber]
let detector = try NSDataDetector(types: types.rawValue)
let swiftRange = index..## To capture or not to capture?
>
>Brief aside, which will be important later: let's talk about the differences between detection, validation and parsing. **Detection** is finding if something is there (and where it is). For example, _is there a phone number in this string?_ **Validation** is determining if the string is a valid form of that data type. For example, _is 12-3456 a valid phone number?_ Finally, **parsing** is reading a string, and interpreting it as structured data. For example, _what is the area code, country code, and main part of the phone number?_ -->
However, regular expressions can also be notoriously difficult to use due to:
1. a syntax that is extremely difficult to read
2. every programming language has their own "flavor" of regular expressions which has its own subtle syntax and differences of capabilities
So thankfully Swift's native Regex holds some huge quality of life improvements including:
1. compile-time type checking
2. an easier to read DSL
3. a literal syntax that is very similar to Perl, Python, Ruby and Java
Long story short, Swift's Regex makes regular expressions easier and safer to use, while not sacrificing on power. However, there's one issue left. There are many different methods to declare regular expressions. Each, offers its own set of tradeoffs, and each has slightly different syntax considerations. These differences can make it harder to understand regular expressions in different contexts. But if you understand each method, and their tradeoffs, then they can make working with regular expressions so much easier!
## The Many Ways to Declare Strings
Strings? I thought we were talking about regular expressions.
Yes, we are. But strings are intimately connected to regular expressions, and like `Regex` there are multiple ways to declare a String.
1. String literals
2. Raw string literal
3. String initializer
### String Literal
```swift
let string = "string"
let name = "Daniel"
let hello = "Hello \(name)" // Hello Daniel
let multilineString = """
This is a string
across
multiple lines.
"""
```
### Raw string literal
As you can see in the code above, [string interpolation](https://www.avanderlee.com/swift/string-interpolation/) allows us to input variables into our strings. To do this we must use `\` to escape our string. However there are some times when we want to be able to use characters like `\` and `"` in our strings. How do we do this? Enter raw strings:
```swift
let rawString = #"This raw string can contain \ and " without escaping"#
let multilineRawString = #"""
This is a multiline
raw string
with \ and "
"""#
```
### String initializers
String is a struct, and so it can be initialized just like any other struct.
```swift
let string = String("string")
```
You won't often need to use a `String` initializer directly, but it can be handy for some use cases.
## The Many Ways to Declare Regular Expressions
Now that we have an overview of the many ways to declare `String`s, we can look at `Regex` and see the similarities.
Swift has many ways to declare regular expressions. Here are some of the most common:
1. `NSRegularExpression`: the "legacy" option
2. `Regex` literals
3. `Regex` extended delimiter literals
4. `Regex` from runtime string
5. `Regex` from `RegexBuilder` DSL
### NSRegularExpression
This Foundation class dates all the way back to Objective-C and macOS 10.7. It is very powerful, and you will find a lot of code examples using it. However it was designed for Objective-C and therefore it's not very "swifty". For example, it uses `NSRange` instead of Swift's native `Range` type, which then means you can't use `Range` literals. In general, there isn't a reason to be using `NSRegularExpression`s today, now that we have `Regex`, but it is important to be aware of it so that you can understand legacy code. Here's an example:
```swift
import Foundation
// Declaration
let pattern = #"(\d{3})-(\d{3})-(\d{4})"#
let regex = try NSRegularExpression(pattern: pattern, options: [])
// Usage
let phoneNumberString = "Call me at 123-456-7890 or 987-654-3210"
let range = NSRange(phoneNumberString.startIndex..., in: phoneNumberString)
let containsPhoneNumber: Bool = regex.firstMatch(in: phoneNumberString, options: [], range: range) != nil
// containsPhoneNumber == true
```
>It's also worth mentioning `NSDataDetector` which is a subclass of `NSRegularExpression`. It has far more accurate capabilities for select data types including phone numbers and emails. NSHipster has a fantastic article about it [here](https://nshipster.com/nsdatadetector/).
### Regex literals
Using `Regex` literals is simple. A literal simply starts and ends with a `/`, just like how a `String` literal starts and ends with `"`. Now, let's look at the legacy method above and see some of it's weaknesses so that we can better understand the problem that Swift's native `Regex` solves.
Notice, the `NSRegularExpression` must be called with `try`. This is because you are passing in a string (`pattern`). The compiler has no way of knowing if this string is a valid regular expression, so it must check at runtime. In other words, if you forget a single character in that string, then the whole thing can break. Now let's look at the same thing with `Regex` literals:
```swift
// Declaration
let regex = /(\d{3})-(\d{3})-(\d{4})/
// Usage
let phoneNumberString = "Call me at 123-456-7890 or 987-654-3210"
let containsPhoneNumber: Bool = phoneNumberString.contains(regex)
// containsPhoneNumber == true
```
Aside from being shorter and easier to read, this code is also safer. Notice how as soon as you write it, the syntax is highlighted! The Swift compiler is checking that the `Regex` is valid at compile time! To prove my point, try deleting one of the `)` characters from the pattern string so that it looks like this:
```swift
let pattern = #"(\d{3}-(\d{3})-(\d{4})"#
```
This is an easy mistake to make, yet this code will happily compile since it is a valid String. The problem won't arise until `NSRegularExpression` errors at runtime. Now try deleting the same character from the `Regex` literal:
```swift
let regex = /(\d{3}-(\d{3})-(\d{4})/
// 🔴 error: cannot parse regular expression: expected ')'
```
Now we immediately get a compile error, and our syntax highlighting clues us into the problem!
### Regex extended delimiter literals
`Regex` literals can use a syntax which is very similar to raw strings:
```swift
let rawString = #"raw\string"#
let regex = #/(\d{3})-(\d{3})-(\d{4})/#
```
The extended delimiter offers a few nice benefits:
1. It will ignore whitespace so that we can structure our code in a more readable format.
2. It allows for comments using `#`.
So our phone number `Regex` can be rewritten like this:
```swift
let regex = #/
(\d{3}) # Capture 3 digits
- # Consume a "-"
(\d{3}) # Capture 3 digis
- # Consume a "-"
(\d{4}) # Capture 4 digits
/#
```
### Regex from runtime string
Compile-time `Regex` is fantastic, but there are still times when runtime `Regex` could be preferable. For example, when we want to dynamically construct `Regex`s.
```swift
var searchString: String // some user inputted string
let regex = try Regex(searchString)
let text = "hello world"
let containsSearchString = searchString.contains(regex)
// containsSearchString == true
```
Since the `Regex` initializer takes a simple `String`, we can dynamically create our regular expression pattern on the fly. This could be used to power a feature where a user would like to configure their search with tags and other features.
### RegexBuilder DSL
Last, but certainly not least. Swift offers a powerful `Regex` DSL (domain-specific language) that is much easier to read and understand. Even better, we can easily convert a `Regex` literal into this DSL. (Note, to use this DSL, we must first import `RegexBuilder`) To do this, in Xcode, right-click any `Regex` literal, and select Refactor -> Convert to Regex Builder. If we do that to our phone number regex we'll get something like this.
```swift
import RegexBuilder
Regex {
Capture {
Repeat(count: 3) {
One(.digit)
}
}
"-"
Capture {
Repeat(count: 3) {
One(.digit)
}
}
"-"
Capture {
Repeat(count: 4) {
One(.digit)
}
}
}
```
What if you're not using Xcode? Try using [SwiftRegex.com](https://www.swiftregex.com). It's a robust Regex playground and it will even convert to the Builder DSL.
As you can see, the syntax is much more readable and it looks a lot like SwiftUI. This is because it's using the same Swift result builder language feature that powers SwiftUI.
`RegexBuilder` can even be mixed and matched with literals.
```swift
Regex {
(\d{3})
"-"
(\d{3})
"-"
Capture {
Repeat(count: 4) {
One(.digit)
}
}
}
.anchorsMatchLineEndings()
```
#### Custom Regex Logic
You may be wondering _If I can automatically convert from Regex literal to RegexBuilder, can I convert back?_ Unfortunately no, and [this Swift Forum thread](https://forums.swift.org/t/any-way-to-get-raw-regex-literal-from-regexbuilder/58327) can give you more context on why. While it is a major bummer, there is actually a very good reason. The Swift Regex literal syntax is only a subset of the full Swift Regex engine. In other words, `RegexBuilder` can do even more than a `Regex` literal.
In particular, `RegexBuilder` allows you to insert your own custom logic into your `RegexBuilder` using [CustomConsumingRegexComponent](https://developer.apple.com/documentation/swift/customconsumingregexcomponent). It also means that you can use Foundation to immediately adopt the complex parsing logic that Apple has been developing for decades!
For more info, make sure you watch [WWDC22 - Swift Regex: Beyond the Basics](https://wwdcnotes.com/documentation/wwdcnotes/wwdc22-110358-swift-regex-beyond-the-basics/).
## Picking the Right Tool for the Job
Swift's `Regex` type elegantly results in code that is safer and easier to read, while also adding more power! It also provides many different options of how to create `Regex`s. For reference we can look at the table below:
| Method | Notes |
| ----------------------------------- | ------------------------------------------------------------------------------------------- |
| `Regex` literals | concise, but esoteric, same syntax as Perl, Python, Ruby, and Java, decades of example code |
| `Regex` extended delimiter literals | more readable |
| `Regex` from runtime strings | dynamic, no type checking |
| `RegexBuilder` DSL | even more readable, but verbose |
I hope that this article has made Swift `Regex`, and regular expressions in general, more approachable. If you'd like to use `Regex` more, then please have a look at [NativeRegexExamples](https://swiftpackageindex.com/DandyLyons/NativeRegexExamples). I created this repository for crowd sourcing regular expression solutions from the Swift community. It includes a robust test suite of each `Regex` example. Together we can learn from each other and develop best practices! Please consider sharing and contributing.
# Using Optionals with SwiftUI Bindings
[Optionals](https://developer.apple.com/documentation/swift/optional) are an invaluable, core feature of Swift, and [Bindings](https://developer.apple.com/documentation/swiftui/binding) are the same for SwiftUI, but unfortunately it can be difficult to get them to play nicely with each other. Bindings are one of the core ways to empower child views to talk to parent views, and they are used throughout the SwiftUI framework. For example all of these core components use Bindings.
```swift
TextField("Last name", text: $person.lastName)
DatePicker("Death date", selection: $person.deathDate)
ColorPicker("Favorite color", selection: $person.favoriteColor)
```
But this gets much more complicated if you need a `Binding` for an `Optional` property. SwiftUI rarely, if ever, provides Views that accept an Optional Binding.
```swift
@Observable class Person {
var lastName: String?
var deathDate: Date?
var favoriteColor: Color?
}
struct PersonForm: View {
@Bindable var person: Person
var body: some View {
Form {
TextField("Last name", text: $person.lastName)
// 🔴 Cannot convert value of type 'Binding' to expected argument type 'Binding'
DatePicker("Death date", selection: $person.deathDate)
// 🔴 Cannot convert value of type 'Binding' to expected argument type 'Binding'
ColorPicker("Favorite color", selection: $person.favoriteColor)
// 🔴 Cannot convert value of type 'Binding' to expected argument type 'Binding'
}
}
}
```
Today we will look at a few potential solutions and strategies:
1. Try removing Optionals if they don't match your use case.
2. Provide a default value for your `Binding`
3. Convert a `Binding` to a `Binding?`
4. Create "Optional" SwiftUI Views
## Removing Optionals
First let's recognize that we are going "against the grain". We are doing something that SwiftUI really wasn't designed for. This doesn't mean that we can't, or we shouldn't do this, but it does mean that it will require extra work. So we should consider if that work is even necessary in the first place. **The best way to solve a problem, is to prevent the problem from existing in the first place.** Do we really need Optionals in our domain? The answer to this question will depend on your specific use case.
In our example, we could simply change all of the properties to be non-Optional and this will immediately remove all the compiler errors. Problem solved. But what if we really need for these values to be Optional? Remember a `String?` can either be a `String` value or it could be `nil`. But a `String` **must** be a `String` value. It **cannot** ever be `nil`. The compiler won't let it.
If your data will never have blank values, then this isn't a problem. But if your data could have blank values, then you must decide what to do with those values. Often, the easiest solution is to provide default values.
```swift
@Observable class Person {
public init(lastName: String?, deathDate: Date?, favoriteColor: Color?) {
self.lastName = lastName ?? ""
self.deathDate = deathDate ?? Date()
self.favoriteColor = favoriteColor ?? Color.accentColor
}
var lastName: String
var deathDate: Date
var favoriteColor: Color
}
```
Here all of the properties are non-Optional, but the initializer can accept Optional values. The initializer will try use the given Optional value, but if there is no value, then it will replace it with a default value.
This approach can be particularly helpful when you are consuming data from other systems that do not have Swift's `Optional` type, and therefore can't guarantee if a value will be present. For example, Apple's Core Data turns almost all properties into Swift Optionals. Also, many Web APIs return a JSON, with keys that may or may not be present.
Remember this principle: **Your View should conform to your model (and not the other way around). And your model should conform to your use case (and not the other way around).** If your model conforms to your view then this will result in code that is error-prone and doesn't make sense. If your model **doesn't** conform to your use case, then your code will solve the wrong problem.
It's also worth noting that `nil` is not the same as "empty" values. An empty string is not the same as a `nil` string.
```swift
let emptyString: String? = ""
let nilString: String? = nil
// nilString != emptyString
```
If you want, you can use both values to represent the same thing, in your model. There's nothing wrong with this approach and many systems have used this strategy for many years. Just be aware that if you use `""` and `nil` to mean the same thing (e.g. both mean that the person doesn't have a last name), then you are creating ambiguity in your code. (Does the person have no last name or is their last name blank? Does the person really have no last name, or did they just forget to fill out that text field?)
For the sake of our example, let's say that our use case warrants `Optional` values. Not every person has a last name, or a death date, or a favorite color. It would not be right to create a model that would force our data to be misaligned with reality. So if our use case calls for an `Optional` then we should use an `Optional` and we should figure out a way to conform our `View` to accept that. Now let's look at some strategies to accomplish that.
## Provide a default value for your `Binding`
For some use cases it might be better and easier to simply provide a default value to our `Binding`. Unfortunately, SwiftUI doesn't have this built in, but it's quite easy to add it with an extension:
```swift
extension Binding {
/// Converts a `Binding` to a `Binding`
///
/// - Parameter defaultValue: the value to return if the `wrappedValue` is `nil`
/// - Returns: A `Binding` of a non-optional value
public func toNonOptional(defaultValue: T) -> Binding where Value == T? {
Binding(
get: { self.wrappedValue ?? defaultValue },
set: { self.wrappedValue = $0 }
)
}
}
```
Then to use it we just do this:
```swift
TextField("Last name", text: $person.lastName.toNonOptional(defaultValue: ""))
DatePicker("Death date", selection: $person.deathDate.toNonOptional(defaultValue: Date()))
ColorPicker("Favorite color", selection: $person.favoriteColor.toNonOptional(defaultValue: .accentColor))
```
This handy extension makes it quite easy to use any optional value as a binding. However, it does not provide any way to represent a `nil` value.
## Convert a `Binding` to a `Binding?`
This one can be really confusing, but it is extremely important to understanding SwiftUI. `Binding` and `Binding?` are not the same. Do you see the difference?
- `Binding`: is a non-Optional `Binding` that is holding onto an `Optional` value. In other words:
- There **is** a `Binding` and there **might** be a `Value`
- `Binding?`: is an `Optional` `Binding` that is holding onto a non-Optional value. In other words:
- There **might** be a `Binding` that is holding onto a `Value` that **must** exist.
Unfortunately, most SwiftUI views want a `Binding` and not a `Binding`. Thankfully, there's a fairly simple solution to this. SwiftUI provides an initializer for `Binding` that can unwrap a `Value`. In other words, it converts a `Binding` to a `Binding?`
```swift
@Observable class Person {
var lastName: String?
var deathDate: Date?
var favoriteColor: Color?
}
struct PersonForm: View {
@Bindable var person: Person
var body: some View {
Form {
if let lastNameBinding: Binding = Binding($person.lastName) {
TextField("Last name", text: lastNameBinding)
}
if let deathDateBinding = Binding($person.deathDate) {
DatePicker("Death date", selection: deathDateBinding)
}
if let favoriteColorBinding = Binding($person.favoriteColor) {
ColorPicker("Favorite color", selection: favoriteColorBinding)
}
}
}
}
```
Now we have safely unwrapped our values, and we have a `Binding?` that can work with our SwiftUI views. We then unwrap our `Binding?` using `if let`. If the `Binding?` has a value, then we display our view, but if it's nil, we simply don't render the view. This approach effectively conforms our View to our model, however it creates new UX problems.
What happens if `lastName` becomes `nil`? Then we lose the `TextField` and we lose any way to edit the value. What if `lastName` has a value but we want to remove that value and turn it into `nil`? Currently our UI doesn't support that. It's not too hard to support all of this, but it does require a lot of boilerplate.
```swift
struct PersonForm: View {
@Bindable var person: Person
var body: some View {
Form {
if let lastNameBinding: Binding = Binding($person.lastName) {
TextField("Last name", text: lastNameBinding)
Button("Remove last name") { person.lastName = nil }
} else {
Button("Add last name") { person.lastName = "" }
}
if let deathDateBinding = Binding($person.deathDate) {
DatePicker("Death date", selection: deathDateBinding)
Button("Remove death date") { person.deathDate = nil }
} else {
Button("Add death date") { person.deathDate = Date() }
}
if let favoriteColorBinding = Binding($person.favoriteColor) {
ColorPicker("Favorite color", selection: favoriteColorBinding)
Button("Remove favorite color") { person.favoriteColor = nil }
} else {
Button("Add favorite color") { person.favoriteColor = Color.accentColor }
}
}
}
}
```
## Create "Optional" SwiftUI Views
To remove boilerplate, we can create reusable Views that actually expect a `Binding`. There are many ways to accomplish this. Here is just one:
```swift
struct OptionalTextField: View {
@Binding var optionalString: String?
let textFieldTitleKey: String
let removeStringTitleKey: String
let addStringTitleKey: String
var body: some View {
if let stringBinding: Binding = Binding($optionalString) {
TextField(textFieldTitleKey, text: stringBinding)
Button(removeStringTitleKey) { optionalString = nil }
} else {
Button(addStringTitleKey) { optionalString = "" }
}
}
}
```
Then we can reuse this view component anywhere that we need a `TextField` for an `Optional`.
```swift
OptionalTextField(
optionalString: $person.lastName,
textFieldTitleKey: "Last name",
removeStringTitleKey: "Remove last name",
addStringTitleKey: "Add last name"
)
```
This approach can be quite great, however, here we lose the ability to use other views as our `TextField` label. These problems are certainly fixable, but to do it in a way that is reusable, yet still flexible requires a highly nuanced approach.
Here is a far more robust solution:
[Github Gist: OptionalTextField.swift](https://gist.github.com/DandyLyons/80312b225934b79fc895cd0b924566a3)
## Conclusion
Today we learned various strategies to using SwiftUI Bindings with Optional values. If I can leave you with one takeaway, I hope it is this. Your model does not need to change to fit SwiftUI. Instead, adapt SwiftUI to meet your needs, and you will surely find that it is more than up to the task.
# Exhaustive Testing Made Easy
Testing is vitally important in virtually any tech stack. That is, unless you want to [shut down 8.5 million computers worldwide](https://en.wikipedia.org/wiki/2024_CrowdStrike_incident). [^1] Testing is more than a tedious chore. It's an automated warning system of current bugs. What is not automated (at least not entirely) is writing the tests. It takes time to write tests, and we have to know what needs to be tested. No matter how well your tests are written, if your tests don't cover a particular situation, then it won't be caught. This means that we need to assert on every value in our code. This is tedious and error-prone.
[^1]: Ok, that jab is not quite fair. Crowdstrike, did have testing, but clearly it wasn't very good.
What if I told you there was a way to test all of your values exhaustively? Today we'll talk about "Exhaustive Testing" and as an added bonus, we'll talk about how to restore exhaustive testing when we have lost `Equatable` conformance.
## The Problem With Non-Exhaustive Testing
Here's a trivial example. Suppose, you had a `Person` class like this:
```swift
class Person {
var name: String?
var hasName: Bool {
name != ""
}
init(name: String) {
self.name = name
}
}
```
You realize that there is some hidden behavior here. `hasName` is effectively a function that calculates if the `Person` has a name. We need to test if this computed variable produces the correct result:
```swift
func testPersonHasName() {
let person = Person(name: "Blob")
XCTAssertEqual(person.hasName, true) // ✅ test passed
}
```
Hooray! The test passed! Nope. This is a bad test, and it gives a false sense of security. If we add just a little more to our test, we'll find the bug.
```swift
func testPersonHasName() {
let person = Person(name: "Blob")
XCTAssertEqual(person.hasName, true) // ✅ test passed
person.name = nil
XCTAssertEqual(person.hasName, false) // 🔴 test failed
}
```
`name` is now `nil`, so we should expect `hasName` to be `false`. It's not, and now we have a failing test proving that we have a bug in our code. We forgot to check for `nil`. But don't forget, **we only have this failing test because we remembered to test this case**.
The problem with non-exhaustive testing is [unknown unknowns](https://en.wikipedia.org/wiki/There_are_unknown_unknowns). You simply do not, and cannot know, what you do not know. The answer to this problem is simple[^4]: more tests. Let's test as much as we can so that we don't miss anything. But that leaves us with less time to develop new features, and in some cases may even give us a false sense of security.
[^4]: but not easy
## The Value of Exhaustive Testing
In principle, **Exhaustive Testing** means testing **every** part of your code exhaustively. This way you have to explicitly predict the exact state of your code so that you can prove that it behaves reliably. You might be thinking, "Well, that sounds... exhausting." It's actually not. In fact, it often results in shorter, simpler tests.
Now let's imagine if our `Person` class grew to something a little more complex.
```swift
public class Person {
var name: String?
var birthPlace: Location
public struct Location {
var country: String
var city: String
var address: String
}
var contact: Contact
public struct Contact {
var phone: String
var email: String
var address: String
}
var hasName: Bool {
name != "" && name != nil
}
// ...
}
```
Now, this is much more laborious to test, if we use the same strategy. We would have to assert on the value of each and every property in the type. We'd even have to assert on the value of the nested types. In practice, what will actually happen is we'll focus "important" stuff and leave the edge cases untested.
Now let's try testing with an exhaustive approach. One way to test exhaustively is to assert on the entire value of the `Person`.
```swift
XCTAssertEqual(person1, person2)
```
This is much better. Now we are asserting on the entire value!
But there are three problems to this approach.
First, `XCTAssertEqual` requires that the types be `Equatable`. For structs this is usually not very hard. We just conform our type to `Equatable` and Swift will automatically write the implementation for us, most of the time. For classes, you have to write the implementation yourself, and it's actually a lot more complex than it may seem.[^5]
[^5]: Equatability for reference types such as classes and actors is a deeply involved topic and should not be considered the same as equatability for value types such as structs and enums. This is because reference types encapsulate not only value, but also object identity. For more information on this complexity, I recommend checking out [this episode](https://www.pointfree.co/episodes/ep254-observation-the-gotchas#gotcha-value-reference-equatability-hashability) of pointfree.
The second problem comes from manually implementing `Equatable`. As your codebase evolves over time, you will eventually need to change the properties of your types, but your `Equatable` conformance will not be automatically updated. This means your tests will incorrectly assert on your outdated `Equatable` implementation!
Third, in order to automatically synthesize an `Equatable` implementation, you must add `Equatable` to the type definition (it won't synthesize an implementation if you add it to an extension). In other words, if you don't own the type (i.e. if the type comes from a library that you can't edit), then you lose automatic `Equatable` implementation.
## Introducing Pseudo-Exhaustive Testing
I'd like to introduce another approach that I call **Pseudo-Exhaustive Testing** which is faster, easier, and safer.
The Swift standard library comes with a very helpful function called [dump](https://developer.apple.com/documentation/swift/dump(_:name:indent:maxdepth:maxitems:)). `dump` will print an entire type, and all of it's nested properties to the console.
```swift
dump(person)
//Person #0
//▿ name: Optional("Blob")
//- some: "Blob"
//▿ birthPlace: Person.Location
//- country: "Some Country"
//- city: "Some City"
//- address: "Some Address"
//▿ contact: Person.Contact
//- phone: "Some Phone Number"
//- email: "Some Email"
//- address: "Some Address"
```
But even better, we can provide a text output stream to `dump`. In other words, we provide it a `String` to write to. Now we can easily write a test like this, and assert on the value of every single nested property, and we didn't even need to conform to `Equatable`!
```swift
let person1 = Person(/*...*/)
let person2 = Person(/*...*/)
var person1String = ""
var person2String = ""
dump(person1, to: &person1String)
dump(person2, to: &person2String)
XCTAssertEqual(person1String, person2String)
```
I can't stress enough how revolutionary this approach is. If we used the property assertion method, we would need to tediously assert on every single nested property. If we remove or change a property, then now our test is broken. Even worse, if we add a property to our type, we need to remember to add the assertion to our test. If we forget, then the test will incorrectly pass, and we'll have false security.
On the other hand, things aren't much better with the equatable asertion method. The test is easier to write, but we've just shirked the responsibility to the `Equatable` conformance. Even worse, if we had to manually conform to `Equatable` then we have the same problems. If we remove a property, then we break `Equatable`. If we add a property then we need to remember to add it to our `Equatable` conformance. Except now, if we forget to add it to `Equatable`, we not only get a false positive in our test, we also get incorrect behavior in our production code! Perhaps the only thing worse than a missing test, or an incomplete test, is a false passing test!
So why do I call it **Pseudo-Exhaustive Testing**? It is important to note that we are not asserting directly on the values themselves. We are asserting on the string values of the dump output. In most cases the dump output string equality should directly match the equality of the values themselves. But nevertheless, we are still asserting on string representations of the values, rather than asserting on the values directly. So there are edge cases where two values could dump the same string, and thus the test would return a false positive. In my estimation, in most cases this will not be a major concern. Later I will recommend how best to handle this.
## Gaining Helpful Diff Reports
We can make exhaustive testing more ergonomic by adding diff print outs for failures! [Pointfree](https://www.pointfree.co/) has created a fantastic library named [CustomDump](https://swiftpackageindex.com/pointfreeco/swift-custom-dump#user-content-expectnodifference), which takes the same concept as Swift's `dump` and adds some extra super powers.
This library includes a very helpful method called [expectNoDifference](https://swiftpackageindex.com/pointfreeco/swift-custom-dump/main/documentation/customdump). `expectNoDifference` basically does the same thing that we did earlier in our dump assertion strategy, except even better. First, `expectNoDifference` requires that the types conform to `Equatable`. This means that it is actual Exhaustive Testing and not mere Pseudo-Exhaustive Testing. But there's another huge benefit which we can see in the image below. `expectNoDifference` will not only assert on the values but if the test fails, it will show a concise diff with the precise property that is different. This can be incredibly valuable when dealing with very large, nested types. I strongly recommend replacing `XCTAssertEqual` with `expectNoDifference` in most cases!
```swift
var person1 = Person(/*...*/)
person1.makeSomeMutation()
let person2 = Person(/*...*/)
expectNoDifference(person1, person2)
// Now we have proof of every change that happened in `makeSomeMutation()`
```
![]()
Once again, however, we must conform to `Equatable`, which may not always be feasible. Does this mean we also have to lose those convenient diffs? No. Once again we can implement Pseudo-Exhaustive Testing. The `CustomDump` library has another function called `diff` which powers the diff output of `expectNoDifference`. We can make a function which will pass if there is no difference in the dump.
```swift
func expectNoDifferenceInDump(_ lhs: T, _ rhs: T) {
if let diff = diff(lhs, rhs) {
XCTFail(diff) // fail and show the diff
} else {
XCTAssertTrue(true) // pass if there's no difference in the dump
}
}
// Usage:
expectNoDifferenceInDump(person1, person2)
```
## Exhaustive Testing Recommendations
I recommend starting with Exhaustive Testing for most use cases. If and when you come to a use case where `Equatable` conformance is not available and cannot be automatically synthesized, then I recommend switching to a hybrid approach using Pseudo-Exhaustive Testing and Non-Exhaustive Testing. Use the Non-Exhaustive Testing to test mission critical business logic, and use Pseudo-Exhaustive Testing to cover blind spots. Also, change how you think about tests for a Pseudo-Exhaustive Test. When a Pseudo-Exhaustive Test passes, you should not think of it as a true passed test, but instead you should think of it as a pseudo passed test. In other words, don't think of it as proof that your code behaves as expected. Instead, think of it as proof that your test has not found any failing edge cases from a dump. This type of test may not be as reassuring as a Non-Exhaustive Test or a truly Exhaustive test, but it is still a valuable tool in your toolbelt. It will make you aware of blind spots in your test suite, which you can then fill with Non-Exhaustive tests.
If you are using a manual implementation of `Equatable` then I recommend also using Pseudo-Exhaustive Testing. This could help alert you to incorrect or out of date `Equatable` implementations. (Don't forget, that even if your `Equatable` implementation is automatically synthesized, if a property has a manual `Equatable` implementation, then your parent type still depends on that manual implementation.)
## Conclusion
Today, we assessed a variety of testing styles along the spectrum of exhaustivity. We looked at Non-Exhaustive, Exhaustive and Pseudo-Exhaustive Testing. We've seen how Exhaustive Testing can be faster to write, and more thorough, covering even edge cases that you forgot to consider testing.
Still I don't want to replace one false sense of security with another. Exhaustive Testing is very valuable, but it is no silver bullet. The name is even a little misleading. For example, it is exhaustive over every child property in a type, but it is not exhaustive over every function. Nor is it exhaustive over side effects from outside dependencies and so forth. My intention with this blog is not to claim that I've found a silver bullet to kill all bugs.
The point is to show that with exhaustive testing, we are exhaustively asserting on every value of every nested property. This is deep test coverage. We are testing issues that we likely would have never considered, and it turns out, it's actually easier to write as well.
---
## Next Steps
If you would like to dip your toes more into the world of exhaustive testing in Swift, then I recommend checking out these two libraries:
- [swift-custom-dump](https://swiftpackageindex.com/pointfreeco/swift-custom-dump): The library which we discussed throughout this article.
- [swift-composable-architecture](https://swiftpackageindex.com/pointfreeco/swift-composable-architecture): A powerful library for building applications. It uses exhaustive testing by default.
- [swift-snapshot-testing](https://swiftpackageindex.com/pointfreeco/swift-snapshot-testing): While **Snapshot Testing** is a whole other style, and is not the same as Exhaustive Testing, it can also alert you to edge cases that you did not consider.
# How to Take Full Advantage of Swift Package Index
The [Swift Package Index](https://swiftpackageindex.com) (SPI) is an invaluable resource for both package users and maintainers, streamlining the process of discovering, using, and managing Swift packages. Whether you're looking to integrate a package into your project or contribute your own, SPI offers a range of features to maximize your productivity and collaboration. This blog post will guide you through the best practices for leveraging SPI to its full potential.
## Tips for Package Users
### How to Open SPI From GitHub
Perhaps you've already found a package you like on GitHub. You can easily jump to viewing the package on SPI simply by changing the url to `swiftpackageindex.com`. For example, if you are currently at the GitHub repo for the new [Swift Testing](https://github.com/swiftlang/swift-testing) framework at https://github.com/swiftlang/swift-testing then simply change the url to https://swiftpackageindex.com/swiftlang/swift-testing. If the package is already indexed on SPI then it will take you to the page. If not, then it will guide you through an easy process to request adding it to SPI.
### Try a Package in a Playground
One of the easiest ways to evaluate a new Swift package is by trying it out in a playground. Playgrounds allow you to experiment with the package’s functionality in an interactive and isolated environment without the need to set up a full project. To do this, simply go to a package page on SPI and click the **Try in a Playground** button. This will open a macOS app called _SPI Playgrounds_ which will download the package, and set up a playground for you. There can be quite a bit of boilerplate to set up a package environment in a Swift Playground, but with SPI, it is trivial to try out a package!
### Use a Package
When you've decided that a package is a good fit for your use case, simple click the **Use this Package** button at the top right of the package page. This will show a modal with extremely helpful and concise installation instructions.

### View Documentation
Comprehensive documentation is crucial for the effective use of any package. SPI simplifies the process of accessing a package’s documentation directly from its index page. Users can view different versions of the documentation, making it easier to refer to the correct information for the specific version of the package they are using. Well-maintained documentation ensures users can implement the package with minimal friction.
![]()
SPI's search results helpfully show if a package has documentation. To view documentation, simply go to the package's page and click the **Documentation** button on the right. When you are looking at documentation, notice how it is rendered in Swift's super helpful DocC format, just like Apple's own documentation. There's also a helpful breadcrumb trail at the top of the page so that you can quickly navigate to the package's page or the author's page. At the end of that breadcrumb is a truly killer feature. **You can pick the exact package version that you would like to view documentation for.** Just hover your mouse over the version number to see the available versions. Lastly, if the package contains documentation for multiple targets, then you will also see a breadcrumb for the target. Hover over that, to see the other available targets!
![]()
As the API of a library evolves over time, this feature can become invaluable. In fact, SPI's documentation hosting has become so valuable to me, that I tend to use it more often than Xcode's local **Build documentation** feature.
### Use Package Collections
In Swift 5.5, the Swift Package Manager added support for [Package Collections](https://www.swift.org/blog/package-collections/). These work sort of like an RSS feed for Swift Packages, and SPI auto-generates these Package Collections for you. For example, if you go to https://swiftpackageindex.com/swiftlang this will take you to the author page for **The Swift Programming Language**. Here you can see all of the packages created by this author or organization. At the top of the page is a URL to the Package Collection. You can copy this URL for your own use.
#### Adding a Package Collection Using Swift's CLI
You can now go to your terminal and type in `swift package-collection add https://swiftpackageindex.com/swiftlang/collection.json`. This will now add the collection to your local collections. Collect many collections onto your machine and now you have all your packages available to search on your local device. And with `swift package-collection refresh` you can ensure that your collections are always up to date. Use `swift package-collection --help` to learn more.
#### Adding a Package Collection Using Xcode
To add a Package Collection to Xcode, go to **File > Add Package Dependencies...**. This will open a modal to add a package to your project. On the left sidebar you can see all the collections you've already added. On the bottom of the sidebar is a **+** button. Click it to add a collection. You can simply paste in that same URL that we got from SPI. There's also a refresh button to refetch the latest data from the package collections.

## Tips For Package Maintainers
### How To Add Your Package to SPI
Adding your package to the Swift Package Index is straightforward and enhances its visibility to a broader audience. To add your package, you can just click the **Add a package** button at the top of the home page. But there's another option that's even easier. If you're already on the GitHub page for the repo, just change the url to `swiftpackageindex.com` (leaving everything after the domain the same), then this will take you to the SPI page if it exists or an _Add Request_ page.
By listing your package on SPI, you make it easier for developers to discover and use your work, fostering a larger community around your project.
### Add shields.io Badges

Perhaps you've noticed that many repos today have informative, glanceable badges at the top of their README's. This can display helpful information such as compatibility for Swift language versions, platforms, as well as automated CI testing results.
SPI automatically runs these tests for you and auto generates the badges for you. All you have to do is paste in a simple code into your repo's README. To add it, go to your package's page, and look for the **Do you maintain this package?** section on the right. Click the link and follow the directions.
### Host Documentation
This is the killer feature of Swift Package Index! Hosting your package documentation is essential for providing users with the necessary information to implement and utilize your package effectively. SPI can build your documentation on your behalf, and host it on their site. You don't have to build your documentation or deploy it. Simply push a new release, and SPI will create your documentation site. All that SPI needs is a little bit of configuration data so that they know how best to build your docs.
Configurations are stored directly in your repo in a `.spi.yml` file. You can find the docs [here](https://swiftpackageindex.com/swiftpackageindex/spimanifest/main/documentation/spimanifest). They also have a very [helpful tool](https://swiftpackageindex.com/swiftpackageindex/spimanifest/~/documentation/spimanifest/manifestvalidation) to validate your `.spi.yml` file before you upload. The tool is available as a CLI or an [Online Validator](https://swiftpackageindex.com/validate-spi-manifest).
**SPI will even generate a new documentation site for each version of your library.**
It's worth noting that, generating and hosting documentation is a non-trivial task. Even a small Swift library can hold documentation for thousands of pages. You might only have a few small types in your code, but Swift and DocC could be generating an enormous amount of methods and documentation on your behalf. Simply conforming to common Swift protocols such as `Collection` or SwiftUI's `View` will add a ton of functionality and therefore documentation. Now multiply all of that by all the versions of your library and this can be truly daunting to self-host. SPI abstracts away so much of that complexity. SPI will even retain the major versions of your library. This means it's easy to keep legacy documentation which will make it so much easier for your library user's to migrate.
### Gather Build Results
Swift is available on so many different language versions and operating systems. Ensuring that your library is compatible (and stays compatible) in all of these environments is prohibitively expensive. Amazingly, SPI handles all of this as well! When you push an update, the [SPI Build System](https://swiftpackageindex.com/docs/builds) will attempt to build for each of these environments, and will display the results on the page. In addition, it will generate shields.io badges, so that users can even see some of these results directly in the README (e.g. when looking on GitHub). Gain a huge insight into how your code builds across a wide array of environments with SPI.
![]()
## Conclusion
By following these tips, both package users and maintainers can take full advantage of the Swift Package Index, creating a more efficient and collaborative environment for Swift development. Whether you're exploring new packages or sharing your own, SPI offers the tools and features necessary to streamline your workflow and elevate your projects. Let me know if I missed one of your favorite features.
# Boost Your Productivity with These macOS Typing Shortcuts
Mastering keyboard shortcuts can significantly enhance your productivity on macOS. These shortcuts are versatile and work in nearly any text field across various macOS apps, including browsers. Moreover, many of these shortcuts can be combined, offering even more powerful text navigation and editing capabilities.
>#### [BONUS] Vim Equivalents:
>Many power users and coders may be familiar with Vim, which is a powerful text editor. All of these features are already available in Vim, or any editor that supports Vim key bindings, but if you are using an app that does not support Vim key bindings, then you do not have access to those features. On the other hand, the keyboard shortcuts, below, are available in almost every app in macOS. Non-Vim users can experience many (definitely not all) of the powerful features that Vim users already enjoy, except across the operating system, and without the obtuse syntax. For learning purposes, I'll include the Vim equivalents in this article.
## Clarifying Key Names and Symbols
Before diving into the shortcuts, let's clarify the different names and symbols used for macOS keys. This article will use the following terms for consistency:
- **Command (CMD)**: Sometimes represented by ⌘.
- **Option (Opt)**: Also known as Alt, represented by ⌥.
- **Control (Ctrl)**: Represented by ^.
- **Shift**: Represented by ⇧.
## The CMD Key
The CMD key, or Command key, is central to many macOS shortcuts. Here are some essential text navigation commands using the CMD key:
- **CMD + (←)**: Jump to the start of the line (equivalent to the HOME key on Windows).
- **CMD + (→)**: Jump to the end of the line (equivalent to the END key on Windows).
- **CMD + (↑)**: Jump to the start of the text field.
- **CMD + (↓)**: Jump to the end of the text field.
**Equivalent VIM Commands**:
- **CMD + (←)**: `^` (move to the start of the line).
- **CMD + (→)**: `$` (move to the end of the line).
- **CMD + (↑)**: `gg` (move to the top of the file).
- **CMD + (↓)**: `G` (move to the bottom of the file).
## The Option Key
The Option key provides another layer of text navigation precision. It allows you to move the cursor by "word". What is a "word"? It depends on the editor you're using, but usually the cursor will move up to the next space character. Sometimes it will stop at special characters such as `(` or `{` Here's how you can use it:
- **Opt + (←)**: Jump to the beginning of the current or previous word. If you are in the middle of a word, this shortcut will take you to the start of that word; otherwise, it will jump to the start of the previous word.
- **Opt + (→)**: Jump to the beginning of the next word.
- **Opt + (↑)**: This works similarly to CMD + (↑), jumping to the start of the text field.
- **Opt + (↓)**: This works similarly to CMD + (↓), jumping to the end of the text field.
**Equivalent VIM Commands**:
- **Opt + (←)**: `b` (move back one word).
- **Opt + (→)**: `w` (move forward one word).
- **Opt + (↑)**: `gg` (move to the top of the file).
- **Opt + (↓)**: `G` (move to the bottom of the file).
## The Shift Key
The Shift key is used to extend your selection while navigating text. Here are some useful combinations:
- **Shift + (←)**: Move the cursor left one character and highlight the text.
- **Shift + (→)**: Move the cursor right one character and highlight the text.
- **Shift + (↑)**: Move the cursor up one line and highlight the text.
- **Shift + (↓)**: Move the cursor down one line and highlight the text.
In other words, adding Shift to any of these commands tells macOS, "I want to move my cursor AND keep my current highlight."
### Combining Shift with CMD and Option Keys
You can combine the Shift key with CMD or Option shortcuts to highlight larger sections of text quickly.
#### CMD + Shift Combinations
- **CMD + Shift + (←)**: Highlight from the cursor position to the start of the line.
- **CMD + Shift + (→)**: Highlight from the cursor position to the end of the line.
- **CMD + Shift + (↑)**: Highlight from the cursor position to the start of the text field.
- **CMD + Shift + (↓)**: Highlight from the cursor position to the end of the text field.
**Equivalent VIM Commands**:
- **CMD + Shift + (←)**: `v` + `0` (enter visual mode and move to the start of the line).
- **CMD + Shift + (→)**: `v` + `$` (enter visual mode and move to the end of the line).
- **CMD + Shift + (↑)**: `v` + `gg` (enter visual mode and move to the top of the file).
- **CMD + Shift + (↓)**: `v` + `G` (enter visual mode and move to the bottom of the file).
#### Option + Shift Combinations
- **Option + Shift + (←)**: Highlight the word to the left of the cursor.
- **Option + Shift + (→)**: Highlight the word to the right of the cursor.
- **Option + Shift + (↑)**: Highlight to the beginning of the paragraph or block of text (similar to CMD + Shift + (←)).
- **Option + Shift + (↓)**: Highlight to the end of the paragraph or block of text (similar to CMD + Shift + (→)).
**Equivalent VIM Commands**:
- **Option + Shift + (←)**: `v` + `b` (enter visual mode and move back one word).
- **Option + Shift + (→)**: `v` + `w` (enter visual mode and move forward one word).
- **Option + Shift + (↑)**: `v` + `gg` (enter visual mode and move to the top of the file).
- **Option + Shift + (↓)**: `v` + `G` (enter visual mode and move to the bottom of the file).
## Multi-Cursor Editing in Xcode
For developers using Xcode, multi-cursor editing can be a game-changer. This feature allows you to create multiple cursors, making simultaneous edits in multiple places possible.
- **Ctrl + Shift + Click**: Create another cursor where you clicked.
- **Ctrl + Shift + (↑)**: Move your cursor up and create a new cursor there.
- **Ctrl + Shift + (↓)**: Move your cursor down and create a new cursor there.
- **CMD + Opt + Enter**: This keyboard shortcut is incredibly powerful! It does so many things at the same time and it is perfect for renaming variables or classes in code. Here's the workflow:
- First, highlight something you would like to rename (i.e. "Find and Replace").
- Then press **CMD + Opt + Enter**. It will find the next occurence of what you highlighted and highlight that as well.
- You can press **CMD + Opt + Enter** many times and it will find more and more occurences and highlight them as well.
- Now that you have all these highlights, you can make any edit you want to all of the highlights at the same time.
- For example, to rename, simply start typing. Since multiple spots are highlighted, the highlighted text will be replaced with a cursor at each highlight.
- Or if you just want to rename part of it, you can press ← and all of your cursors will move to the beginning of their highlight, and you can start typing there.
## In Practice
Let's explore some practical use cases and how you can combine the techniques from this article with basic commands like copy, paste, and undo.
### Delete an Entire Line (or Multiple Lines)
1. **Select the Line(s)**:
- If your cursor is in the middle of the line, first move your cursor to the end of the line by pressing **CMD + (→)**.
- Then press **CMD + Shift + (←)**. This will move the cursor to the beginning of the line AND highlight at the same time.
2. **Delete the Line(s)**:
- Simply press **delete** or press **CMD + X** to cut (delete) the selected line(s).
**Equivalent VIM Command**: `dd` (delete the current line) or `d{n}d` (delete multiple lines).
### Move an Entire Line (or Multiple Lines) Up or Down
1. **Select the Line(s)**:
- Select the line(s) using the same process, described above.
2. **Cut the Line(s)**:
- Press **CMD + X**.
3. **Move the Cursor**:
- Use **CMD + (↑)** or **CMD + (↓)** to move the cursor to the desired location.
- You may need to create a new line, so you have a blank place to paste your lines.
4. **Paste the Line(s)**:
- Press **CMD + V** to paste the cut line(s).
>#### Moving lines in code editors
>Most code editors have a command with a name like "Move line up" which will make this process even easier by moving the line up, without the need to select text.
>In Xcode, this command is **CMD + Opt + [** by default.
![An example of quickly moving a line down without needing to use a mouse to highlight.]()
**Equivalent VIM Commands**:
- Move the current line up: `ddkP`.
- Move the current line down: `ddp`.
- Move multiple lines: `d{n}d{move to desired line}P`.
### Additional Practical Use Cases
#### Copy and Paste a Word(s)
1. **Select the Word**:
- Place your cursor at the start of the word.
- Use **Shift + Opt + (→)** to highlight the word.
2. **Copy the Word**:
- Press **CMD + C**.
3. **Move the Cursor**:
- Use **Opt + (→)** to navigate to the desired location.
4. **Paste the Word**:
- Press **CMD + V**.
**Equivalent VIM Commands**:
- Select the word: `viw`.
- Copy the word: `y`.
- Paste the word: `p`.
### Cross-Platform Consistency
These powerful text navigation and editing shortcuts are not exclusive to macOS; similar concepts are also available on Windows and Linux. On Windows, the CTRL key often substitutes for the CMD key, with shortcuts like CTRL + (←) and CTRL + (→) allowing you to jump between words, and CTRL + Shift combinations enabling extended selections. Linux systems, particularly those running desktop environments like GNOME or KDE, offer comparable functionality, with the CTRL and ALT keys providing similar navigation and selection capabilities. Additionally, many text editors and IDEs across these platforms support Vim key bindings, offering a consistent editing experience for those familiar with Vim commands. This cross-platform availability ensures that users can maintain their productivity regardless of the operating system they are using.
### Conclusion
By integrating these keyboard shortcuts into your workflow, you can navigate and edit text more efficiently, saving time and boosting your productivity on macOS. Whether you are a writer, a developer, or anyone who spends a lot of time typing, mastering these shortcuts will make your macOS experience smoother and more efficient. Try using these methods today, and soon enough it will just become a part of your muscle memory!
# How to Scroll to a Percentage in a ScrollView
SwiftUI can make many tasks extremely easy, yet SwiftUi struggles to do other seemingly simple tasks. Today we will learn how to accomplish one of those tasks. We will create a ScrollView that can programmatically scroll to a specific location within the ScrollView. First let's create a new type called `ProgrammaticScrollView`.
```swift
struct ProgrammaticScrollView: View {
@Binding private var scrollID: Int?
let content: () -> Content
init(scrollID: Binding, @ViewBuilder content: @escaping () -> Content) {
self._scrollID = scrollID
self.content = content
}
var body: some View {
ScrollView {
ForEach(1..<101) { num in
VStack {
Text("\(num)").frame(maxWidth: .infinity, alignment: .leading)
.id(num)
Spacer()
}
}
}
.scrollPosition(id: $scrollID, anchor: .top)
}
}
```
Here we're using iOS 17's new [scrollPosition(id: anchor:)](https://developer.apple.com/documentation/swiftui/view/scrollposition(id:anchor:)) method. This method receives an `id` of type `Binding<(some Hashable)?>` and then scrolls to a child view with that id. As you can see there are 100 child views numbered 1 to 100, each with a corresponding id. Programmatically scrolling is now as simple as changing the value of our scrollID Binding!
Notice how the numbers are evenly spaced vertically. Now why don't we hide those numbers from the user?
```swift
// ...
ScrollView {
content()
.padding(.horizontal)
.background {
VStack {
ForEach(1..<101) { num in
VStack {
Text("\(num)").frame(maxWidth: .infinity, alignment: .leading)
.id(num)
.opacity(0.0)
Spacer()
}
}
}
}
}
.scrollPosition(id: $scrollID, anchor: .top)
// ...
```
You might be thinking, why don't we just use ScrollViewReader. Well, the techniques in this tutorial should be just as easy to implement using iOS 14's `ScrollViewReader`. It would just be slightly more complex since you would need to wrap your `ScrollView` in a `ScrollViewReader` and then give commands to a `ScrollViewProxy`.
## Some Quirks
`scrollPosition(id: anchor:)` has some other benefits over `ScrollViewReader`. The docs promise that the ScrollView will automatically update the Binding, thus giving you the freshest position of the ScrollView. The docs say:
>As the scroll view scrolls, the binding will be updated with the identity of the leading-most / top-most view.
Unfortunately, seemingly due to bugs, it just doesn't do that at all. In my testing, the Binding is just never updated by the ScrollView. But at least you can scroll programmatically.
Also, the docs say that you must use `scrollTargetLayout()`. I don't see why. I have found no difference in behavior with or without that method, so I'm just leaving it out of my view.
## iOS 18's New API
Now apparently, iOS 18 added yet another new method called [scrollPosition(_: anchor:)](https://developer.apple.com/documentation/swiftui/view/scrollposition(_:anchor:)) which receives a new `ScrollPosition` type. (I haven't tried the new iOS 18 beta yet, so I don't know if this actually works yet.)
## In Practice
Now that have something workable, let's take it for a spin.
```swift
struct ExampleView: View {
@State private var scrollPercentage: Int? = 1
@State private var picker = 34
var body: some View {
ProgrammaticScrollView(scrollID: $scrollPercentage)
.safeAreaInset(edge: .bottom) {
bottomBar
}
}
@ViewBuilder var bottomBar: some View {
VStack {
HStack {
Picker("Select a number", selection: $picker) {
ForEach(0..<100) { num in
Text("\(num)").id(num)
}
}
Button("Scroll to \(picker)%") { scrollPercentage }
}
LabeledContent("scrollPercentage", value: "\(scrollPercentage)") // useful for debugging
}
.padding(.horizontal)
.background(.thinMaterial, ignoresSafeAreaEdges: .bottom)
}
}
struct CircleButton: ButtonStyle {
let background: Background
func makeBody(configuration: Configuration) -> some View {
configuration.label
.padding()
.background(background, in: .circle)
}
}
```
Now we have a View where we can test programmatically scrolling our scroll view to any arbitrary position on our screen. This type of behavior would be extremely helpful for situations such as scrolling the transcript of a podcast, to current position of the audio while listening.
Today we learned how, with a little bit of ingenuity we can add powerful features to our UI. If you'd like to see a full code example, you can have a look at this [gist](https://gist.github.com/DandyLyons/e95af09ad40a8a7e9ee9bb04931fca3e).
If you like this work, please share it with others. Check back every week on Wednesdays for new posts.
# Job Copilot
*Job Copilot is currently available for pre-release testing.*
## About
Job Copilot makes it easy to advance your career. It includes:
- Job Application tracker to keep track of your progress on opportunities
- A "Resumé Closet", a place to keep track of work history, skills and anything else that may fit your resume.
- AI powered generators for resumés and cover letters.
- Career advice chat feature.
## Tech Stack
| Component | Tech |
| ------------ | --------------------------------- |
| Platforms | iOS, iPadOS |
| Architecture | TCA (The Composable Architecture) |
| UI | SwiftUI |
| LLM | Gemini |
# Hello Hugo
Hello!
Welcome to my personal site! Here I will be posting my projects and things I'm learning.
I've recently rewritten this site in [hugo](https://gohugo.io/)! I appreciate how blazingly fast and customizable it is. The code for this site can be found [here](https://github.com/DandyLyons/DandyLyons.github.io).
## Dev Diary
Now I'd like to share some of my journey of creating this site.
When creating this site, I had a few priorities:
1. It should be statically generated.
2. It should be easy to write on using Markdown.
3. It should be customizable.
4. It should support modern "tablestakes" website features. (dark mode, social previews, favicons etc.)
5. It should be developed in Swift.
### Initial Priorities
#### It should be statically generated
One of my first encounters with the concept of statically generated sites was [Swift by Sundell](https://www.swiftbysundell.com). This has been one of my favorite blogs for years, and so eventually I learned that John Sundell created his site using something called Static Site Generation, which is when the entire site generated ahead of time statically.
#### It should be easy to write on using Markdown
What attracted me to SSG was that I can write articles in simple Markdown. This is a lightweight simple syntax that allows me to just focus on the content. Furthermore, I can develop my site locally, and see my changes update in real time (much like a SwiftUI Preview), and then deploy my changes when I'm ready.
I've also been an avid Obsidian user over the past few years. Markdown has become deeply ingrained into the way that I think and write.
#### It should be customizable
In years past, on other sites, I've used Wordpress. It was liberating to see how powerful I could make my sites using themes and plugins. But inevitably, I would find a small little change that I wanted to make and it would be unsupported by the plugin. Or, I would have absolutely bizarre buggy behavior, only to evenutally discover that it was because the plugin was outdated, or conflicted with another plugin. This whack-a-mole was debilitating.
This time around I knew that I needed a solution that was customizable. I'm too opinionated to be beholden to someone else's theme. But I also knew that, in my current situation, it was not tenable for me to create the entire site on my own.
I knew HTML, CSS, and JavaScript. At least the core concepts. But I wasn't using it at a deep level. Certainly not on a regular basis. So I wanted a solution where the majority of best practices were just already included "for free" and instead I could just focus on the "small tweaks" that I wanted.
#### It should support modern "tablestakes" website features
Today's readers just expect websites to be responsive. It should smoothly transition from Desktop, to tablet, to mobile. It should switch automatically between light and dark mode. It should display correctly when I share a link on social media. If any of these features are missing or buggy, then the site feels "janky" or "broken".
#### It should be developed in Swift
Swift by Sundell is published using a Static Site Generator which he created called [Publish](https://github.com/johnsundell/publish). In fact, it really is quite a full featured suite, including a Markdown parser (Ink) and a HTML-like Swift DSL (Plot). This seemed to be my holy grail. I could develop for the web using the same tools that I use to develop for mobile. But I soon found a few issues.
There were a few features that were missing. Thankfully, Publish has a great plugin system where you can add new features, but that leads to the second problem: there's not a huge community of Publish users. It was difficult to find example repos, or plugins that met my needs.
It was certainly possible to create my own plugins, but that had two problems. First, creating those plugins would require deeper learning about both Plot (the HTML interpreter) and HTML itself. If I need to learn HTML anyways, I might as well just learn and write it in actual HTML. So this was my second problem: the promise of a primarily Swift workflow, seemed to not actually deliver.
### The Trouble with DSL's
One of my takeaways from this experience is I started to learn some of the pros and cons of a DSL, or Domain Specific Language. For example with Plot we can write code like this:
```swift
var body: Component {
Article {
Image(url: imagePath, description: "Header image")
H1(title)
Span(description).class("description")
}
.class("news")
}
```
This code is so cool and so powerful! As you can see, it is using the same names and concepts as HTML such as `` and `
` but it's written in native Swift code that is just like SwiftUI. It also comes with all the benefits of Swift such as static type checking.
But what happens when you want to take a slight detour off the happy path? What happens when you need a feature that isn't natively supported? To be clear, I'm not trying to criticize John Sundell or his fantastic libraries. I'm just trying to point out that DSLs have a basically impossible task. It's not fair to expect a library owner to keep up with a mature, full-featured, decades old technology, with one of the largest dev communities in the world.
Also, how transferrable are these skills? If I get really used to reading "html" code in a Swifty way, what am I going to do if I'm expected to work on a project that uses actual HTML code. The syntax is similar, but not the same. Will I ever be hired to a team that's working on a Plot stack. Probably not.
On the other hand, what happens if I just grok and use actual HTML? Well that knowledge is transferrable to tons of domains. React uses `jsx` which looks and behaves much more like HTML. There are also templating languages like Django and Stencil which can use real HTML. By learning and using HTML, I am using a technology that is in demand, is mature, has a huge community, and is transferrable to many domains.
But more importantly, now I have simplified the stack. I have one less system of complexity to consider. I no longer have to wonder if my DSL has generated the HTML code that I think it has. I can just write HTML code.
### Revised Priorities
So it was with a heavy heart that I looked for a new solution. I was no longer prioritizing a Swift-first solution. I experimented with a few others along the way.
- **Quartz**: Quartz turns an Obsidian vault into a publishable site. (It's a replacement for Obsidian Publish).
- For a while, I wondered if I could just host my blog inside of my Obsidian vault.
- Eventually I realized that it's just a different problem space with different needs. I still love Quartz and plan to use it in the future, but just for a *notes* section of the site, and not for the whole site.
- **Jekyll**: I also tried Jekyll.
- In my limited time with it I discovered, I like Jekyll, but I'm not a fan of Ruby's developer experience. It took a very long time to install jekyll, mostly because it took a long time to install Ruby.
- But really, the thing that was the dealbreaker was that Jekyll takes too long to build and iterate. Especially, when I am first learning, it is vital that I get quick feedback so that I can verify that the changes that I'm making do what I think they are doing.
- In Jekyll, my build times were averaging between 1 and 1.25 seconds. That may not seem like much but that happens every single time my site hot reloads. It breaks your flow of though when you are constantly waiting for a tool to catch up.
- Even if Jekyll is usable now, I only have a few pages on my site. How much more will it slow down as my site grows over time?
- **Hugo**: Finally, I tried Hugo, and the faster build times won me over:
- Currently my Hugo build times average to about 50ms. That's about a 20x increase in speed. That means faster build times, deploy times, and faster iterative renders.
## Stop Looking for a Perfect Solution
But hugo is not without it's drawbacks. A small part of me misses jekyll's liquid templating language which is very similar to Swift's Stencil language. Both of those templating languages felt easier to read and understand.
Hugo on the other hand uses Go's html/template library. Currently it feels less intuitive to me. But this is partly just because I've never learned Go before. But as I've seen with each solution that I've tried, there simply is no perfect solution. Everything has it's own set of tradeoffs. Know yourself, know your wants and needs, find something that works "well enough" and then just stick with it. Stop trying to look for the "optimal" solution. If the "optimal" solution takes you 5 times as long to find as something that is almost as good, then that makes it not very optimal.
## Don't Be Afraid of Learning
Which brings me to my next takeaway: don't be afraid of learning. In SWE, we feel an immense pressure to "learn the right things". _Don't learn that language, no one is hiring for it anymore. You should learn this language instead._ It takes a very long time to learn a new language, framework, tool, or skill, and it can be incredibly demotivating to invest all that time and effort to learn it only to discover that it's not _in demand_, or _that's not the modern way to do it_.
I was "afraid" to use native HTML and web technologies, because I was focused on mobile and Swift. Adding something else to my pile felt daunting. But when I finally gave in and tried it, I realized it wasn't so scary. Now, I have another tool in my toolbox and that's fantastic.
There is a balance that is, perhaps, difficult to find. On the one hand, I've learned that it's simply impossible to "learn everything". You will become a jack of all trades and a master of none. And the world is simply too big. It simply isn't possible to keep up with everything. I think it's important to specialize and focus your learning.
But now I can see that I focused so much that I missing out on valuable solutions right next to me. Even a surface-level knowledge of a wide variety of topics is valuable. While it may not be enough to tell you the solution to that problem, it could certainly point you in the right direction.
## Looking to the Future
There's a part of me that feels like I've spent too much time writing and rewriting this personal site. Perhaps. But dwelling on that isn't going to help me going forward. Not only that, but these experiences are still valuable. They will shape and guide my direction going forward. Do you feel like your path has been a meandering waste? Maybe it's not such a waste. Personally, I like that Hugo uses Go's templating language. Hopefully it will provide me an opportunity to learn some Go basics.
And with that, I'm reminded of this verse:
>Not that I have already obtained all this, or have already been made perfect, but I press on to take hold of that for which Christ Jesus took hold of me. Brothers, I do not consider myself yet to have taken hold of it. But one thing I do: **Forgetting what is behind and straining toward what is ahead, I press on toward the goal** to win the prize of God’s heavenly calling in Christ Jesus.…
>- Philippians 3:12-14
# AestheText
AestheText makes it easy to create _aesthetic_ text by mutating them into fun _fonts_ and _kaomoji_ facial characters.
#### Fonts
There are dozens of fonts to choose from like 𝕥𝕙𝕚𝕤 or even ꓄ꀍꀤꌚ! These fonts are universal unicode symbols meaning they are compatible with practically any app or website.
#### Kaomojis
Kaomojis are like emojis except they are made from multiple unicode characters, meaning there are literally infinite possible combinations. For exaple you could have a cute bear: ʕ·͡ᴥ·ʔ or even an angry man throwing a table: (╯°□°)╯︵ ┻━┻
## Tech Stack
| Component | Tech |
| ------------ | --------------------------------- |
| Platforms | iOS, iPadOS |
| Architecture | TCA (The Composable Architecture) |
| UI | SwiftUI |
| Purchases | RevenueCat |
## Behind the Scenes
### The Composable Architecture
I chose to use TCA for two main reasons: modularity and testability. TCA makes it easy to separate your app into self-contained modules. This means, it's easy to refactor, since I can build a portion of the project without needing to build the entire project. It's also exhaustively testable since everything is a value type, so I can test that the values equal exactly what I intended.
### In-App Purchases
For this project, I decided to use RevenueCat, so that I can take advantage of their robust In-App Purchase features, including IAP screens which can be updated remotely without the user needing to download a new version of the app.
# Concrete and "Soft" Types in Swift
In our [last article]({{< ref "explicit-implicit-types-in-swift" >}}), we learned about how the generics system is deeply integrated into Swift at practically every level. This can give us magical features that help like *Type Inference* which makes our code easier to read and right, but it can also lead frustrating and confusing compile-time errors. Furthermore, most modern Swift libraries are filled with generic code, especially in Apple first-party frameworks such as **SwiftUI**, **Combine**, and the recently announced **SwiftData**. I hope that I've made a strong case that **generics in Swift are simply too important to ignore**. So without further ado, let's dive into generics, albeit with a slightly different approach than you might expect.
## Reading Generic Code
You might expect an article on Swift Generics to start with writing generic code, and in fact many fantastic authors have already covered this quite well. But perhaps a better approach would be to start with **reading** generic code. This is for a few reasons:
1. By nature, generic code is generalized to multiple use cases. It takes work to understand **one** use case, let alone many.
2. Generic code is quite abstract.
So here is what we will do. Let's look at a few basic common types that are used throughout SwiftUI, and see what we can learn from them, starting with the most basic of them all, the humble [View](https://developer.apple.com/documentation/swiftui/view).
### SwiftUI's `View`
Every single SwiftUI View has a `: View` after it's name like so:
```swift
struct MyView: View {
var body: some View {
Text("Hello World")
}
}
```
In Xcode, right click on the word `View` and click "Jump to Definition". You should see something like this:
```swift
public protocol View {
/// ...
associatedtype Body : View
/// ...
@ViewBuilder @MainActor var body: Self.Body { get }
}
```
What can we learn here about the `View` type? Well, that's a bit of a trick question. `View` isn't really a Type, exactly. It's a protocol. The Swift documentation says this:
> ## [Protocols as Types](https://docs.swift.org/swift-book/documentation/the-swift-programming-language/protocols/#Protocols-as-Types)
>
> Protocols don’t actually implement any functionality themselves. Regardless, you can use a protocol as a type in your code.
Think of protocols as rules. In real life, if we follow certain rules, we get perks. If you pass the driving test, then you get the perk of being allowed to drive legally. Likewise, if your type conforms to the `View` protocol, then it now gets to do all the cool things that SwiftUI Views can do. But the View protocol doesn't actually do anything since it doesn't "actually implement any functionality". **The Type that conforms to the `View` protocol is the actual thing that has properties and methods.**
### Introducing Concrete and "Soft" Types
If you look at the Swift docs on [Types](https://docs.swift.org/swift-book/documentation/the-swift-programming-language/types/) and do a CMD-F search for "*concrete type*", you'll see that the phrase is used throughout. Unfortunately, though, I haven't yet found an official definition of what exactly *concrete type* means.[^1] But I think the definition is pretty clear from the context. **A concrete type is the *actual* type that will be used at runtime.** But if there's such a thing as *concrete types* then that implies that there are *non-concrete* types, types that aren't actually used at runtime. However, I haven't found an official name for these *non-concrete* types, so I'll refer to them as *soft types*. **A _soft type_ is a type isn't actually used at runtime. Instead, it gives instructions to Swift on how to find the _concrete type_.** We can see an example of this in every SwiftUI View:
[^1]: You might say that I haven't found a *concrete* definition of *concrete types*.
```swift
var body: some View
```
The `body` property is explicitly typed using `:` but what is the type? `some View`. But `View` is not a *concrete type* since it's a protocol. Somewhere, Swift has to infer the *concrete type*. Remember, Swift is a strongly typed language so **everything** has a type. The answer is that this is an example of an [opaque type](https://docs.swift.org/swift-book/documentation/the-swift-programming-language/opaquetypes). Essentially, we're telling Swift that body will be "some View". We're not telling Swift which specific type it will be. Instead, Swift will infer the type for us as long as we give it a type that conforms to `View`. For example:
```swift
var body: some View { // `some View` is the soft type
Text("Hello World") // `Text` is the concrete type
}
// ...
var body: some View {
VStack { // `some View` is the soft type
Text("Hello World")
} // The concrete type is `VStack`
}
```
As you can see VStack is generic. Now try altering your `body` to look like this:
```swift
struct MyView: View {
var body: VStack { // 🛑 Error: Reference to generic type 'VStack' requires arguments in <...>
VStack { // `some View` is the soft type
Text("Hello World")
} // The concrete type is `VStack`
}
}
```
So I would say that `VStack` is also a *soft type*. In other words, even if Swift knows that it's a `VStack`, that is not enough information for Swift to infer the *concrete type*. In fact, every generic type is a *soft type*. Every time that we use a generic type, we have to make sure that we are giving Swift enough information to find the concrete type. This could get very tedious and error prone, and so that's why Swift gives us various tools like opaque types (the `some` keyword) to make this easier.
```swift
struct MyView: View {
var body: some View { // `some View` is the soft type
List { // ⭐ the concrete type is some gigantic nested monstrosity
ForEach(0..<9) { num in
VStack {
Text("This is some text in a row cell.")
Text("This is the current number: \(num)")
}
}
.onAppear {
print("The type of MyView.body is \(type(of: self.body))")
}
}
}
}
```
### `associatedType`: generics for protocols
Just as we can make types generic, we can also make protocols generic using the `associatedType` keyword. The [Swift docs says](https://docs.swift.org/swift-book/documentation/the-swift-programming-language/generics/):
>When defining a protocol, it’s sometimes useful to declare one or more associated types as part of the protocol’s definition. An _associated type_ gives a placeholder name to a type that’s used as part of the protocol. The actual type to use for that associated type isn’t specified until the protocol is adopted.
So just like how the `Array` type has a *generic type parameter* called `Element`, the `View` protocol has an *associated type* called `Content`. And as we can see in the definition, `Body` must conform to the `View` protocol.
```swift
public protocol View {
associatedtype Body : View
@ViewBuilder @MainActor var body: Self.Body { get }
}
```
But don't forget `Body` is **not** a concrete type. It's a *soft type*, a placeholder for a type that conforms to `View`. **This means that every time you use a protocol with an associatedtype, you must tell the compiler what the associatedtype is.**
So in the example below how are we telling Swift the type for `body`?
```swift
struct MyView: View {
var body: some View {
List {
Text("Hello")
}
}
}
```
When we used the `:` we declared the type for `body` explicitly right? Well, no. Remember that the `some` keyword is also a placeholder, a *soft type*. No, the concrete type is actually `List` in this case, and so the `associatedtype` `Body` was implicitly[^2] evaluated to be `List`.
### How to explicitly declare the `associatedtype`
If you recall, earlier we learned how to explicitly and implicitly declare generic types:
```swift
let implicitArray = ["strings"]
let explicitArray: Array = ["more strings"]
```
But did you know you can even do this for `associatedtype`s?
```swift
struct MyView: View {
typealias Body = Text // explicitly set the associatedtype
var body: Text {
Text("Hello")
}
}
```
In practice, this wouldn't be the most practical way to do this, in this situation[^3], but there are some situations when it can be helpful. In fact this is often what Xcode will automatically do if you click a "Fix Me" button.
[^3]: because we would have to remember to keep the types of `Body` and `body` in sync with each other.
If you write this:
```swift
struct MyView: View { // 🔴 type 'MyView' does not conform to protocol 'View'
// this is intentionally blank
}
```
... and then click the "Fix Me" button in the error, then Xcode will add this:
```swift
struct MyView: View { // 🔴 type 'MyView' does not conform to protocol 'View'
typealias Body =
}
```
This is because, Xcode doesn't have all the information it needs to help you fulfill the protocol requirement yet. It doesn't know what type `Body` is. Now fill in `Body`...:
```swift
struct MyView: View { // 🔴 type 'MyView' does not conform to protocol 'View'
typealias Body = Text
}
```
and click "Fix Me" one more time and Xcode will add this..."
```swift
struct MyView: View { // 🔴 type 'MyView' does not conform to protocol 'View'
typealias Body = Text
var body: Text
}
```
### Why not just explicitly type everything?
Perhaps you are thinking, "Why can't I just explicitly type everything? Why do we need concrete and so-called soft-types?" In other words, why do we need type inference.
There are a few reasons why type inference is powerful. As we established earlier, Swift's strongly typed system allows the compiler to guarantee that your code is safe and that certain bugs are impossible to write! 🎉 In addition, it allows the compiler to make some optimizations behind the scenes that make our code more performant, and we get all these benefits for free!
But a strongly typed system is also more strict and cumbersome to use. It also requires more maintenance as our codebase evolves over time. For this reason, the Swift team decided to adopt a philosophy of design called Progressive Disclosure of Information. In other words, Swift will hide complexity until it is actually relevant and helpful, and one of the ways that they achieved this was through generics. Through type inference, the Swift compiler is empowered to handle a lot of the grunt work for us, and we can focus on only the things that we care about. For example, we don't need to explicitly tell Swift what the concrete type of `Body` is. But it is also nice to know that we have the power to be explicit, should the need arise.
## Conclusion
In this article we learned about concrete types, and so-called *soft* types. We also learned how they can be used explicitly and implicitly. Once again, we've learned how the Swift compiler has your back and can prevent you from writing certain types of bugs. Furthermore, while the type system can produce some confusing error messages, that can feel very unhelpful, Swift become much more helpful when you "have a conversation with it". This can be done by explicitly setting types in order to see what errors are produced.
# Explicit and Implicit Types in Swift
Generics are one of the most powerful features in Swift, yet they can often feel overwhelming, even for seasoned Swift developers. In this series we'll learn how to make generics simple, useful, and even fun!
### Back to Basics
But to start off, we'll look somewhere you probably won't expect: declaring variables.
```swift
let strings = ["John", "Paul", "George", "Ringo"]
let oneLongString = strings.joined(separator: ", ")
```
This seemingly simple piece of code has some hidden functionality. Consider for a second, what type is `strings`. That's easy. It's an `Array`. But that answer is only half correct. Notice, how does `strings` know about the `joined` method? How does it know how to join the elements? What if that was an array of numbers?. Here, most Swift developers would say that the answer is [Type Inference](https://docs.swift.org/swift-book/documentation/the-swift-programming-language/types/#Type-Inference). And while that answer is technically correct, it's still missing part of the story.
The problem with simply saying that it's Type Inference is that it feels like magic, and while Swift certainly feels magical, it most certainly is **not** magical (and that's actually a good thing). Magic, may produce joy, surprise, and wonder but it is also mysterious, unpredictable, and impossible to understand. So, how did Swift infer the type for the `strings` variable? Was it just really smart? No, absolutely not. The first step to understanding Swift, the Swift type system, and Swift generics is learning this lesson:
> Swift is not magic, even when it feels like it is. Every single thing it does has a predictable reason.
Sorry to wax philosophical on you, but the sooner that we learn this lesson, the sooner generics will make sense to us. So, finally, let's answer the question. How does Swift know that `strings` is an `Array`. The answer is: you said that it was! Swift found the type from the value, and assigned that same type to the variable.
```swift
["John", "Paul", "George", "Ringo"] // this is an `Array` Literal.
// by assigning an Array literal to `strings`, Swift has "inferred" that
// strings must be an Array.
let strings: Array = ["John", "Paul", "George", "Ringo"]
// it's as if you 👆🏼 actually declared the type right here
```
### Explicit vs. Implicit types
Try it for yourself. Declare an Array like so:
```swift
let strings = ["John", "Paul", "George", "Ringo"]
```
and then *afterwards*, declare the type explicitly like this:
```swift
let strings: Array = ["John", "Paul", "George", "Ringo"]
// notice how there's no error
```
Now, let's see what happens if we use a different type.
```swift
let strings: Dictionary = ["John", "Paul", "George", "Ringo"]
// Error: Dictionary of type 'Dictionary' cannot be initialized with array literal
```
Why did we get an error? Because we gave Swift two conflicting instructions. We said that `strings` is a `Dictionary` but we didn't give it a `Dictionary`, we gave it an Array literal, which is an `Array`. So, which one is it? Is `strings` an Array or a Dictionary? The answer is Dictionary. Notice how the error says `Dictionary of type 'Dictionary' cannot be initialized with array literal` and it doesn't say something like `Array cannot be type casted into Dictionary`.
**The point is that this line has not one but 2 type declarations (explicit on the left, and implicit on the right) and they have to agree with each other. No exceptions.** So remember this principle:
>Swift is a **very** strongly typed language. In other words, it won't allow you to break the rules. Learn how to follow the rules, or your code simply won't compile.
Or a better way of thinking of it is: "Swift's got your back and will protect you from making silly mistakes".
### Generic Types
But we still haven't answered one question, how does `strings` know what the `joined` method is? Is it just a method on `Array`? Nope.
```swift
let strings: Array = ["John", "Paul", "George", "Ringo"]
let oneLongString = strings.joined(separator: ", ") // no Error
let numbers: Array = [3, 4, 5]
let maybeOneLongNumber = numbers.joined(separator: ", ") // Error: No exact matches in call to instance method 'joined'
```
This is because `strings` and `numbers` are not the same type even though they are both `Array`s. `strings` is type `Array` and `numbers` is type `Array`. See those `<`angle brackets`>`? Those are generics. This is because `Array` is a generic type. To illustrate my point, let's look at the definition of Array. Right-click `Array` and choose "Jump to Definition".
```swift
@frozen public struct Array {
// ...
}
```
What's `Element`? It's a [type parameter](https://docs.swift.org/swift-book/documentation/the-swift-programming-language/genericparametersandarguments/). It's kind of like Swift is saying "I have this type called `Array` that can hold some other type (let's call it `Element`), but you, the programmer, get to decide which type `Element` will be". This is why, for some, it might be unhelpful to call this *type inference*. *Type inference* seems to imply that Swift just sort of "figured out" what the type is. But that really isn't what happened. Swift didn't "figure it out", you told Swift what the type was (either explicitly or implicitly).
```swift
let strings = ["John", "Paul", "George", "Ringo"] // implicit type declaration of Array
let numbers: Array = [3, 4, 5] // explicit type declaration
```
> **Tip:** `[String]` is syntactic sugar for `Array`.
> Note that Array is special in that it has [two ways](https://docs.swift.org/swift-book/documentation/the-swift-programming-language/types#Array-Type) to explicitly declare its type. `[String]` and `Array` which both mean the same thing.
The moral of the story is:
>Swift Generics are everywhere in Swift. If you don't understand generics, then you won't understand Swift.
### Think of Swift as your pair programmer
Finally, let's leave you with something that is actually useful for you. SwiftUI often feels magical until you get hit with one of these kinds of errors.
```swift
struct Contact: Identifiable {
let id: UUID
var name: String
}
struct BottomBarView: View {
@State private var contacts = []
var body: some View {
NavigationStack {
List {
ForEach(self.$contacts) { contact in
// 👆🏼 🛑 Cannot convert value of type 'Binding<[Any]>' to expected argument type 'Range'
TextField("Name", text: contact.name)
// 👆🏼 🛑 Value of type 'Int' has no member 'name'
}
}
.navigationTitle("Contacts")
}
}
}
```
Why does Swift think that name is an `Int`. And why is `ForEach` expecting a `Range`? Moments like this can be extremely frustrating. Worse, yet, they are very difficult to search for an answer since you're error message is likely to be too specific to your code. Even worse still, there is no way to debug this problem since our code isn't even compiling. Moments like this can make us want to scream at the compiler, but instead **why don't we try having a *conversation* with it?**
Notice how the first message `Cannot convert value of type 'Binding<[Any]>' to expected argument type 'Range'` starts with `Cannot convert value`? In my experience, **this almost always means that there is some sort of type mismatch**. In other words, the type that I think I'm using and the type that the compiler determines I'm using are actually different types.
>Us: Hey Swift, what is the type?
What is the type of `self.$contacts`? Isn't it `Array`? Swift already knows that it's an Array because I assigned an Array literal (`[]`). But don't forget, `Array` is a generic type. This means that it's actually not complete to say that it's an Array. Let's ask the compiler "What kind of Array is it?" Right-click the `contacts` variable after `@State private var` and choose "Show Quick Help". Hopefully, if Xcode doesn't fail[^1], it should show the following:
```swift
@State var contacts: [Any] { get nonmutating set }
```
[^1]: In my experience, Xcode will often fail when I click "Show Quick Help", instead of displaying "No Quick Help". If you can find any tips to make Quick Help more reliable, please let me know on social media.
>Swift: It's an `[Any]`.
As you can see `contacts` is not a `[Contact]` but instead a `[Any]`. You might say that Swift *inferred the wrong type* but that's not very helpful. I think it's more accurate to say that **we did not give Swift enough information**.
>Us: Actually Swift, could you make sure that is a `[Contact]`, please.
```swift
@State private var contacts: [Contact] = []
```
And *voila* all of the errors should be gone now! Before, we didn't give Swift enough information to know what type contacts was, so Swift essentially had to fallback to a default type. In this case Swift fell back to `[Any]` and this produced a whole host of problems. For example, `ForEach` creates a view for each element in our contacts array, and we named that element `contact`. But because `contacts` was `[Any]` that means `contact` was `Any`, and this produced the error. `Any` has no parameter `name`.
But afterwards we *explicitly* said that the type is `[Contact]`. Now, that Swift has more information, it can tell that `contact` is a `Contact` and therefore has a `name` property.
### Takeaways
Ask yourself "What type does Swift think this variable is and is that the same type I'm expecting."
If your code won't compile, the reason why is often going to be because of an incorrect type somewhere in your code. **Try explicitly declaring the type of your variables to see what will happen.** Many times, this will give Swift just the amount of info that it needs. Other times, you might discover that the type wasn't what you assumed it was. This doesn't mean that you should explicitly type everything, nor does it mean that you should avoid type inference. Type inference in many instances can lead to code that is easier to read, maintain, understand and is even safer.
But sometimes you and Swift will understand each other more if you just talk to each other.
[Next time]({{< ref "concrete-soft-types-in-swift" >}}), we start learning about generics in Swift.
# Hawaiian Vocab
_Hawaiʻian Vocab_ is a thoughtfully designed dictionary for the native Hawaiʻian language. There are 1000 Hawaiʻian words with definitions, pronunciations and example sentences.
## Tech Stack
| Component | Tech |
| ------------ | --------------------------------- |
| Platforms | iOS, iPadOS |
| Architecture | TCA (The Composable Architecture) |
| UI | SwiftUI |
| ORM | GRDB |
## Behind the Scenes
I started building _Hawaiʻian Vocab_ when I saw that there were no modern Hawaiʻian dictionary apps on the App Store. All were either vastly out of date (not even supporting retina screens) or they were missing basic information about the language. After 3 years of studying Hawaiʻian in High School, I wanted to brush up on my vocabulary and
### Getting the Data
My first challenge was to find a suitable data source. Initially, I hoped to pull from Wikipediaʻs free and open Wiktionary dataset. Unfortunately I discovered that their Hawaiʻian word data set is lacking and their data is notoriously unstructured and difficult to parse.
Then I started to experiment with generating my own data using LLMʻs. First I created my own dictionary entries written in simple JSON, then I let the LLM create new entries for me. They were surprisingly up to this task, meanwhile, with my prior knowledge of Hawaiʻian, I was able to make the necessary corrections.
Then I had a large JSON object. I then created a python script to read the JSON from disk and load them into a SQLite database of my design. I then added this SQLite database as a resource in my iOS project, which is read at startup and run by [GRDB](https://swiftpackageindex.com/groue/GRDB.swift).
I chose GRDB because it is very testable and easy to use since itʻs powered entirely by Swift value types. This is made even better because of The Composable Architectures extensive testing tools.
# TCACalc
[GitHub](https://github.com/DandyLyons/TCACalc)
## Tech Stack
| Component | Tech |
| -------------- | --------------------------------- |
| Platforms | iOS |
| Architecture | TCA (The Composable Architecture) |
| Model Paradigm | FSM (Finite State Machine) |
| UI | SwiftUI |
## Behind the Scenes
Partway through development, I discovered that the common calculator is much more complicated than it seems from the outside. The actual calculation is trivial, but they behave differently depending which "mode" they are currently in. This particular problem is best modeled as a Finite State Machine. While TCA is already a state machine, with no implicit side effects, it's states are not finite. With a small bit of extra infrastructure, I was able to implement a FSM in TCA, thus vastly reducing the complexity of the calculator, now that I no longer needed to account for an exponential growth of behavior branch paths.
# How to add Apple’s “Night Mode” to your SwiftUI Views
> **Tip**: Try the code for yourself!
> If you like this, please try the Swift Package that I created called [PlusNightMode]({{}}).
> **Note**:
> I originally posted this blog post to Medium, [here](https://medium.com/@_DandyLyons/how-to-add-apples-night-mode-to-your-swiftui-views-e172bb41dc94).
Screens have propagated to practically every area of our lives and while that has been tremendously beneficial in many ways, it has led [chronic sleep issues](https://healthmatch.io/blog/too-many-of-us-are-sleep-deprived-and-its-become-a-crisis#:~:text=Even%20with%20just%20one%20night,of%20chronic%20conditions%20and%20death.). To address this, Apple and the rest of the tech industry has slowly rolled out a variety of features to tackle this problem. First, there was [Night Shift](https://support.apple.com/en-us/HT207570), [Dark Mode](https://support.apple.com/en-us/HT210332), then [Screen Time](https://support.apple.com/en-us/HT208982). Now in iOS 17, Apple has introduced “Night Mode”, except it’s not in it’s own feature. It’s buried inside of other features ([StandBy](https://www.macrumors.com/how-to/use-standby-mode-iphone/) on iPhone, and the [Wayfinder](https://9to5mac.com/2023/06/07/apple-watch-ultra-auto-night-mode/) watch face on Apple Watch Ultra).

# What is Night Mode?
When I first used StandBy, I was dramatically surprised by how effective it was. For the past decade we’ve been told how light at night wreaks havoc on our circadian rhythm, and in particular blue light. Because of this, many companies added a Night Shift mode that would filter out blue light. While Night Shift does help, and I still have it active on all my devices, it really has been marginally helpful in my life. The truth is that **any light at night is detrimental to our sleep**. Blue light may be worse than other colors, but even a small amount of any light is bad.
And so, I was quite skeptical when I first tried iOS 17’s new Night Mode inside of StandBy. Would it be marginally helpful, like Night Shift? Actually, no. When I placed my iPhone, horizontally, onto my MagSafe charger, it automatically detected that the room was dark and switched the screen into Night Mode. Meanwhile my body still felt sleepy. The screen appeared to have a dramatically smaller effect on my awakeness.
In Night Mode, every single pixel is either pitch black, or a shade of red. And remember, on OLED screens, a pitch black pixel is emitting no light whatsoever. This means that overall the screen is much darker and virtually all blue light is filtered out. In other words, Night Mode is a much more aggressive combination of Dark Mode and Night Shift.
The fact that Apple has rolled out this feature onto two products signals to me that over time Apple will ship this feature across the entire system. I’m looking forward to the day when our devices automatically switch to Night Mode when it’s time to [wind down](https://support.apple.com/guide/iphone/change-wind-period-sleep-goal-iph7d4d2b690/ios) and our screens are far less detrimental to our health.
But we don’t have to wait for that future. Most of the seeds of that future are already built into SwiftUI, and we can fairly easily implement Night Mode inside of our own apps.
# Implementing Night Mode
Dark Mode is built into SwiftUI, so every SwiftUI View supports dark mode by default. So the easiest first step is to simply turn on Dark Mode inside of our SwiftUI Views using `preferredColorScheme(.dark)`.
```swift
struct NightModeView: View {
var body: some View {
NavigationStack {
List {
Image(.blindingWhite)
.resizable()
.frame(maxWidth: .infinity)
.aspectRatio(1.0, contentMode: .fill)
Text("This is a text view")
Text("Blue").foregroundStyle(.blue)
Text("Green").foregroundStyle(.green)
Text("Yellow").foregroundStyle(.yellow)
}
.navigationTitle("Hello World!")
}
.preferredColorScheme(.dark)
}
}
```
[preferredColorScheme(_:)](https://developer.apple.com/documentation/swiftui/view/preferredcolorscheme(_:)) essentially ignores the user’s Dark Mode state, and sets the [ColorScheme](https://developer.apple.com/documentation/swiftui/colorscheme) directly on the View. What’s even better, it changes the `\.colorScheme` environment value, which means that every child View will automatically inherit and observe that colorScheme.
Now the screen is dark but there is still a lot of blue light. (Remember that colors like white and green still contain blue.) Also any Image is unaffected by the colorScheme. (I remember watching The Fellowship of the Ring for the first time in theaters, and being blinded when Frodo first meets Galadriel 😵 because the screen was so bright).
## Implementing a red filter
A naive approach might look like overlaying a red view with 50% opacity like so:
```swift
struct NightModeView: View {
var body: some View {
NavigationStack {
List {
Image(.blindingWhite)
.resizable()
.frame(maxWidth: .infinity)
.aspectRatio(1.0, contentMode: .fill)
Text("This is a text view")
Text("Blue").foregroundStyle(.blue)
Text("Green").foregroundStyle(.green)
Text("Yellow").foregroundStyle(.yellow)
}
.navigationTitle("Hello World!")
}
.preferredColorScheme(.dark)
.overlay {
Color.red.opacity(0.5)
.ignoresSafeArea()
}
}
}
```
However, while that does indeed turn the screen red (and thereby filter out most of the blue), it actually makes the screen brighter. Before the background was pitch black but now it’s red.
So we want to keep all black pixels black, but we want all the other colors to be a shade of red. 🤔 Thankfully, digital photo editors solved this problem long ago, and SwiftUI has added many of the same functions that we’ve been using in Photoshop for decades. I played around with a few of them and here is my best result so far:
```swift
struct NightModeView: View {
var body: some View {
NavigationStack {
List {
Image(.blindingWhite)
.resizable()
.frame(maxWidth: .infinity)
.aspectRatio(1.0, contentMode: .fill)
Text("This is a text view")
Text("Blue").foregroundStyle(.blue)
Text("Green").foregroundStyle(.green)
Text("Yellow").foregroundStyle(.yellow)
NavigationLink("Go to second page", value: "second page")
}
.navigationTitle("Hello World!")
.navigationDestination(for: String.self) { string in
Text(string)
}
}
.monochromed(color: .red)
}
}
extension View {
func monochromed(color: Color, colorScheme: ColorScheme = .dark) -> some View {
let filter: some View = color
.blendMode(.color)
.opacity(0.5)
.allowsHitTesting(false)
return self
.preferredColorScheme(colorScheme)
.tint(color)
.overlay {
filter
.ignoresSafeArea()
}
.colorMultiply(color)
}
}
```
Wow, I feel like I turned my iPhone into a [VirtualBoy](https://vrscout.com/news/27-years-later-and-the-virtual-boy-still-refuses-to-die%EF%BF%BC/)!
Let’s explain how we did this. I made a new function called `monochromed(color: colorScheme:)` so in the future we can add Night Mode with a single line of code. The `color:` parameter is what color we want the whole screen to be. In our case, we’ll use `.red` . Next, the `colorScheme:` can be light or dark but it defaults to dark.
`monochromed(color:)` essentially does the same thing as our earlier example. It overlays a red View. However, the View that it overlays is slightly more sophisticated. First we start off with the same red view. Then we add [.blendMode(.color)](https://developer.apple.com/documentation/swiftui/view/blendmode(_:)). Like many functions we’ll be using here, [blend mode](https://en.wikipedia.org/wiki/Blend_modes) should be fairly familiar to anyone who’s worked in photo editors. Trailing Closure has a fantastic [cheat sheet](https://trailingclosure.com/blendmode-cheat-sheet/) about all the available blend modes in SwiftUI. In it we can see:
> `.color`
>
> The Color blend mode preserves the luma of the bottom layer, while adopting the hue and chroma of the top layer.
🤷🏼♂️ i.e. It blends the colors together.
`opacity(0.5)` I played around with the opacity of this filter a bit and so far 50% was my favorite. 100% made everything too bright red, and 25% didn’t filter out other colors enough.
`.colorMultiply(color)` : This [SwiftUI function](https://developer.apple.com/documentation/swiftui/view/colormultiply(_:)) adds a [color multiplication effect](https://en.wikipedia.org/wiki/Blend_modes#Multiply_and_Screen). This is in fact another blend mode that we can find in most photo editors. Wikipedia states:
> Multiply blend mode takes the RGB channel values from 0 to 1 of each pixel in the top layer and multiples them with the values for the corresponding pixel from the bottom layer. Wherever either layer was brighter than black, the composite is darker; since each value is less than 1, their product will be less than each initial value that was greater than zero.
Again 🤷🏼♂️. But my very limited understanding is that this is what enables the black pixels to remain black. A black pixel has an RGB channel value of 0. So anything multiplied by 0 is 0, i.e. black pixels stay black. Notice that `.colorMultiply` is applied to the View itself and not the overlayed filter View. Next let’s look at a few quality of life improvements.
`.allowsHitTesting(false)` : If we didn’t have this then no touch events would reach our Views at all, since we’d be touching the red filter view and not the views underneath.
`.tint(color)` : We are essentially filtering out every color except for red. So why not change the tint of our app to match, so that it doesn’t get filtered out. This is extra important because the default tint color in SwiftUI is blue. Remember, the entire point of a Night Mode is to filter out blue light, so by monochroming to red, we are effectively filtering out blue. Anything that is not red is going to be harder to see, and the further it is from red, the less visible it will be, meaning that blue is practically invisible now. The entire point of [tint in SwiftUI](https://developer.apple.com/documentation/swiftui/view/tint(_:)-23xyq) is to highlight certain elements to the user. So while using our filter, it makes sense to match our tint to the color of the filter so that our tinted elements remain highly visible.
## Room for improvement
As much as I love Night Mode, and I impatiently wait for Apple to roll out Night Mode everywhere, it makes sense that Apple has only rolled out this feature to two small niche areas. **Design systems are hard**. As we can see there are many edge cases. We’ve covered many edge cases so far. For example, this solution now effectively turns every pixel in every SwiftUI View into either black or a shade of red. However, it creates new problems. Anything blue is effectively invisible, rendering many apps unusable. In addition, many Views will lose contrast and legibility. For example, look at the green Text. It’s still visible, but it is much harder to read. These are all design problems that we will work on as an industry over the next several years.
I expect that the industry will slowly have a transition to supporting Night Mode everywhere, just as we are still transitioning to supporting Dark Mode everywhere. Dark Mode used to be extremely difficult to adopt in UIKit, but with SwiftUI, Apple made it trivial. Now Dark Mode is not just on Apple and Android apps, but it’s almost everywhere, even in our operating systems and many websites. I hope that one day soon, Apple sherlocks this implementation and simply makes it a baked in part of the system. I also hope that over time Night Mode will be adopted everywhere. But we must recognize that that is a gargantuan task. It will require designers and engineers everywhere to change their workflow, and the transition will take years.
Is all of that work worth it? Absolutely, yes! Screens are here to stay, whether we like it or not. Yet we are currently in the middle of a [sleep deprivation crisis](https://www.ncbi.nlm.nih.gov/pmc/articles/PMC6473877/). For more information on how important sleep is, and how disasterous light from devices can be, I highly recommond [this podcast by Andrew Huberman](https://www.youtube.com/watch?v=h2aWYjSA1Jc). The point is that users shouldn’t have to choose between your wonderful app and their sleep. And we shouldn’t be making software that negatively impacts our user’s health. Period.
Thankfully, there is a solution, and it’s not that hard to implement. It’s not perfect, but it’s a start. Do your users a favor and adopt the option for Night Mode. And do yourself a favor. Adopt Night Mode. I wouldn’t be surprised if Night Mode becomes very popular in the near future, just like Dark Mode. If so, then many users will crave, no, demand Night Mode. Night Mode could not only differentiate you from other apps, it could actually be the thing preventing users from choosing your app. Let me be clear. I don’t want to give you false hype. Night Mode is not a silver bullet, just as Night Shift and Dark Mode were not silver bullets. But soon Night Mode will be another important tool in our tool belt toward building healthy sleep. You’d be a fool not to adopt it.
# Conclusion
In this tutorial we learned how incredibly harmful device lights can be to your sleep and therefore health. We saw how Apple made a powerful filter called Night Mode that we too can adopt with a few lines of code.
I’ve created a [public gist](https://gist.github.com/DandyLyons/36cd8c126d6c648c361307bccf5feca4) where you can try out this implementation for yourself. If you like it, please ⭐ Star it.
Next time, we will learn how to make our Night Mode more dynamic so that the user can turn it on and off. We will also learn how to tell child views that they are in Night Mode so that they can present themselves more legibly.
# How to use a JS for...of loop with an index
> **Note**:
> I originally posted this blog post to Medium, [here](https://medium.com/@_DandyLyons/how-to-use-a-js-for-of-loop-with-an-index-a4675ed22351).
JavaScript’s `for...of` loop is a powerful construct for iterating over elements in an [iterable](https://developer.mozilla.org/en-US/docs/Web/JavaScript/Reference/Iteration_protocols#built-in_iterables), such as arrays, strings, or [other iterable objects](https://developer.mozilla.org/en-US/docs/Web/JavaScript/Reference/Iteration_protocols#built-in_iterables:~:text=iterables%20and%20iterators.-,Built%2Din%20iterables,-String%2C%20Array). However, unlike the traditional [C-style for loop](https://developer.mozilla.org/en-US/docs/Web/JavaScript/Reference/Statements/for), **the** `for...of` **loop doesn't provide a built-in index**. But fear not! In this blog post, we'll learn how to use the `for...of` loop with an index.
## The Traditional `for...of` Loop
Before diving into adding an index, let’s quickly review how the standard `for...of` loop works:
```js
const nums = [10, 20, 30, 40, 50];
for (const num of nums) {
console.log(num);
}
```
This loop will iterate through ==`nums`== and print each element to the console. However, if you need to keep track of the index as well, you can modify the loop…
## Adding an Index to the `for...of` Loop
To add an index to the `for...of` loop, you can use the [entries()](https://developer.mozilla.org/en-US/docs/Web/JavaScript/Reference/Global_Objects/Array/entries) method of an array, which returns an iterable containing index-value pairs. Here's how you can do it:
```js
const nums = [10, 20, 30, 40, 50];
for (const [index, num] of nums.entries()) {
console.log(`Index: ${index}, Value: ${num}`);
}
```
In this modified loop, we use the `entries()` method to get an iterable of index-value pairs, and then we [destructure](https://developer.mozilla.org/en-US/docs/Web/JavaScript/Reference/Operators/Destructuring_assignment) each pair into `index` and `num`. Now, you have access to both the index and the value during each iteration.
## Output
```
Index: 0, Value: 10
Index: 1, Value: 20
Index: 2, Value: 30
Index: 3, Value: 40
Index: 4, Value: 50
```
With this approach, you can easily work with both the elements and their respective indices when using the `for...of` loop.
## Considerations
Be aware that the `entries()` method used above loops through the array once with an efficiency of `O(n)`. So if you have a very large array, you will notice a performance cost. As with everything else, there are tradeoffs. Personally, I think readability and maintainability are worth a negligible performance cost. For example, this style of for loop makes it all but impossible to commit the subtle [Off-by-one error](https://en.wikipedia.org/wiki/Off-by-one_error). The best code is the code you never have to write in the first place, and if you eliminate the need to check for an off-by-one error in the first place, then I think that’s a great tradeoff.
Nevertheless, if you’re dealing with strict performance constraints, weak hardware, or massive datasets, then you should certainly consider using the C-style for loop.
## Conclusion
JavaScript’s `for...of` loop is a versatile way to iterate over iterable objects. By leveraging the `entries()` method, you can easily include an index alongside the values in your loops. This can be especially useful when you need to perform operations that require knowledge of the element's position within the iterable. Happy coding!
# PlusNightMode
## Available at
- [GitHub](https://github.com/DandyLyons/PlusNightMode)
- [Swift Package Index](https://swiftpackageindex.com/DandyLyons/PlusNightMode)
## Tech Stack
| Component | Tech |
| ------------ | --------------------- |
| Platforms | iOS, iPadOS |
| UI | SwiftUI |
| Distribution | Swift Package Manager |
## Developer Diary
- [How to add Apple’s “Night Mode” to your SwiftUI Views]({{< ref "implement-swiftui-night-mode" >}})
# 7 Ways to Organize SwiftUI Code
> NOTE:
> I originally posted this blog post to Medium, [here](https://medium.com/@_DandyLyons/7-ways-to-organize-swiftui-code-e786307d3916).
SwiftUI is a complete paradigm shift in how we write apps for Apple platforms. It’s functional and declarative rather than object-oriented and imperative. And there is no need for ViewControllers anymore! While all of this means that we can write code that is more readable, testable, and reusable, it also means that we don’t have decades of tried and true architecture patterns to draw from.
Thankfully SwiftUI makes it easy to break apart your code into reusable components. Today, I’d like to explore all the ways I’ve found to organize SwiftUI code. (Actually, I’m not so much talking about the architecture. Instead, right now I’d like to explore the different techniques we can use to split SwiftUI code into smaller, more manageable piece.)
## A Bad Example
Throughout this blog post, I’ll be looking at an example of “bad” SwiftUI code. This code is bad, not because it’s non-performant. It’s actually just as performant as all of the later, examples. Neither is it bad because it’s verbose. It’s actually quite short. Only 27 lines of code. No, this code is bad because it’s really confusing to read:
```swift
struct NestedListExample: View {
@State var notificationsOn: Bool = false
@State var soundOn: Bool = true
@State var hapticsOn: Bool = true
var body: some View {
NavigationView {
List {
NavigationLink("Settings", destination:
List {
NavigationLink("Notifications", destination:
List {
Toggle("Notifications: ", isOn: $notificationsOn)
}.navigationTitle("Notifications")
)
NavigationLink("Sound and Haptics", destination:
List {
Toggle("Sound: ", isOn: $soundOn)
Toggle("Haptics: ", isOn: $hapticsOn)
}.navigationTitle("Notifications")
)
}.navigationTitle("Settings")
)
}
.navigationTitle("1st List")
}
}
}
```
This monstrosity, is technically valid SwiftUI code, but I wouldn’t recommend using it. It’s three layers deep of nested `List`s. Let’s look at how we can split it into smaller pieces that are easier to read, reason, test, reuse and maintain.
## Your SwiftUI App is just one giant View
First, let’s look at that these two templates that we’ve see a million times:
```swift
// ExampleApp.swift
import SwiftUI
@main
struct ExampleApp: App {
var body: some Scene {
WindowGroup {
ContentView()
}
}
}
```
```swift
// ContentView.swift
import SwiftUI
struct ContentView: View {
var body: some View {
Text("Hello, world!")
.padding()
}
}
```
Pardon me for stating the obvious, `ExampleApp`calls `ContentView()`which means that if you wanted to you could condense `ExampleApp` and `ContentView`into one file like this:
```swift
// ExampleApp.swift
import SwiftUI
@main
struct ExampleApp: App {
var body: some Scene {
WindowGroup {
Text("Hello, world!")
.padding()
}
}
}
```
A SwiftUI app is really just an `App` holding a `Scene`, holding a `View`, holding a `View`, holding a `View`, etc. In fact, you could run your entire app from one file. **Obviously, I wouldn’t recommend this.** But just knowing that we can shows us the first way to split SwiftUI code.
## Seven Ways To Split Your SwiftUI Code
## Method #1: Extract To Separate Struct
If we look at my combined `ExampleApp` implementation, and Apple’s template of `ExampleApp` and `ContentView` we can see that Apple extracted `Text("Hello, world!").padding()` out into its own `View` struct called `ContentView`. We can follow this pattern for any of our views.
Let’s look at how we could use this in our monster List example from earlier:
```swift
// NestedListExample.swift
struct NestedListExample: View {
@State var notificationsOn: Bool = false
@State var soundOn: Bool = true
@State var hapticsOn: Bool = true
var body: some View {
NavigationView {
List {
NavigationLink("Settings", destination:
SettingsView(notificationsOn: $notificationsOn, soundOn: $soundOn, hapticsOn: $hapticsOn)
)
}
.navigationTitle("1st List")
}
}
}
// NotificationsView.swift
struct NotificationsView: View {
@Binding var notificationsOn: Bool
var body: some View {
List {
Toggle("Notifications: ", isOn: $notificationsOn)
}.navigationTitle("Notifications")
}
}
// SettingsView.swift
struct SettingsView: View {
@Binding var notificationsOn: Bool
@Binding var soundOn: Bool
@Binding var hapticsOn: Bool
var body: some View {
List {
NavigationLink("Notifications", destination:
NotificationsView(notificationsOn: $notificationsOn)
)
NavigationLink("Sound and Haptics", destination:
SoundAndHapticsView(soundOn: $soundOn, hapticsOn: $hapticsOn)
)
}.navigationTitle("Settings")
}
}
// SoundAndHapticsView.swift
struct SoundAndHapticsView: View {
@Binding var soundOn: Bool
@Binding var hapticsOn: Bool
var body: some View {
List {
Toggle("Sound: ", isOn: $soundOn)
Toggle("Haptics: ", isOn: $hapticsOn)
}.navigationTitle("Notifications")
}
}
```
🙀 Ay caramba! Now the code is even longer and more confusing! Well actually no. This new code is far more readable. There’s no longer a pyramid of doom.
Also, it’s easier to maintain and edit. What if your designer designer said to you “Actually, could you please move the notifications onto the sound page?” Now it is much easier to simply paste `NotificationsView()` wherever you want to use it.
Yes this new code is quite a bit longer (54 lines as opposed to just 27 lines before) but shorter is not always better, especially if it means making your code less readable.
Still, this approach does have a drawback. Every nested struct loses access to its parent’s properties, which means that we have to pass in a binding into each struct. While this method is great at separating our Views into smaller pieces, some times it adds more friction than it’s worth. Let’s look at some other methods.
> **Quick Tip:** Let Xcode do at least some of the work for you. If you ⌘-Click any subview and choose `Extract subview` then Xcode will create the separate struct for you! Wow! But bear in mind it won’t create any properties that you will need. At least it can do a lot of the busywork for you.
## Method #2: Extract To Local Computed Property
Looking more at all over our SwiftUI code we can see that every single View contains `var body: some View`. Don’t let SwiftUI’s “magic” fool you. It’s not magic at all. This is just a plain old computed property which is built into the Swift language. So:
```swift
var body: some View {
Text("Hello World!")
}
Is really just short for:
var body: some View {
get {
return Text("Hello World!")
}
}
```
We can use this exact same approach anywhere in our code. For example like this:
```swift
struct NestedListExample: View {
@State var notificationsOn: Bool = false
@State var soundOn: Bool = true
@State var hapticsOn: Bool = true
var body: some View {
NavigationView {
List {
NavigationLink("Settings", destination:
settings
)
}
.navigationTitle("1st List")
}
}
var settings: some View {
List {
NavigationLink("Notifications", destination:
notifications
)
NavigationLink("Sound and Haptics", destination:
soundAndHaptics
)
}.navigationTitle("Settings")
}
var notifications: some View {
List {
Toggle("Notifications: ", isOn: $notificationsOn)
}.navigationTitle("Notifications")
}
var soundAndHaptics: some View {
List {
Toggle("Sound: ", isOn: $soundOn)
Toggle("Haptics: ", isOn: $hapticsOn)
}.navigationTitle("Notifications")
}
}
```
Once again, our code is more readable, but notice that this time we didn’t have to pass any `Binding`s. Why? Because everything is inside the same struct. It can just read the same properties that are already there.
## Method #3: Extract To A Function
Remember before that we extracted our subview out into a computed property? Well what is a computed property? Really, it’s just a function. So:
```swift
var soundAndHaptics: some View {
List {
Toggle("Sound: ", isOn: $soundOn)
Toggle("Haptics: ", isOn: $hapticsOn)
}.navigationTitle("Notifications")
}
```
can be rewritten as:
```swift
func soundAndHaptics() -> some View {
List {
Toggle("Sound: ", isOn: $soundOn)
Toggle("Haptics: ", isOn: $hapticsOn)
}.navigationTitle("Notifications")
}
```
It’s basically exactly the same thing. In fact, the compiler thinks it’s the exact same thing. If you include both of these definitions, then the compiler will say `Invalid redeclaration of 'soundAndHaptics()'`which means that a computed property is really just another function under the hood.
However, there is a difference at the call site. If you declare it as a computed variable then you will call it with `soundAndHaptics`. But if you declare it as a func then you will call it with `soundAndHaptics()`. The extra `()` tells Swift that we are running that function inline and immediately using the returned View.
Still, I probably wouldn’t use this extraction method very often. Why? Semantics. When I think of a func, I think of verbs. When I think of a var I think of nouns. In my brain, `View`s are nouns.
==However, one difference between a func and a computed property is that computed properties can’t accept parameters. But a func can. So we could write something like this:==
```swift
func soundAndHaptics(isPremiumUser: Bool) -> some View {
let anyView: AnyView
if isPremiumUser {
anyView = List {
Toggle("Sound: ", isOn: $soundOn)
Toggle("Haptics: ", isOn: $hapticsOn)
}.navigationTitle("Notifications") as! AnyView
} else {
anyView = List {
Toggle("Sound: ", isOn: $soundOn)
// Haptics are not included for non premium users
}.navigationTitle("Notifications") as! AnyView
}
return anyView
}
```
Now that we’re using a func instead of a computed property, we can add more logic to dynamically change the View as necessary. (There are better ways to achieve that variability, but it’s nice to know that this is another tool in the toolbox.)
## Method #4: Extract To an @ViewBuilder Function
If you’ve been paying attention then that last method must have left a bad taste in your mouth. _Why is he using AnyView?_ Anytime, you see AnyView, it’s a sign that there’s probably a better way to do what you’re trying to do. And oftentimes that better way is `@ViewBuilder`. Let’s look at how we can use `@ViewBuilder` to clean up our last example.
```swift
@ViewBuilder
func soundAndHaptics(isPremiumUser: Bool) -> some View {
if isPremiumUser {
List {
Toggle("Sound: ", isOn: $soundOn)
Toggle("Haptics: ", isOn: $hapticsOn)
}.navigationTitle("Notifications")
} else {
List {
Toggle("Sound: ", isOn: $soundOn)
// Haptics are not included for non premium users
}.navigationTitle("Notifications")
}
}
```
Now, Swift no longer complains. We don’t have to type erase with AnyView anymore. John Sundell does a great job of explaining this here: Avoiding SwiftUI’s AnyView
This method is used extensively in Apple’s own SwiftUI framework. Take a look at the declaration of VStack. It’s initializer accepts a parameter called `content` that looks like this: `@ViewBuilder content: () -> Content`This is just a function, just like the one we just made. And as we can see in the declaration of VStack here:
`@frozen struct VStack where Content : View`
Content is just a generic name for any type that conforms to View.
So while @ViewBuilder functions might be somewhat useful when we want to separate a subview, they are way more useful when we want to accept a @ViewBuilder from someone else.
## Method #5: Extract To an @ViewBuilder Computed Property
It’s worth mentioning that computed properties can also be wrapped in a `@ViewBuilder`. `@ViewBuilder` is just a `@resultBuilder`. `@ResultBuilder` ’s can be applied to functions, and since computed properties are basically functions under the hood, that means you can use `@ViewBuilder` on a computed property!
So we can rewrite:
```swift
// func version
@ViewBuilder
func soundAndHaptics(isPremiumUser: Bool) -> some View {
if isPremiumUser {
List {
Toggle("Sound: ", isOn: $soundOn)
Toggle("Haptics: ", isOn: $hapticsOn)
}.navigationTitle("Notifications") as! AnyView
} else {
List {
Toggle("Sound: ", isOn: $soundOn)
// Haptics are not included for non premium users
}.navigationTitle("Notifications") as! AnyView
}
}
```
into:
```swift
// computed variable version
@ViewBuilder
var soundAndHaptics: some View {
if isPremiumUser {
List {
Toggle("Sound: ", isOn: $soundOn)
Toggle("Haptics: ", isOn: $hapticsOn)
}.navigationTitle("Notifications")
} else {
List {
Toggle("Sound: ", isOn: $soundOn)
// Haptics are not included for non premium users
}.navigationTitle("Notifications")
}
}
```
Now our computed variable can use any logic that we need just like the function version. Plus, we don’t even need to pass in a parameter, as long as `isPremiumUser` is in the same struct.
## Method #6: Extract To static func or var
Of course, if a View can be a var or a func, then that also means that it can be a static var or func. Something like this:
```swift
// static var
@ViewBuilder
static var exampleTableCell: some View {
List {
Text("Hello")
}
}
// static func
@ViewBuilder
static func exampleToggle(_ binding: Binding) -> some View {
List {
Toggle("Toggle", isOn: binding)
}
}
```
This method can be really helpful for adding in example View’s when you are still prototyping. Just remember that any static var or func, won’t be able to use any of your instance variables like our `isPremiumUser` variable from earlier.
## Method #7: Extract To A Style
What if I want to create a View that has some customization, but I still want to keep some of the uniformity of the built-in Views? For example, what if I have a Button that has some custom styling. Here’s a simple example:
```swift
struct RedCircleButton: View {
let string: String
let action: () -> Void
var body: some View {
Button(string, action: action)
.clipShape(Circle())
.foregroundColor(.red)
}
}
```
Now my button is very reusable. But I’ve sacrificed customizability. What if I want to use a View as my label instead of a String? Thankfully, SwiftUI has a solution to this as well: Styles. Many SwiftUI views come Style types. These let you call a normal built-in type, and place all your custom styling in your “Style” Type. For example:
```swift
struct RedCircleButtonStyle: ButtonStyle {
public func makeBody(configuration: RedCircleButtonStyle.Configuration) -> some View {
RedCircleButton(configuration: configuration)
}
struct RedCircleButton: View {
let configuration: RedCircleButtonStyle.Configuration
var body: some View {
configuration.label
.foregroundColor(.red)
.clipShape(Circle())
}
}
}
```
And to use it we just write:
```swift
Button("Some String") { print("Do something")}
.buttonStyle(RedCircleButtonStyle())
```
SwiftUI comes with many style protocols including `ButtonStyle`, `ListStyle`, `PickerStyle` , you get the picture.
## The Right Method for the Job
Those are all the methods of splitting SwiftUI code that I’ve found. Have you found anymore that I should add?
With so many options for splitting code. How do we know which to use when? First, don’t overthink it. Thankfully, SwiftUI makes it much easier to split and refactor code than UIKit. We don’t have massive ViewControllers with complex side effects to think about (but it is our responsibility, to separate View and Model logic). Here are my suggestions of when to use each of these methods:
- **Method #1: Extract To Separate Struct**: Use when you want something, custom and reusable.
- **Method #2: Extract To Local Computed Property:** Use when you want something private and internal.
- **Method #3: Extract To A Function:** Also works for something private and internal, but personally I would prefer a computed property for that use case.
- **Method #4: Extract To an @ViewBuilder Function**: Great for when you want to enable another View to pass you a View.
- **Method #5: Extract To an @ViewBuilder Computed Property:** Great for when you need something internal and private, that also has some internal logic, especially if you need to erase Type.
- **Method #6: Extract To static func or var:** Great for when you want mock example Views.
- **Method #7: Extract To A Style**: Great for when you only want to extract custom styling but not custom logic.
I’m sure there are many use cases that are not listed here but I hope it’s a good starting point. Now get out there and start organizing your SwiftUI code!
#
# Building md-utils: Architecture, Parsing, and Working with AI Coding Agents
md-utils is a CLI and Swift library for structurally manipulating Markdown files — frontmatter CRUD, section extraction and reordering, heading adjustment, wikilink resolution, and more. This post is about how it was built: the architecture decisions, the parsing strategy, the dependency choices, the testing approach, and how AI coding agents fit into the development workflow.
## Motivation
I manage a large Obsidian vault. Over time I kept running into the same friction: I needed to batch-update frontmatter fields, check for broken wikilinks, extract sections, reorder content. Obsidian is great as an editor, but it doesn't expose these operations as scriptable commands. And the existing Markdown CLI tools — pandoc, remark, marked — are renderers. They convert Markdown to other formats. They don't help you manipulate Markdown *as Markdown*.
What I wanted was a tool that understands Markdown as a structured document: YAML frontmatter as typed data, headings as a hierarchy that defines sections, wikilinks as resolvable references. And I wanted it as both a CLI for scripting and a library for programmatic use.
## Architecture Decisions
### Two Products, One Repository
md-utils ships two products from a single Swift package:
1. **`MarkdownUtilities`** — a library with zero CLI dependencies
2. **`md-utils`** — a CLI built on top of that library
This separation is intentional. The library knows nothing about `ArgumentParser`, terminal I/O, or file system traversal for batch processing. It operates on strings and data structures. The CLI handles argument parsing, file discovery, output formatting, and error reporting.
The practical benefit: anyone can add `MarkdownUtilities` as an SPM dependency and get frontmatter parsing, section extraction, wikilink resolution, and everything else without pulling in CLI infrastructure.
### MarkdownDocument: The Central Type
Everything flows through `MarkdownDocument`:
```swift
public struct MarkdownDocument: @unchecked Sendable {
public var frontMatter: Yams.Node.Mapping
public var body: String
}
```
Two fields. That's it. The frontmatter is a `Yams.Node.Mapping` and the body is a `String`. All operations — frontmatter mutation, section extraction, heading adjustment, wikilink scanning — are extensions on this type.
### Why Yams.Node.Mapping Instead of [String: Any]
This was a deliberate choice. When you parse YAML into `[String: Any]`, you lose information:
- **Key ordering** — YAML mappings have meaningful order. `[String: Any]` (a `Dictionary`) doesn't preserve insertion order. If someone carefully ordered their frontmatter keys (`title`, `author`, `date`, `tags`), you want to preserve that.
- **YAML tags and structure** — `Yams.Node` preserves the full YAML representation: scalar styles, tags, comments adjacent to nodes. Round-tripping through `[String: Any]` destroys this.
- **Type fidelity** — `Any` requires casting everywhere. `Node.Mapping` gives you `Node` values that you can pattern-match on (`.scalar`, `.mapping`, `.sequence`).
The tradeoff is that `Node.Mapping` is less ergonomic than a dictionary for simple lookups. But for a tool that reads, modifies, and writes back frontmatter, preserving structure matters more than convenience.
### Feature-Focused Module Organization
The library is organized by feature, not by layer:
```
Sources/MarkdownUtilities/
├── MarkdownDocument.swift
├── FrontMatter/
├── TOC/
├── FormatConversion/
├── HeadingAdjustment/
├── SectionExtraction/
├── SectionReordering/
├── Wikilink/
├── FileMetadata/
└── Helpers/
```
Each directory contains the types, parsers, and `MarkdownDocument` extensions for that feature. `FrontMatter/` has `FrontMatterParser`, `YAMLConversion`, and the mutation extensions. `Wikilink/` has the parser, scanner, resolver, and document extensions. You can understand a feature by reading one directory.
## Dependency Choices
Six direct dependencies, each chosen for a specific reason:
### swift-parsing (Point-Free)
Used for `FrontMatterParser` and `WikilinkParser`. Point-Free's [swift-parsing](https://github.com/pointfreeco/swift-parsing) library provides declarative, composable parser combinators. Compare this to the regex alternative:
```swift
// swift-parsing: declarative, composable, testable
private var frontMatterOnlyParser: some Parser {
Parse {
"---\n"
PrefixUpTo("---").map { String($0) }
"---"
Optionally { "\n" }
}
.map { (frontMatter, _) in frontMatter }
}
```
vs.
```swift
// Regex: fragile, hard to extend
let pattern = /^---\n([\s\S]*?)---\n?/
```
The parser combinator approach composes. `WikilinkParser` handles `[[target]]`, `[[target|display]]`, `![[embed]]`, `[[page#heading]]`, `[[page#^blockID]]`, and combinations — all built from small, testable pieces. The regex for the same grammar would be a maintenance nightmare.
### MarkdownSyntax (wrapping swift-cmark)
[MarkdownSyntax](https://github.com/hebertialmeida/MarkdownSyntax) provides AST parsing — turning Markdown body text into a tree of headings, paragraphs, code blocks, links, etc. It wraps the C `swift-cmark` library (the reference CommonMark parser) with Swift-native types. Used for TOC generation, heading adjustment, and format conversion.
### Yams
[Yams](https://github.com/jpsim/Yams) is the standard YAML library in the Swift ecosystem. Mature, widely used (SwiftLint depends on it), and critically, it exposes the `Node` type that preserves YAML structure. The frontmatter pipeline is: raw string → `Yams.compose()` → `Node.Mapping`.
### swift-argument-parser
Apple's [swift-argument-parser](https://github.com/apple/swift-argument-parser) is the standard choice for Swift CLIs. It supports async commands (`AsyncParsableCommand`), which md-utils needs for operations that go through the async MarkdownSyntax parser.
### PathKit
[PathKit](https://github.com/kylef/PathKit) provides a clean `Path` type for file system operations. Used throughout the CLI for batch processing — directory traversal, extension filtering, path resolution.
### jmespath.swift
[jmespath.swift](https://github.com/adam-fowler/jmespath.swift) implements JMESPath, a query language for JSON. Powers the `fm search` command, which lets you find files whose frontmatter matches a query expression. This is a CLI-only dependency — the library doesn't depend on it.
## How Text is Parsed
md-utils has multiple parsing layers, each handling a different level of the document:
### Layer 1: FrontMatter Separation
`FrontMatterParser` (a `swift-parsing` parser) splits the raw document into two strings: the YAML frontmatter content (between `---` delimiters) and the body (everything after).
```
--- ← opening delimiter
title: Hello ← raw frontmatter string
tags: [a, b]
--- ← closing delimiter
# Body ← body string
Content here
```
If there's no opening `---`, the entire document is body and frontmatter is empty.
### Layer 2: YAML Parsing
`YAMLConversion` passes the raw frontmatter string to `Yams.compose()`, which returns a `Yams.Node`. We then validate it's a `.mapping` (not a scalar or sequence — frontmatter should always be key-value pairs) and extract the `Node.Mapping`.
### Layer 3: Wikilink Parsing
`WikilinkParser` is another `swift-parsing` combinator that handles the full Obsidian wikilink grammar:
- `[[target]]` — basic link
- `[[target|display text]]` — aliased link
- `[[page#heading]]` — heading anchor
- `[[page#^blockID]]` — block reference
- `![[embed]]` — embedded content
- Escaped pipes (`\|`) in targets
`WikilinkScanner` uses this parser to find all wikilinks in a string. `WikilinkResolver` takes a vault root directory, builds a file index, and resolves each wikilink target against it — detecting broken links (no match) and ambiguous links (multiple matches).
### Layer 4: Markdown AST
`MarkdownSyntax` (wrapping `swift-cmark`) parses the body text into a full AST. This powers TOC generation (extracting heading hierarchy), heading adjustment (modifying heading levels), and format conversion (walking the tree to produce plain text or CSV). AST parsing is async because `MarkdownSyntax` uses async APIs internally.
## Testing with Swift Testing
md-utils has 718 tests, all using Apple's native [Swift Testing](https://developer.apple.com/documentation/testing/) framework — not XCTest.
### Why Swift Testing
Swift Testing is newer, more expressive, and better aligned with modern Swift. The key advantages for this project:
- **`#expect` and `#require` macros** — cleaner assertion syntax with better failure messages than `XCTAssertEqual`
- **Backtick naming** — test functions named with backticks read as documentation
- **`@Suite` grouping** — logical test organization without subclassing
- **`try #require()`** — safe optional unwrapping that fails the test with a clear message, replacing `XCTUnwrap`
### Test Style
Tests use backtick identifiers for readable names:
```swift
@Suite("FrontMatterParser Tests")
struct FrontMatterParserTests {
@Test
func `Parse document with valid frontmatter`() async throws {
let content = "---\ntitle: Hello\n---\n# Body"
let doc = try MarkdownDocument(content: content)
let title = try #require(doc.getValue(forKey: "title"))
#expect(title == "Hello")
}
@Test
func `Parse document with no frontmatter`() async throws {
let content = "# Just a heading"
let doc = try MarkdownDocument(content: content)
#expect(doc.frontMatter.isEmpty)
#expect(doc.body == content)
}
}
```
Every test is marked `async throws` even if it doesn't use async operations — this keeps the signature uniform and avoids refactoring when a test later needs to call an async API.
## CLI Design Patterns
### GlobalOptions via @OptionGroup
Every CLI command includes shared options through a single `@OptionGroup`:
```swift
struct MyCommand: AsyncParsableCommand {
@OptionGroup var options: GlobalOptions
// command-specific arguments...
}
```
`GlobalOptions` provides `paths`, `recursive`, `includeHidden`, `extensions`, and `noSort`. The `resolvedPaths()` method expands directories, applies filters, and returns the final list of files to process. This means every command gets batch processing for free — point it at a directory and it just works.
### Consistent Batch Processing
All commands follow the same pattern: resolve paths, iterate, process each file. Commands that modify files have `--in-place` flags. Commands that output data handle single-file output (direct) and multi-file output (cat-style headers) automatically.
### Stdin Support
Commands accept piped input, so you can compose md-utils with other tools:
```bash
md-utils extract --name "API" doc.md | md-utils convert to-text
```
## Using AI Coding Agents
AI coding agents were one tool in the development workflow for md-utils, alongside the compiler, the test suite, and documentation. I used [Claude Code](https://docs.anthropic.com/en/docs/claude-code) as the primary agent for this project. Other agents in the same category — OpenAI's Codex, Google's Gemini Code Assist, OpenCode — are worth experimenting with. This is a rapidly evolving space and no single tool has a lock on it.
### What Worked Well
**Rapid feature scaffolding.** When adding a new command — say `fm array append` — the agent could generate the `AsyncParsableCommand` struct, the argument declarations, the `run()` method, and a full test suite in one pass. The boilerplate-to-logic ratio in CLI commands is high, and agents handle boilerplate well.
**Test generation.** Given an implementation, the agent could produce comprehensive test cases covering happy paths, edge cases, and error conditions. The 718 tests in the project were largely agent-generated, then reviewed and adjusted.
**Exploring unfamiliar APIs.** I hadn't used Point-Free's `swift-parsing` library before. The agent could write parser combinators, explain how `PrefixUpTo` and `Parse` compose, and generate working parsers faster than I could have by reading docs alone.
### Friction Points and How They Were Addressed
**Force unwrap (`!`) habit.** The agent consistently used `!` to unwrap optionals — `dictionary["key"]!`, `array.first!`. In Swift, force unwrapping is a runtime crash waiting to happen. I initially corrected this case by case, but it kept recurring. The fix: I elevated the prohibition to a "Critical Rule" in the project instructions, with explicit forbidden patterns and required alternatives. This mostly solved it, though occasional violations still needed catching.
**XCTest vs Swift Testing.** The agent defaulted to XCTest patterns: `XCTAssertEqual`, `XCTUnwrap`, `func testSomething()`. Swift Testing uses completely different macros (`#expect`, `try #require`) and conventions (backtick naming, `@Test` attribute). I had to write explicit documentation listing every forbidden XCTest pattern alongside its Swift Testing replacement. Once this was in the project docs, compliance improved significantly.
**Context window limits.** As the codebase grew, the agent would lose track of project conventions established earlier in the session. A pattern that was corrected in one file would reappear in the next. This is a fundamental constraint of current LLMs — they work within a finite context window. The solution was better project documentation (see "The CLAUDE.md Progressive Disclosure Pattern" below).
### Third-Party Skills and Customization
I installed third-party skills to improve the agent's Swift knowledge:
- **Antoine van der Lee's Swift best practices** — a skill that teaches Swift idioms and patterns
- **Swift Testing expert** — specialized knowledge for the Swift Testing framework
- **Swift language reference** — the complete Swift Programming Language book as a skill
I also created custom slash commands (like `/update-claude-md`) for common workflows, and configured a permission allowlist that whitelisted `swift build`, `swift test`, and `swift run` while keeping destructive operations gated behind confirmation prompts.
## The CLAUDE.md Progressive Disclosure Pattern
This is a general-purpose technique for managing AI agent context that I developed while building md-utils. It's applicable to any AI coding agent, not just Claude Code.
The problem: AI agents have finite context windows. If you front-load all your project documentation into the agent's context, you waste tokens on information that isn't relevant to the current task. If you provide too little, the agent makes incorrect assumptions.
The solution: **progressive disclosure**. Structure your project instructions as a small root file that links to detailed topic documents.
md-utils uses this structure:
```
CLAUDE.md ← 48 lines, loaded every session
docs/
├── architecture.md ← project structure, core types, dependencies
├── testing-standards.md ← Swift Testing conventions, patterns
├── swift-coding-standards.md ← language rules, forbidden patterns
├── cli-patterns.md ← command structure, argument parsing
├── development-workflow.md ← feature process, commit checklist
├── common-use-cases.md ← CLI examples and recipes
└── release-procedures.md ← versioning and release process
```
The root `CLAUDE.md` is intentionally kept to 48 lines. It contains:
- Build and test commands
- The one critical rule (no force unwrapping)
- Links to the seven detail documents
The agent loads `CLAUDE.md` on every session. It only pulls in detail documents when the task requires them — writing tests triggers reading `testing-standards.md`, adding a CLI command triggers reading `cli-patterns.md` and `architecture.md`. This keeps the context window focused on what matters for the current task.
**Why this works better than a single large file:**
1. **Relevance filtering** — the agent only loads context it needs
2. **Maintainability** — updating testing conventions means editing one file, not searching through a monolithic document
3. **Scalability** — as the project grows, you add new topic files without bloating the root
4. **Human readability** — the docs are useful for human contributors too, not just agents
This pattern isn't specific to Claude Code. Any AI coding agent that reads project files can benefit from this structure. The key insight is that *the agent's context window is a resource to be managed*, just like memory or CPU. Progressive disclosure is the technique for managing it.
## What's Next
md-utils v0.1.0 is the first public release. The API is not yet stable, and there's a clear roadmap ahead:
- **Link validation** — checking URLs and reference links, not just wikilinks
- **More format conversions** — HTML, RTF, and XML (the converter protocol infrastructure is already in place)
- **Markdown flavor validation** — CommonMark, GFM, and Obsidian compliance checking
- **File metadata writing** — the read side is done
- **LLM agent skill** — exposing md-utils as a tool that AI agents can call directly
On the tooling side, I plan to continue experimenting with different AI coding agents as the space evolves. The workflow patterns I've described — progressive disclosure, critical rules, explicit documentation of conventions — are transferable across agents. The specific agent matters less than the discipline of clearly specifying what you want.
The project is open source at [github.com/DandyLyons/md-utils](https://github.com/DandyLyons/md-utils).
# About Daniel Lyons
# About Daniel Lyons
I'm a Swift developer crafting indie iOS apps and working in music publishing admin. As a Christian, I enjoy writing about technology, philosophy, and a variety of other subjects.
## Links
- [My Projects](https://dandylyons.net/projects/)
- [Developer Blog](https://dandylyons.net/posts/)
- [My Essays](https://dandylyons.net/essays/)
- [Random thoughts](https://dandylyons.net/thoughts/)
- [My Notes](https://dandylyons.net/notes/)
# Search
Search the site for posts, essays, thoughts, projects and more.


 *Job Copilot is currently available for pre-release testing.*
## About
Job Copilot makes it easy to advance your career. It includes:
- Job Application tracker to keep track of your progress on opportunities
- A "Resumé Closet", a place to keep track of work history, skills and anything else that may fit your resume.
- AI powered generators for resumés and cover letters.
- Career advice chat feature.
## Tech Stack
| Component | Tech |
| ------------ | --------------------------------- |
| Platforms | iOS, iPadOS |
| Architecture | TCA (The Composable Architecture) |
| UI | SwiftUI |
| LLM | Gemini |
# Hello Hugo
Hello!
Welcome to my personal site! Here I will be posting my projects and things I'm learning.
I've recently rewritten this site in [hugo](https://gohugo.io/)! I appreciate how blazingly fast and customizable it is. The code for this site can be found [here](https://github.com/DandyLyons/DandyLyons.github.io).
## Dev Diary
Now I'd like to share some of my journey of creating this site.
When creating this site, I had a few priorities:
1. It should be statically generated.
2. It should be easy to write on using Markdown.
3. It should be customizable.
4. It should support modern "tablestakes" website features. (dark mode, social previews, favicons etc.)
5. It should be developed in Swift.
### Initial Priorities
#### It should be statically generated
One of my first encounters with the concept of statically generated sites was [Swift by Sundell](https://www.swiftbysundell.com). This has been one of my favorite blogs for years, and so eventually I learned that John Sundell created his site using something called Static Site Generation, which is when the entire site generated ahead of time statically.
#### It should be easy to write on using Markdown
What attracted me to SSG was that I can write articles in simple Markdown. This is a lightweight simple syntax that allows me to just focus on the content. Furthermore, I can develop my site locally, and see my changes update in real time (much like a SwiftUI Preview), and then deploy my changes when I'm ready.
I've also been an avid Obsidian user over the past few years. Markdown has become deeply ingrained into the way that I think and write.
#### It should be customizable
In years past, on other sites, I've used Wordpress. It was liberating to see how powerful I could make my sites using themes and plugins. But inevitably, I would find a small little change that I wanted to make and it would be unsupported by the plugin. Or, I would have absolutely bizarre buggy behavior, only to evenutally discover that it was because the plugin was outdated, or conflicted with another plugin. This whack-a-mole was debilitating.
This time around I knew that I needed a solution that was customizable. I'm too opinionated to be beholden to someone else's theme. But I also knew that, in my current situation, it was not tenable for me to create the entire site on my own.
I knew HTML, CSS, and JavaScript. At least the core concepts. But I wasn't using it at a deep level. Certainly not on a regular basis. So I wanted a solution where the majority of best practices were just already included "for free" and instead I could just focus on the "small tweaks" that I wanted.
#### It should support modern "tablestakes" website features
Today's readers just expect websites to be responsive. It should smoothly transition from Desktop, to tablet, to mobile. It should switch automatically between light and dark mode. It should display correctly when I share a link on social media. If any of these features are missing or buggy, then the site feels "janky" or "broken".
#### It should be developed in Swift
Swift by Sundell is published using a Static Site Generator which he created called [Publish](https://github.com/johnsundell/publish). In fact, it really is quite a full featured suite, including a Markdown parser (Ink) and a HTML-like Swift DSL (Plot). This seemed to be my holy grail. I could develop for the web using the same tools that I use to develop for mobile. But I soon found a few issues.
There were a few features that were missing. Thankfully, Publish has a great plugin system where you can add new features, but that leads to the second problem: there's not a huge community of Publish users. It was difficult to find example repos, or plugins that met my needs.
It was certainly possible to create my own plugins, but that had two problems. First, creating those plugins would require deeper learning about both Plot (the HTML interpreter) and HTML itself. If I need to learn HTML anyways, I might as well just learn and write it in actual HTML. So this was my second problem: the promise of a primarily Swift workflow, seemed to not actually deliver.
### The Trouble with DSL's
One of my takeaways from this experience is I started to learn some of the pros and cons of a DSL, or Domain Specific Language. For example with Plot we can write code like this:
```swift
var body: Component {
Article {
Image(url: imagePath, description: "Header image")
H1(title)
Span(description).class("description")
}
.class("news")
}
```
This code is so cool and so powerful! As you can see, it is using the same names and concepts as HTML such as `